WeData -> DataWorks
This topic describes how to migrate WeData scheduling workflows to DataWorks using the LHM scheduling migration tool. The process consists of three steps: exporting WeData tasks, converting scheduling tasks, and importing tasks into DataWorks.
1. Export WeData scheduling workflows
The export tool calls the WeData software development kit (SDK) to obtain project space information, workflow definitions, data source definitions, and resource files.
<dependencies>
  <dependency>
    <groupId>com.tencentcloudapi</groupId>
    <artifactId>tencentcloud-sdk-java-common</artifactId>
    <version>3.1.1241</version>
  </dependency>
  <dependency>
    <groupId>com.tencentcloudapi</groupId>
    <artifactId>tencentcloud-sdk-java-wedata</artifactId>
    <version>3.1.1241</version>
  </dependency>
</dependencies>
1. Prerequisites
You must prepare a Java Development Kit (JDK) 17 runtime environment. Ensure network connectivity between the runtime environment and WeData. Download the scheduling migration tool to your local machine and decompress it.
To test network connectivity, you can verify that you can connect to the WeData endpoint.
ping wedata.tencentcloudapi.com2. Configure connection information
In the `conf` folder of the project directory, create an export configuration file in JSON format, such as `read.json`.
Before you use the file, delete the comments from the JSON file.
{
  "schedule_datasource": {
    "name": "YourWedata", // Give your WeData data source a name.
    "type": "Wedata", // Data source type (WeData)
    "properties": {
      "region": "ap-guangzhou", // Region
      "secretId": "***********************", // SecretId
      "secretKey": "***********************", // SecretKey
      "projectId": "2100000000000000000", // Project ID
      "projectName": "MyProject" // Project name
    },
    "operaterType": "AUTO"
  },
  "conf": {

  }
}
2.1 How to get the region
For more information, see Document Center > WeData > API reference > Invocation method > Request structure > Endpoints. Examples include `ap-guangzhou` for Guangzhou, `ap-beijing` for Beijing, `ap-shanghai` for Shanghai, and `ap-chengdu` for Chengdu.
https://cloud.tencent.com/document/product/1267/76338
2.2 How to get the SecretId and SecretKey
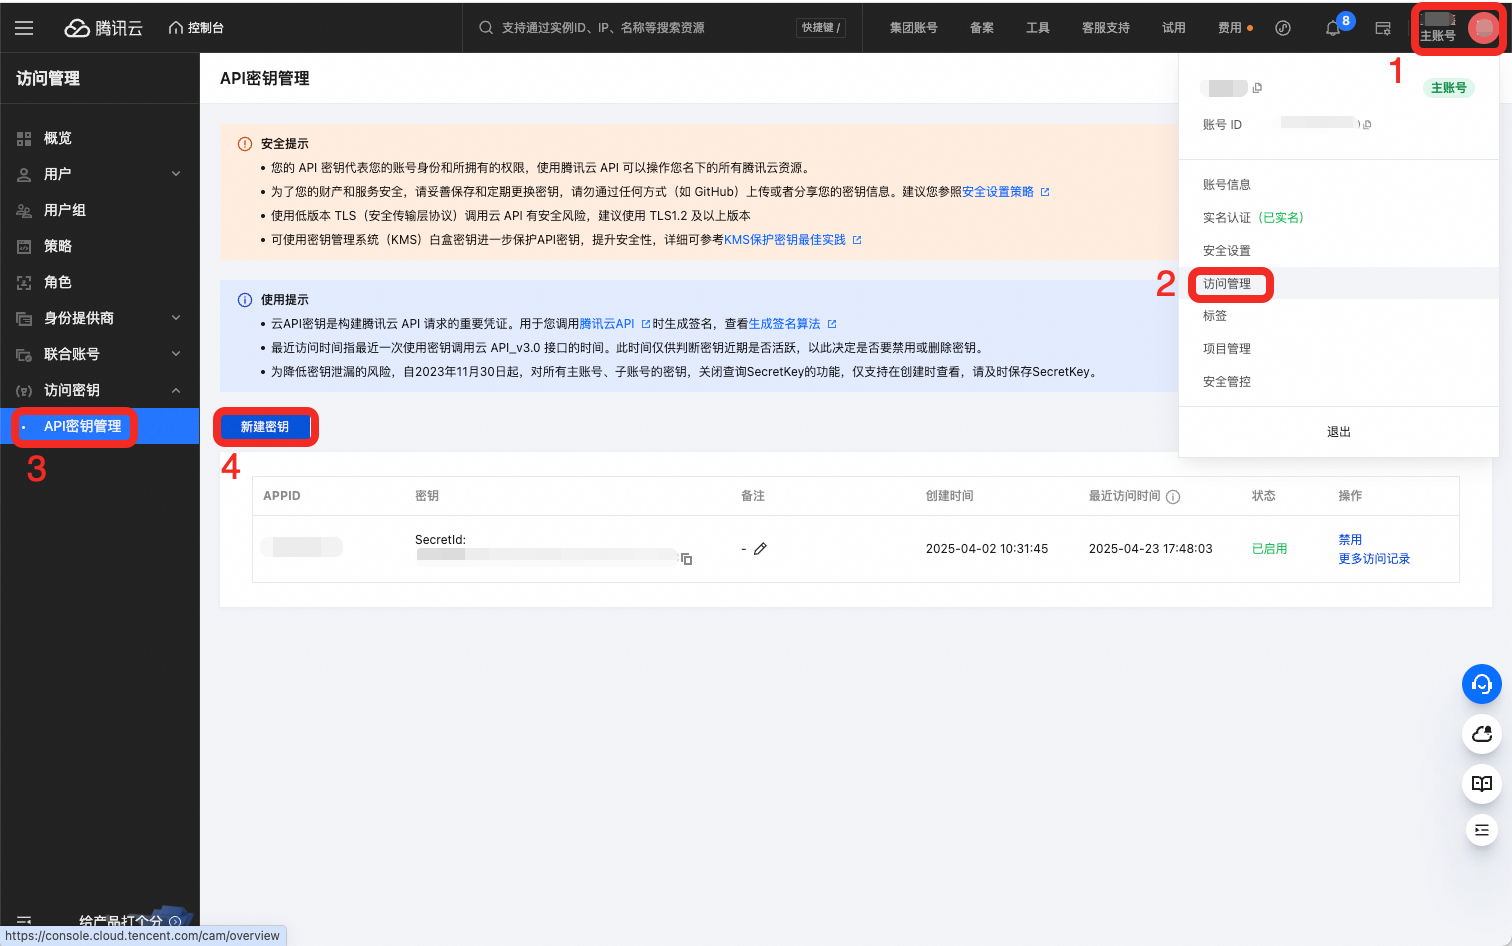
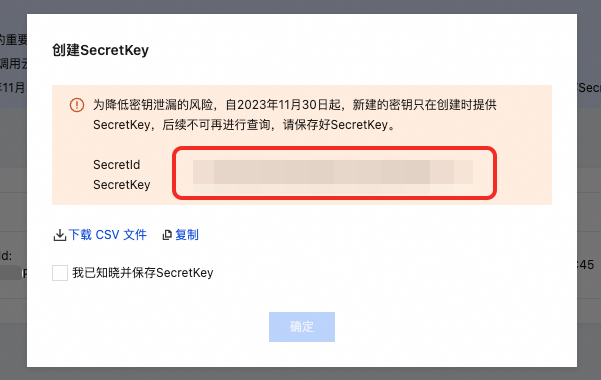
In Access Management - API Key Management, create a new key to obtain the SecretId and SecretKey. Make sure that the account has the required permissions.
2.3 How to get the ProjectId and ProjectName
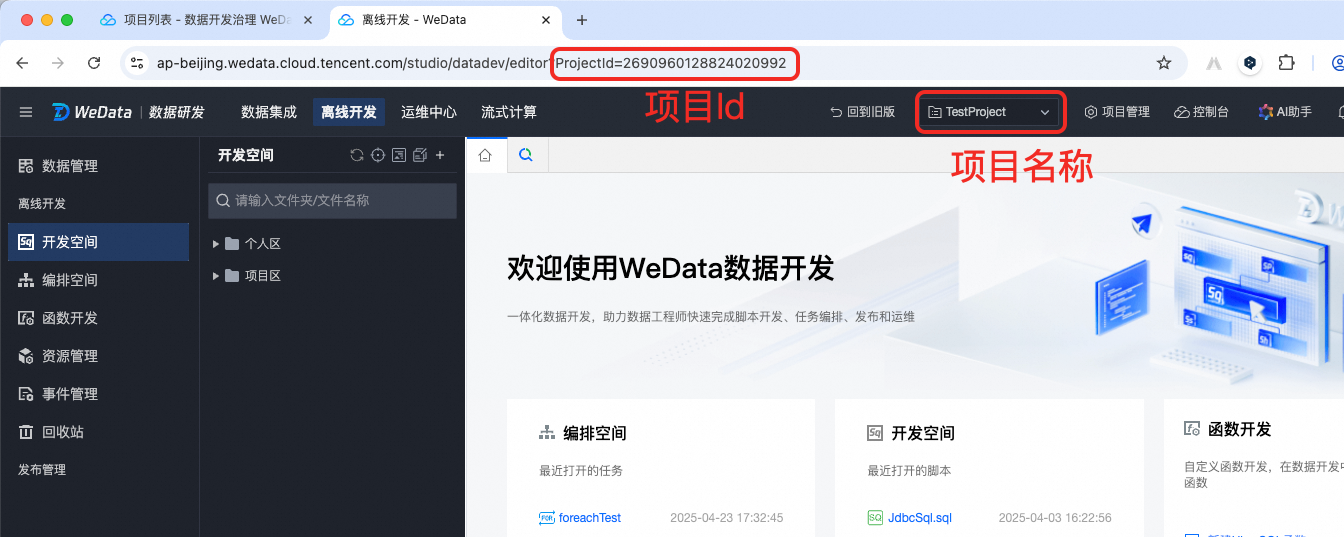
Obtain the project space name from the project list page. Extract the project space ID from the URL of the offline development page.
3. Run the scheduling discovery tool
Call the discovery tool from the command line. The command is as follows:
sh ./bin/run.sh read \
-c ./conf/<your_config_file>.json \
-o ./data/1_ReaderOutput/<source_discovery_export_package>.zip \
-t wedata-reader
In the command, `-c` specifies the path to the configuration file, `-o` specifies the storage path for the ReaderOutput package, and `-t` specifies the name of the discovery plugin.
The following example shows how to export Project A from WeData:
sh ./bin/run.sh read \
-c ./conf/projectA_read.json \
-o ./data/1_ReaderOutput/projectA_ReaderOutput.zip \
-t wedata-reader
The discovery tool prints process information as it runs. Check for errors during the process.
4. View the export results
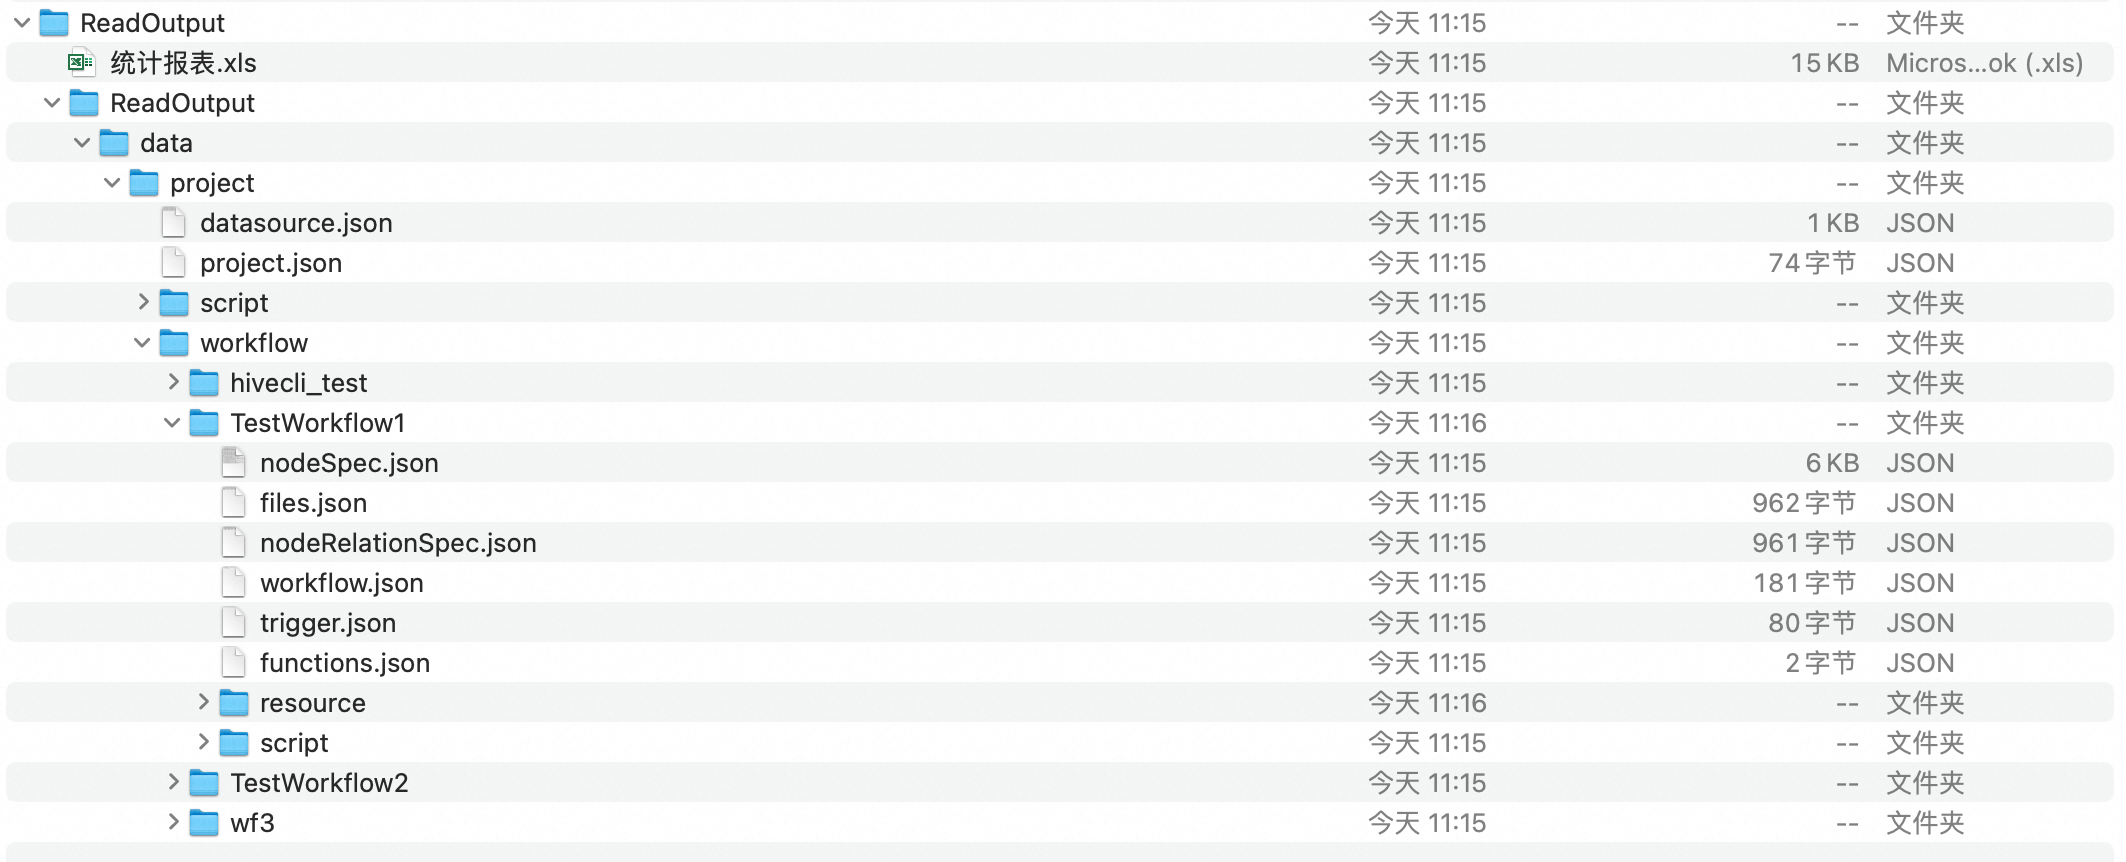
Open the generated `ReaderOutput.zip` package in the `./data/1_ReaderOutput/` directory to preview the export results.
The statistical report provides a summary of basic information about the workflows, nodes, resources, functions, and data sources in WeData.
The `data/project` folder contains the WeData scheduling information that is converted into a standardized data structure.
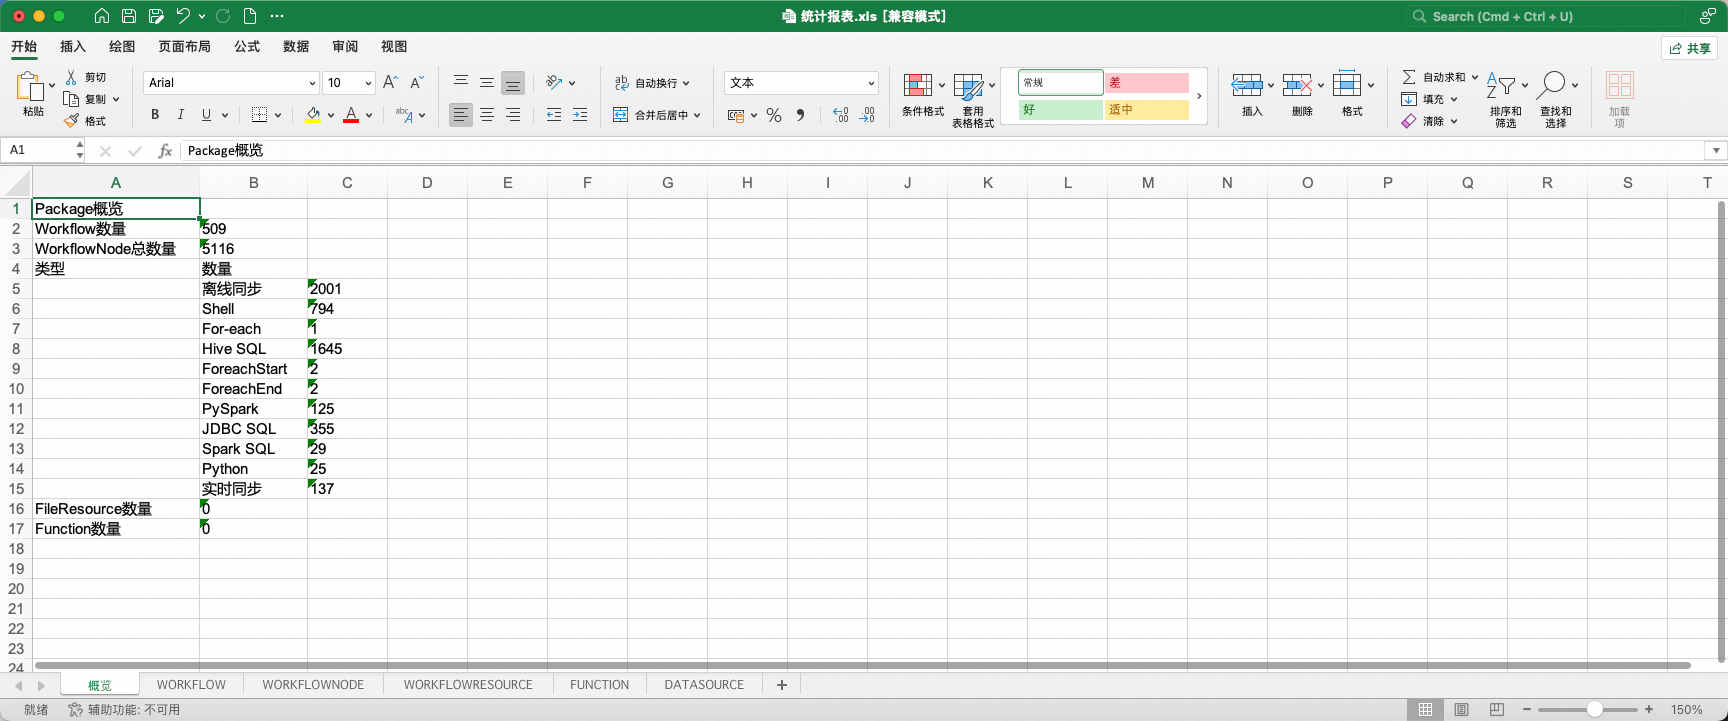
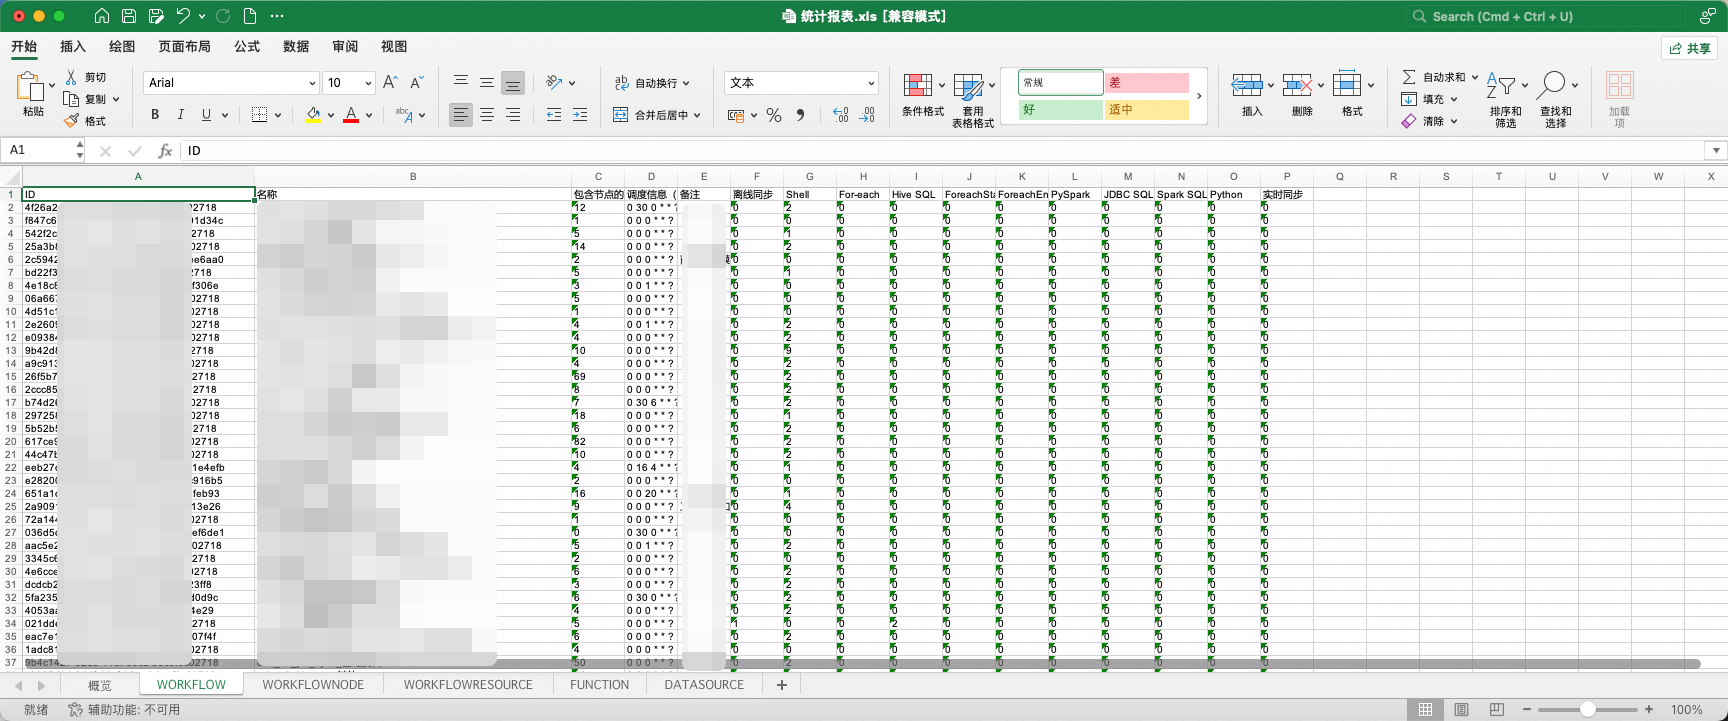
The statistical report provides two special features:
1. You can change some properties of workflows and nodes in the report. Editable fields are displayed in blue font. In the next stage, scheduling conversion, the tool retrieves these property changes from the table and applies them during initialization.
2. The report lets you skip workflows during conversion by deleting rows from the workflow child table. This acts as a workflow blacklist. Note: If workflows have dependencies on each other, you must convert the related workflows in the same batch. Do not separate them using the blacklist. Separating them causes errors.
For more information, see Use the overview report in scheduling migration to add or modify scheduling properties.
2. Convert WeData workflows to DataWorks
1. Prerequisites
The discovery tool has successfully run and exported the WeData scheduling information to the `ReaderOutput.zip` file.
(Optional, recommended) Open the discovery export package and view the statistical report to check whether the scope of the migration was fully exported.
2. Configuration items for conversion
The converter provides multiple configuration items. These items help you adapt to various compute engines on the target end.
In the `conf` folder of the project directory, create a configuration file in JSON format, such as `transform.json`.
The two core configuration items are:
1. `di.datasource.map`: Configures the mapping relationship (name, type) between WeData data sources and DataWorks data sources.
2. `conf.rule.settings`: Configures the conversion rules, such as node types, between WeData nodes and DataWorks nodes.
2.1 Conversion configuration template
Before you use the file, delete the comments from the JSON file.
{
  "name": "wedata-dw-converter",
  "self": {
    "di.datasource.map": [ // Mapping rules for WeData and DataWorks data sources
      {
        "srcName": "MyHiveDatasource", // WeData Hive data source
        "srcType": "hive",
        "tgtName": "MyMaxComputeDatasource", // DataWorks MaxCompute data source
        "tgtType": "odps"
      },
      {
        "srcName": "MyMysqlDatasource", // WeData MySQL data source
        "srcType": "mysql",
        "tgtName": "MyMysqlDatasource", // DataWorks MySQL data source
        "tgtType": "mysql"
      }
    ],
    "conf": [
      {
        "rule": { // Node conversion rule configuration (configure based on the scheduling conversion plan)
          "settings": {
            // Convert WeData Shell node to DataWorks Shell node
            "workflow.converter.shellNodeType": "DIDE_SHELL",
            // Convert WeData Python node to DataWorks Python node
            "workflow.converter.pythonNodeType": "PYTHON",
            // If a Python node uses a custom third-party package, or if the DataWorks Python version does not match the required version, create a custom image and configure it here.
            // DataWorks Python node image (optional)
            "workflow.converter.pythonImageId": "python_image_0000",
            // DataWorks PyODPS node image (optional)
            "workflow.converter.pyodps2ImageId": "odps_python2_image_0000",
            // DataWorks PyODPS3 node image (optional)
            "workflow.converter.pyodps3ImageId": "odps_python3_image_0000",
            // Convert WeData HiveSQL node to DataWorks MaxCompute SQL node
            "workflow.converter.hiveSqlNodeType": "ODPS_SQL",
            // Convert WeData JDBC SQL node to a DataWorks database node based on the connected data source type
            "workflow.converter.jdbcSqlNodeType": {
              "doris": "HOLOGRES_SQL",
              "oracle": "Oracle",
              "mysql": "MYSQL",
              "tencent_mysql": "MYSQL"
            },
            // Convert WeData Spark SQL node to DataWorks MaxCompute SQL node
            "workflow.converter.sparkSqlNodeType": "ODPS_SQL",
            // Convert WeData SparkPy node to DataWorks MaxCompute Spark node
            "workflow.converter.sparkPyNodeType": "ODPS_SPARK",
            // Spark version number
            "workflow.converter.sparkVersion": "3.x"
          }
        },
        "nodes": "all"
      }
    ],
    "if.use.migrationx.before": false,
    "if.use.default.convert": false,
    "if.use.dataworks.newidea": true,
  },
  "schedule_datasource": {},
  "target_schedule_datasource": {}
}
2.2 Data source mapping table di.datasource.map
The `di.datasource.map` data source mapping table is used to configure the mapping relationship (name, type) between WeData and DataWorks data sources. For example, if the source has a Hive data source named `MyHiveDatasource` and its data is migrated to a MaxCompute data source named `MyMaxComputeDatasource`, you can configure the mapping relationship as follows.
{
  "srcName": "MyHiveDatasource"
  "srcType": "hive",
  "tgtName": "MyMaxComputeDatasource"
  "tgtType": "odps"
}
The tool currently supports configuring the following WeData data sources:
tencent_mysql, mysql, oracle, doris, hive, dlc, ckafka, kafka, oceanbase, starrocks, postgre, and sqlserver
The tool currently supports configuring the following DataWorks data sources:
mysql, oracle, holo (Hologres), odps (MaxCompute), kafka, oceanbase, starrocks, postgre, and sqlserver
The conversion tool modifies the binding relationship between nodes, such as SQL and data integration nodes, and data sources based on the data source mapping rules. The tool also completes the mapping of data integration configurations.
For more information about WeData data integration configuration, see https://cloud.tencent.com.cn/document/product/1267/110747.
For more information about DataWorks data integration configuration, see Data Source List.
The data integration task configuration mapping of the tool currently covers the following scenarios:
WeData data integration reader plugin -> DataWorks data integration reader plugin:
tencent_mysql -> mysql, mysql -> mysql, oracle-> oracle, doris -> holo, hive -> odps, dlc -> odps, ckafka -> kafka, kafka -> kafka, oceanbase -> oceanbase, starrocks -> starrocks, postgre -> postgre, sqlserver -> sqlserver, ... (More are coming soon.)
WeData data integration writer plugin -> DataWorks data integration writer plugin:
tencent_mysql -> mysql, mysql -> mysql, oracle-> oracle, doris -> holo, hive -> odps, dlc -> odps, ckafka -> kafka, kafka -> kafka, ... (More are coming soon.)
2.3 Node conversion rules conf.rule.settings
The tool currently supports converting the following types of WeData nodes:
· Shell, HiveSql, JDBCSql, Python, SparkPy, and SparkSql
· Foreach, ForeachStart, ForeachEnd, and Offline Sync
The types for which you can configure DataWorks mapping rules include the following:
· Shell (`workflow.converter.shellNodeType`):
We recommend that you convert the node to a DIDE_SHELL, EMR_SHELL, or VIRTUAL node.
· HiveSql (`workflow.converter.hiveSqlNodeType`):
We recommend that you convert the node to an ODPS_SQL or EMR_HIVE node.
· JDBCSql (`workflow.converter.jdbcSqlNodeType`):
We recommend that you convert the node to various SQL nodes or database nodes.
· Python (`workflow.converter.pythonNodeType`):
We recommend that you convert the node to a PYTHON, PYODPS, PYODPS3, or EMR_SHELL node.
· SparkPy (`workflow.converter.sparkPyNodeType`):
We recommend that you convert the node to an ODPS_SPARK or EMR_SPARK node.
· SparkSql (`workflow.converter.sparkSqlNodeType`):
We recommend that you convert the node to an ODPS_SQL or EMR_SPARK_SQL node.
Node types with fixed conversion rules:
· Foreach, ForeachStart, and ForeachEnd:
These nodes are converted by default to DataWorks Foreach nodes and their start and end nodes.
· Offline Sync: This node is converted by default to a DataWorks data integration node.
Additional conversion information:
· For Python, PYODPS, and PYODPS3 nodes that need to load custom images, you can configure the `workflow.converter.pythonImageId`, `workflow.converter.pyodps2ImageId`, and `workflow.converter.pyodps3ImageId` conversion rules.
· Spark nodes require the Spark version number. You can configure this using the `workflow.converter.sparkVersion` parameter.
For more information about DataWorks node types, see the following enumeration class:
3. Run the scheduling conversion tool
Call the conversion tool from the command line. The command is as follows:
sh ./bin/run.sh convert \
-c ./conf/<your_config_file>.json \
-f ./data/1_ReaderOutput/<source_discovery_export_package>.zip \
-o ./data/2_ConverterOutput/<conversion_result_output_package>.zip \
-t wedata-dw-converter
In the command, `-c` specifies the path to the configuration file, `-f` specifies the storage path for the ReaderOutput package, `-o` specifies the storage path for the ConverterOutput package, and `-t` specifies the name of the conversion plugin.
For example, to transform WeData project A:
sh ./bin/run.sh convert \
-c ./conf/projectA_convert.json \
-f ./data/1_ReaderOutput/projectA_ReaderOutput.zip \
-o ./data/2_ConverterOutput/projectA_ConverterOutput.zip \
-t wedata-dw-converter
The conversion tool prints process information as it runs. Check for errors during the process. After the conversion is complete, statistics for successful and failed conversions are printed to the command line. Note: The failure of some node conversions does not affect the overall conversion process. If a few nodes fail to convert, you can manually modify them after you migrate the nodes to DataWorks.
4. View the conversion results
Open the generated `ConverterOutput.zip` package in the `./data/2_ConverterOutput/` directory to preview the conversion results.
The statistical report provides a summary of basic information about the converted workflows, nodes, resources, functions, and data sources.
The `data/project` folder is the main part of the converted scheduling migration package.
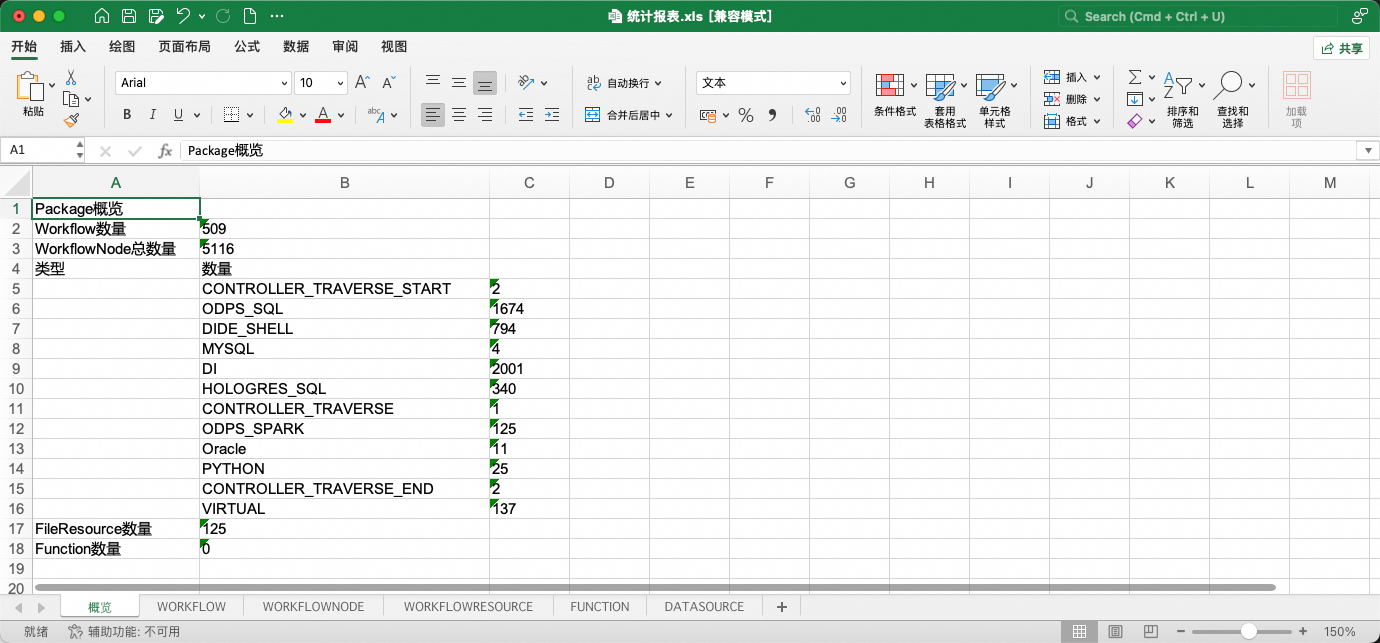
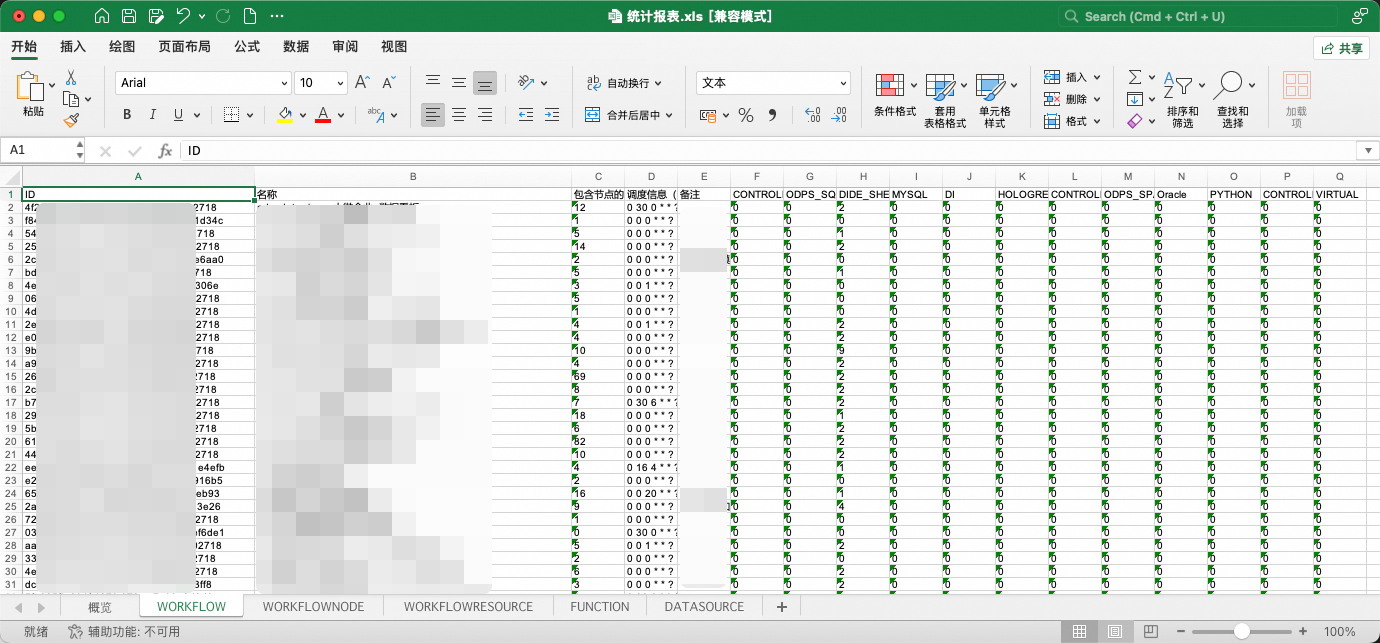
The statistical report provides two special features:
1. You can change some properties of workflows and nodes in the report. Editable fields are displayed in blue font. In the next stage, when you import the workflows and nodes to DataWorks, the tool retrieves these property changes from the table and applies them.
2. The report lets you skip workflows during the import to DataWorks by deleting rows from the workflow child table. This acts as a workflow blacklist. Note: If workflows have dependencies on each other, you must import the related workflows in the same batch. Do not separate them using the blacklist. Separating them causes errors.
For more information, see Use the overview report in scheduling migration to add or modify scheduling properties.
3. Import to DataWorks
The LHM migration tool converts source scheduling elements into the DataWorks scheduling format and provides a unified entry point to import workflows for different migration scenarios.
The import tool supports multiple write cycles. It automatically creates or updates workflows in Overwrite mode.
1. Prerequisites
1.1 Successful conversion
The conversion tool has successfully run and converted the source scheduling information to DataWorks scheduling information. The `ConverterOutput.zip` file is also successfully generated.
(Optional, recommended) Open the conversion output package and view the statistical report to check whether the scope of the migration was converted successfully.
1.2 Configuration on the DataWorks side
On the DataWorks side, perform the following operations:
1. Create a workspace.
2. Create an AccessKey pair. Ensure that the AccessKey pair has administrator permissions for the workspace. (We strongly recommend that you create an AccessKey pair that is bound to your account to help troubleshoot write issues.)
3. In the workspace, create data sources, attach computing resources, and create resource groups.
4. In the workspace, upload resource files and create user-defined functions (UDFs).
1.3 Network connectivity check
Verify that you can connect to the DataWorks endpoint.
Endpoints:
ping dataworks.aliyuncs.com2. Import configuration items
In the `conf` folder of the project directory, create a configuration file in JSON format, such as `writer.json`.
Before you use the file, delete the comments from the JSON file.
{
  "schedule_datasource": {
    "name": "YourDataWorks", // Give your DataWorks data source a name.
    "type": "DataWorks",
    "properties": {
      "endpoint": "dataworks.cn-hangzhou.aliyuncs.com", // Endpoint
      "project_id": "YourProjectId", // Workspace ID
      "project_name": "YourProject", // Workspace name
      "ak": "************", // AK
      "sk": "************", // SK
    },
    "operaterType": "MANUAL"
  },
  "conf": {
    "di.resource.group.identifier": "Serverless_res_group_***_***", // Scheduling resource group
    "resource.group.identifier": "Serverless_res_group_***_***", // Data integration resource group
    "dataworks.node.type.xls": "/Software/bwm-client/conf/CodeProgramType.xls", // Path to the DataWorks node type table
    "qps.limit": 5 // QPS limit for sending API requests to DataWorks
  }
}
2.1 Endpoints
Select an endpoint based on the region where your DataWorks workspace is located. For more information, see the following topic:
2.2 Workspace ID and name
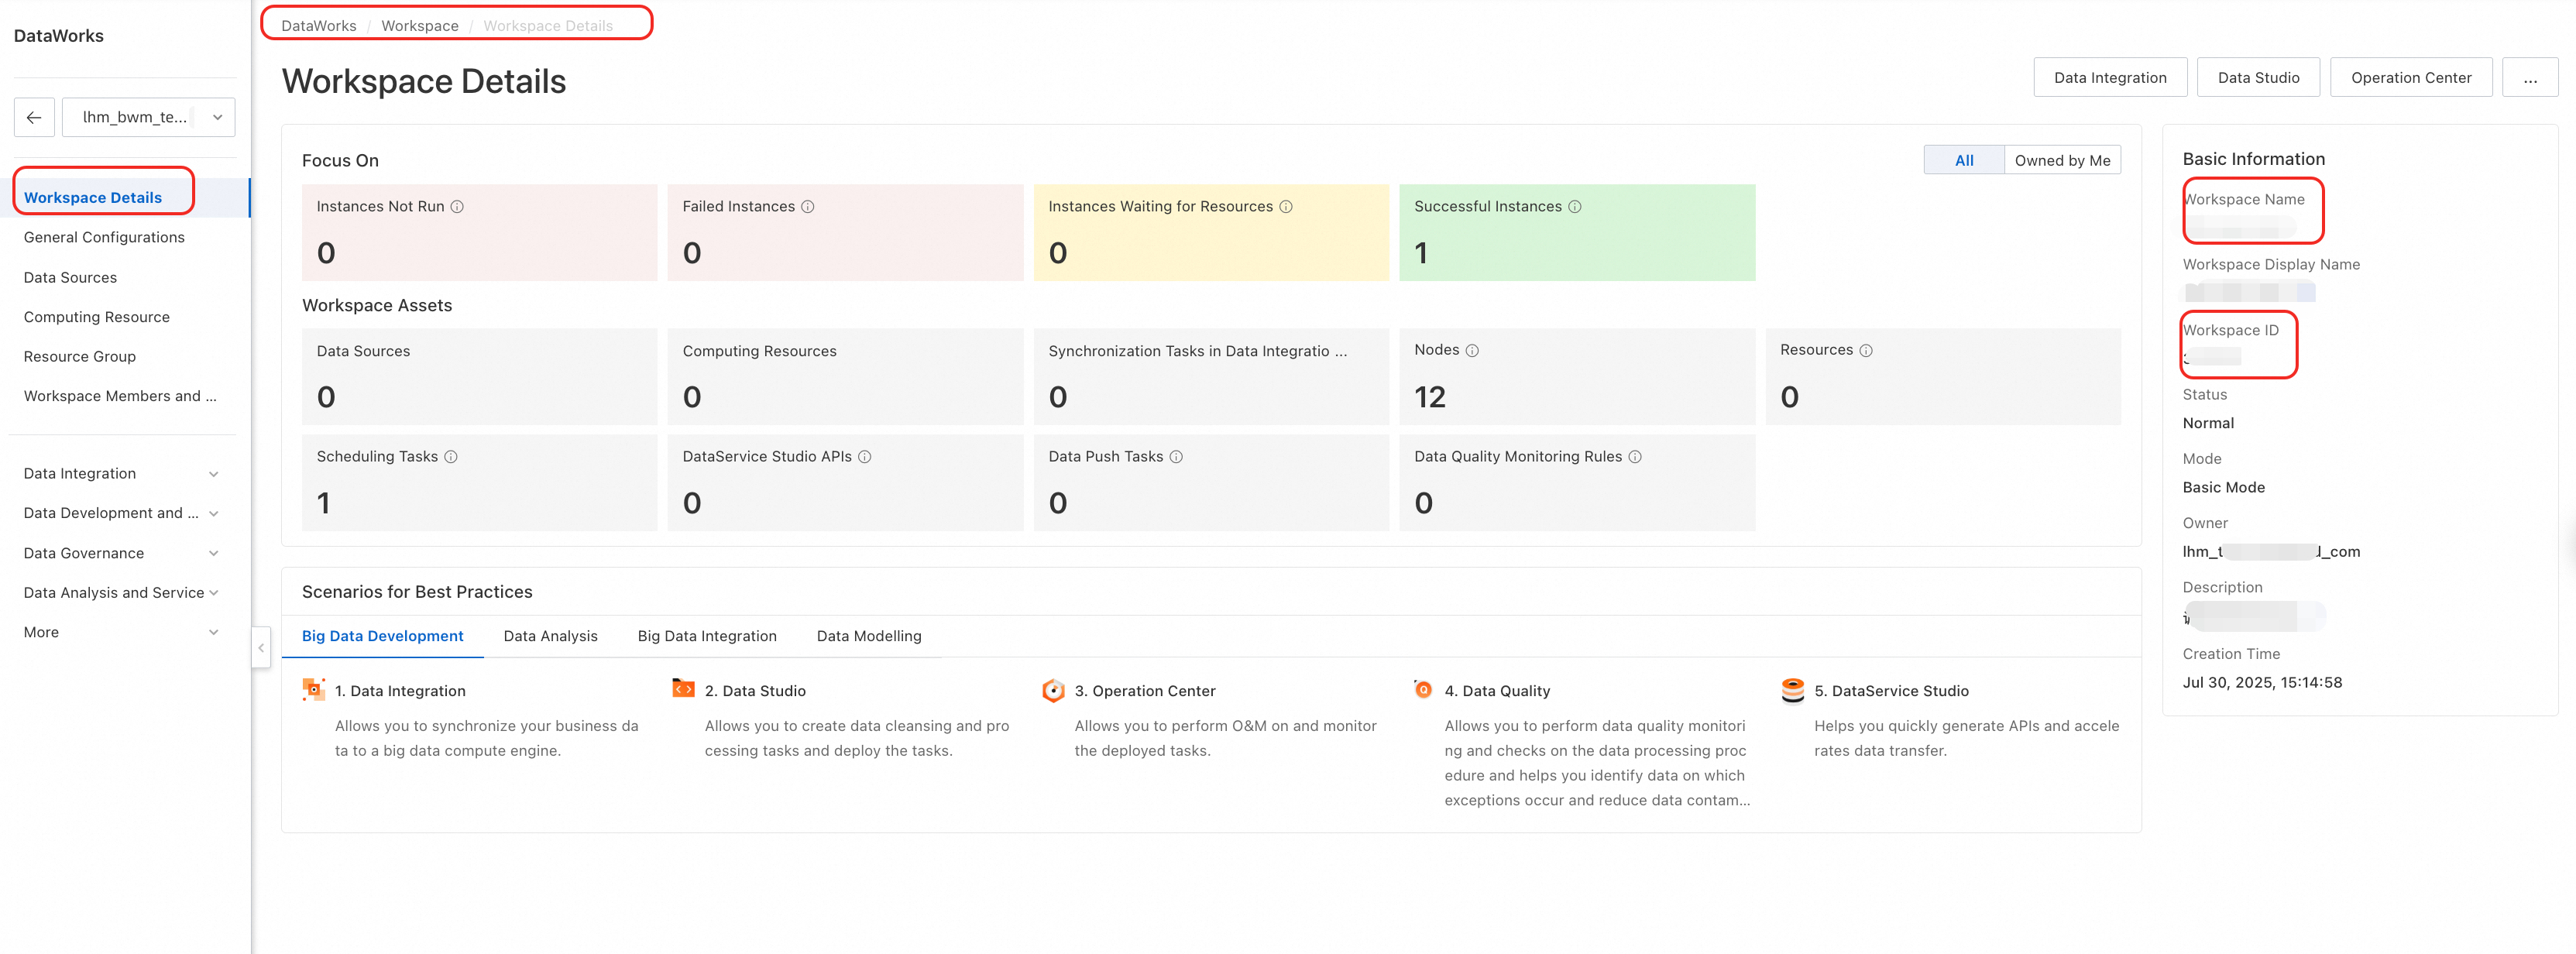
Open the DataWorks console and go to the workspace product page. Obtain the workspace ID and name from the basic information on the right.
2.3 Create and grant permissions to an AccessKey pair
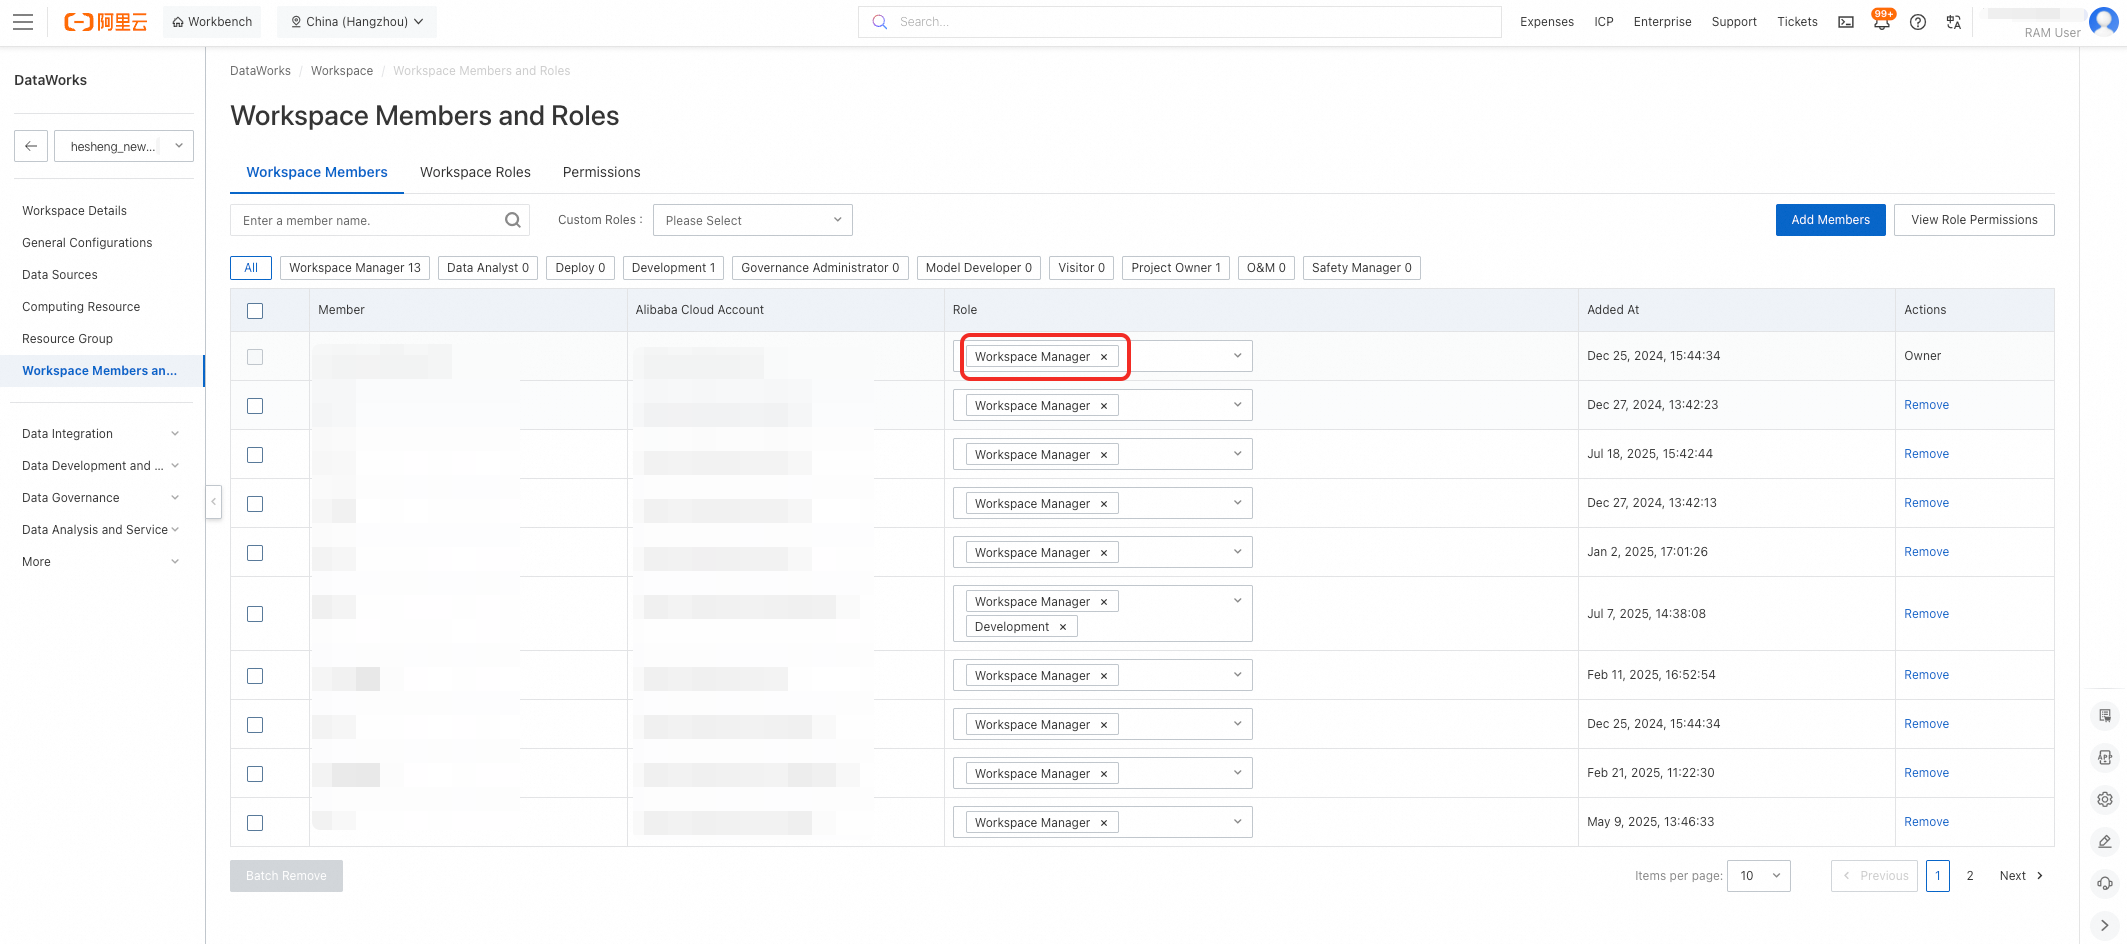
On the user page, create an AccessKey pair. The AccessKey pair must have administrator read and write permissions for the target DataWorks workspace.
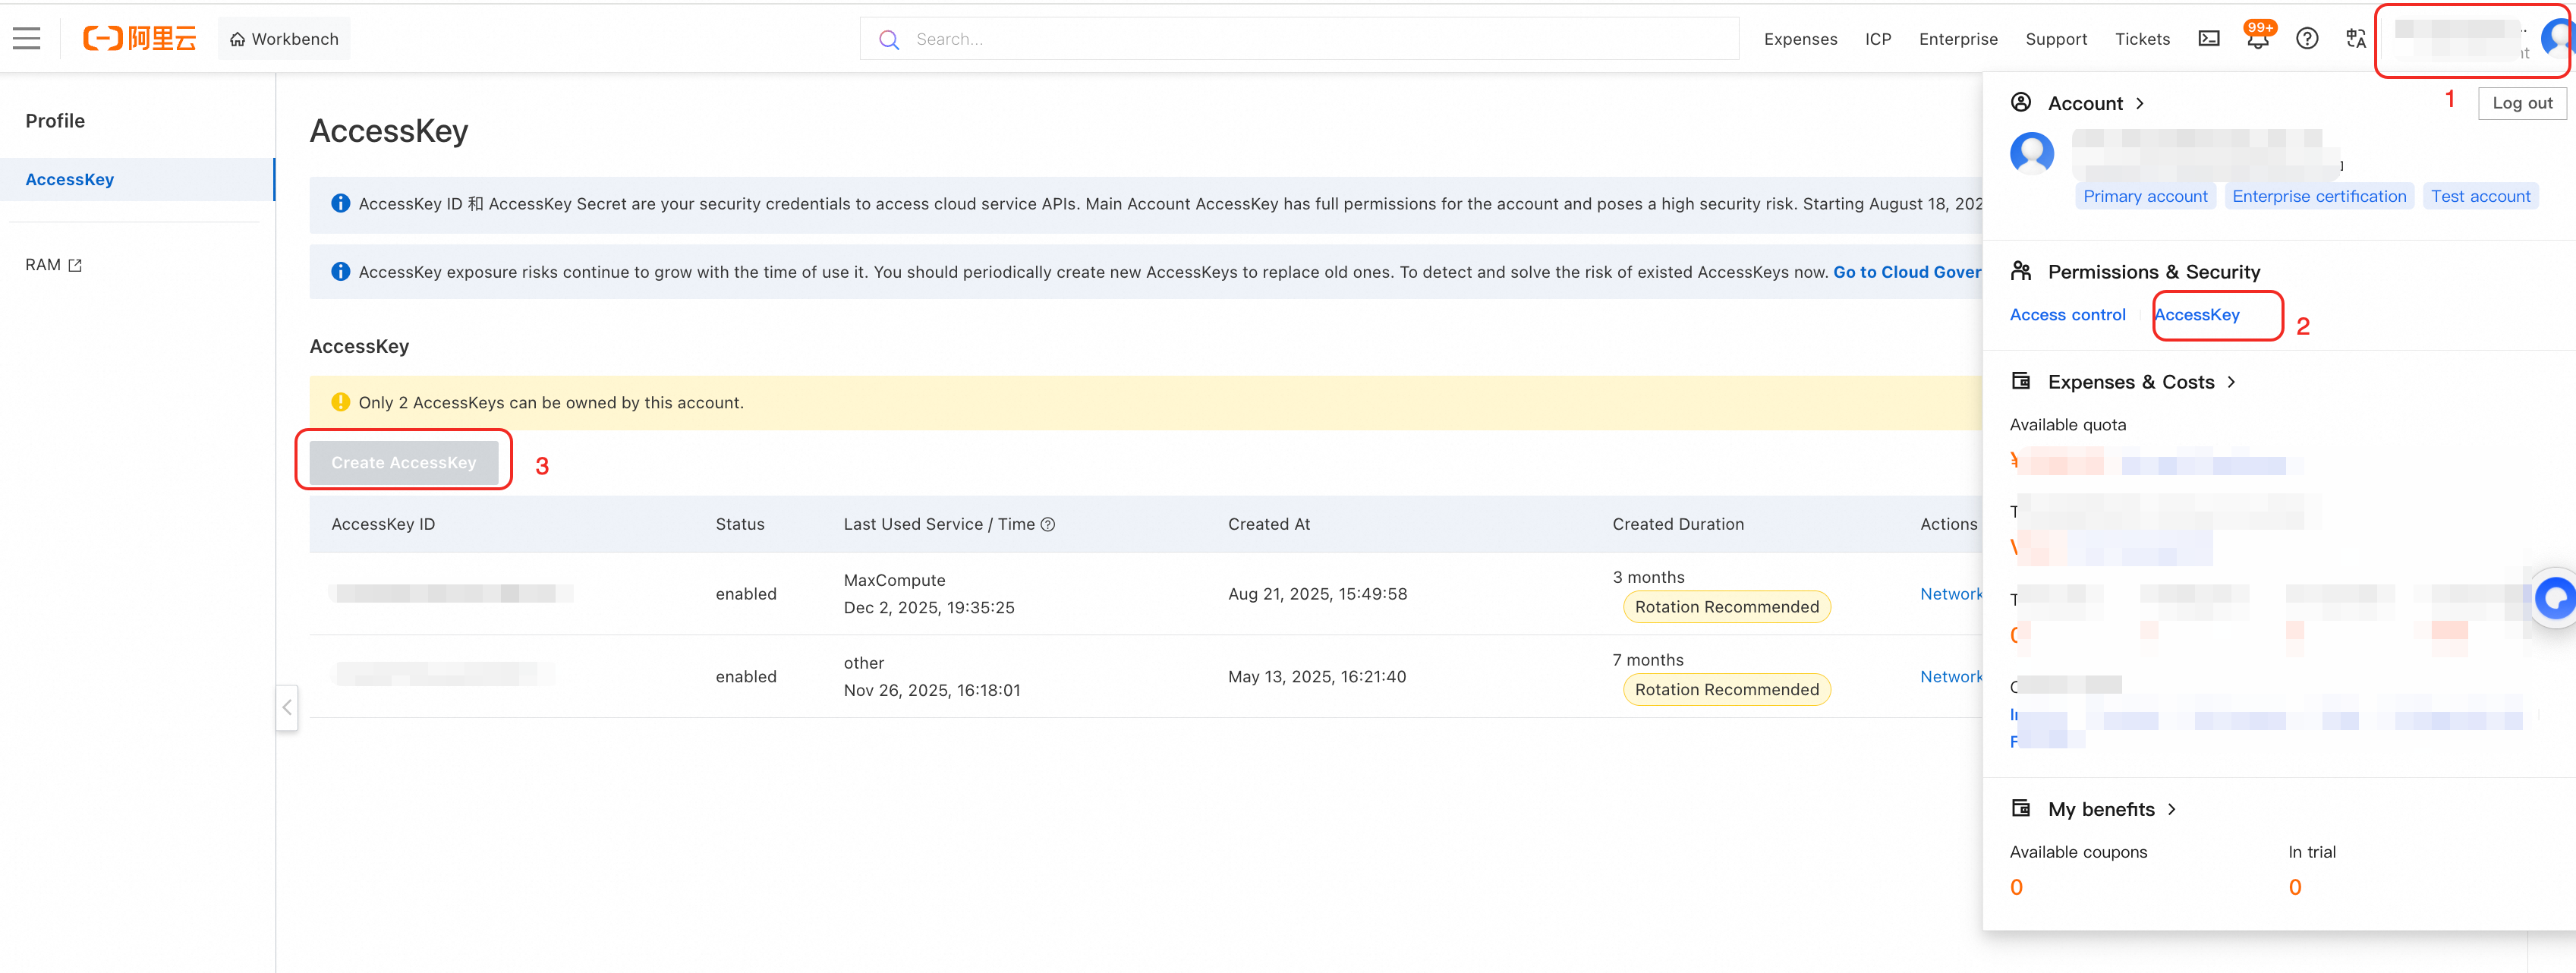
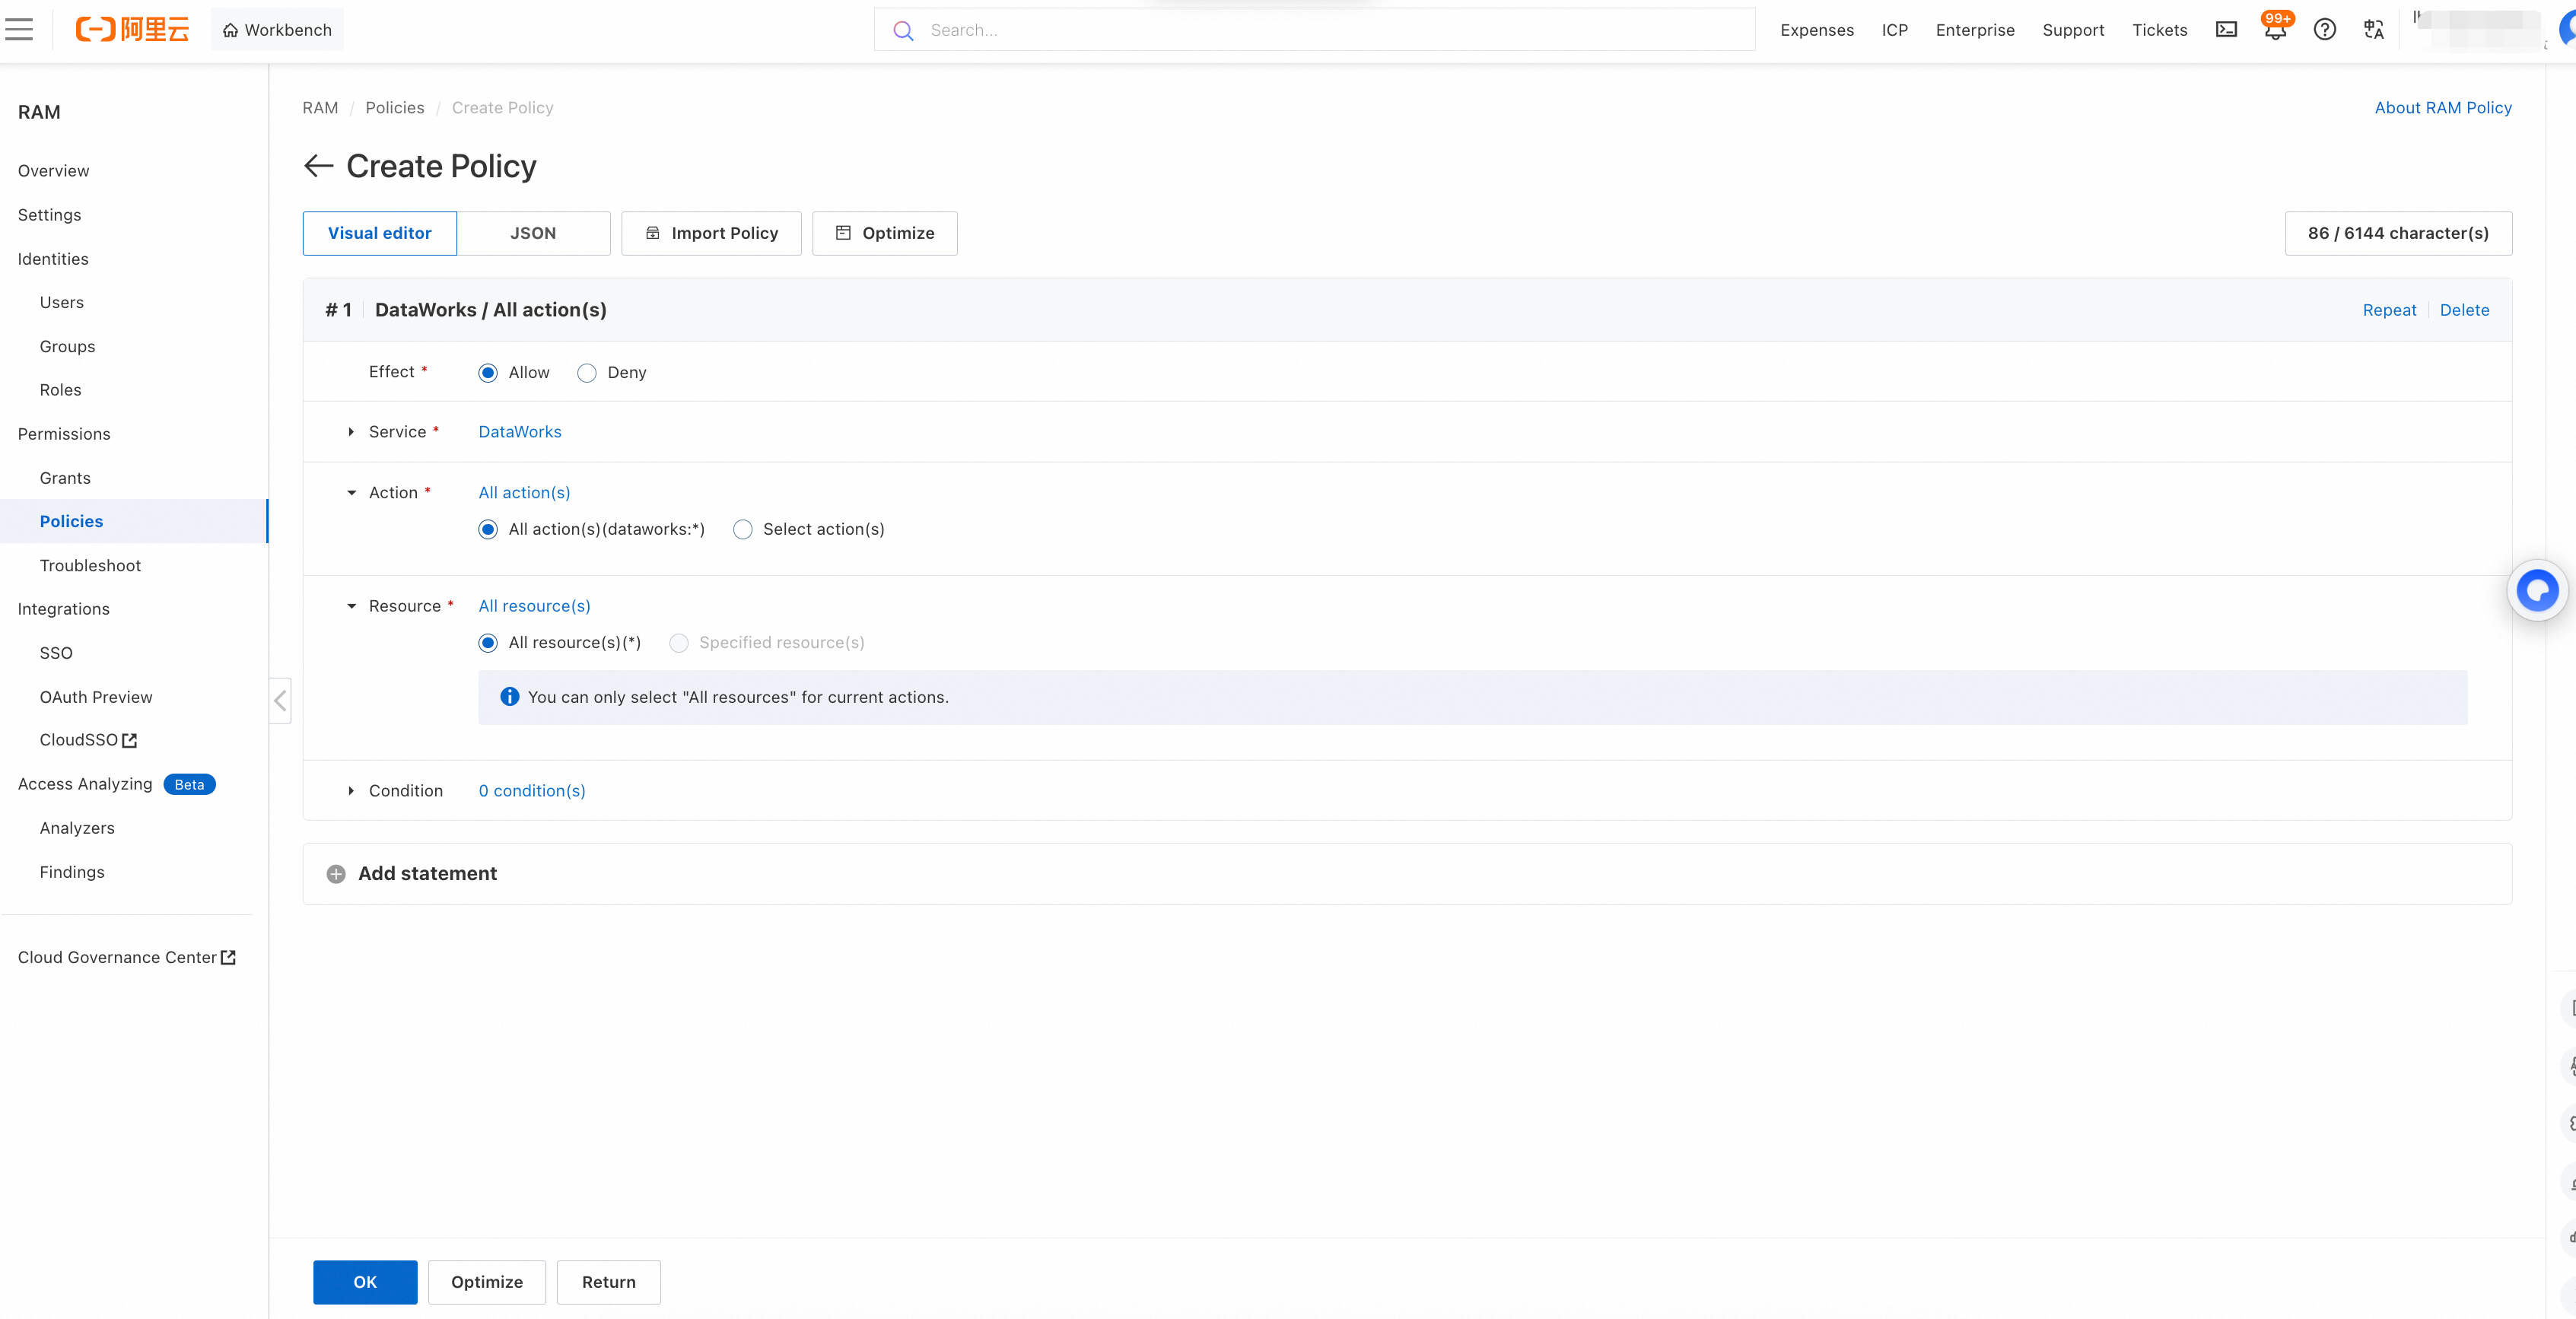
Permission management involves two locations. If the account is a Resource Access Management (RAM) user, you must first grant the RAM user authorization for DataWorks operations.
Policy page: https://ram.console.aliyun.com/policies
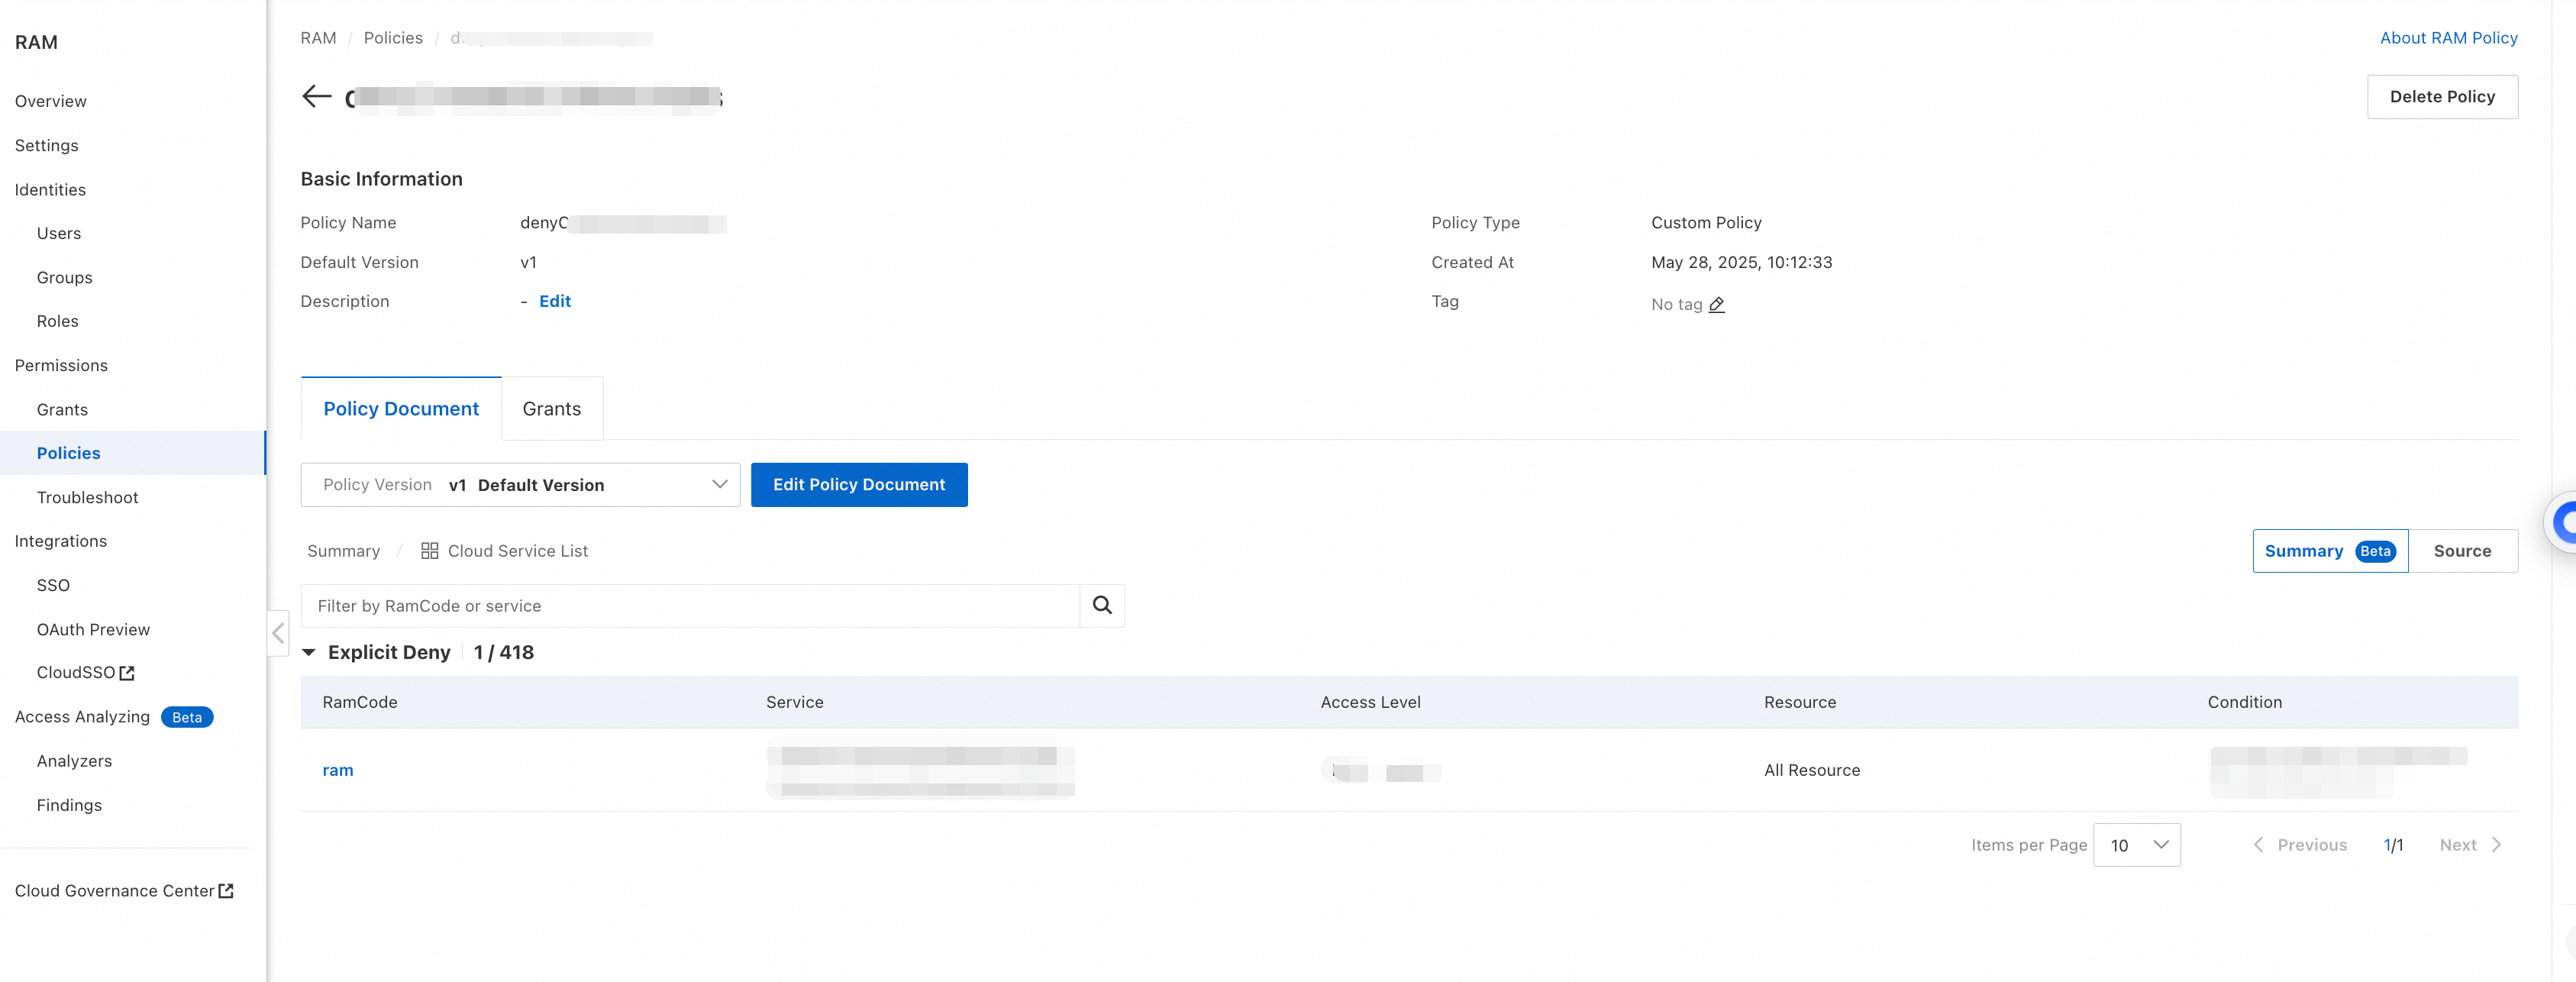
Then, in the DataWorks workspace, assign workspace permissions to the account.
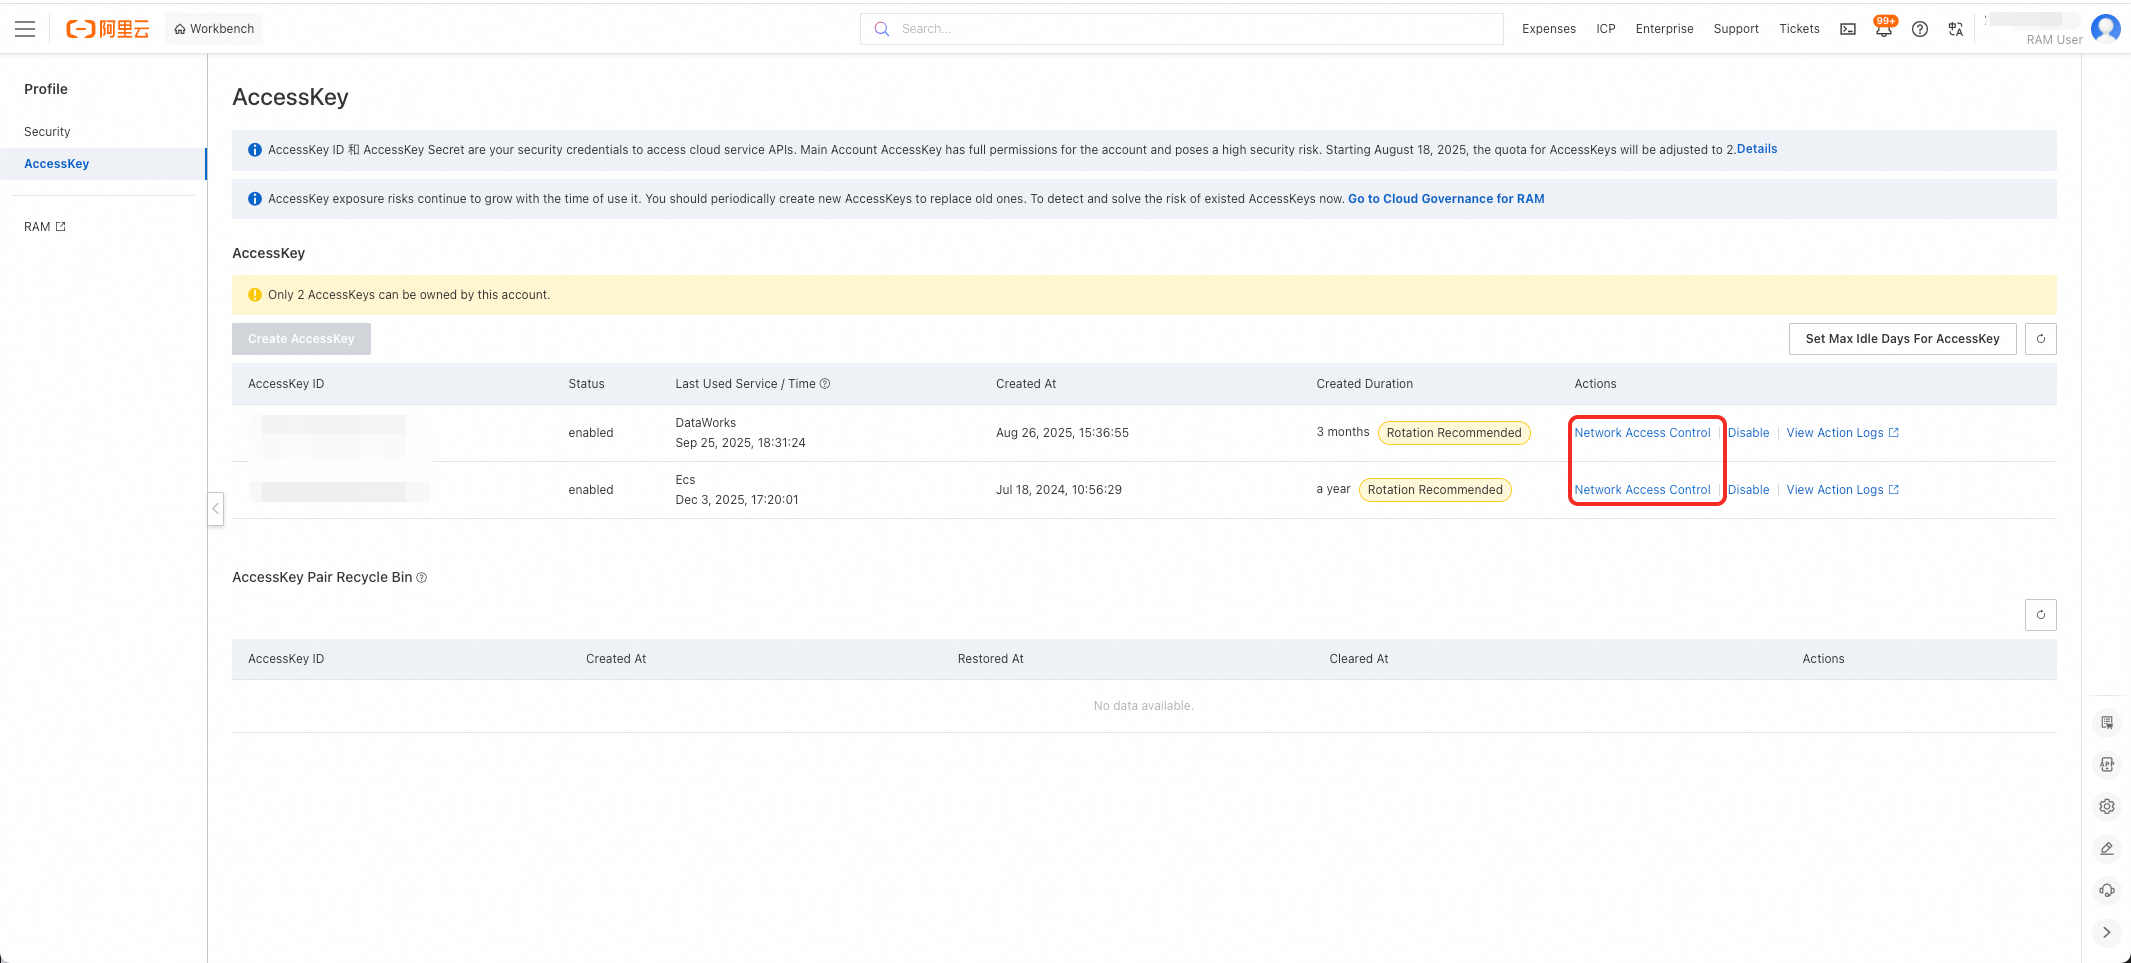
Note: You can set a network access control policy for an AccessKey. Make sure that the IP address of the machine where the migration tool is located is allowed to access DataWorks.
2.4 Resource groups
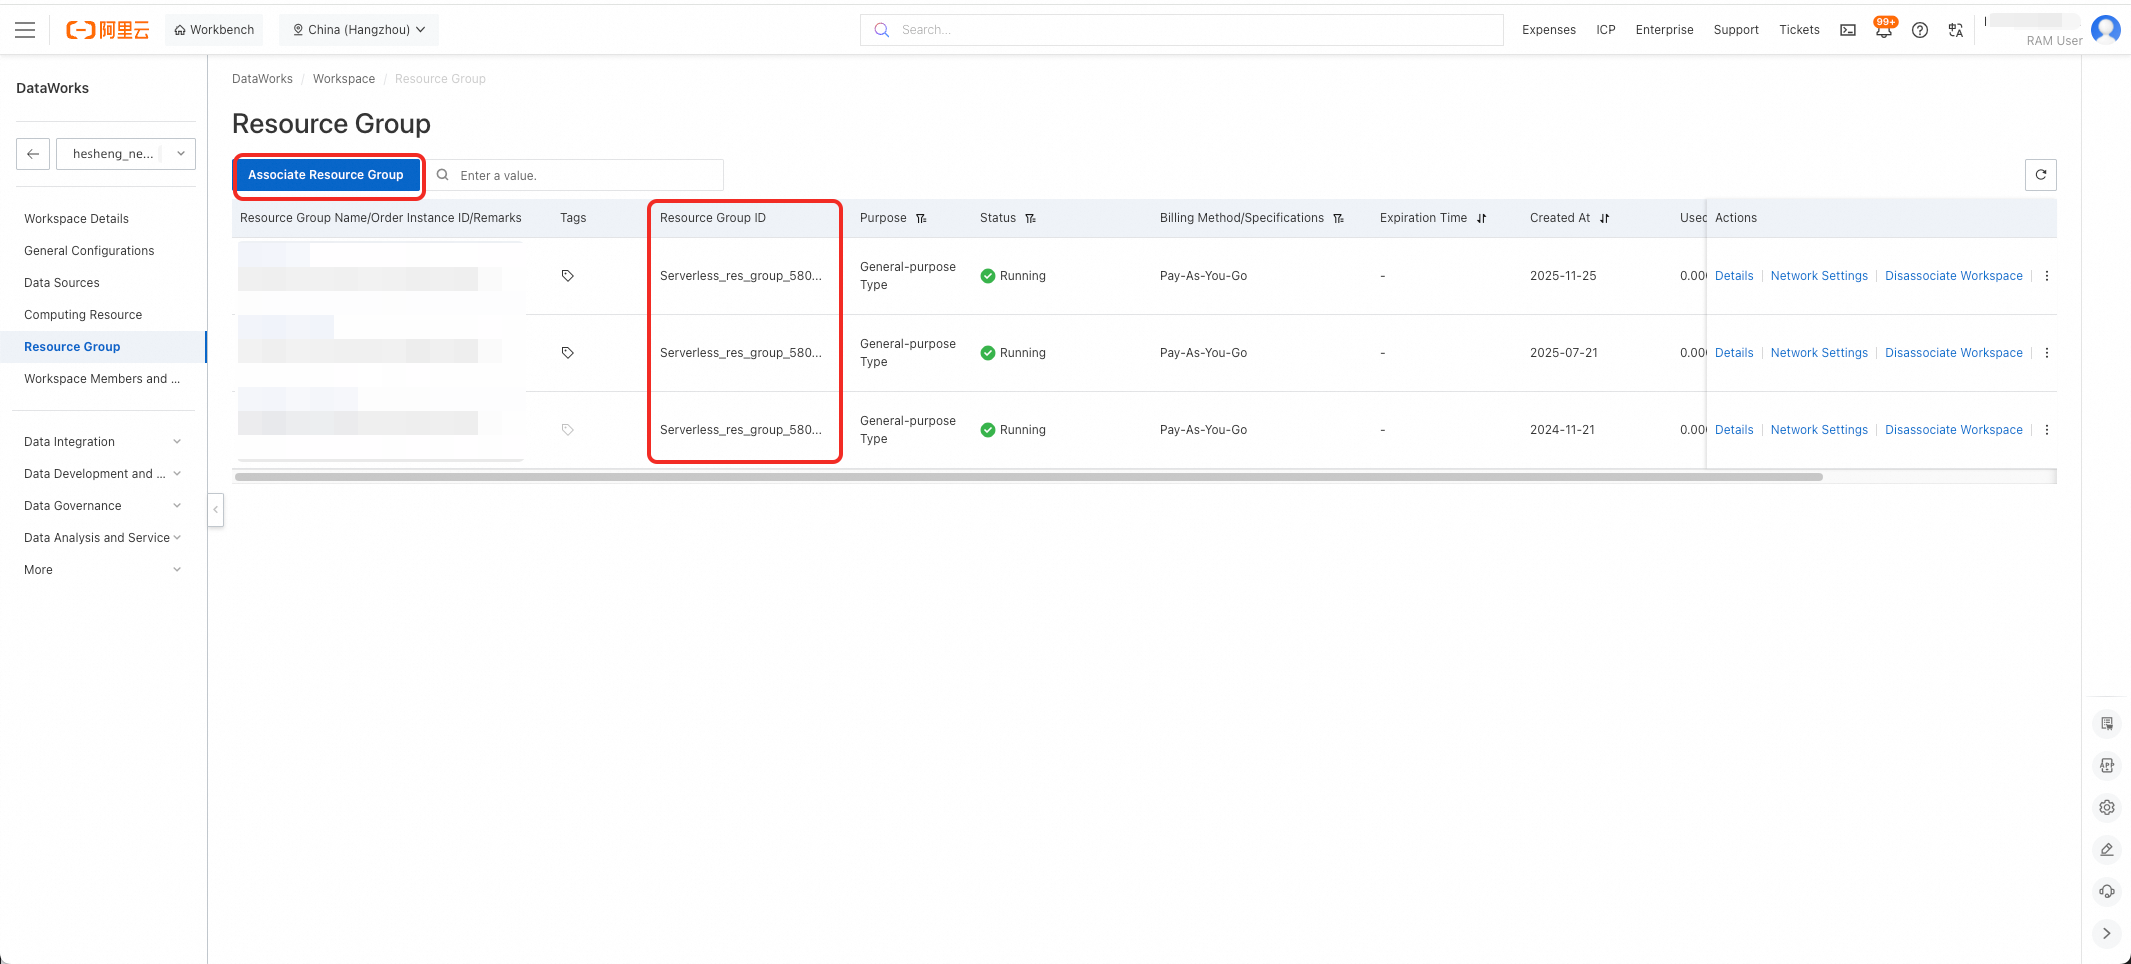
In the navigation pane on the left of the DataWorks workspace product page, go to the resource group page. Attach a resource group and obtain its ID.
A general-purpose resource group can be used for node scheduling and data integration. You can set the scheduling resource group (`resource.group.identifier`) and the data integration resource group (`di.resource.group.identifier`) to the same general-purpose resource group in the configuration.
2.5 QPS settings
The tool imports data by calling DataWorks APIs. Different editions of DataWorks have different queries per second (QPS) limits and daily call limits for read and write OpenAPI. For more information, see Limits.
For DataWorks Basic Edition, Standard Edition, and Professional Edition, set `qps.limit` to 5. For Enterprise Edition, set `qps.limit` to 20.
Note: Avoid running multiple import tools at the same time.
2.6 DataWorks node type ID settings
In DataWorks, some node types are assigned different TypeIds in different regions. The actual TypeID depends on the DataWorks Data Development interface. This characteristic mainly applies to database nodes. For more information, see Database nodes.
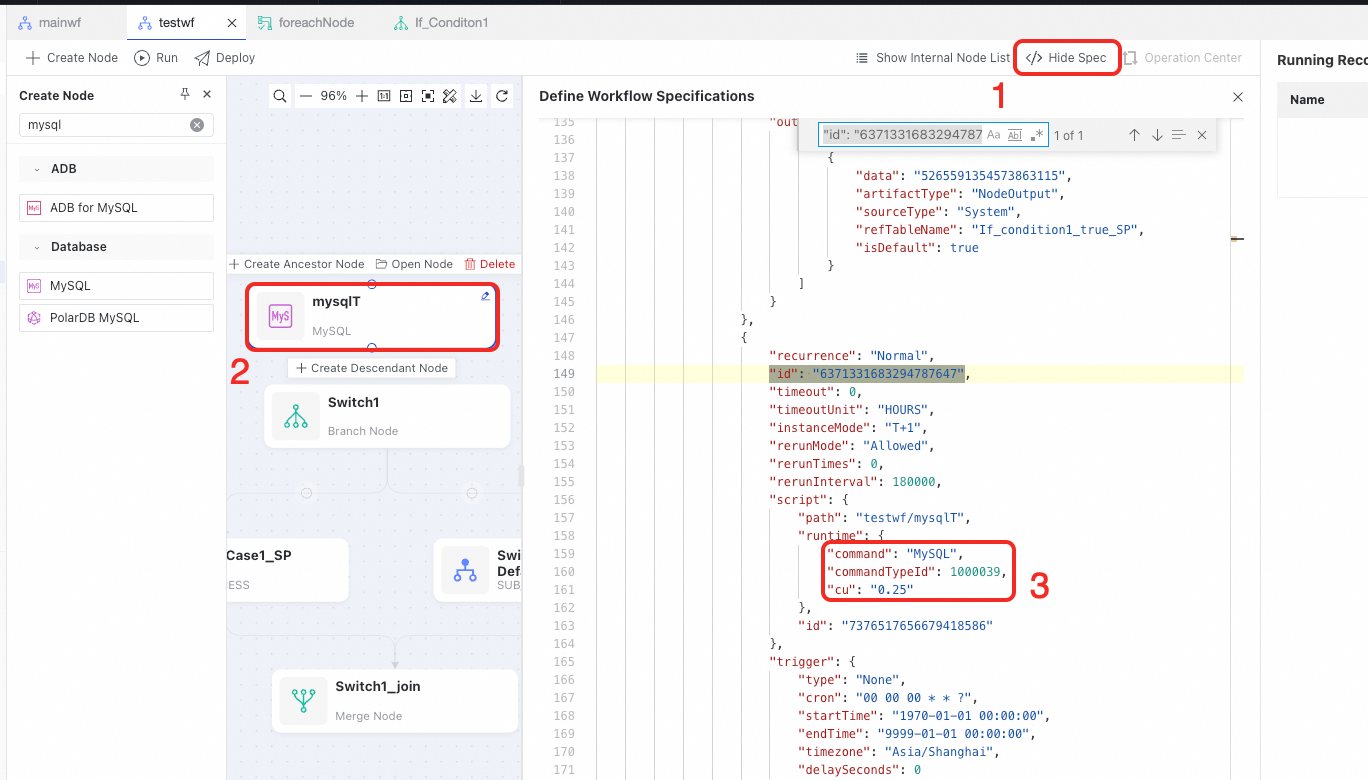
For example, the NodeTypeId for a MySQL node is 1000039 in the Hangzhou region and 1000041 in the Shenzhen region.
To adapt to these differences across DataWorks regions, the tool provides a configurable method that lets you configure the node TypeId table that the tool uses.
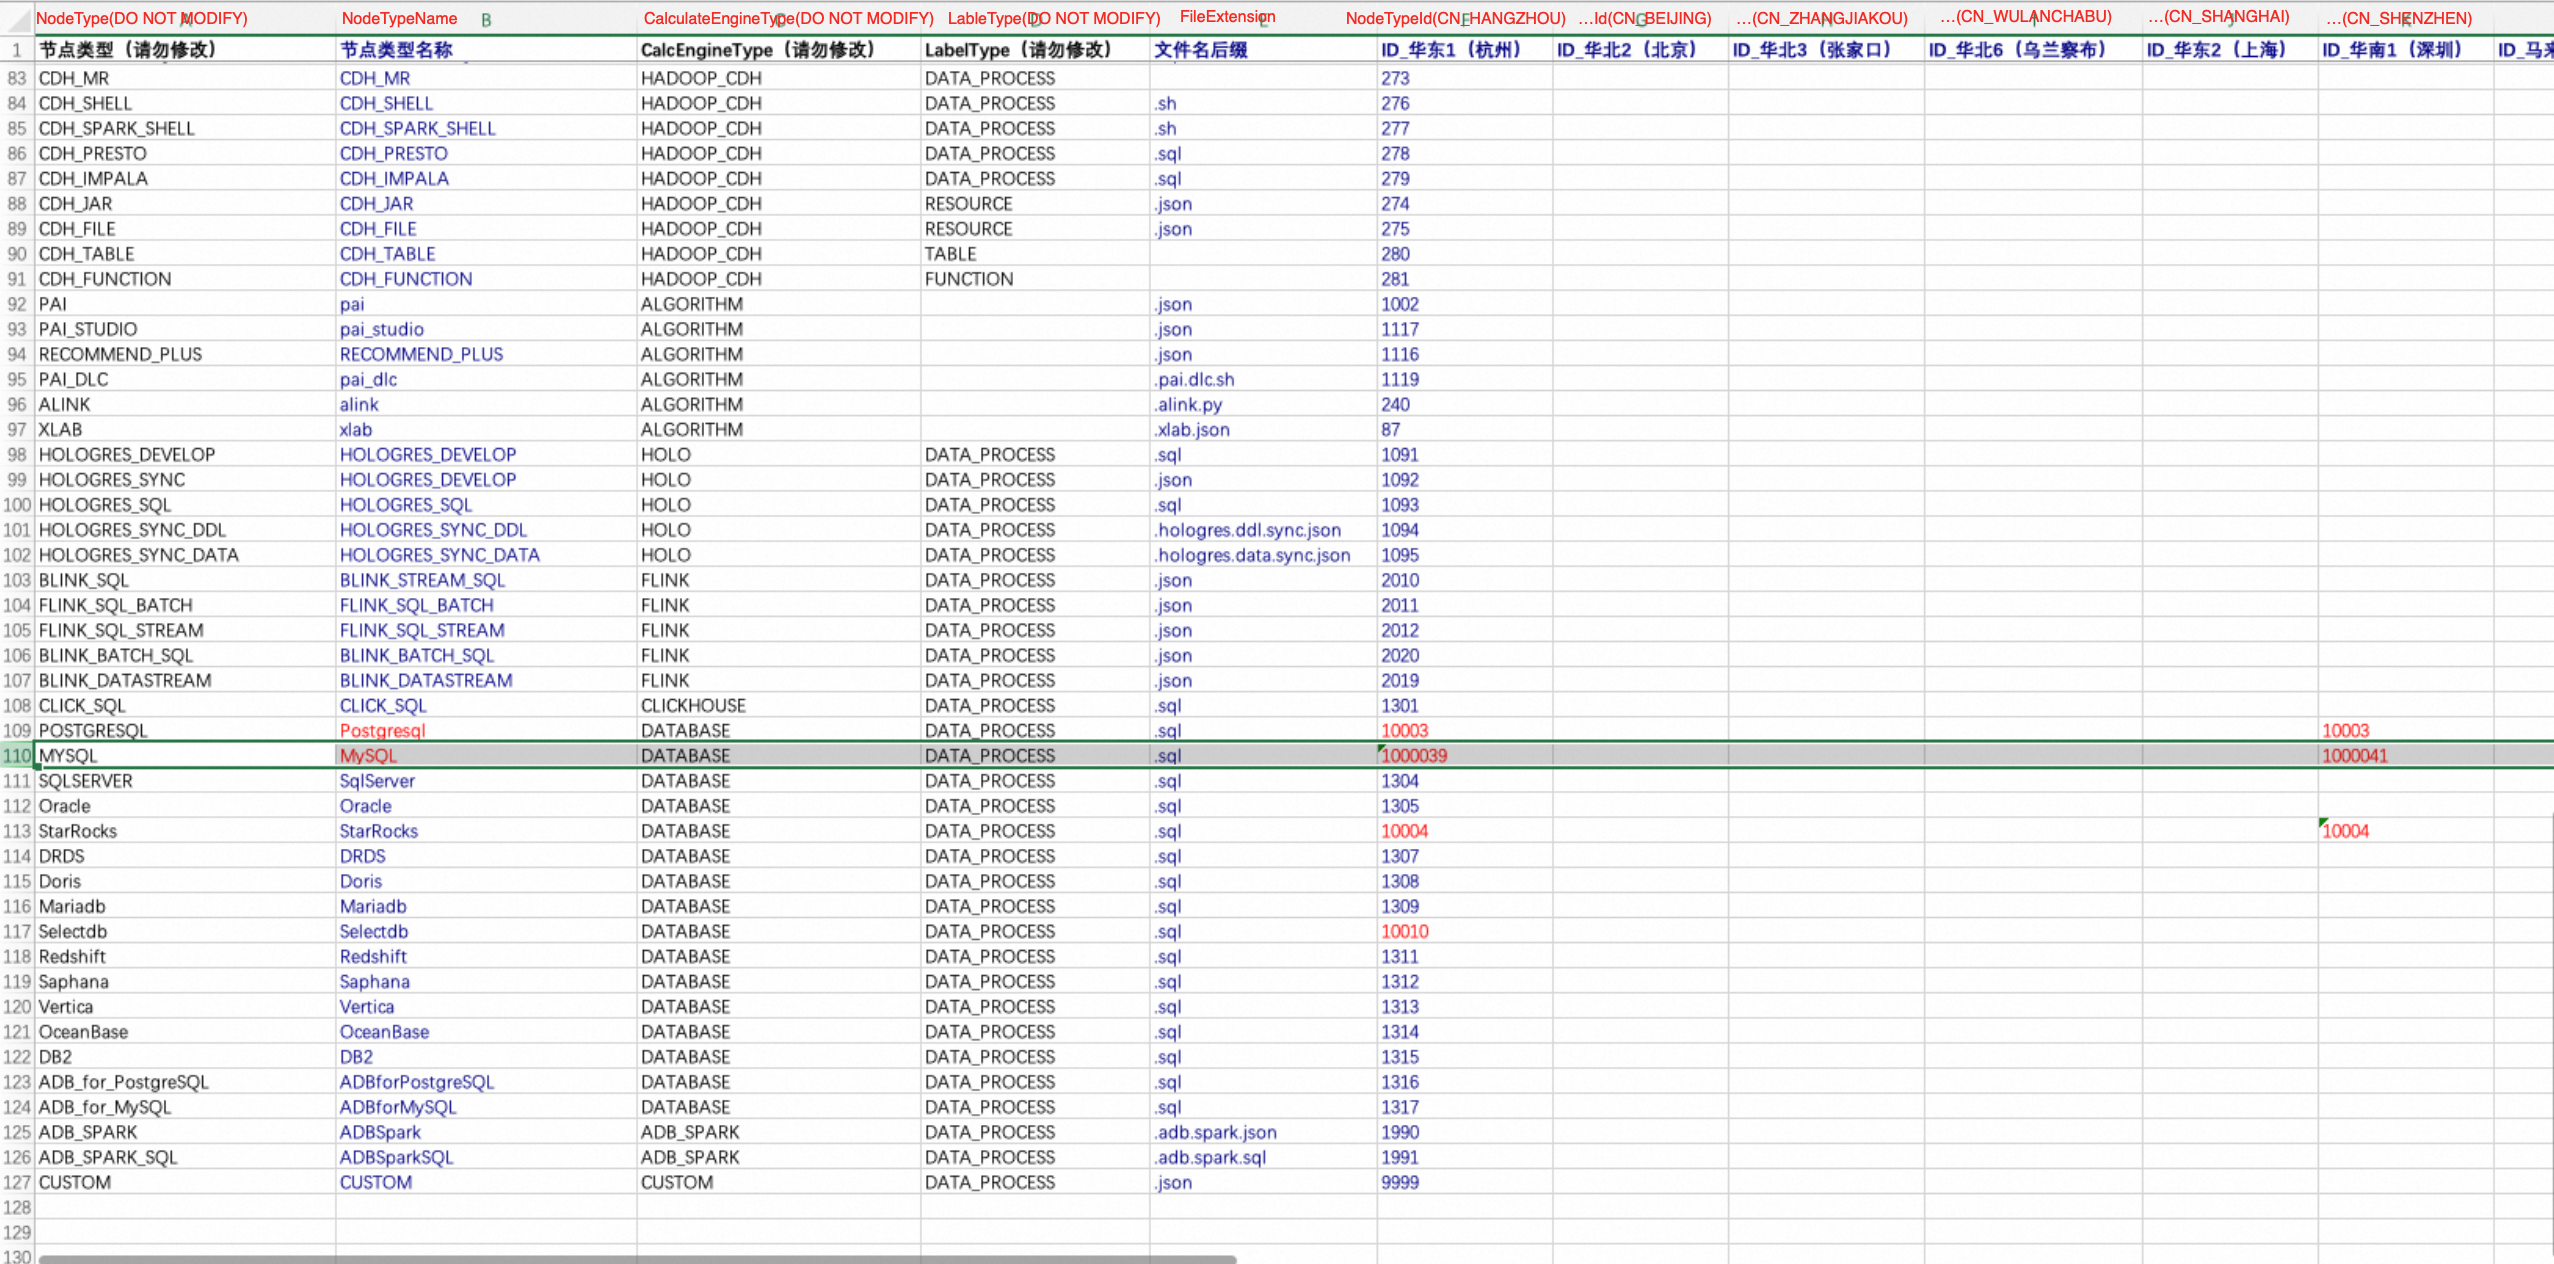
The table is imported using a configuration item in the import tool:
"conf": {
    "dataworks.node.type.xls": "/Software/bwm-client/conf/CodeProgramType.xls" // Path to the DataWorks node type table
 }
To obtain the node type ID from the DataWorks Data Development interface, create a workflow. In the workflow, create a node. After you click Save, view the workflow's Spec.
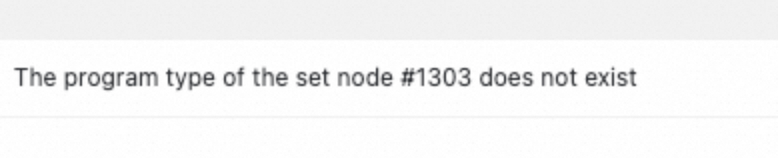
If the node type is configured incorrectly, the following error is reported when the workflow is published:
3. Run the DataWorks import tool
Call the import tool from the command line. The command is as follows:
sh ./bin/run.sh write \
-c ./conf/<your_config_file>.json \
-f ./data/2_ConverterOutput/<conversion_result_output_package>.zip \
-o ./data/4_WriterOutput/<import_result_storage_package>.zip \
-t dw-newide-writer
In the command, `-c` specifies the path to the configuration file, `-f` specifies the storage path for the ConverterOutput package, `-o` specifies the storage path for the WriterOutput package, and `-t` specifies the name of the submission plugin.
For example, if you want to import Project A into DataWorks:
sh ./bin/run.sh write \
-c ./conf/projectA_write.json \
-f ./data/2_ConverterOutput/projectA_ConverterOutput.zip \
-o ./data/4_WriterOutput/projectA_WriterOutput.zip \
-t dw-newide-writer
The import tool prints process information as it runs. Check for errors during the process. After the import is complete, statistics for successful and failed imports are printed to the command line. Note: The failure of some node imports does not affect the overall import process. If a few nodes fail to import, you can manually modify them in DataWorks.
4. View the import results
After the import is complete, you can view the results in DataWorks. During the import, you can also monitor the process as workflows are imported one by one. If you find a problem and need to stop the import, you can run the `jps` command to find `BwmClientApp` and then run the `kill -9` command to stop the import.
5. Q&A
5.1 The source is under continuous development. How are these increments and changes submitted to DataWorks?
The migration tool operates in Overwrite mode. You can rerun the export, conversion, and import processes to submit incremental changes from the source to DataWorks. Note that the tool matches workflows by their full path to decide whether to create or update them. To migrate changes, do not move the workflows.
5.2 The source is under continuous development, and workflows on DataWorks are being modified and governed at the same time. Will incremental migration overwrite the changes on DataWorks?
Yes, it will. The migration tool operates in Overwrite mode. We recommend that you complete the migration before you make further modifications in DataWorks. Alternatively, you can migrate in batches. After a batch of workflows is migrated and you confirm that they will not be overwritten again, you can start modifying them in DataWorks. Different batches do not affect each other.
5.3 The entire package takes too long to import. Can I import only a part of it?
Yes, you can. You can manually trim the package to import only a part of it. In the `data/project/workflow` folder, keep the workflows that you want to import and delete the others. Recompress the folder into a ZIP package, and then run the import tool. Note: Workflows with mutual dependencies must be imported together. Otherwise, the node lineage between the workflows is lost.