Resource scheduling
This topic describes common issues related to resource scheduling.
1. The resource scheduling dashboard displays no data or the display time is not updated
4. A "resource waiting" message is displayed when running a task
7. Auto rerun upon failure is configured, but is not triggered after a task times out
The resource scheduling dashboard displays no data or the display time is not updated
Check whether the Prometheus component is installed and whether the connection to Prometheus is functioning properly.
If the Prometheus component is not installed, contact the Dataphin deployment team. If the component is installed but the dashboard still shows an outdated time range, there may be a connection issue with Prometheus. Contact the Dataphin O&M team for troubleshooting, or determine whether a connection issue exists by following these steps:
Log on to the Dataphin cluster.
Run the
kubectl get pods -n dataphin | grep rscommand to locate the rs pod.Run the
kubectl describe pod <pod_name> -n dataphincommand to identify the primary rs pod.You can check the `labels` field to determine if the status of
dataphin-rs-scheduler-rpc-serviceisactive. A status ofactiveindicates that the pod is the primary pod, and a status ofstandbyindicates that it is the secondary pod.Run the
kubectl exec -it <pod_name> -n dataphin -- bashcommand to log on to the primary rs pod.Run the
cd /home/admin/logs/dataphin-rscommand to navigate to the rs log folder.Check the log for information about Prometheus connection issues. You can search by running the
grep "failed to connect to" <log_file>command. If the log contains references to Prometheus, a connection issue has occurred.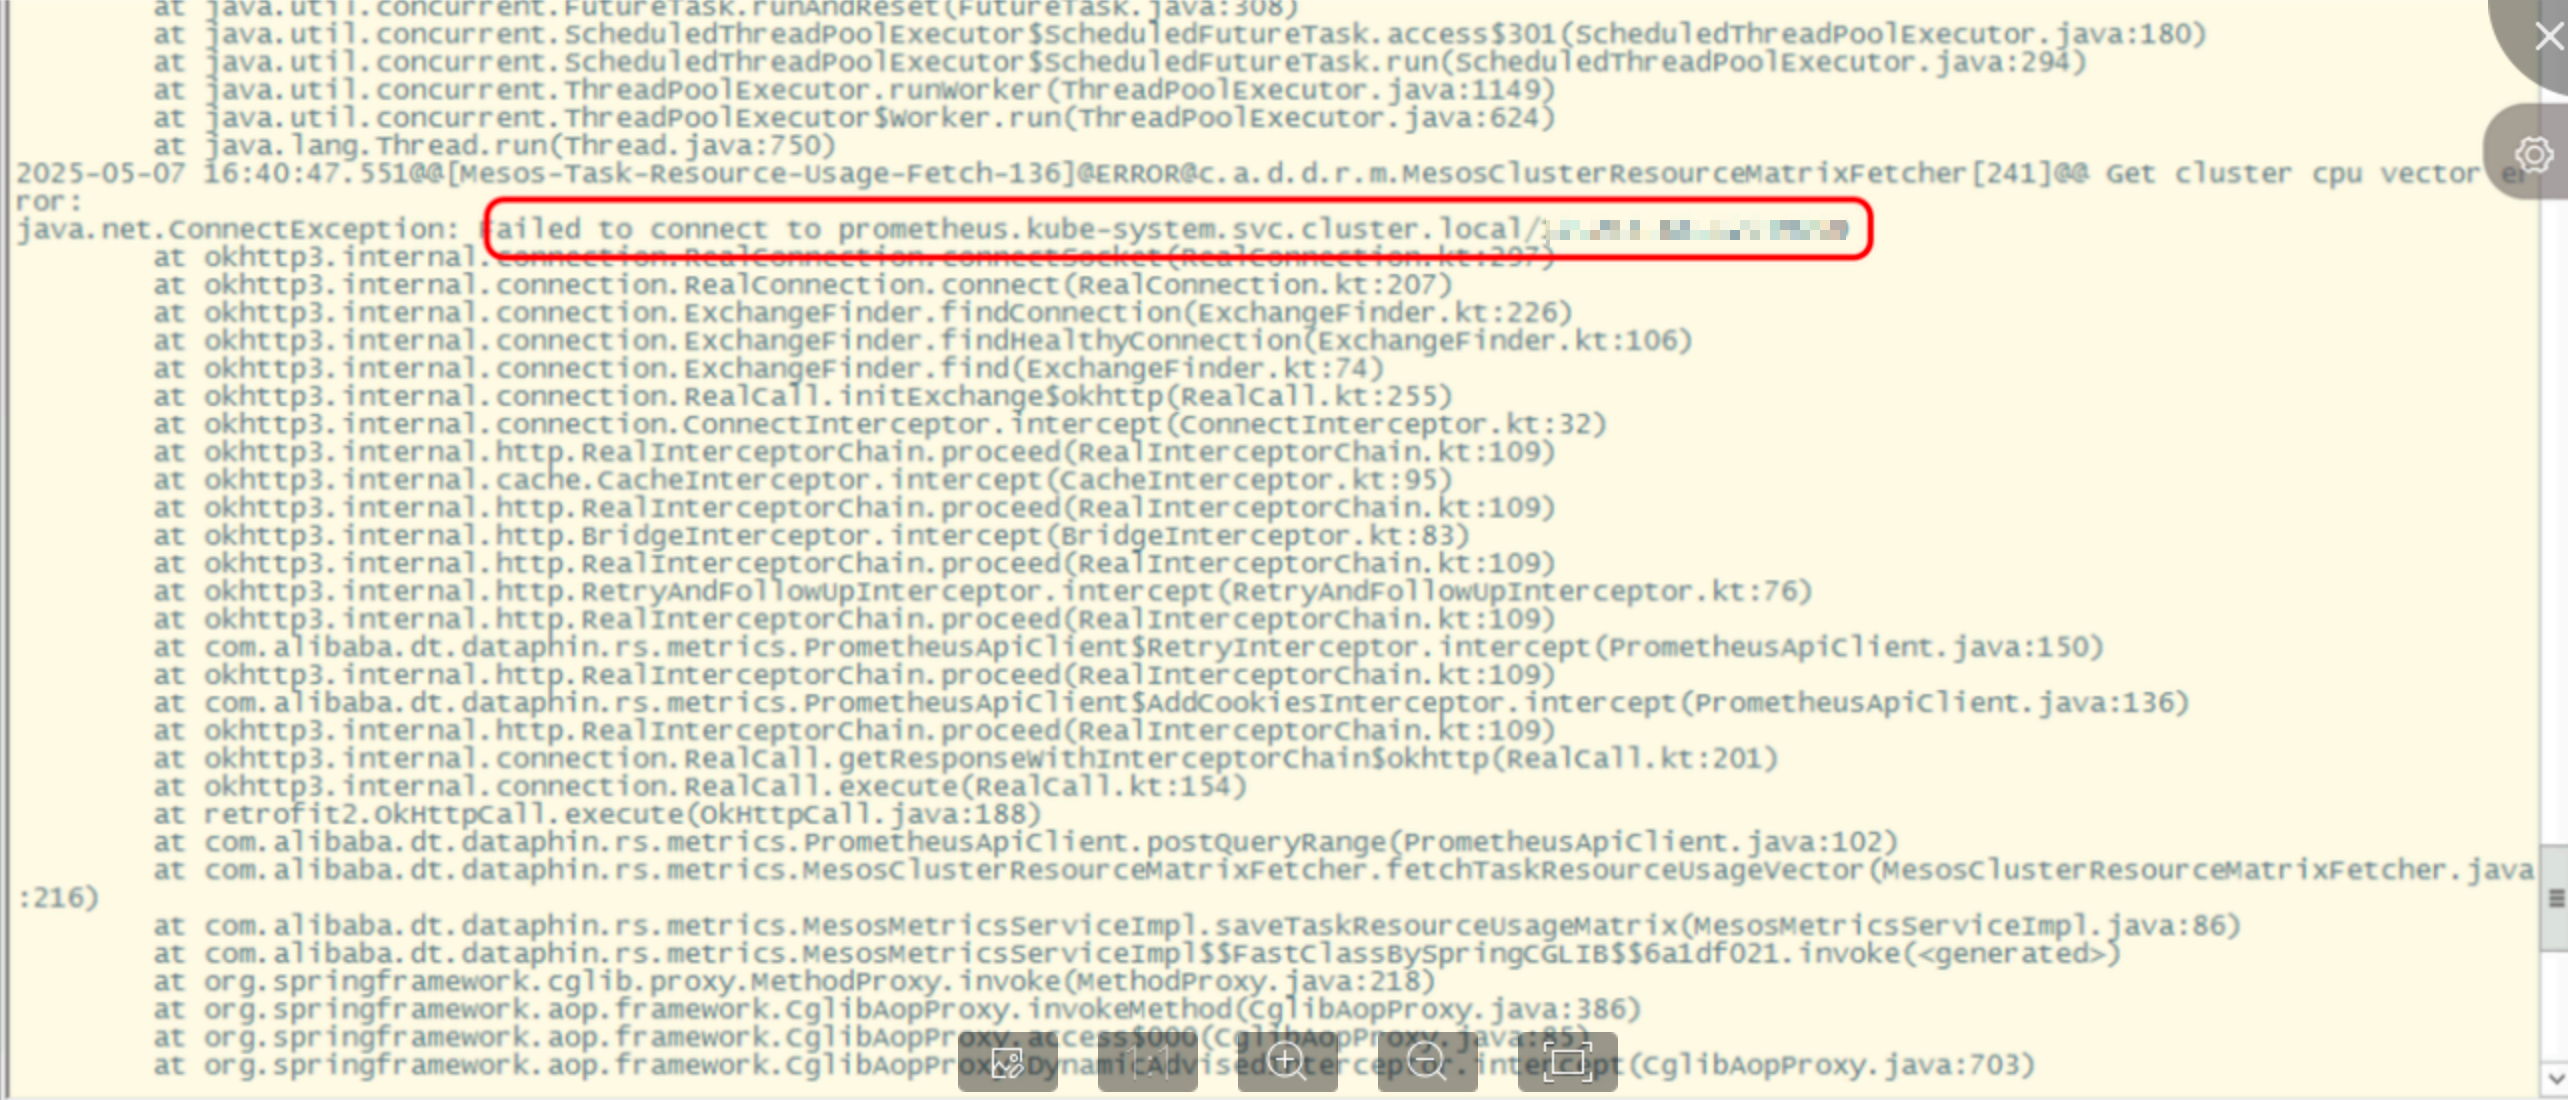
A task is executed again after it runs successfully
Check whether the task has an upstream dependency. If an upstream dependency exists, rerunning the upstream task triggers the downstream task to run again.
The Resource Settings page is not displayed
After you import the license, the Resource Settings page becomes available under Management Hub > System Settings.
A "resource waiting" message is displayed when running a task
Check the following conditions in sequence:
Many tasks are running in the current resource group.
Many large, long-running tasks are consuming resources in the resource group.
Verify that the settings for the current resource group are correct. You can configure the resource group in Management Hub > System Settings > Resource Settings.
This indicates whether the resource configuration for the current tenant is valid. If the resource values for the tenant change, the tenant's resource group is updated accordingly.
For example, if the last message in the operational log resembles Sending to agent e405****-****-****-****-****2fc2, the task was successfully sent to the scheduling cluster. However, an issue may have occurred when creating the task pod in the scheduling cluster. Possible causes include the following:
The scheduling cluster lacks sufficient remaining resources to create a new task pod.
The scheduling cluster may have a fault. Common issues include abnormal network plugins and clock problems.
Suggestions for insufficient tenant resources
Stop low-priority tasks in the resource group to release resources.
Increase the allocation ratio for the tenant's resource group.
Schedule tasks during off-peak hours to avoid resource contention.
Optimize the task's resource configuration based on its actual usage. You can view task resource usage on the resource dashboard.
Suggestions for insufficient cluster resources
Stop low-priority tasks in the resource group to release resources.
Schedule tasks during off-peak hours to avoid resource contention.
Optimize the task's resource configuration based on its actual usage. You can view task resource usage on the resource dashboard.
Scale out the cluster resources.
A "resource waiting" message is displayed when running a shared task, but resources are sufficient
If resources are sufficient but a "resource waiting" message appears, the issue may stem from the concurrency limit for shared tasks. If the number of concurrent shared tasks exceeds the configured limit, new tasks are blocked and enter a waiting state.
The concurrency limit varies by shared task type.
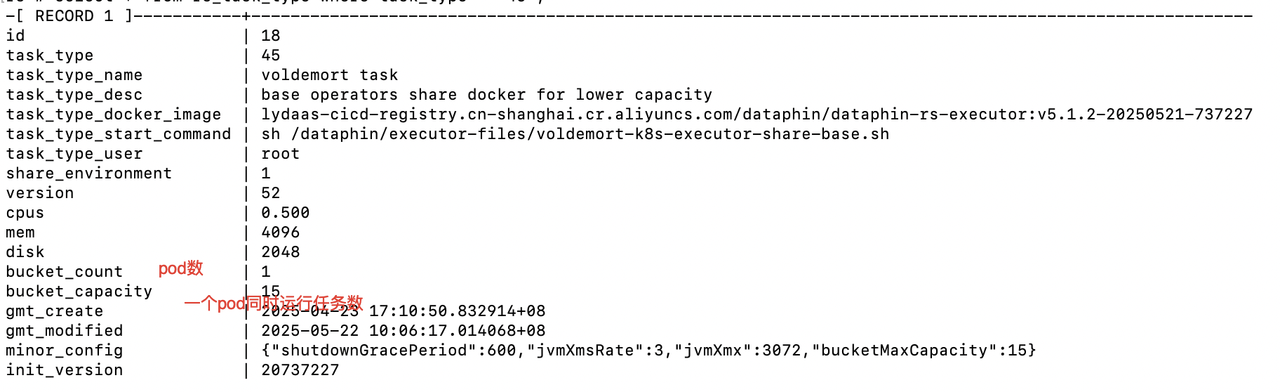
Default for SQL tasks: By default, one shared container pod is created. A single shared container pod can run 200 tasks concurrently.
Default for Python and Shell tasks: By default, one shared container pod is created. A single shared container pod can run 15 tasks concurrently.
You can adjust the number of shared container pods and the number of tasks that can run concurrently in each shared container pod as needed.
Do the resource-consuming instances in the operational diagnostics belong to the current resource group or the current tenant?
The resource-consuming instances in the operational diagnostics belong to the current tenant.
Auto rerun upon failure is configured, but is not triggered after a task times out
By default, a task timeout does not trigger an auto rerun upon failure. To enable auto rerun for timed-out tasks, go to O&M > Global Configuration > Runtime Configuration > Rerun Configuration and turn on the switch.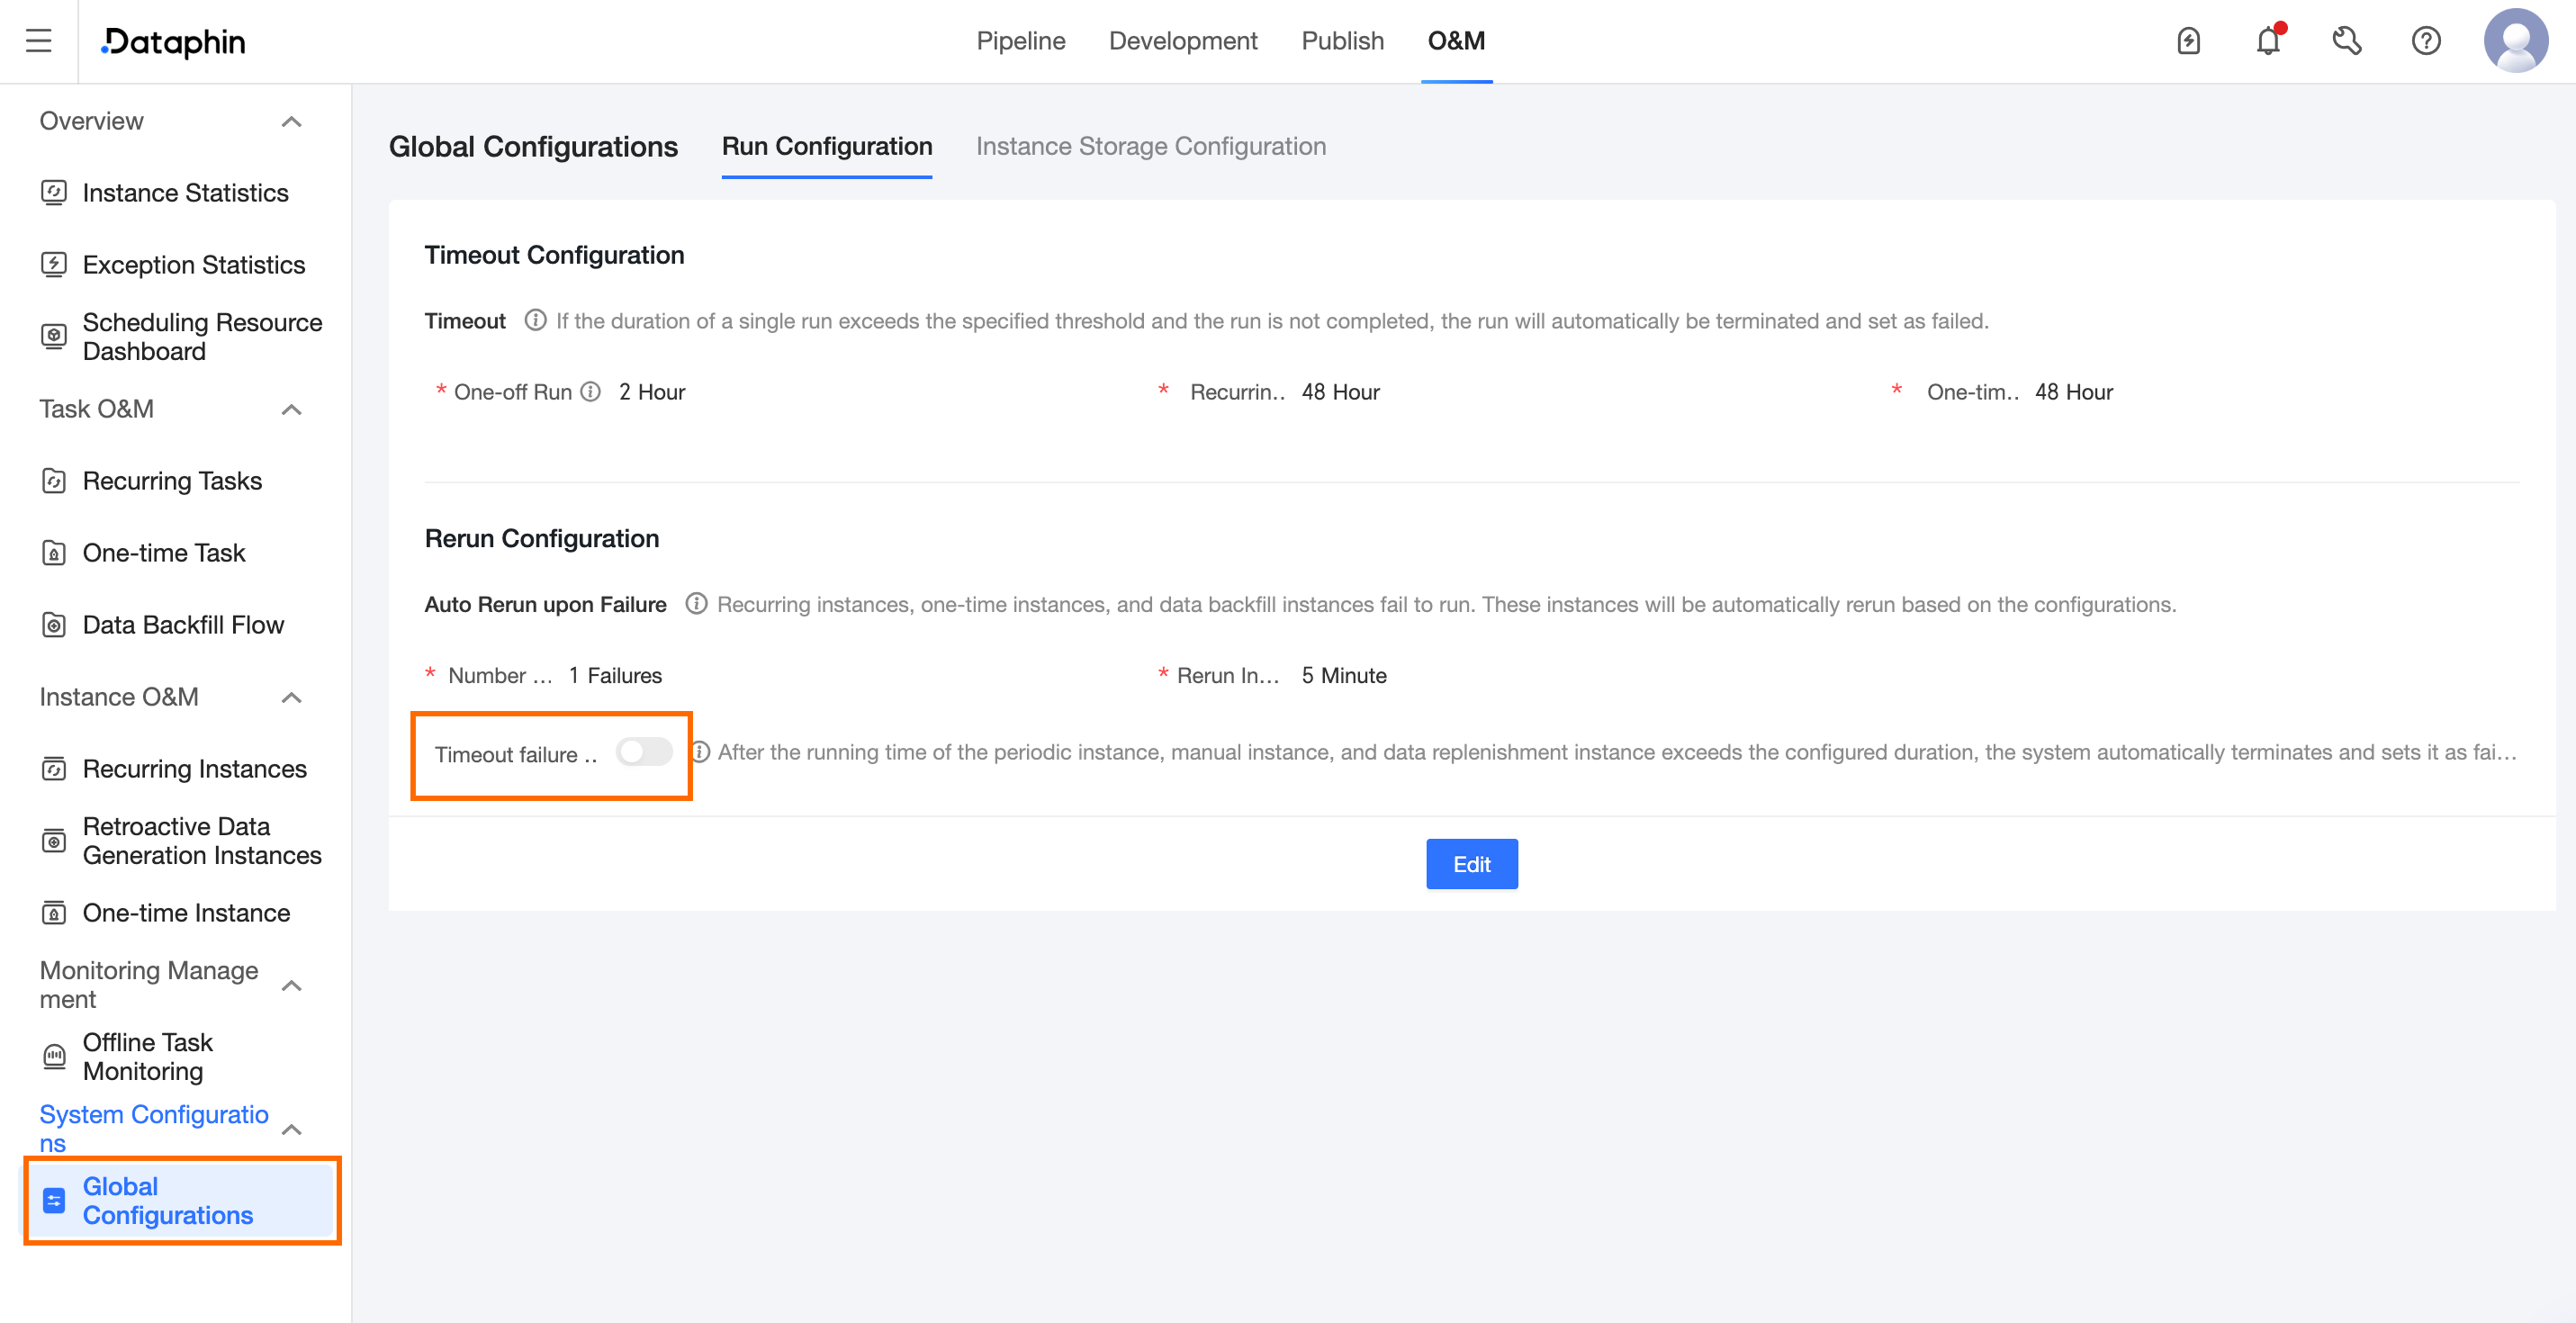
Explanation of resources for running offline tasks
For more information about resources for running offline tasks, see Task execution resources.
For example, for a shared Python task type that starts 20 pods, with each pod processing 50 tasks, the required resources are calculated as follows.
The resources consumed by one pod consist of two parts: base resources and task resources. The base resources are 0.5 cores and 4096 MB (4 GB). The default resources for a Python task are 0.1 cores and 256 MB. Therefore, the total resources required for one pod are 0.6 cores and 4352 MB. If you deploy 20 pods, the required resources are 20 × 0.6 cores = 12 cores and 20 × 4352 MB = 87040 MB (85 GB).
A "503 Service Temporarily Unavailable" error is returned when querying the instance list on the O&M page
First, check whether the request is blocked by a Web Application Firewall (WAF). A WAF is a network security tool used to detect and block malicious traffic, such as SQL injection and cross-site scripting (XSS) attacks.
Timestamps in the operational log appear out of order
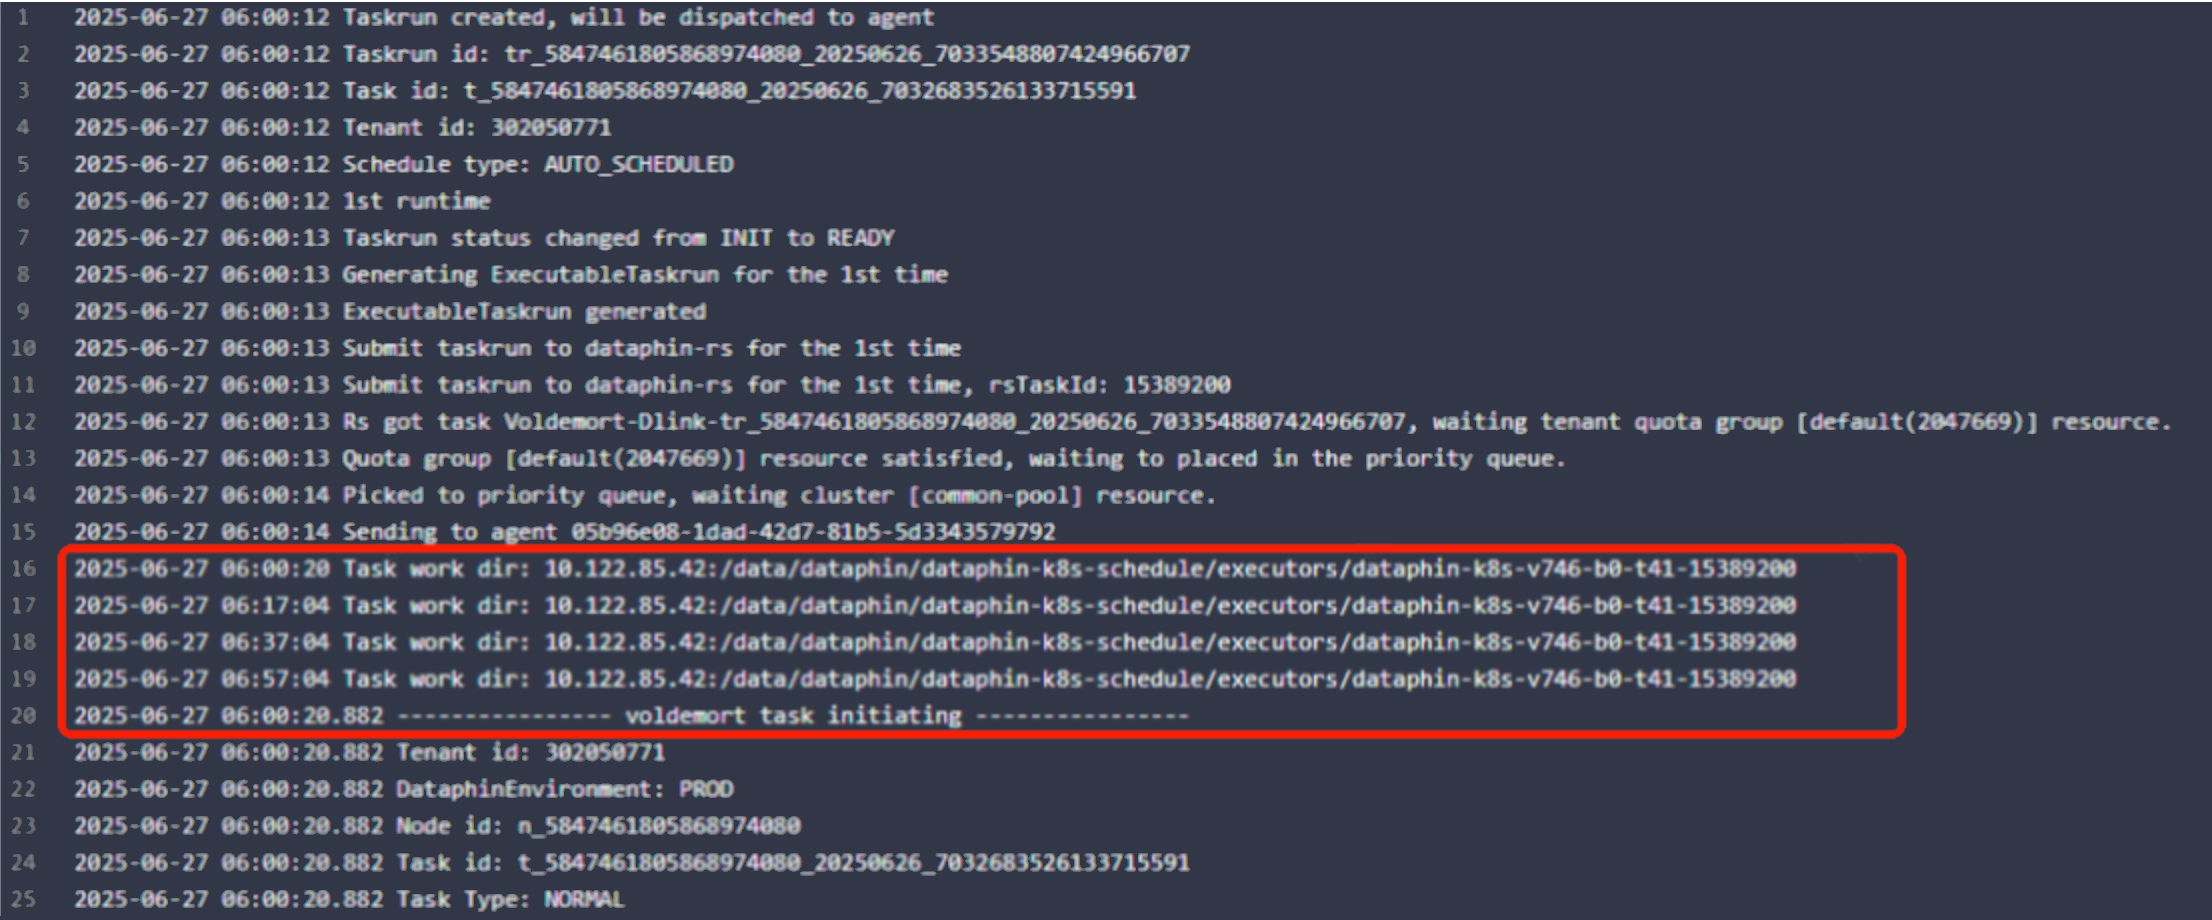
The timestamps are not actually out of order. The operational log combines entries from three stages. The middle portion contains logs periodically polled from the server-side. Logs from the three stages are not merged and sorted together by timestamp.
Resource annotations specified in the code are commented out but are still included in the statistics for task optimization suggestions
Commented-out resource annotations remain effective. To exclude them from the statistics, you must delete the annotations entirely.
After an upgrade, a previously working OpenAPI call fails with a "tenantId cannot be empty" error
This error occurs if you upgrade from a version earlier than Dataphin V3.0. Starting with Dataphin V3.x, the tenantId parameter is required.
A task is configured for normal scheduling but appears as paused on the auto triggered task page in O&M
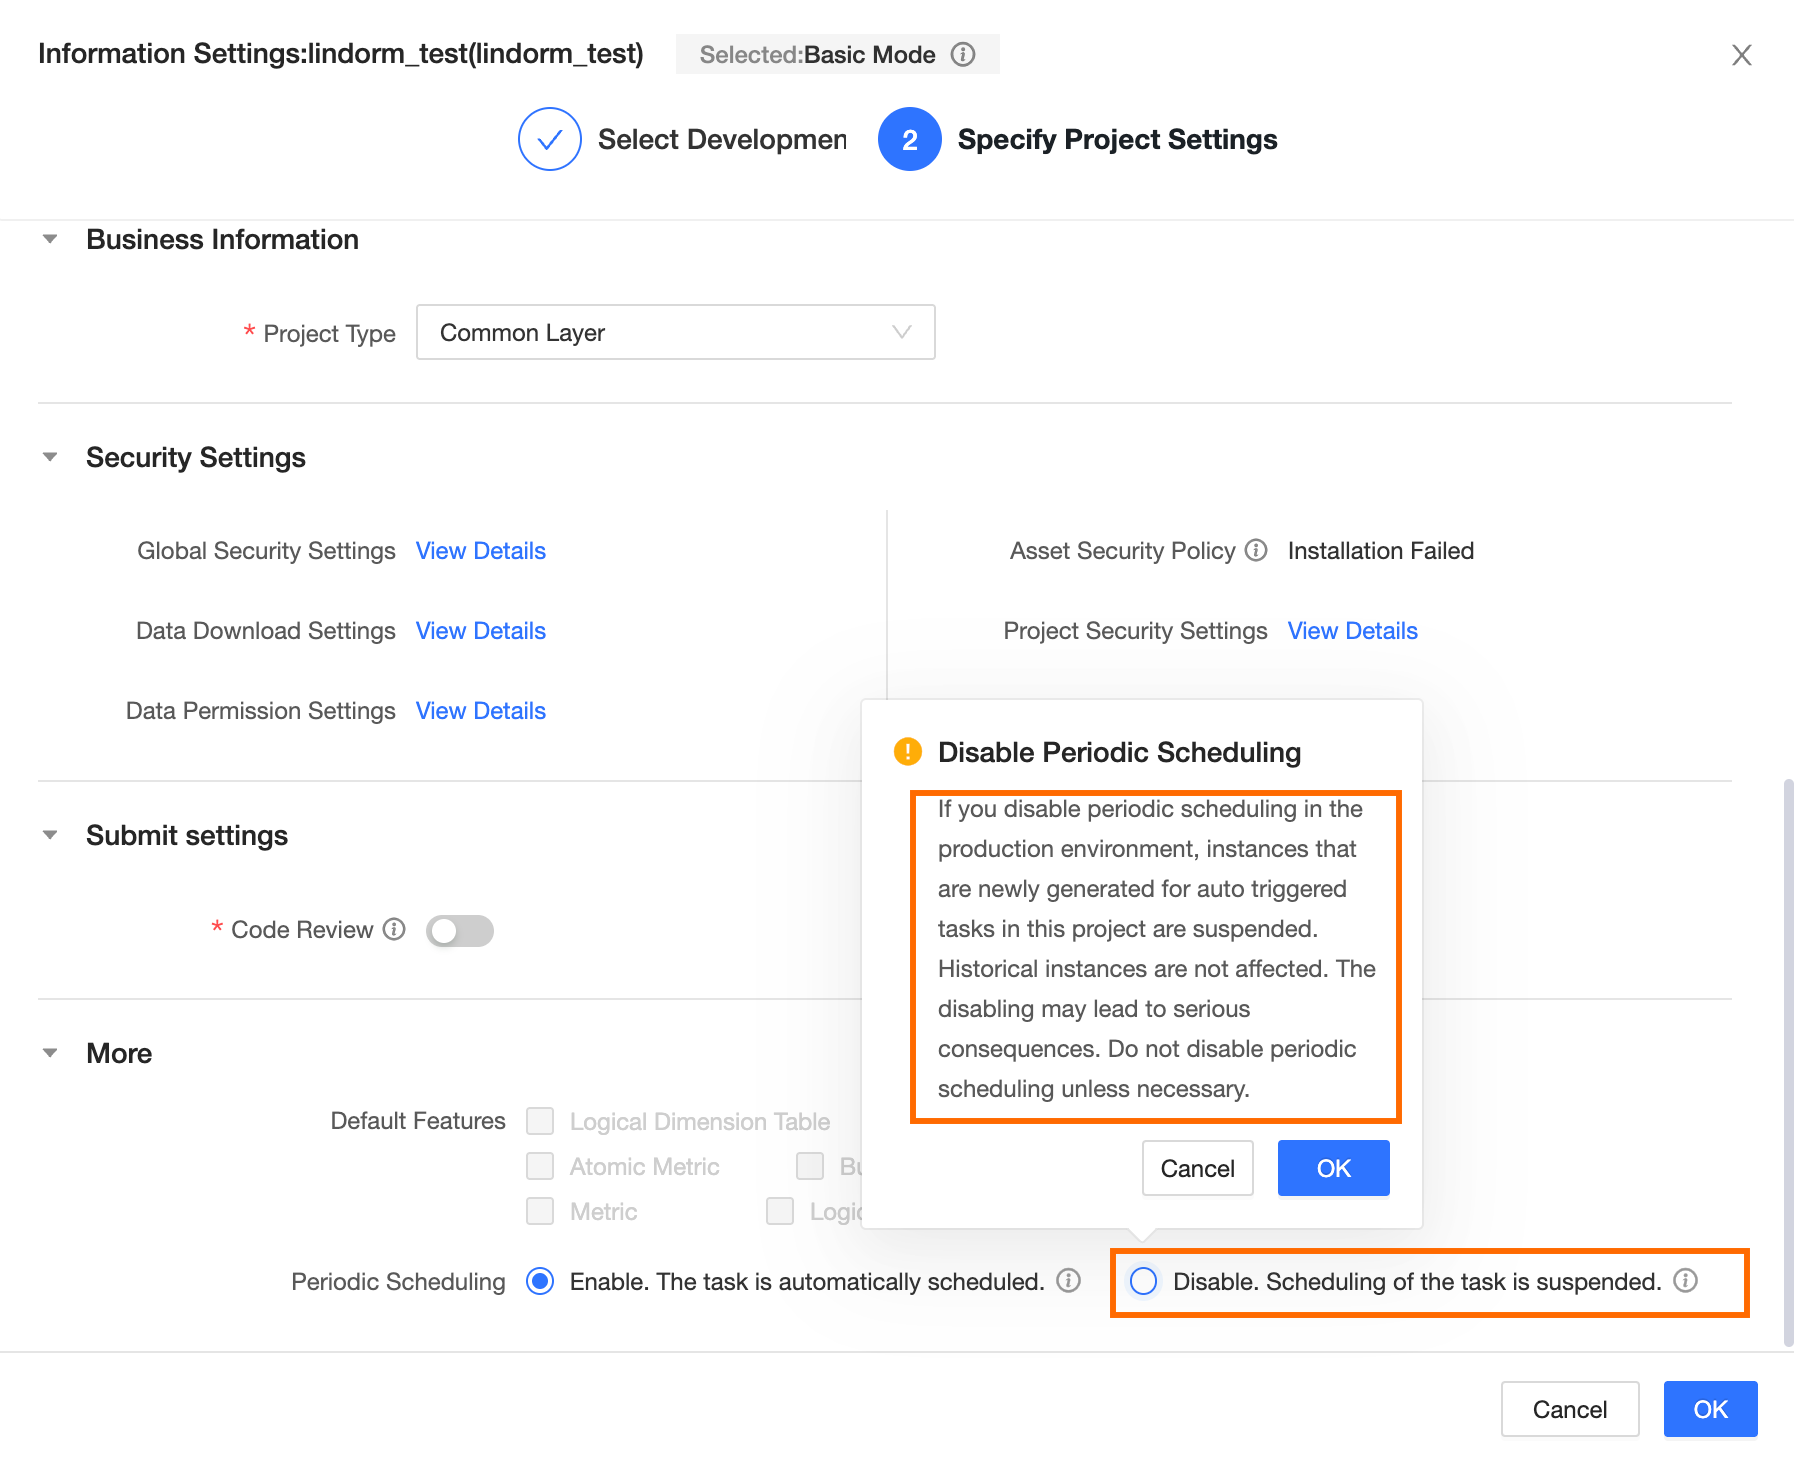
Check whether the periodic scheduling setting for the project containing the task is set to Disabled, skip task execution. Change this setting to Enabled, schedule tasks automatically.