Configure the Amazon Redshift output component
The Amazon Redshift output component writes data to an Amazon Redshift data source. When you synchronize data to Amazon Redshift, you must configure this component as the target. This topic describes how to configure the Amazon Redshift output component.
Prerequisites
You have created an Amazon Redshift data source. For more information, see Create an Amazon Redshift data source.
The account that you use to configure the Amazon Redshift output component has write-through permissions on the data source. If the account does not have the permissions, request them. For more information, see Request, renew, and return data source permissions.
Procedure
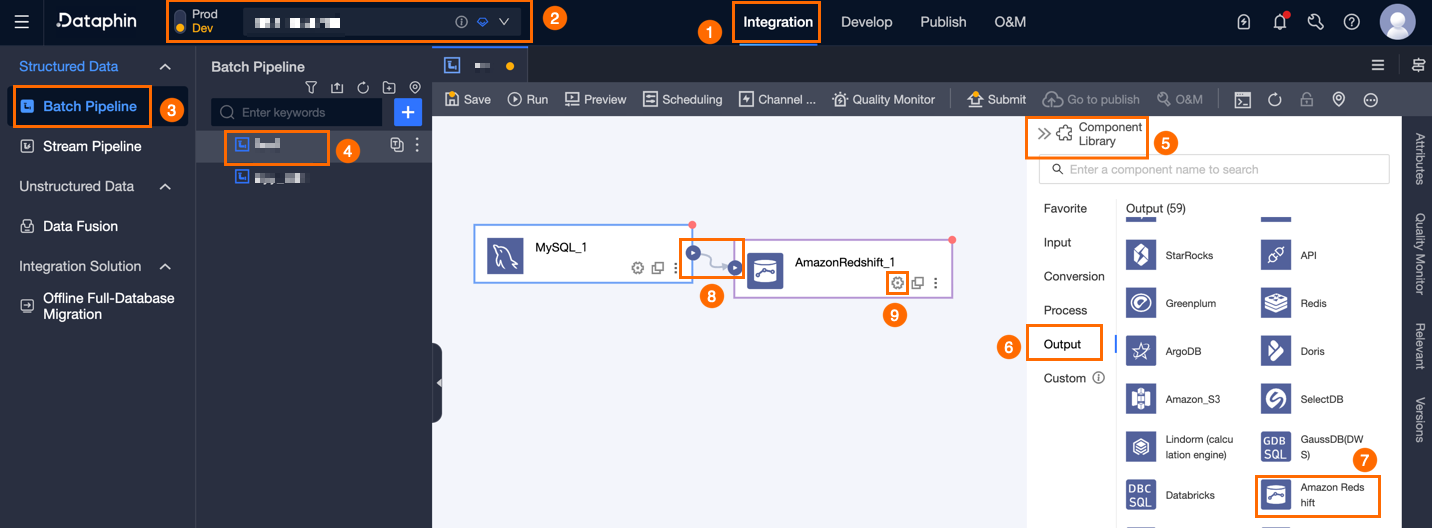
In the top menu bar of the Dataphin home page, choose R&D > Data Integration.
In the top menu bar of the integration page, select a project. If you use the Dev-Prod mode, you must also select an environment.
In the navigation pane on the left, click Batch Pipeline. In the Batch Pipeline list, click the batch pipeline that you want to develop to open its configuration page.
In the upper-right corner of the page, click Component Library to open the Component Library panel.
In the navigation pane on the left of the Component Library panel, choose Output. Find the Amazon Redshift component in the output component list on the right and drag it to the canvas.
You can click and drag the
 icon of the target input, transform, or flow component to connect it to the current Amazon Redshift output component.
Click the
 icon on the Amazon Redshift output component card to open the Amazon Redshift Output Configuration dialog box.
In the Amazon Redshift Output Configuration dialog box, configure the following parameters.
Parameter
Description
Basic Settings
Step Name
The name of the Amazon Redshift output component. Dataphin automatically generates a step name. You can also change the name as needed. The name must meet the following requirements:
Can contain only Chinese characters, letters, underscores (_), and digits.
Cannot exceed 64 characters in length.
Datasource
The drop-down list displays all Amazon Redshift data sources, including those for which you have write-through permissions and those for which you do not. Click the
 icon to copy the current data source name.
For data sources where you do not have write-through permissions, click Request to request the permissions. For more information, see Request data source permissions.
If you do not have an Amazon Redshift data source, click the
 icon to create one. For more information, see Create an Amazon Redshift data source.
Time Zone
Time-formatted data is processed based on the current time zone. By default, this is the time zone configured in the selected data source and cannot be changed.
NoteFor nodes created before version 5.1.2, you can select Data source default configuration or Channel configuration time zone. The default is Channel configuration time zone.
Data source default configuration: The default time zone of the selected data source.
Channel configuration time zone: The time zone configured in Properties > Channel Configuration for the current integration node.
Schema (Optional)
You can select tables across schemas. Select the schema where the table resides. If you do not specify a schema, the schema configured in the data source is used by default.
Table
Select the target table for the data output. You can enter a keyword to search for the table name, or enter the exact table name and click Exact Search. After you select a table, the system automatically checks the table status. Click the
 icon to copy the name of the selected table.
If no target table for data synchronization exists in the Amazon Redshift data source, you can use the one-click DDL feature to quickly generate one. The procedure is as follows:
Click One-click DDL. Dataphin automatically generates the code to create the target table. This includes the target table name (source table name by default) and field types, which are converted based on Dataphin fields.
Modify the SQL script to create the target table as needed, and then click Create. After the target table is created, Dataphin automatically uses it as the target table for the data output.
NoteIf a table with the same name exists in the development environment, an error is reported when you click Create.
If there are no matching items, you can still perform integration based on a manually entered table name.
Policy for missing production table
The policy for when a production table does not exist. You can select Do not process or Automatic creation. The default is Automatic creation. If you select Do not process, the production table is not created when the node is published. If you select Automatic creation, a table with the same name is created in the target environment when the node is published.
Do not process: If the target table does not exist, a message is displayed when you submit, but you can still publish the node. In this case, you must manually create the target table in the production environment before you can run the node.
Automatic creation: You must edit the DDL statement. The DDL statement for the selected table is filled in by default, which you can modify. Use the placeholder
${table_name}for the table name in the DDL statement. This is the only placeholder supported. It will be replaced with the actual table name during execution.If the target table does not exist, it is created based on the DDL statement. If the table creation fails, the publishing check fails. You can modify the DDL statement based on the error message and try to publish again. If the target table already exists, the DDL statement is not executed.
NoteThis parameter is supported only in projects that use the Dev-Prod mode.
Batch write data volume (Optional)
The amount of data to write in a single operation. You can also set Batch write count. The system writes data when either limit is reached. The default is 32 MB.
Batch write count (Optional)
The default is 2048 records. Data is written using a batching strategy. The parameters for this strategy are Batch write count and Batch write data volume.
When the accumulated data reaches either of the set limits (the data volume or the record count), the system considers the batch full and writes it to the target at once.
Set the batch write data volume to 32 MB. You can adjust the batch insert count based on the actual size of a single record. A large value is usually set to take full advantage of batch writing. For example, if a single record is about 1 KB, you can set the batch insert size to 16 MB. In this case, set the batch insert count to a value greater than 16 MB divided by 1 KB (which is 16,384). For example, set it to 20,000. With this configuration, the system triggers a batch write operation based on the batch insert size. A write action is performed each time the accumulated data reaches 16 MB.
Pre-SQL statement (Optional)
The SQL script to execute on the database before data import.
For example, to ensure continuous service availability, you can create a target table Target_A before the current step writes data. Then, write data to Target_A. After the current step finishes writing, rename the continuously available service table Service_B to Temp_C. Then, rename Target_A to Service_B, and finally, delete Temp_C.
Post-SQL statement (Optional)
The SQL script to execute on the database after data import.
Field Mapping
Input Fields
Displays the input fields based on the output from the upstream component.
Output Fields
Displays the output fields. You can perform the following operations:
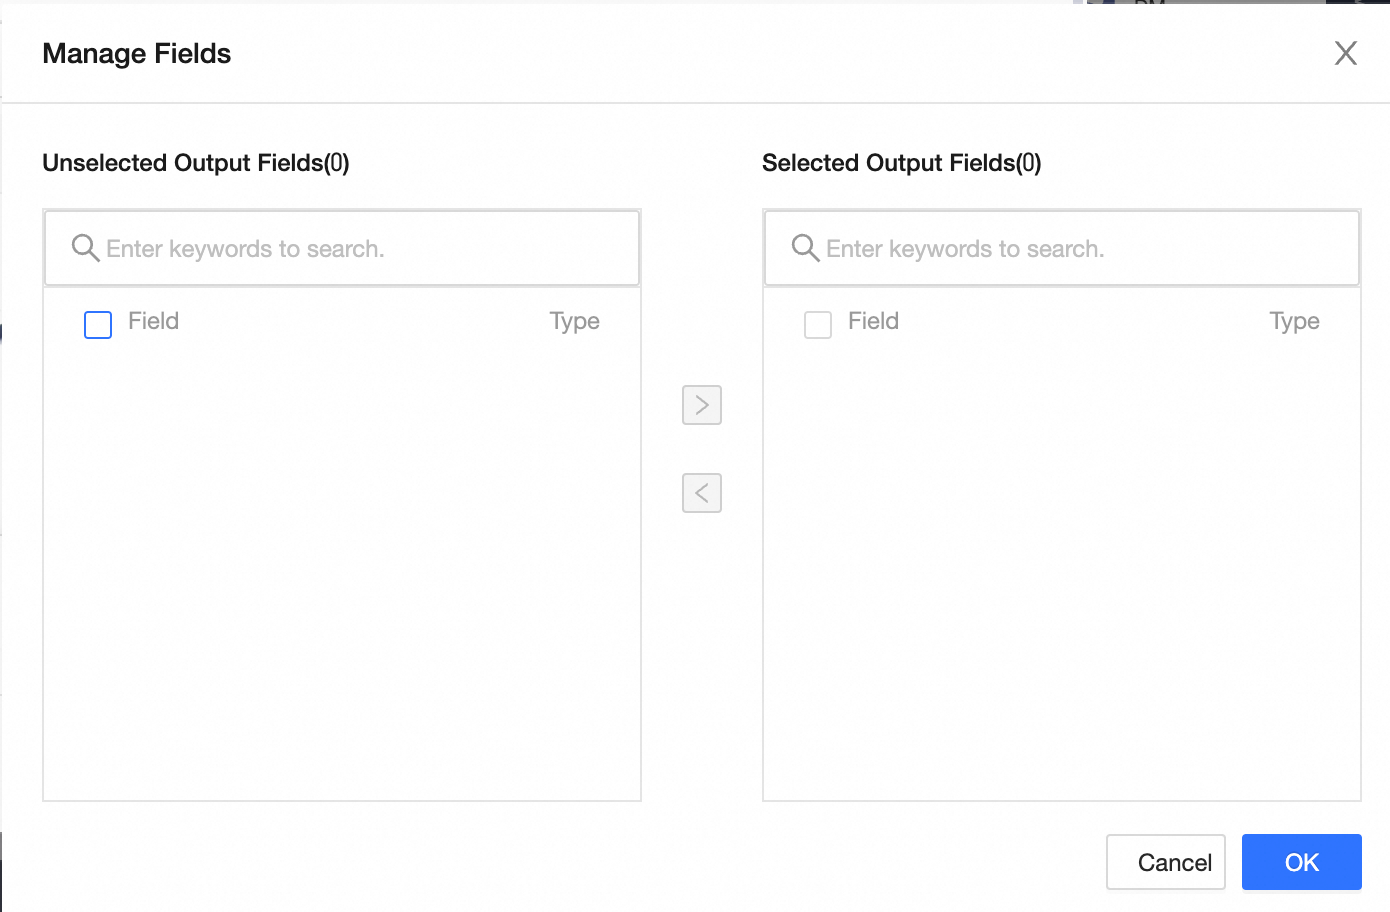
Field Management: Click Field Management to select output fields.
Click the
icon to move fields from Selected Input Fields to Unselected Input Fields.Click the
icon to move fields from Unselected Input Fields to Selected Input Fields.
Batch Add: Click Batch Add to configure fields in batches using JSON, TEXT, or DDL format.
To configure in JSON format, for example:
// Example: [{ "name": "user_id", "type": "String" }, { "name": "user_name", "type": "String" }]Notename indicates the name of the imported field, and type indicates the field type after import. For example,
"name":"user_id","type":"String"imports the field named user_id and sets its type to String.To configure in TEXT format, for example:
// Example:
user_id,String
user_name,String
The row delimiter separates the information for each field. The default is a line feed (\n). Semicolons (;) and periods (.) are also supported.
The column delimiter separates the field name from the field type. The default is a comma (,).
To configure in DDL format, for example:
CREATE TABLE tablename (
    id INT PRIMARY KEY,
    name VARCHAR(50),
    age INT
);
Create Output Field: Click + Create Output Field, enter a Column name, and select a Type. After you configure the current row, click the
icon to save.
Mapping
You can manually select field mappings based on the upstream input and the target table fields. Quick Mapping includes Map by Row and Map by Name.
Map by Name: Maps fields that have the same name.
Map by Row: Maps fields in the same row when the source and target table field names are different but the data corresponds. Only fields in the same row are mapped.
Click Confirm to complete the configuration of the Amazon Redshift output component.
 icon to copy the name of the selected table.
 icon to move fields from Selected Input Fields to Unselected Input Fields.
 icon to move fields from Unselected Input Fields to Selected Input Fields.
 icon to save.