Create a Teradata data source
By creating a Teradata data source, you can enable Dataphin to read business data from Teradata or write data to Teradata. This topic describes how to create a Teradata data source.
Background information
Teradata is a large-scale data warehouse system. If you use Teradata and want to connect it to Dataphin for data development or export Dataphin data to Teradata, you need to create a Teradata data source first. For more information about Teradata, see Teradata official website.
Permissions
Only custom global roles with the Create Data Source permission and system roles such as super administrator, data source administrator, domain architect, and project administrator can create data sources.
Procedure
In the top navigation bar of the Dataphin homepage, choose Management Center > Datasource Management.
On the Datasource page, click +Create Data Source.
On the Create Data Source page, in the Relational Database section, select Teradata.
If you have recently used Teradata, you can also select Teradata in the Recently Used section. You can also quickly search for Teradata by entering keywords in the search box.
On the Create Teradata Data Source page, configure the connection parameters.
Configure the basic information of the data source.
Parameter
Description
Datasource Name
The name must meet the following requirements:
It can contain only Chinese characters, letters, digits, underscores (_), or hyphens (-).
It cannot exceed 64 characters in length.
Datasource Code
After you configure the data source code, you can reference tables in the data source in Flink_SQL tasks by using the
data source code.table nameordata source code.schema.table nameformat. If you need to automatically access the data source in the corresponding environment based on the current environment, use the variable format${data source code}.tableor${data source code}.schema.table. For more information, see Flink_SQL task development method.ImportantThe data source code cannot be modified after it is configured.
You can preview data on the object details page in the asset directory and asset checklist only after the data source code is configured.
In Flink SQL, only MySQL, Hologres, MaxCompute, Oracle, StarRocks, Hive, SelectDB, and GaussDB data warehouse service (DWS) data sources are currently supported.
Data Source Description
A brief description of the data source. It cannot exceed 128 characters.
Data Source Configuration
Select the data source to configure:
If your business data source distinguishes between production and development data sources, select Production + Development Data Source.
If your business data source does not distinguish between production and development data sources, select Production Data Source.
Tag
You can categorize and tag data sources using tags. For information about how to create tags, see Manage data source tags.
Configure the connection parameters between the data source and Dataphin.
If you select Production + Development data source for your data source configuration, you need to configure the connection information for the Production + Development data source. If your data source configuration is Production data source, you only need to configure the connection information for the Production data source.
NoteTypically, production and development data sources should be configured as different data sources to achieve environment isolation and reduce the impact of development data sources on production data sources. However, Dataphin also supports configuring them as the same data source with identical parameter values.
Parameter
Description
JDBC URL
The format of the connection URL is
jdbc:teradata://host:port/dbname.Username, Password
The username and password used to log on to the Teradata database.
Type
Supports Directly Connectable Database and Self-managed Database On ECS (VPC). You can select and configure based on your database type and business requirements.
Directly Connectable Database: Connect to the database directly through the default scheduling cluster or registered scheduling cluster. This applies to the following scenarios: ① Public network databases, ② Databases in the same network environment as the registered scheduling cluster. If you need to add access to the whitelist, you can add the public network outbound IP address of the Dataphin default scheduling cluster: 47.102.192.174.
Self-managed Database On ECS (VPC): When the database you are using is an Alibaba Cloud database in a VPC network environment, specify the authorized IP whitelist for connection: 100.104.0.0/16.
Region: The region where the database is located. Only databases in the same region as your Dataphin instance are supported. If your Dataphin instance is in China (Shanghai), you can only select the China (Shanghai) region.
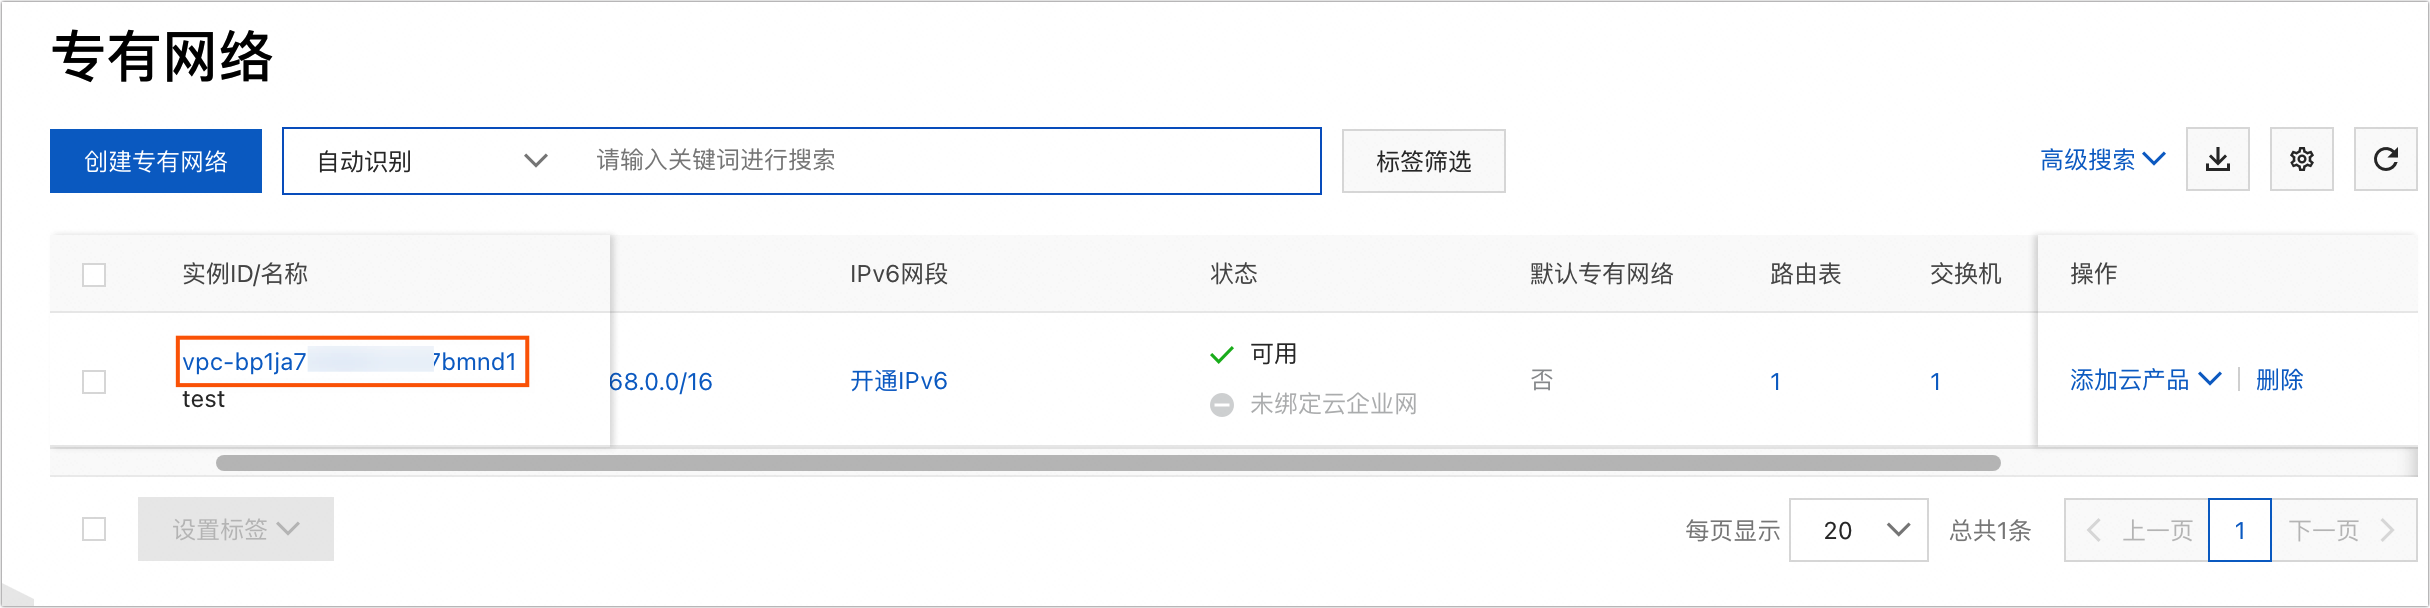
VPC ID: Enter the VPC ID of the VPC network where the ECS is located. You can log on to the Virtual Private Cloud console to view it. As shown in the following figure:
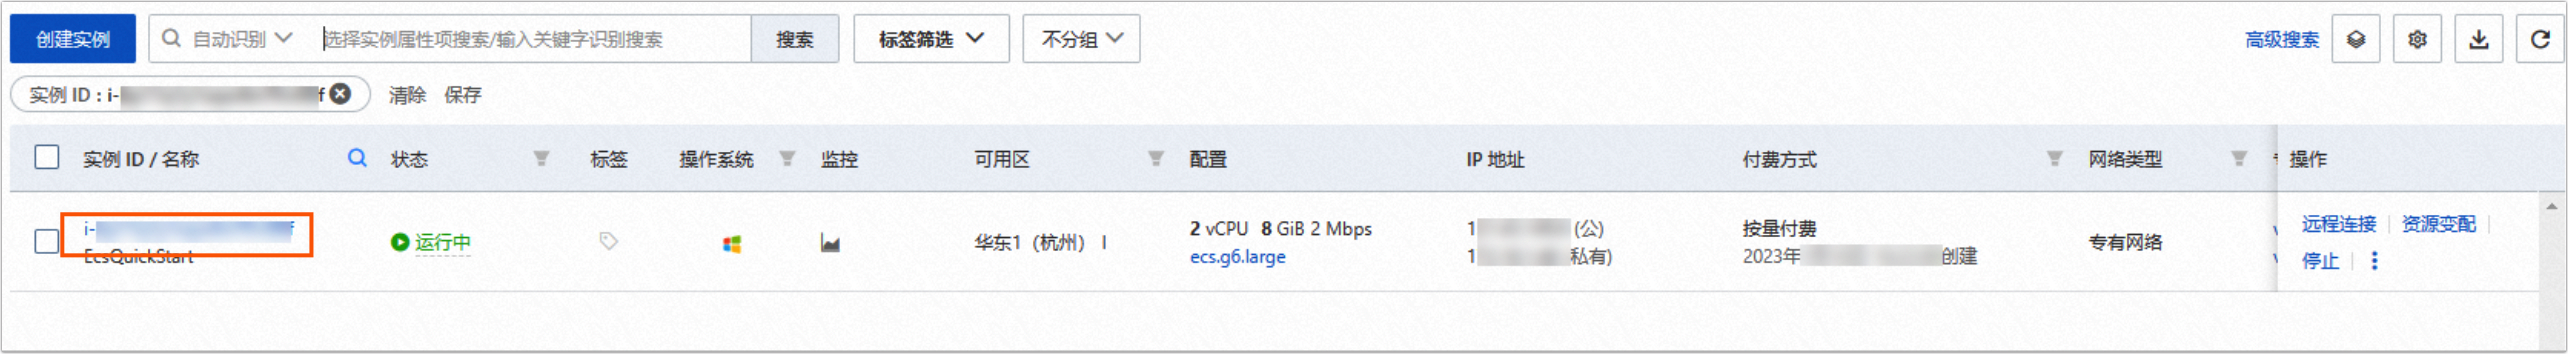
ECS ID: Enter the ECS ID of the ECS server where the database is deployed. You can log on to the ECS console to view it. As shown in the following figure:
Configure advanced settings for the connection between the data source and Dataphin.
Connection Retries: If the database connection times out, the system will automatically retry the connection until the specified number of retries is reached. If the connection still fails after the maximum number of retries, the connection is considered failed.
NoteThe default number of retries is 1, and you can configure a value between 0 and 10.
The connection retry count will be applied by default to offline integration tasks and global quality (requires the asset quality function module to be enabled). In offline integration tasks, you can configure task-level retry counts separately.
Select a Default Resource Group, which is used to run tasks related to the current data source, including database SQL, offline database migration, data preview, and more.
Click Test Connection or directly click OK to save and complete the creation of the Teradata data source.
When you click Test Connection, the system tests whether the data source can connect to Dataphin normally. If you directly click OK, the system will automatically test the connection for all selected clusters, but the data source can still be created normally even if all selected clusters fail to connect.
ImportantIf the connection test fails, you can troubleshoot based on common network connectivity issues. For more information, see Network connectivity solutions.
When the test connection reports an error
VPC_GRANT_ACCESS_API_ERROR, you can refer to Solution for VPC_GRANT_ACCESS_API_ERROR for resolution.