Develop custom component examples
This topic provides examples for developing custom input and output components.
Prerequisites
Single click Download dependency package to download the dependency package.
Add the
plugin.center.base-0.0.1-SNAPSHOT.jarfrom the downloaded file to your Maven private repository.
Background information
To use custom components, you must first create an offline custom source type and the corresponding data source.
Create an RDBMS type offline custom source type. The system will automatically generate input and output components in the open directory of the integrated pipeline component library.
For other database types, create the offline custom source type. The system will generate the corresponding input components and output components in the component library's open directory based on the uploaded read plug-in and write plug-in.
Procedure
Step 1: Prepare the JAR files for the read/write plug-ins
Maven dependencies are as follows:
<dependency>
  <groupId>com.alibaba.dt.pipeline</groupId>
  <artifactId>plugin.center.base</artifactId>
  <version>0.0.1-SNAPSHOT</version>
</dependency>
The code example of the read plug-in file is as follows.
package demo;

import com.alibaba.dt.pipeline.plugin.center.base.Reader;
import com.alibaba.dt.pipeline.plugin.center.base.RecordSender;
import com.alibaba.dt.pipeline.plugin.center.conf.Configuration;
import com.alibaba.dt.pipeline.plugin.center.element.*;
import com.alibaba.dt.pipeline.plugin.center.record.Record;
import org.slf4j.Logger;
import org.slf4j.LoggerFactory;

import java.util.List;
import java.util.Random;
import java.util.stream.Collectors;
import java.util.stream.IntStream;


public class ReaderDemo extends Reader {

    public static final String DS_KEY = "demo_ds";

    public static final String TASK_INDEX = "taskIndex";

    public static final String USER_KEY = "user_param";

    public static class Job extends Reader.Job {
        private static final Logger logger = LoggerFactory.getLogger(Job.class);

        Configuration jobConfig;

        @Override
        public void init() {
            logger.info("job init");

            this.jobConfig = super.getPluginJobConf();
            String value = jobConfig.getString(USER_KEY, "default_value");
            String ds = jobConfig.getString(DS_KEY, "default_ds");
            logger.info("user_param:{} ds:{}", value, ds);
        }

        @Override
        public void prepare() {
            super.prepare();
            logger.info("job prepare");
        }

        @Override
        public List<Configuration> split(int i) {
            logger.info("job split:{}", i);
            return IntStream.range(0, i).boxed().map(x -> {
                Configuration tmpConfiguration = jobConfig.clone();
                tmpConfiguration.set(TASK_INDEX, x);
                return tmpConfiguration;
            }).collect(Collectors.toList());
        }

        @Override
        public void post() {
            super.post();
            logger.info("job post");
        }

        @Override
        public void destroy() {
            logger.info("job destroy");
        }
    }


    public static class Task extends Reader.Task {
        private static final Logger logger = LoggerFactory.getLogger(Task.class);

        private Configuration taskConfig;
        private int index;
        private RowMeta rowMeta;

        @Override
        public void init() {

            this.taskConfig = super.getPluginJobConf();

            index = taskConfig.getInt(TASK_INDEX, -1);
            logger.info("task init:{}", index);
        }

        @Override
        public void prepare() {
            super.prepare();
            logger.info("task prepare");
        }

        @Override
        public void startRead(RecordSender recordSender) {
            logger.info("task start");

            Random random = new Random();


            for(int i = 0; i < 10; i++) {
                Record record = recordSender.createRecord();
                record.addColumn(new LongColumn(i));
                record.addColumn(new StringColumn("name_" + i));
                record.addColumn(new DoubleColumn(random.nextDouble()));
                recordSender.sendToWriter(record);
                logger.info("read record:{}", i);
            }
        }

        @Override
        public RowMeta getInputRowMeta(){
            logger.info("task column meta");
            rowMeta = new RowMeta();


            ColumnMeta columnMeta1 = new ColumnMeta();
            columnMeta1.setName("id");
            columnMeta1.setType(Column.Type.LONG);
            rowMeta.addColumnMeta(columnMeta1);

            ColumnMeta columnMeta2 = new ColumnMeta();
            columnMeta2.setName("name");
            columnMeta2.setType(Column.Type.STRING);
            rowMeta.addColumnMeta(columnMeta2);

            ColumnMeta columnMeta3 = new ColumnMeta();
            columnMeta3.setName("score");
            columnMeta3.setType(Column.Type.DOUBLE);
            rowMeta.addColumnMeta(columnMeta3);

            return rowMeta;
        }

        @Override
        public void post() {
            super.post();
            logger.info("task post");
        }

        @Override
        public void destroy() {
            logger.info("task destroy");

        }
    }
}
The code example of the write plug-in file is as follows.
package demo;

import com.alibaba.dt.pipeline.plugin.center.base.RecordReceiver;
import com.alibaba.dt.pipeline.plugin.center.base.Writer;
import com.alibaba.dt.pipeline.plugin.center.conf.Configuration;
import com.alibaba.dt.pipeline.plugin.center.record.Record;
import org.slf4j.Logger;
import org.slf4j.LoggerFactory;

import java.util.List;
import java.util.stream.Collectors;
import java.util.stream.IntStream;

public class WriterDemo extends Writer {

    public static final String DS_KEY = "demo_ds";

    public static final String TASK_INDEX = "taskIndex";

    public static final String USER_KEY = "user_param";

    public static class Job extends Writer.Job {
        private static final Logger logger = LoggerFactory.getLogger(Job.class);

        Configuration jobConfig;

        @Override
        public void init() {
            logger.info("job init");

            this.jobConfig = super.getPluginJobConf();
            String value = jobConfig.getString(USER_KEY, "default_value");
            String ds = jobConfig.getString(DS_KEY, "default_ds");
            logger.info("user_param:{} ds:{}", value, ds);
        }

        @Override
        public void prepare() {
            super.prepare();
            logger.info("job prepare");
        }

        @Override
        public List<Configuration> split(int i) {
            logger.info("job split:{}", i);
            return IntStream.range(0, i).boxed().map(x -> {
                Configuration tmpConfiguration = jobConfig.clone();

                tmpConfiguration.set(TASK_INDEX, x);
                return tmpConfiguration;
            }).collect(Collectors.toList());
        }

        @Override
        public void post() {
            super.post();
            logger.info("job post");
        }

        @Override
        public void destroy() {
            logger.info("job destroy");
        }
    }

    public static class Task extends Writer.Task {
        private static final Logger logger = LoggerFactory.getLogger(Task.class);

        private Configuration taskConfig;
        private int index;

        @Override
        public void init() {

            this.taskConfig = super.getPluginJobConf();

            index = taskConfig.getInt(TASK_INDEX, -1);
            logger.info("task init:{}", index);
        }

        @Override
        public void prepare() {
            super.prepare();
            logger.info("task prepare");
        }

        @Override
        public void startWrite(RecordReceiver recordReceiver) {
            logger.info("task start");

            Record record;
            while ((record = recordReceiver.getFromReader()) != null) {
                logger.info("======: " + record.toString());
            }
        }

        @Override
        public void post() {
            super.post();
            logger.info("task post");
        }

        @Override
        public void destroy() {
            logger.info("task destroy");

        }
    }
}
Step 2: Create other database types of offline custom source types
On the Dataphin home page, single click the top menu bar Management Center > Datasource Management.
In the left-side navigation pane, single click Custom Source Types.
On the Custom Source Types page, single click Create Custom Source Type and choose Create Offline Custom Source Type from the dropdown menu.
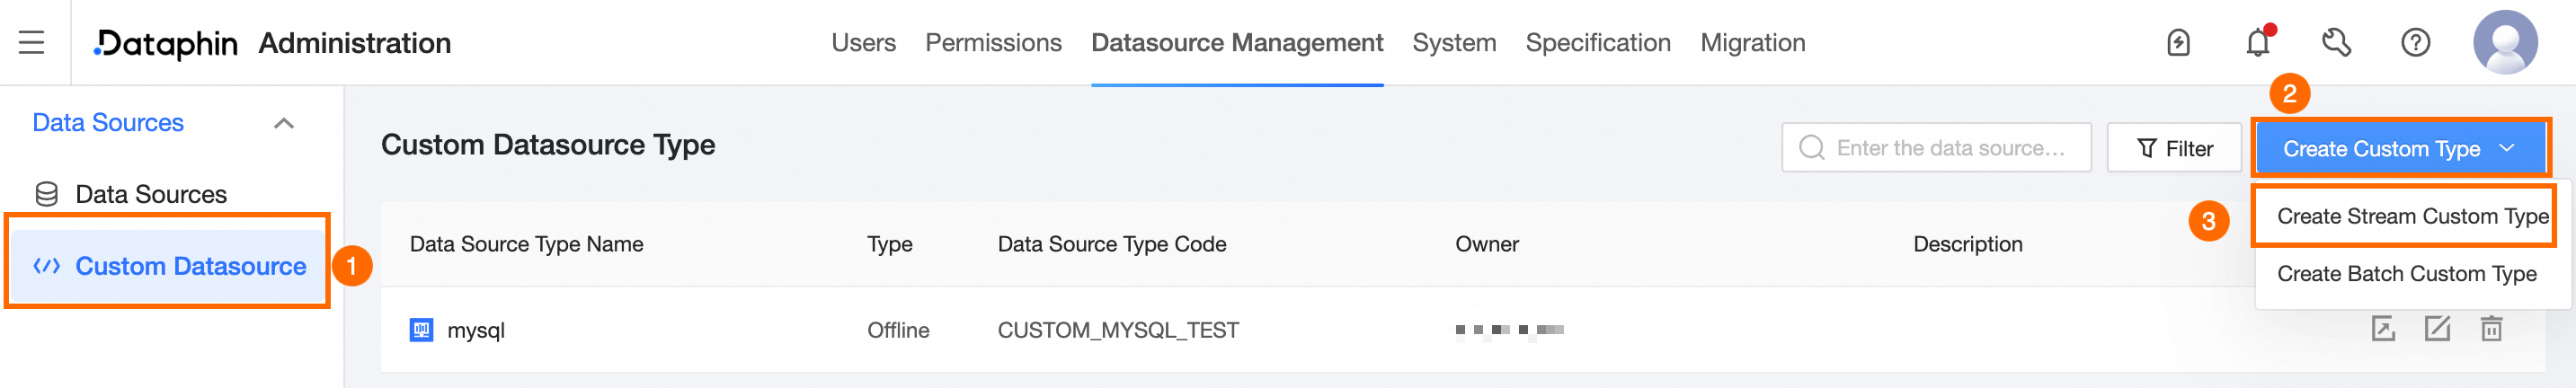
On the Create Offline Custom Source Type page, configure the parameters as follows:
Parameter
Description
Basic Configuration
Type
Select Other Database.
Name
Enter the name of the custom component, which can include Chinese characters, English letters (case-sensitive), underscores (_), and numbers, up to 64 characters in length.
Supports Chinese characters, English letters (case-sensitive), underscores (_), and numbers, with a maximum length of 64 characters.
Type Code
This unique identifier for the component is used by the backend and cannot be changed once created. It must consist of English letters (case-sensitive), numbers, and underscores (_), and cannot start with a number.
Supports only English letters (case-sensitive), numbers, and underscores (_), and must not begin with a number.
Data Source JSON
Enter the data source JSON code and upload the read/write plug-ins. The JSON code defines the data source's configuration items, as illustrated below:
Enter the JSON code for the data source, detailing the configuration items. The following example explains the code structure:
[
  {
    "columnName": "url",
    "columnType": "NORMAL",
    "text": {
      "zh_CN": "链接地址",
      "en_US": "address",
      "zh_TW": "鏈接地址"
    },
    "placeholder": {
      "zh_CN": "请输入链接地址",
      "en_US": "input address",
      "zh_TW": "請輸入鏈接地址"
    }
  },
  {
    "columnName": "username",
    "columnType": "NORMAL",
    "text": {
      "zh_CN": "用户名",
      "en_US": "username",
      "zh_TW": "用戶名"
    },
    "placeholder": {
      "zh_CN": "请输入用户名",
      "en_US": "input username",
      "zh_TW": "請輸入用戶名"
    }
  },
  {
    "columnName": "password",
    "columnType": "ENCRYPT",
    "text": {
      "zh_CN": "密码",
      "en_US": "password",
      "zh_TW": "密碼"
    },
    "placeholder": {
      "zh_CN": "请输入密码",
      "en_US": "input password",
      "zh_TW": "請輸入密碼"
    }
  }
]
The JSON fields are described as follows:
columnName: The name of the parameter.
columnType: The type of parameter, either NORMAL or ENCRYPT. Password-type parameters must be ENCRYPT.
placeholder: The default value displayed in the input box in three languages. If not specified, the input box will be empty.
text: The display name of the parameter in three languages.
Resource Configuration
Read/write Plug-ins
Choose the type of plug-in to configure, enter the corresponding ClassName (class name of the plug-in), and upload the plug-in files prepared in Step 1. The plug-in files must be in .jar format and not exceed 50MB in size.
NoteAt least one read/write plug-in is required. Once the read plug-in and write plug-in are configured, the corresponding input plug-in and output plug-in will be generated.
Description Information
Description
Provide a brief description of the custom data source, not exceeding 128 characters.
Click Create.