Configure real-time full-database synchronization tasks
The real-time full-database synchronization feature combines one-time full synchronization with continuous incremental capture to synchronize an entire source database (such as MySQL or Oracle) to a destination system with low latency. Real-time full-database synchronization tasks support full synchronization of historical data from the source database and automatically initialize the table schema and data on the destination. Then, the task automatically switches to real-time incremental mode and uses technologies such as change data capture (CDC) to continuously capture and synchronize subsequent data changes. This feature is applicable to scenarios such as real-time data warehousing and data lake construction. This topic uses real-time full-database synchronization from MySQL to MaxCompute as an example to describe how to configure the task.
Prerequisites
Data source preparation
The source and destination data sources are created. For information about how to configure data sources, see Configure data sources.
Make sure that the data sources support real-time full-database synchronization. For more information, see Supported data sources.
Some data sources require log enabling, such as MySQL, Hologres, and Oracle. The method for enabling logs varies by data source. For more information, see Data source configurations.
MaxCompute: The Decimal data type is supported by MaxCompute 2.0. Before synchronization, you must enable the MaxCompute 2.0 data types. For more information, see MaxCompute 2.0 data types.
Resource group: A serverless resource group is purchased and configured.
Network connectivity: Network connectivity between the resource group and the data sources must be configured.
Usage notes
DataWorks supports two types of full-database synchronization: real-time full-database and full and incremental full-database. Both types support full synchronization of historical data from the source database and then automatically switch to real-time incremental mode. However, the two types differ in timeliness and destination table requirements:
Timeliness: Real-time full-database synchronization provides second-level to minute-level timeliness. Full and incremental full-database synchronization provides T+1 timeliness.
Destination table (MaxCompute):
PK Delta Table: Real-time full-database synchronization supports all features.
Regular tables and Append Delta Tables: The Append mode is supported only when you select the incremental synchronization mode in a real-time full-database synchronization task.
Full and incremental full-database synchronization: All the preceding table types are supported.
Real-time full-database synchronization tasks can be configured in the DataStudio (Data Studio) and Data Integration modules. The two modules are functionally interoperable.
Consistent configuration: Regardless of whether you create a task in the Data Studio or Data Integration module, the configuration interface, parameter settings, and underlying features are identical.
Bidirectional synchronization: Tasks created in the Data Integration module are automatically synchronized and displayed in the
data_integration_jobsdirectory of the Data Studio module. These tasks are categorized by thesource type-destination typechannel for unified management.
Configure a task
Step 1: Create a synchronization task
Log on to the DataWorks console. In the target region, click in the left-side navigation pane. Select a workspace from the drop-down list and click Go to Data Integration.
In the left-side navigation pane, click Synchronization Task. On the page that appears, click Create Synchronization Task and configure the task information:
Source Type:
MySQL.Destination Type:
MaxCompute.Specific Type:
Real-time Full-database.Synchronization Mode:
Schema Migration: Automatically creates database objects (such as tables, columns, and data types) on the destination that match those on the source, without including data.
Full Synchronization (optional): Copies all historical data from specified objects (such as tables) on the source to the destination as a one-time operation. This is typically used for initial data migration or data initialization.
Incremental Sync (optional): Continuously captures data changes (inserts, updates, and deletes) from the source after full synchronization is complete, and synchronizes them to the destination.
Step 2: Configure data sources and runtime resources
In the Source Data Source section, select the
MySQLdata source that has been added to the workspace. In the Destination section, select theMaxComputedata source that has been added.In the Running Resources section, select the Resource Group for the synchronization task and allocate Resource Group CU to the task.
NoteWhen a message such as
Please confirm whether there are enough resources...appears in the task logs, the available compute units (CUs) of the current resource group are insufficient to start or run the task. In the Configure Resource Group panel, increase the number of CUs allocated to the task to assign more compute resources.For recommended resource size values, see Recommended CUs for Data Integration. Adjust the values based on your actual requirements.
Make sure that both the source and destination data sources pass Connectivity Check.
Step 3: Synchronization plan configuration
1. Configure the data source
In this step, you can select the tables to be synchronized from the source data source in the Source Tables area, and click the
 icon to move them to the Selected Tables area on the right. If there are many tables, you can use Database Filtering or Table filtering to select the tables to be synchronized by configuring regular expressions.
To write multiple sharded tables (with the same schema) to a single destination table, you can Select Tables by Regex.
Enter a regular expression in the source table configuration. DataWorks automatically identifies and collects all matching source tables and writes their data to the destination table mapped by the expression.NoteThis method is applicable to scenarios where sharded tables are merged during synchronization (similar to database and table sharding synchronization). It improves configuration efficiency and avoids the need to repeatedly add many-to-one synchronization rules.
2. Configure the data destination
If only Incremental Sync is selected for the real-time full-database synchronization task, you can configure the incremental synchronization mode for writing to the destination table.
Replay: Only PK Delta Table is supported. Similar to normal synchronization, only data columns are synchronized.
Incremental stream: Both regular tables and Append Delta Table are supported. Real-time data from the source table is appended with metadata such as insert, update, and delete operations before being written to the destination table. For the format of incremental stream tables, see Incremental stream table format.
3. Target table mapping
In this step, you need to define the mapping rules between source tables and destination tables, and specify rules such as primary keys, dynamic partitions, and DDL/DML configurations to determine how data is written.
Operation | Description | ||||||||||||
Refresh | The system automatically lists the source tables you selected, but the specific properties of the destination tables take effect only after you refresh and confirm them.
| ||||||||||||
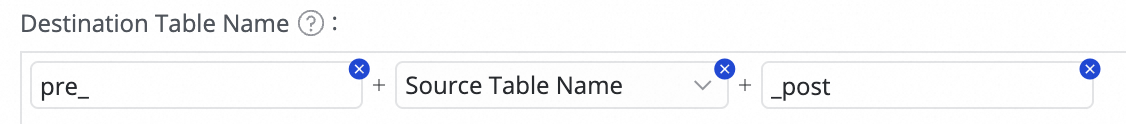
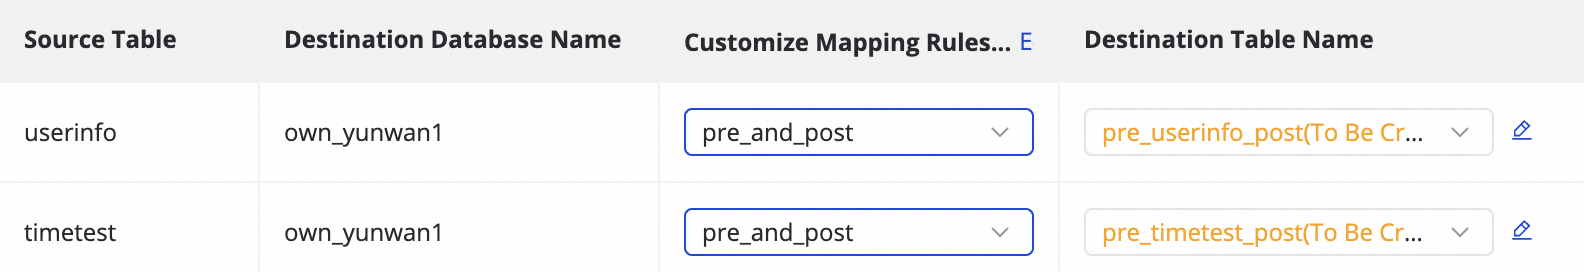
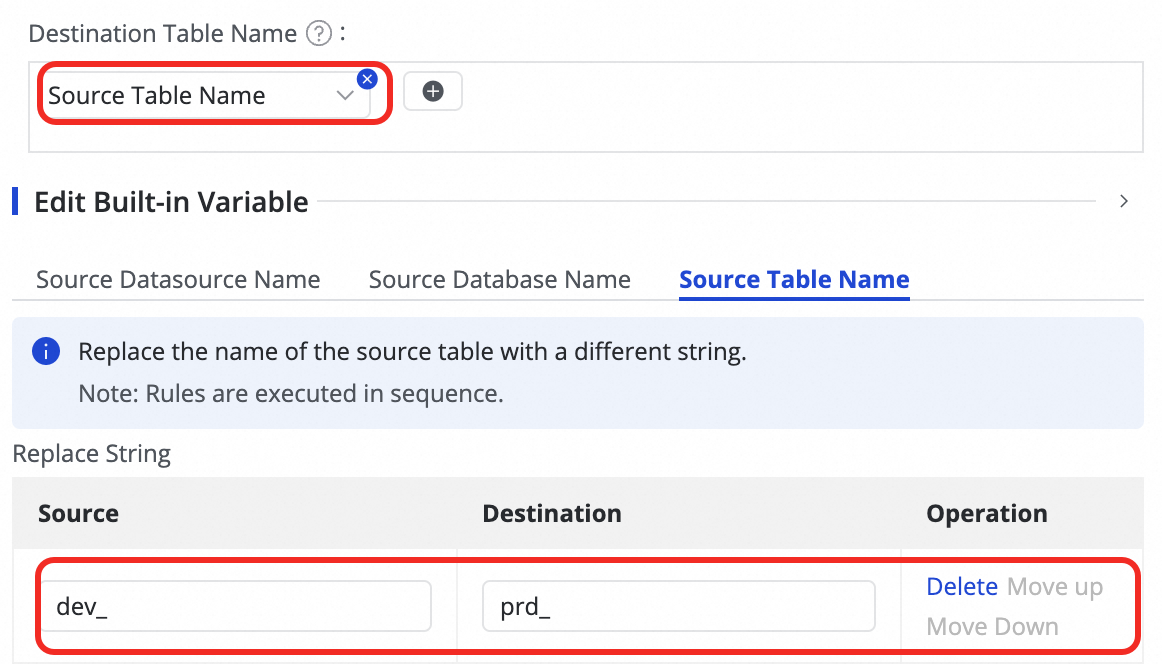
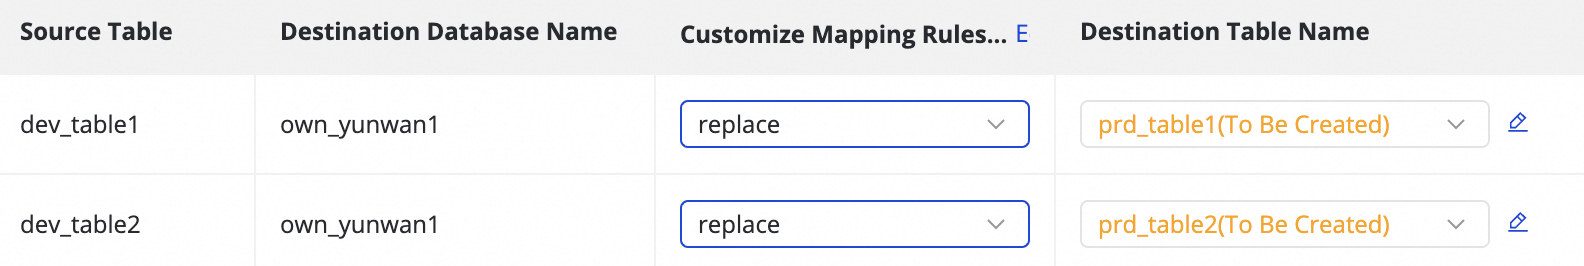
Customize Mapping Rules for Destination Table Names (optional) | The system has a default table name generation rule:
The following scenarios are supported:
Both MaxCompute and Hologres support target schema name mapping customization. When you synchronize a full MySQL database to MaxCompute in real time, you can configure target schema name mapping customization rules to route synchronized data to a specified non-default schema in the destination MaxCompute project, rather than writing all data to the default schema. Important The Schema feature of MaxCompute is disabled by default. Before you use the target schema name mapping customization feature, you must manually enable the Schema mode for the destination MaxCompute project. Otherwise, the mapping rules do not take effect. | ||||||||||||
Edit column type mapping (optional) | The system has default mappings between source column types and destination column types. You can click Edit Mapping of Field Data Types in the upper-right corner of the table to customize the column type mappings between the source and destination tables, and then click Apply and Refresh Mapping. When editing column type mappings, make sure that the type conversion rules are correct. Incorrect rules may cause type conversion failures, resulting in dirty data and affecting task execution. | ||||||||||||
Edit destination table schema (optional) | The system automatically creates destination tables that do not exist based on the custom table name mapping rules, or reuses existing tables with the same name. DataWorks automatically generates the destination table schema based on the source table schema. In most cases, no manual intervention is required. You can also modify the table schema in the following ways:
For existing tables, you can only add columns. For new tables, you can add columns, partition columns, and configure the table type or table properties. For details, see the editable areas on the page. | ||||||||||||
Value assignment | Native columns are automatically mapped based on columns with the same name in the source and destination tables. The added columns and partition columns in the preceding steps require manual value assignment. Perform the following operations:
When assigning values, you can use constants or variables. Switch the type in Value Type. The following methods are supported:
Note An excessive number of partitions degrades synchronization performance. If more than 1,000 new partitions are created in a single day, partition creation fails and the task is terminated. Therefore, when you define the value assignment method for partition columns, estimate the number of partitions that may be generated. Exercise caution when using second-level or millisecond-level partition creation methods. | ||||||||||||
Source Split Key | You can select a column from the source table or select Not Split from the drop-down list of the source split key. During task execution, the data is split into multiple tasks based on this column to enable concurrent and batch data reads. We recommend that you use the primary key of the table as the source split key. String, floating-point, date, and other types are not supported. Currently, the source split key is supported only when the source is MySQL. | ||||||||||||
Skip Full Synchronization | If full synchronization has been configured in Step 3, you can individually cancel full data synchronization for a specific table. This is applicable to scenarios where full data has already been synchronized to the destination by other means. | ||||||||||||
Full condition | Apply conditional filtering to the source during the full synchronization phase. Enter only the WHERE clause here without the WHERE keyword. | ||||||||||||
Configure DML Rule | DML message processing is used to perform fine-grained filtering and control on change data captured from the source ( | ||||||||||||
Others | Table Type: MaxCompute supports regular tables,
For more information about Delta Table, see Delta Table overview. |
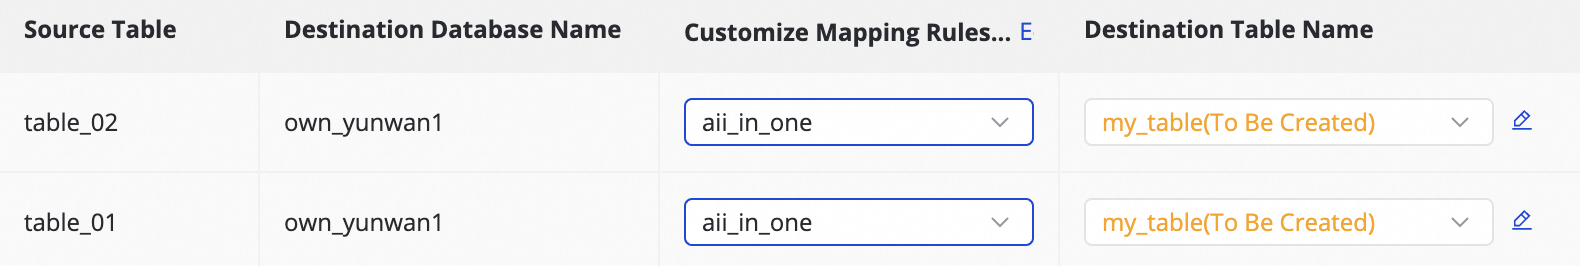
 button and select Manually enter and Built-in Variable to concatenate and generate the destination table name. The supported variables include the source data source name, source database name, and source table name.
 button in the Target Table column to add columns.
 tooltip on the page.
Step 4: Advanced configuration
Advanced parameter configuration
If you need fine-grained configuration for the task to meet custom synchronization requirements, go to the Advanced Parameters tab to modify advanced parameters.
Click Advanced Configuration in the upper-right corner of the page to go to the advanced parameter configuration page.
Modify parameter values based on the parameter prompts. The meaning of each parameter is described after the parameter name.
AI-assisted configuration is also supported. You can enter natural language instructions, such as adjusting the task concurrency, and a large language model generates recommended parameter values. You can choose whether to accept the AI-generated parameters based on your actual requirements.
Modify parameters only after you fully understand their meanings. Improper modifications may cause unexpected issues such as task latency, excessive resource consumption that blocks other tasks, or data loss.
DDL capability configuration
Some real-time synchronization channels can detect metadata changes to the source table schema, notify the destination, and synchronize the updates to the destination. Other handling policies such as alerting, ignoring, or terminating the task are also available.
You can click Configure DDL Capability in the upper-right corner of the page to set the handling policy for each type of DDL change. The available handling policies vary depending on the channel.
Process normally: The destination processes the DDL change information from the source.
Ignore: The change message is ignored, and the destination is not modified.
Error: The real-time full-database synchronization task is terminated, and the status is set to Error.
Alert: An alert is sent to you when this type of change occurs at the source. You must configure DDL notification rules in Configure Alert Rule.
After a column is added to the source table and created in the destination table via DDL sync, the system does not backfill the existing data in the destination table.
Column deletion is not supported for automatic synchronization in MySQL sources. When you delete a column from a source MySQL table, the table schema becomes inconsistent with the binary log, which may cause synchronization task errors.
To remove a column that has already been synchronized to the destination table, use the following workaround:
Delete the corresponding destination table (for example, the Hologres destination table).
Edit the synchronization task and remove the table from the task.
Re-add the table to the task.
Refresh the column mappings.
Save and deploy the task.
If the task is in the running state, click Apply Updates for the changes to take effect.
Step 5: Deploy and run the task
After you complete all configurations, click Save at the bottom of the page to save the task configuration.
Full-database synchronization tasks do not support direct debugging and must be deployed to Operation Center to run. Therefore, both new and edited tasks require the Deploy operation to take effect.
During deployment, if you select Start immediately after deployment, the task is started simultaneously upon deployment. Otherwise, after the deployment is complete, you need to go to the page and manually start the task in the Actions column of the target task.
Click the Name/ID of the corresponding task in the Tasks to view the detailed execution process of the task.
Step 6: Alert configuration
1. Add an alert
In the list, find the target real-time full-database synchronization task, and click in the Actions column to configure alert policies for the task.
(1) Click Create Rule to configure an alert rule.
You can set Alert Reason to monitor metrics such as Business delay, Failover, Task status, DDL Notification, and Task Resource Utilization for the task, and configure CRITICAL or WARNING alert levels based on specified thresholds.
By configuring Configure Advanced Parameters, you can control the interval between alert messages to prevent excessive messages from being sent at once, which may cause waste and message backlogs.
If you select Business delay, Task status, or Task Resource Utilization as the alert reason, you can also enable recovery notifications to notify recipients when the task returns to normal.
(2) Manage alert rules.
For alert rules that have been created, you can use the alert toggle to enable or disable an alert rule. You can also send alerts to different recipients based on alert levels.
2. View alerts
Click in the expanded task list to go to the alert events page, where you can view the alerts that have been triggered.
Manage tasks
Edit a task
On the page, find the synchronization task that you created, click More in the Operation column, and then click Edit to modify the task information. The procedure is the same as that for configuring a task.
For tasks that are not in the running state, you can directly modify the configuration, save the changes, and then deploy the task to the production environment for the changes to take effect.
For tasks in the Running state, if you edit and deploy the task without selecting Start immediately after deployment, the original action button changes to Apply Updates. You must click this button for the changes to take effect in the production environment.
After you click Apply Update, the system performs three sequential steps: Stop, Deploy, and Restart.
If the change involves adding new tables or switching existing tables:
When applying the update, you cannot select a checkpoint. After you click confirm, the system performs schema migration and full initialization for the new tables. After full initialization is complete, incremental synchronization begins for the new tables along with the existing tables.
If other configurations are modified:
When applying the update, you can select a checkpoint. After you click confirm, the task resumes from the specified checkpoint. If no checkpoint is specified, the task resumes from the checkpoint where it last stopped.
Unmodified tables are not affected and resume running from the checkpoint where they last stopped after the update and restart.
View tasks
After you create a synchronization task, you can view the list of created synchronization tasks and the basic information of each task on the synchronization task page.
In the Actions column, you can Start or Stop synchronization tasks, and from the More menu, you can edit or View synchronization tasks.
For started tasks, you can view the basic running status in Execution Overview, and click the corresponding overview area to view the execution details.
Checkpoint-based resumption
Use cases
Manually resetting checkpoints when starting or restarting a task is applicable to the following scenarios:
Task recovery and data resumption: When a task is interrupted unexpectedly, you may need to manually specify an interruption time point as the new start checkpoint to ensure that data is resumed from the accurate breakpoint.
Data troubleshooting and backtracking: If you find that synchronized data is missing or abnormal, you can roll back the checkpoint to a time point before the issue occurred, and replay and repair the problematic data.
Major task configuration changes: After making major changes to the task configuration, such as the destination table schema or column mappings, we recommend that you reset the checkpoint to start synchronization from a specific time point to ensure data accuracy under the new configuration.
Instructions
Click Start, and in the dialog, select Whether to reset the site:
First start: You do not need to select the reset checkpoint option. Run the task directly. The system automatically performs full initialization and then switches to incremental synchronization after the initialization is complete.
Run without resetting the checkpoint: The task resumes from the checkpoint where it last stopped (the last checkpoint).
Reset the checkpoint and select a time: The task starts from the specified time checkpoint. Make sure that the selected time does not exceed the earliest time checkpoint supported by the source binlog.
If a checkpoint error or a checkpoint-not-found error occurs when you run a synchronization task, try the following solutions:
Reset the checkpoint: When you start the real-time synchronization task, reset the checkpoint and select the earliest available checkpoint of the source database.
Adjust the log retention period: If the database checkpoint has expired, consider adjusting the log retention period in the database. For example, set the retention period to 7 days.
Data synchronization: If data has been lost, consider performing a full synchronization again, or configure a batch synchronization task to manually synchronize the lost data.
Task O&M and tuning
After a task is started, if you encounter issues such as data consumption latency, stuck tasks, or poor performance, see Troubleshoot and tune real-time synchronization tasks for solutions.
FAQ
For frequently asked questions about real-time full-database synchronization, see FAQ about real-time full-database synchronization.
Appendix: Incremental changelog table format
Source column flat layout
Column name | Description |
sequence_id | The record ID of the incremental event. The value is unique and auto-incrementing. |
operation_type | The operation type (I/D/U). |
execute_time | Timestamp of the data |
before_image | Whether this is a pre-change record (Y/N) |
after_image | Whether this is a post-change record (Y/N) |
src_datasource | Source data source of the data |
src_database | Source database of the data |
src_table | Source table of the data |
Column 1 | Actual data column 1 |
Column 2 | Actual data column 2 |
Column 3 | Actual data column 3 |
Merge source table columns into JSON
Column name | Description |
sequence_id | Record ID of the incremental event. The value is unique and incrementing. |
operation_type | Operation type (I/D/U) |
execute_time | Timestamp of the data |
before_image | Whether this is a pre-change record (Y/N) |
after_image | Whether this is a post-change record (Y/N) |
src_datasource | Source data source of the data |
src_database | Source database of the data |
src_table | Source table of the data |
ddl_sql | When the operation is a DDL type, the DDL statement is written to this column. |
data_columns | Merge actual data columns into JSON |