Data annotation
If you do not have annotated data, you can use the annotation platform to create it. This is an alternative to creating a dataset from a JSON file.
This example shows how to use the annotation platform. In the project that you just created, you can create an annotation task.
Note: Only data files with UTF-8 encoding are supported.
Enter a name for the dataset and upload the raw data file to be annotated. After the upload is complete, click Next. On the entity name settings page, click Add Entity and enter the name of the entity to extract, as shown below:
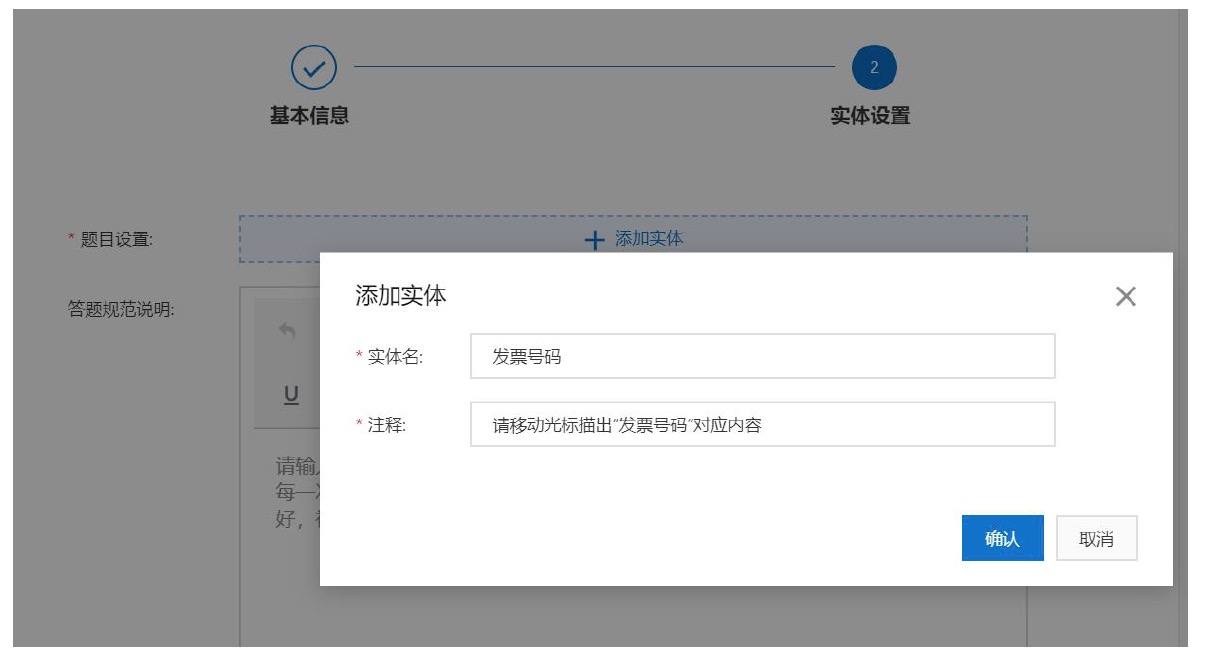
Click the Add Entity button repeatedly until all entities appear in the right-side column. Then, click Submit. After the dataset finishes parsing, you can start annotating. Follow the on-screen prompts to annotate your data.
Annotation guidelines
Annotate all entity occurrences in the document. We recommend that you enable the "Annotate Same Value" feature in the upper-left corner.
If an entity is annotated in one document, must it be annotated again in another document? Yes, it must.
Annotated entities cannot contain line feeds (`\n`) or periods (`.`). If an entity contains these characters, it will not be detected during inference. However, this does not affect the training process.
FAQ
After you build a dataset, the model begins to learn. The model has no prior knowledge. Its knowledge comes exclusively from the training dataset that you provide. Therefore, the model can only make judgments based on what it has learned from the training data and cannot infer information beyond that scope.
Common questions include the following:
I need to extract a monetary amount from a sentence, so I annotated 500 sentences that contain this amount. When I test the model, can I use an entire article that contains one sentence with the target entity?
A: No, you cannot. Your test data must be consistent with your training data. Therefore, you must also use a single sentence for testing. Alternatively, you can use complete articles for both training and testing.
I have a paragraph from a legal document and need to infer the judgment from a specific sentence. Can I annotate these sentences to extract and infer the answer?
A: Entity extraction supports short, complete texts and does not perform inference. If the content that you need to annotate spans multiple sentences or paragraphs, consider other projects or solutions to solve your problem.
Annotation is tedious. The text I need to extract comes in several formats. Can I just annotate one format? Can I annotate a few examples first to test the performance?
A: The more data you annotate and the more diverse the data, the better the model will perform. High-quality data annotation is essential for a high-performing model. Do not annotate only a few examples to test performance. The results will be poor because a model cannot learn patterns from a very small sample. If you have data in multiple formats, annotate samples from each format instead of focusing on only one. This improves the model's stability and accuracy.