SDK release notes
PPU SDK v1.6.1 release notes
1. Main features and bug fixes
New features
Released PPU-Flash Attention 2.7.4 with support for FA3.
Added support for vLLM 0.10.0.
Added support for the bf16 and int8 mixed-precision quantization method for the QWen3 MoE model.
Added support for SGLang 0.4.10.
Added support for FlashInfer 0.2.9rc2.
Added support for the
gdrCopyfeature in PCCL.The
acextpackage is no longer distributed withPPU_SDKand is released as a wheel.The usage of
acextwith PTG vLLM/SGLang has changed. See Introduction to Using acext for details.For instructions on compiling the
acextwheel and configuring environment variables to build vLLM/SGLang, see Build and Run from Source.
Known issues
In some cases when using the Qwen3-8B model with sglang 0.4.10, throughput under high concurrency can be lower than under low concurrency. This is because high concurrency can trigger a tile configuration that degrades the performance of the gemm and flashinfer kernels. We recommend using a lower concurrency setting for better throughput.
sglang 0.4.10 uses the FA3 backend by default. For scenarios involving the Qwen3-235B-A22B model with an input of 4,000 and an output of 1,500, the FA3 backend performs worse than the FlashInfer backend. We recommend using the FlashInfer backend in this case.
When using the default FA3 backend in sglang 0.4.10 with the Qwen3-235B-A22B model and BF16 precision, the process might hang during the CUDA graph capturing stage. To resolve this, lower the value of
--mem_fraction_static, for example, to 0.8.In a vLLM dual-node environment, execution may fail if both torchao and transformers version 4.53.3 or later are installed. This issue also occurs on GPUs. To resolve this, uninstall torchao.
PPU SDK v1.6 release notes
1. Release
1.1 Software stack
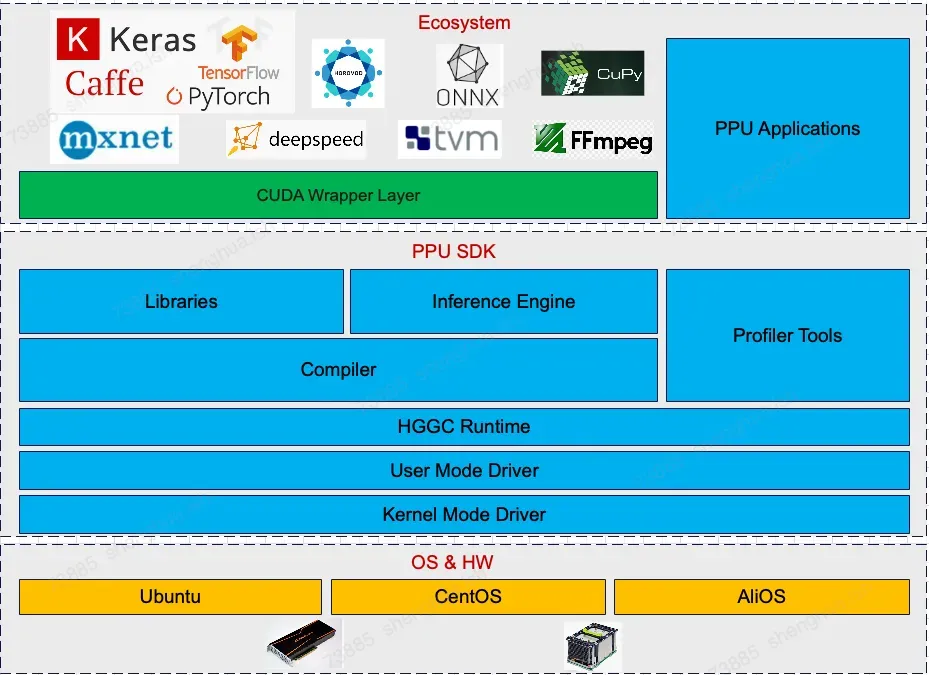
Helps CUDA application developers reduce costs and increase efficiency with PPU hardware and software.
Provides three layers of deliverables: framework software packages and models compatible with the CUDA ecosystem, a CUDA SDK-compatible package, and the T-Head SAIL SDK.
1.2 Core components
Parameter | Description |
Firmware | PPU firmware |
KMD | PPU kernel-mode driver |
UMD / HGGC | PPU user-mode driver and runtime |
Compiler toolchain | PPU compiler toolchain |
Acompute | PPU compute acceleration library |
Acext | PPU quantization acceleration library |
PCCL | PPU communication acceleration library |
PPU SMI | PPU device management tool |
PPU DCGM | PPU online monitoring tool |
Asight System | PPU system profiling tool |
Asight Compute | PPU compute profiling tool |
PPU GDB | PPU debugging tool |
PPU MemCheck | PPU Sanitizer tool |
PPU hgobjdump | PPU device binary tool |
CUDA SDK Wrapper | CUDA API compatibility library |
1.3 Key features
1.3.1 Firmware
Supports installation from binary packages (RPM or DEB).
Supports dynamic power management. By default, the PPU firmware dynamically adjusts the core frequency (from 200 MHz to the maximum operating frequency) and operating voltage based on real-time workload, temperature, and power consumption.
Supports PPU frequency locking. For details, see PPU-SMI Device Management Tool.
Supports secure firmware signing and a dual-backup feature to ensure firmware security and reliability.
Supports firmware upgrades for the power management integrated circuit (PMIC).
Supports out-of-band management through the Baseboard Management Controller (BMC), including device status monitoring and out-of-band firmware upgrades.
1.3.2 Kernel driver
Supports two installation methods: binary packages (RPM or DEB) and runfile packages.
Supports decoupling the kernel driver from the PPU SDK, allowing any combination of kernel driver and PPU SDK versions v1.0 or later.
Supports flexible machine configurations, including single-node single-card; single-node 8-card/16-card (ICN interconnect); multi-node, multi-card (ICN interconnect); and multi-node, multi-card (GDR). Before using GDR, ensure the
alixpu-peermemkernel module, which is released with the PPU kernel driver, is installed.Supports PPU fault reporting and handling.
Supports the
auto-resetfeature. The driver automatically resets the PPU device when it detects akill overtimeorcp invalid cmderror, enabling automatic recovery. This feature is enabled by default. Useppu-smito check the status or disable it.Supports Multi-Pipe Service (MPS). Run
ppudbg --config_submit_mode 1/0to enable or disable this feature.Supports tidal mode for workloads that mix small-model and large-model tasks in MPS mode.
Supports NVML GPM metric collection, including SM utilization, SM occupancy, tensor core utilization, memory bandwidth utilization, PCIe read/write speeds, and ICN link read/write speeds.
Supports full-card passthrough virtualization. You can unbind the PPU driver on the host and pass the card through to a virtual machine. When using this feature, ensure ICN is isolated between different virtual machines.
Supports hot upgrades of the host driver in SR-IOV virtualization mode. This feature lets you update the PPU driver on the host while services are running in the virtual machines.
Supports single-node 16-card Zhenwu 810E configurations and optimizes the default PPU device order (sorted by rear-panel ID).
Supports GPM collection for L1/L2 cache hit rates, which can be queried using the DCGM tool.
Adjusts the logical numbering rule for 16-card Zhenwu 810E devices to improve interconnect performance.
Supports querying the MPS tidal mode status.
Supports querying Xid error information.
Supports querying the GPM status and enabling or disabling GPM.
Disables HBM parity Xid error reporting.
1.3.3 User-mode driver and runtime
Compatible with most CUDA runtime APIs (cudaXXX) and CUDA driver APIs (cuXXX).
Outputs more detailed error logs when an Xid 896 error occurs to facilitate troubleshooting.
Optimizes performance for 2D/3D
cudaMemcpyandcudaMemsetoperations.Supports Stream Memory Operation v2 APIs.
Supports APIs related to edge data in graph management.
Supports APIs related to batch memory operation nodes in graph management.
Supports basic texture features.
Optimizes PPU performance when
CUDA_DEVICE_MAX_CONNECTIONS=1.Supports the
cuCtxCreate_v3API.Ensures that
printfcontent from device code is correctly output after an exception occurs.Supports the
HGGC_EXCLUSIVE_STREAMSenvironment variable to map stream groups to different hardware queues.Fixes an issue where CUDA Graph did not support cooperative kernel nodes.
Supports the
cudaLaunchKernelExCinterface.Supports collecting hardware channel information for streams using the asys tool.
Supports AD extension APIs.
Fixes a
cudaErrorIllegalAddresserror that occurred whencudaCreateTextureObjectwas called while Colmap was running.Fixes an issue where the
cudaMallocAsyncinterface returned an error when allocating a size of 0.
1.3.4 Compiler
Provides a C/C++ extension language compiler based on the Clang/LLVM framework for the PPU architecture that supports a host/device mixed programming style and is fully compatible with the CUDA C/C++ language specification.
Provides a rich set of compilation modules, allowing developers to flexibly build compilation pipelines through API calls and easily integrate JIT compilation capabilities.
Implements support for inline PTX instructions, with partial support for dense MMA, sparse MMA, and texture-related instructions. It also extends the PTX instruction definition for PPU tensor cores.
Implements support for CUDA device APIs, with this release adding support for some texture-related APIs.
Supports the system-level reserved shared memory feature.
Supports GCC host compiler versions from 5.5 to 14.2 and Clang host compiler versions from 9 to 18.
Supports Triton versions 2.3.x, 3.0.x, 3.1.x, 3.2.x, and 3.3.x. Extends the
triton.langsyntax to include support for AIU.The split section option is enabled by default for the device ELF binary format, reducing runtime module loading overhead.
Provides a rich set of libraries and tools to simplify development and debugging:
hgobjdump,memcheck,ppu-gdb, sanitizer library,hgprune,hgfatbin,hglink, andhgJitlink.Updates to the
hgrtcruntime JIT compilation library:Supports caching of compilation artifacts to reduce JIT compilation time.
Provides PPU-GDB, a debugging tool that allows you to debug both GPU and CPU code within the same application.
Provides PPU Memcheck, a tool suite for functional correctness checking. This suite includes
memcheck,initcheck,synccheck, andracecheck.Provides
hgobjdump, a PPU binary tool for extracting device-related information from binaries.Provides
hgprune, a PPU prune tool for extracting device-related information from binaries.Provides
hgfatbin, a PPU fatbin development library that supports various runtime operations on fatbin files.Provides
hglink, a PPU link tool for linking PPU device code.Provides
hgjitlink, a PPU JITLink development library that supports runtime linking of PPU device code.
1.3.5 Acceleration libraries
Compute acceleration libraries
Supported closed-source compute libraries:
acdnn,acblas,acfft,acsolver,acrand.Operators supported by
acdnn:Conv
BatchNorm
Pooling
Softmax
Activation
CTCLoss
Dropout
LRN
LSTM
GRU
MultiHeadAttn
Tensor Ops
SpatialTransform
Backend fusion
Operators supported by
acblas:Level 1 Ops
Gemv
Gemm
Matmul + epilogue
MatrixTransform
trsm
getrfBatched
getrsBatched
geqrfBatched
gelsBatched
acfft: Supports R2C/C2R/C2C/D2Z/Z2Z + FFT/iFFT transforms.acsolver: Supports LU factorization/solve, Cholesky factorization/solve, QR factorization, SVD, and eigenvalue decomposition.acrandsupports:Pseudo-random number generators: XORWOW, MRG32K3A, and PHILOX4_32_10.
Data distributions: Default, Uniform, Normal, and LogNormal.
The
acextquantization library supports:A16W8/A16W4 kernel variants, including PerChannel and GroupWise.
A8W8 kernel variants, including PerChannel and PerToken.
An accelerated kernel for WeightonlyBatchedGemv with small batch sizes.
The following MoE types: FP16/BF16, and a8w8 PerChannel/PerToken.
Supported open-source projects:
PPU FlashMLA v1.5
PPU FlashAttention 2.4.2/2.5.6/2.5.7/2.7.2/2.7.4.post1
PPU cutlass 2.5
PPU cutlass 3.3/3.4/3.6
PPU Xformers 0.0.22/0.0.25/0.0.27/0.0.29.post1/0.0.30
PPU FasterTransformer
PPU extension library
acext:Provides high-performance implementations for a16w8, a16w4, and a8w8 quantization, group-gemm, MoE, and batch gemv.
Available as a PPU SDK library and an open-source repository for integration with various frameworks and applications.
PPU DeepGemm:
Supports dense gemm and group gemm.
Supports FP16 and A8W8 formats, but does not support FP8.
Supports PerChannel and PerToken quantization, but does not currently support BlockWise quantization.
Key updates:
Adds initial support for DeepGemm, achieving performance comparable to competitors in typical EP scenarios.
Optimizes MoE performance for scenarios such as DPSK and Qwen3, improving performance by over 50% on average compared to the Triton version.
blaslt: Enhances cross-version descriptor support and improves communication-computation parallelization.conv: Improves support for different format combinations and adds support for strided channels.solver: Adds support forgesvda.Improves error handling for Driver/Runtime calls within compute libraries.
Optimizes
deconvperformance, increasing performance by up to 40% in some scenarios.Optimizes LSTM performance, increasing performance by up to 30% in some scenarios.
Interconnect acceleration libraries
PCCL:
Compatible with most NCCL APIs (ncclXXX) and environment variables.
Supports standard collective operations, such as AllReduce, AllGather, ReduceScatter, Broadcast, Reduce, Send, and Recv.
Supports intra-node multi-card communication via ICN, PCIe, and shared memory.
Supports inter-node communication via RDMA (GDR & non-GDR), Sockets, and ICN.
Performance optimizations:
Improves the performance of
allreduce,reducescatter, andallgatheroperations on single-node 16-card Zhenwu 810E configurations, with a 10% to 20% improvement for large data sizes.Optimizes
allreduceperformance for medium-sized data on single-node 4/8/16-card configurations, with improvements ranging from 10% to 60%.
Supports setting different algorithms and protocols for each collective operation.
Supports the
NCCL_IB_SPLIT_DATA_ON_QPSfeature.Supports more CPU vendors and applies corresponding optimizations for PHB and SYS bandwidth.
Fixed a hang in ext-kernel that occurred when input/output buffer alignment was inconsistent across different ranks.
pccltools:pccl perf:Supports AllReduce, AllGather, ReduceScatter, AlltoAll, Broadcast, and Reduce.
Enhancements to the
p2pBandwidthAndLatencyPerftool:Evaluates ICN P2P interconnect bandwidth and latency for products like Zhenwu 810E on servers with various multi-card interconnect topologies.
DeviceOrderSearchtool:Finds the optimal visible device order on Zhenwu 810E machines for Megatron framework training tasks based on the parallel training configuration. For usage instructions, see the linked documentation.
pccl checktools:Performs functional readiness checks for products like Zhenwu 810E in multi-card and multi-node scenarios.
sailSHMEM:
Compatible with all
nvshmempoint-to-point (pt2pt) related APIs.Supports pt2pt operations for PPU cards for both intra-node and inter-node communication, including thread-, warp-, and block-level put/get bandwidth tests, latency tests, and synchronous operations such as signal and wait.
Supports ICN Link P2P, RDMA IBRC, and IBGDA network transfers.
Added support for the data combine feature on
shmem_p_bwandshmem_p_latpaths, improving performance by about 1 to 3 times.
DeepEP:
Compatible with most DeepEP Python APIs.
Supports three types of kernel implementations:
intranodefordispatchandcombine,internode, andinternode low latency.Supports communication through transport methods such as icn link and inter-node RDMA ibgda or ibrc.
Support for int8 groupwise and channelwise quantization implementation using low latency kernels;
Supports intranode and low latency kernel instances with 2 & 4 ranks.
Fixed potential race conditions on some internode kernel paths.
Fixed an issue with the release order for some resources that caused crashes.
1.3.6 Video/image codec hardware acceleration
Compatible with the NVIDIA Video Codec SDK, including cuvid decode, nvenc (up to v13.0), and nvjpeg (up to v12.4). Also compatible with NPP interfaces (up to v12.9). This enables direct support for hardware codec acceleration in higher-level frameworks such as FFmpeg (up to v7.1.1), OpenCV4, DALI (up to v1.44), PyAV, and TorchCodec.
Video decode
Supports the NVIDIA
cuviddecoder.Codecs:
HEVC (H.265) - ITU-T Rec. H.265 (04/2013), ISO/IEC 23008-2
Main Profile, Level 5.1, High Tier
Main10 Profile, Level 5.1, High Tier
Main Still Profile
VP9 - vp9-bitstream-specification-v0.6-20160331-draft
Profile 0, 8-bit
Profile 2, 10-bit
AVC (H.264) - ITU-T Rec. H.264 (03/2010) / ISO/IEC 14496-10
Main Profile, levels 1 - 5.2
High Profile, levels 1 - 5.2
High 10 Profile, levels 1 - 5.2
Baseline Profile, levels 1 - 5.2
AV1 Bitstream & Decoding Process Specification Version 1.0.0 with Errata 1
Main Profile, Level 5.1
AVS2
Resolution up to 8192×8192
Up to 192 FHD streams
Video encode
Supports
nvenc.Codecs:
AVC (H.264): Spec Version 12:ISO/IEC 14496-10 / ITU-T Rec. H.264 (03/2010)
Baseline Profile, levels 1 - 5.2
Main Profile, levels 1 - 5.2
High Profile, levels 1 - 5.2
High 10 Profile, levels 1 - 5.2
HEVC (H.265): ITU-T Rec. H.265 (04/2013), ISO/IEC 23008-2
Main Profile, Level 5.1, High Tier
Main10 profile, Level 5.1, High Tier
Main Still Profile
AV1 Bitstream Specification Version 1.0.0 with Errata 1
Main Profile, Level 5.1
Supports resolutions up to 4K.
Supports input RGB format (converted to YUV420 via inlinePP).
Supports crop, scale, and rotate with inlinePP.
Up to 32 FHD streams
JPEG:
Supports
nvjpegdecoder & encoder.Resolution up to 32K×32K
Supports RGB format input and output with inlinePP.
Supports crop, scale, and rotate with inlinePP.
Up to 960 FPS for UHD
Image processing:
Supports NVIDIA 2D Image NPP.
1.3.7 Software tools
The following PPU management tools and libraries are available for cloud-scale monitoring and integration into operational systems:
PPU device management tool
ppu-smi(similar tonvidia-smi). For details, see PPU-SMI Device Management Tool.New features in
ppu-smiv1.3:Supports querying the HBM manufacturer.
Supports setting and querying the drain state.
Supports querying the rear-panel ID.
Allows the
toposubcommand to filter and group the topology diagram by rear-panel ID.Allows the
toposubcommand to display RDMA NIC information in the topology diagram.
New features in
ppu-smiv1.4:Supports querying XID error codes.
Supports querying performance counter status.
Adds
gpmsubcommand to query and set GPM.Supports querying tidal mode.
Supports querying product architecture and minor number.
Supports setting and querying MPS mode.
New features in
ppu-smiv1.5:Updates known issues.
Supports querying version information of SDK components.
Data center management and monitoring tool PPU DCGM (similar to NVIDIA DCGM). For details, see DCGM Management and Monitoring Tool.
New features in DCGM v1.3:
Supports field IDs related to cache hit rates.
Supports field IDs for Tensor Core utilization.
The main new features in DCGM v1.4 include:
Added support for field IDs for ICN per-link transmit and receive rates.
Updated the field ID support list.
New features in DCGM v1.5 include:
Instructions for using DCGM in a Docker environment.
Enhancements in DCGM v1.6 include:
Support for field IDs related to integer compute pipe utilization.
hgml(similar to NVIDIAnvml).
Provides the PPU performance analysis tools Asight Systems and Asight Compute (similar to NVIDIA Nsight Systems and Nsight Compute) for analyzing single-node, multi-node, training, and inference performance.
Asight Systems is a low-overhead, system-level performance analysis tool. It collects system events, CPU and PPU activities, API execution times, call stacks, NVTX ranges, and CPU/PPU activity correlations, and presents them in a unified Timeline View. Developers can use the Timeline View to analyze CPU/PPU workloads, identify performance bottlenecks, and maximize parallelism. For details, see Asight Systems Application Performance Analysis Suite.
New features in Asight Systems v1.3:
Supports Python Functions Trace to profile specified Python functions without modifying user code.
Supports collecting application log output and tracking device memory allocation failures.
Adds Expert System and Statistics System with 15 analysis rules.
asys statssupports duration statistics and trace export for HGGC APIs, OSRT APIs, HGTX ranges, and HGGC kernels.asys statscorrelates HGTX and PPU-side traces to output statistical reports and export correlated data.
Timeline View enhancements:
Displays HGGC Launch APIs in the Timeline View by the names of the kernels they launch.
The Timeline View supports the display of the blocking property for user-created streams.
Timeline View now supports the WASD shortcut keys for zooming and panning. A prompt now notifies you if an inaccurate acu command is generated when you right-click a timeline item of the kernel type.
Function tables, such as the Top-Down View, support searching by module name.
Advanced Open feature supports more event types (PCCL, Log, Backtrace, NIC metrics).
New features in Asight Systems v1.4:
Improves UI styling and layout, with more tab styles available. Supports closing report tabs while a report is loading.
asysenhancements: The tool now supports specifying the CPU and Python profiling call stack depth. The tool can collect trace data for a subset of application processes and basic PPU information such as frequency and temperature. It also supports a shorter sampling period for CPU call stack information. Theasys statscommand supports HGGC kernel grid and block statistics, trace export, and both HGGC and memory Python backtrace call stack collection. TheasysPython Functions Trace feature supports collecting all threads under a Python process.The Timeline View is enhanced. It now supports custom HGTX colors and updates the time percentage of PPU nodes after filtering. The view can display RDMA network card metrics, PPU Activity dependencies, and HGGC Graph information independently. You can also mark timelines and show different types of video timelines in different colors. The HGGC Launch API is now displayed by kernel name. Additionally, the Events View adds a tile mode and improves search history autofill. The Function View adds flame graphs and icicle graphs. The HGTX range summary now supports specifying process and thread lists.
New features in Asight Systems v1.5:
asys statssupports HGTX PPU projection summary statistics.asys stats supports statistics on tracked data volume and time consumption for HGGC PPU memory.
The asys stats subcommand now supports adding an HGTX range prefix for PPU kernel statistics.
The asys stats subcommand's HGTX Range Summary supports filtering by process.
The PPU tracking and statistics feature of the asys stats subcommand supports specifying a list of PPU devices.
The asys stats subcommand supports two viewing modes for Device Memory Usage Details and four for Device Memory Usage Summary.
The asys analyze subcommand supports a selection mode to specify a time range for PPU time utilization analysis.
Simplified the description for the asys expert and statistics systems and added a link to the documentation.
asys supports limiting the generated report file size.
asys supports collecting device and pinned memory usage via the --hggc-memory-usage option.
Supports monitoring the usage of dynamically allocated memory on the CPU side, including memory leak analysis, memory usage statistics, and allocation count statistics.
Supports collecting compute resource information associated with an HGGC context when MPS mode is enabled.
Memory View supports four view modes and a flame graph.
The Timeline view improves the display of PPU activity dependencies.
Timeline View supports a group display feature that lets you add timeline rows of interest to the Group View and display them separately.
Timeline View supports the Device Memory Timeline for analyzing the memory usage of each module. This timeline supports three modes: normal, grouped, and grouped and colored.
Timeline View supports a hierarchical view of communication operators.
Timeline View displays different kernels in different colors.
The Timeline View supports a timeline for CPU heap memory.
The time range tooltip now shows the percentage of PPU active/idle time.
In Timeline View, hold down the Shift key when selecting a time range to snap to the nearest timeline start or end point.
Timeline View supports selecting multiple timeline rows by pressing the Shift or Ctrl key.
Optimized the performance of Timeline View to resolve GUI unresponsiveness when opening very large reports.
The HGGC API supports a mixed display of C and Python call stacks.
New features in Asight Systems v1.6:
asyssupports trace collection for CPU metrics.The asys analyze subcommand supports specifying a list of Compute Pipes in MPS mode for PPU time utilization analysis.
asys supports collecting trace data from multi-node applications launched by the Ray framework, and a report is generated for each server.
asys supports collecting trace data from multi-node applications launched by mpirun, generating one report for each server.
asys supports collecting trace data for HGGC stream memory operations.
The asys stats subcommand supports filtering the HGTX PPU Projection Trace / Summary by HGTX range.
The HGTX PPU Projection Summary of the asys stats subcommand outputs the time percentage and total time of HGTX projection.
The asys stats subcommand supports filtering by HGTX range for the HGTX Range Kernel Trace / Summary.
The
asys statssubcommand'sHGTX Range Kernel Tracesupports exporting HGGC Graph information.The asys stats / analyze subcommand supports specifying the output precision for ratio data.
The asys stats subcommand supports analyzing the asynchrony between PCCL communication kernels and exporting trace and summary data.
asys supports projecting the HGTX range during the HGGC graph capture phase to the corresponding activity of the PPU-side HGGC graph node.
ASYS supports event-based control to start and stop a capture range multiple times. All traces are saved to a single report.
asys lets you specify PPU device IDs to trace only the processes that use those devices.
Timeline View supports local options, which let you hide rows you are not interested in and customize the report's display.
The Timeline View now groups and displays kernel nodes by kernel name.
Added global tips to Timeline View to show shortcut information.
Calculates the time percentage for PCCL separately in the time range tooltip of Timeline View.
The CPU timeline colors threads by name.
The HGGC PPU Kernel Summary rule automatically sums the percentages for the Time and Total Time columns.
Added PCCL Desynchronization Summary / Trace rules to the statistics system to analyze desynchronization between PCCL kernels.
Bookmarks supports import/export and load/save.
The statistical and expert systems support searching and filtering tables.
Asight Compute is a kernel performance analysis tool. It collects PPU hardware performance counters and combines them into metrics. The GUI presents these metrics from various dimensions to help you analyze and optimize kernels in depth. For details, see Asight Compute Kernel Analyzer.
New features in Asight Compute v1.3:
The Metric Details Widget supports displaying a list of metric instances.
The Raw Page and Summary Page support selecting the display format for multi-instance metrics. The selection mode is changed from row-based to cell-based selection.
Adds an ICN link throughput table.
acusupports the--clock-controloption.
New features in Asight Compute v1.4:
Adds topology diagram display for 16-card and 8-card Zhenwu 810E configurations.
The Source Page now supports Source Marker and can collect and display kernel assembly instruction execution information, including Instructions Executed and Thread Instructions Executed.
Improves metric accuracy and enhances stability.
New features in Asight Compute v1.5:
The Memory Chart in the Details Page supports display by transfer size or throughput.
The tooltip for connection links in the Details Page Memory Chart now displays link utilization.
Tooltips on the Details Page can be pinned. After a tooltip is pinned, its text can be selected and copied.
Added Stack Size Per Thread to Launch Statistics on the Details Page.
Added Driver SharedMemory Per Block to Launch Statistics on the Details page.
The Baseline button layout is updated to show what each button does.
The Source Page supports jumping from branch instructions and highlighting all search results.
Source Page enhances source code resolution by automatically resolving other files in the same directory structure.
New features in Asight Compute v1.6:
The Source Page indicates whether the source code is imported, its import source, and how to collect line information.
You can view not issued stall reasons on the Source Page and the Details Page.
The Source Page provides a Source Lookup button and a "Remember import directory" option.
The Source Page allows you to click the file not found message to open the source code import window.
The Source Page supports syntax highlighting for Python and Pasm.
The Source page supports table header tooltips.
The Source Page lists functions in ascending order by address.
The Source Page displays the source code included with the report.
The Metric Details window sorts the searched metrics.
1.4 Supported operating systems
Category | Operating system | Architecture | Kernel version | GCC |
Ubuntu | Ubuntu 24.04 LTS | x86_64 | 6.8.0-53-generic | 13.3.0 |
Ubuntu 22.04 LTS | 6.2.0-39-generic | 11.4.0 | ||
Ubuntu 20.04 LTS | 5.4.0-131-generic (GA) | 9.5.0 | ||
5.4.0-92-generic | 9.5.0 | |||
Ubuntu 18.04 LTS | 4.15.0-112-generic (GA) | 7.5.0 | ||
4.18.0-15-generic | 7.5.0 | |||
CentOS | CentOS 8.2 | 5.10.134-007.ali5000.al8.x86_64 | 8.5.0 | |
AliOS | AliOS 7U2 | 5.10.112-005.ali5000.alios7.x86_64 | 10.2.1 | |
5.10.84-004.ali5000.alios7.x86_64 | 10.2.1 | |||
alippu-driver-4.19.91-014.kangaroo.alios7.x86_64 | 10.2.1 | |||
Alibaba Cloud Linux | Alibaba Cloud Linux 3 | 5.10.134-12.2.al8.x86_64 | 10.2.1 | |
5.10.134-13.al8.x86_64 | 10.2.1 |
1.5 SDK compatibility
1.5.1 KMD compatibility
Version 1.6 is backward-compatible with the kmd and mcu_fw components from versions 1.5 and 1.4.
1.5.2 Firmware compatibility
Zhenwu 810E requires mcu_fw version 1.2.1 or later.
1.5.3 SDK compatibility
SDK v1.6 maintains backward compatibility with SDK v1.5 for APIs, device binary formats, and library files. However, like v1.5, this version is not backward-compatible with SDK v1.4. The following sections describe these breaking changes.
SDK v1.5 introduced four changes to files, APIs, and the compilation environment. These changes, also present in v1.6, can cause incompatibilities when you mix components from different SDK versions. The changes are as follows:
The SDK no longer includes the
libgomp.soandlibomp.solibrary files. It now uses the versions from your host operating system and host compiler, such as GCC or Clang.This change may cause applications built with older SDKs to fail when running in a v1.5 or v1.6 environment, producing a "missing shared library" error.
Compiler options with the
-alippu-xxxprefix now use the-ppu-xxxprefix.Because these options are primarily used in custom compilation scenarios, this change may cause compilation errors when compiling with source code or running JIT processes from different SDK versions.
Several PTX extension instruction prefixes have changed:
alippu.mma.xxxchanges toppu.mma.xxx.alippu.ldmatrix.xxxchanges toppu.ldmatrix.xxx.cp.async.aiu.xxxchanges toppu.cp.async.aiu.xxx.
The custom data type
__ali_bfloat16in SDK header files is now__ppu_bfloat16.
The last three changes can cause build failures in some open-source PPU libraries, such as vllm, cutlass, flash-attn, and flashinfer. You must use library versions that are updated for these v1.5 changes.
In summary, these four changes can cause compilation and runtime issues if you do not fully update your source code and runtime components. These potential incompatibilities have been confirmed by internal SDK compatibility tests. To avoid these problems, we recommend using the complete v1.5 or v1.6 SDK for your build and runtime environments.
1.5.4 Asight file compatibility
Asight Systems/Compute v1.6 is compatible with v1.5 report files.
2. CUDA ecosystem compatibility
2.1 Introduction
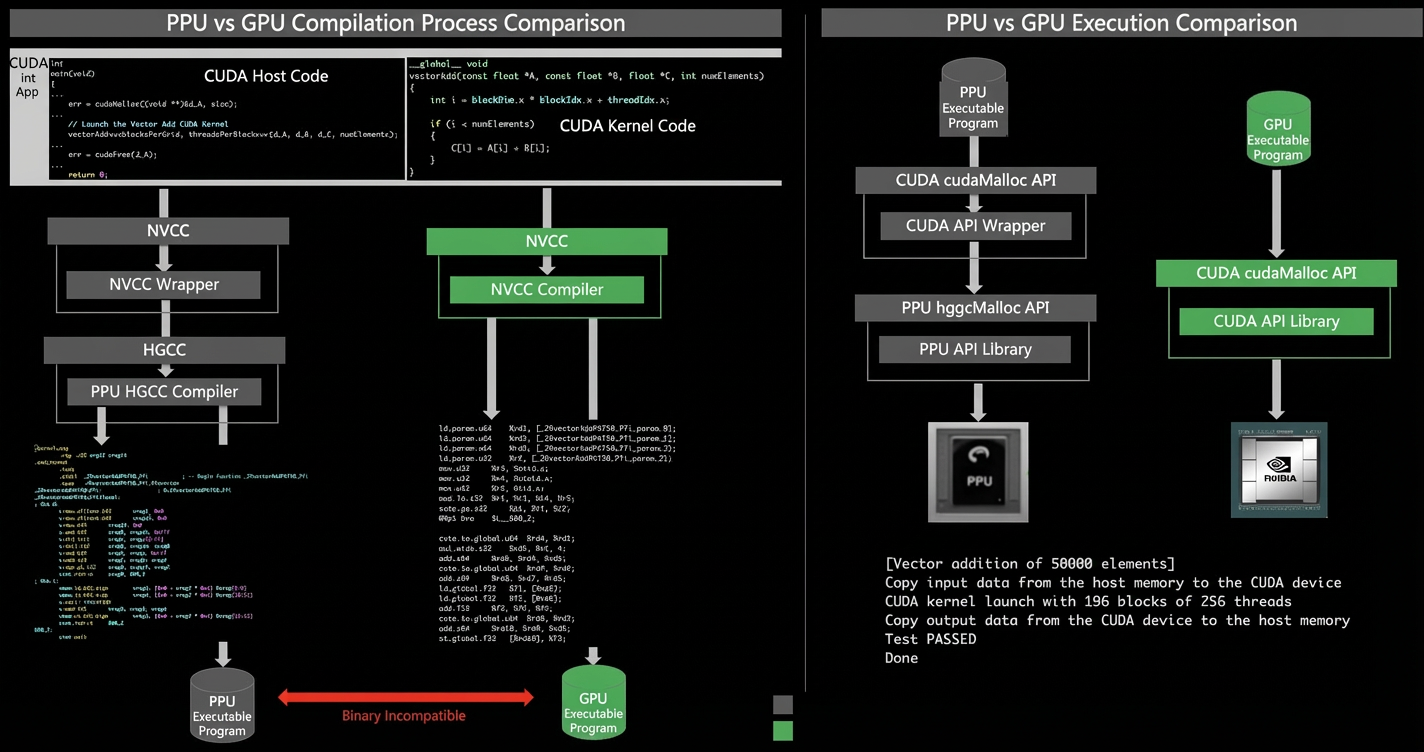
Applications for the PPU platform can be developed using either the PPU SDK API or the CUDA language. Applications written in CUDA must be recompiled with the PPU compiler to run on a PPU. The following figure illustrates the differences in compiling and running the same CUDA application on a PPU versus a GPU.
CUDA ecosystem compatibility approach: Automatic code generation creates a CUDA SDK Wrapper that ensures API compatibility across different CUDA versions. This allows CUDA applications to run on the PPU after recompilation with the PPU compiler.
This solution provides source code compatibility between PPUs and GPUs, but their binaries remain incompatible.
2.2 CUDA API compatibility
PPU SDK v1.6 supports CUDA API versions up to 12.8.0. However, due to differences in the hardware architecture, CUDA API compatibility focuses primarily on the deep learning domain. The following table lists the supported versions. For more information, see Compatibility.
CUDA version |
11.1 |
11.2 |
11.3 |
11.4 |
11.5 |
11.6 |
11.7 |
11.8 |
12.1 |
12.2 |
12.3 |
12.4 |
12.5 |
12.6 |
12.8 |
12.9 (preview) (Validated with CUDA Samples and PyTorch 2.7 unit tests, but has not undergone comprehensive end-to-end model testing.) |
2.3 Open-source frameworks and libraries
2.3.1 Supported open source frameworks and libraries
Framework/library | Version |
apex | 24.4.1 |
auto_gptq | 0.7.1 |
bitsandbytes | 0.40.0, 0.41.0, 0.42.0, 0.43.0, 0.44.1, 0.45.3 |
byte_flux | 1.0.4, 1.1.1 |
cumm | 0.2.9, 0.5.3 |
cupy | 13.1.0, 13.3.0, 13.4.1 |
faiss | 1.7.3, 1.7.4, 1.8.0 |
cutlass | 2.4, 3.3, 3.4.1, 3.5, 3.6, 3.7 |
flash-attn | 1.0.5, 2.0.9, 2.4.2, 2.4.3, 2.5.0, 2.5.1, 2.5.2, 2.5.3, 2.5.4, 2.5.5, 2.5.6, 2.5.7, 2.5.8, 2.5.9, 2.6.0, 2.6.1, 2.6.2, 2.6.3, 2.7.0, 2.7.1, 2.7.2, 2.7.3, 2.7.4.post1 |
flashinfer | 0.1.0, 0.1.1, 0.1.2, 0.1.6, 0.2.0.post1, 0.2.1.post1, 0.2.2.post1, 0.2.3, 0.2.6 |
DeepGemm | main |
grouped_gemm | 1.1.4 |
jax_cuda12_pjrt | 0.4.34 |
jax_cuda12_plugin | 0.4.34 |
jaxlib | 0.4.34 |
lightllm | 1.0.0 |
lmdeploy | 0.4.2, 0.5.3, 0.6.3, 0.6.4, 0.7.0, 0.7.1 |
mamba_ssm | 2.1.0, 2.2.0, 2.2.1, 2.2.2 |
mlflow | 2.16.1, 2.16.2, 2.17.0, 2.17.1, 2.17.2, 2.18.0 |
mmcv-full | 1.4.2, 1.5.3, 1.6.0, 1.7.2 |
mmcv | 2.0.0, 2.1.0, 2.2.0 |
mmdet | 2.14.0, 2.24.0, 2.26.0, 2.28.2, 3.3.0 |
mmdet3d | 1.17.0, 1.0.0rc4, 1.0.0rc6, 1.4.0 |
natten(*) | 0.17.3, 0.17.5 |
numba | 0.55.0, 0.58.0, 0.59.0, 0.60.0, 0.61.0rc2, 0.62.0dev0 |
nvidia_dali_cuda120 | 1.20.0, 1.44.0 |
onnxruntime_gpu | 1.20.0, 1.20.1 |
onnxruntime_training | 1.18.0, 1.19.0, 1.19.2 |
open3d | 0.18.0, 0.19.0 |
opencv-contrib-python | 4.10.0.84 |
paddlepaddle-gpu(*) | 2.6.2, 3.0.0 |
pytorch3d | 0.7.6, 0.7.7 |
sgl_kernel | 0.0.2.post8, 0.0.3, 0.0.3.post6, 0.0.5 |
sglang | 0.2.14, 0.4.1, 0.4.2, 0.4.3, 0.4.4.post1, 0.4.4.post3 |
spconv-cu | 2.1.21, 2.2.6, 2.3.6 |
TensorFlow | 2.14.1, 2.17.0, 2.6.3 |
torch | 1.10.0, 1.10.1, 1.8.0, 1.9.0, 1.9.1, 2.0.1, 2.1.0, 2.1.2, 2.2.0, 2.2.1, 2.3.0, 2.3.1, 2.4.0, 2.5.1, 2.6.0, 2.7.0 |
torch_xla | 2.3.0, 2.4.0, 2.5.1, 2.6.0 |
torchao | 0.2.0, 0.3.0, 0.4.0, 0.7.0 |
torchaudio | 2.4.0, 2.5.1 |
torchdata | 0.6.1, 0.7.0, 0.7.1, 0.8.0 |
torchrec | 0.7.0 |
torchtext | 0.15.2, 0.16.0, 0.16.2, 0.17.0, 0.17.1, 0.18.0 |
torchvision | 0.10.0, 0.10.1, 0.11.0, 0.11.1, 0.16.2, 0.19.0, 0.20.1 |
transformer_engine | 1.11, 1.12, 1.13, 1.5, 1.7, 2.0 |
triton | 2.1.1, 2.2.0, 3.0.0, 3.1.0, 3.2.0, 3.3.0 |
vllm-flash-attn | 2.6.2, 2.7.2.post1 |
vllm | 0.6.3.post1, 0.6.4.post1, 0.6.6.post1, 0.7.1, 0.7.2, 0.7.3, 0.8.3, 0.8.5, 0.9.1 |
xformers | 0.0.22, 0.0.25, 0.0.27, 0.0.29.post1, 0.0.30 |
xgboost | 1.6.2, 2.0.1, 3.0.2 |
OneFlow | 0.7.0 |
MXNet | 1.8.0 |
TorchACC | 1.12 |
HIE-ALLSPARK | 1.0.0 |
BladeDISC | 0.21 |
rtp-llm | 0.2.0 |
Triton Inference Server | 2.21.0 |
Megatron-Core | 0.5.0, 0.7.0, 0.8.0, 0.9.0 |
DeepSpeed-Megatron | 0.2.0 (d65921c) |
DeepSpeed | 0.8.0, 0.10.0, 0.12.3, 0.13.1, 0.14.4 |
Horovod | 0.24.2 |
ray | 2.6.1, 2.8.0 |
Nemo | 1.13.0 |
NVTabular | 0.7.1 |
rmm | 23.2.0a0 |
torchmetrics(*) | 1.4.0 |
fbgemm | 0.7.0 |
nvidia_dali_cuda110(*) | 1.20.0 |
nvidia_dali_cuda120(*) | 1.20.0 |
wholegraph(*) | 24.12.00a |
gsplat(*) | 1.5.3 |
lammps(*) | 2024.8.29.0.0 |
lightgbm(*) | 4.5.0, 4.6.0 |
MinkowskiEngine(*) | 0.5.4 |
taichi(*) | 1.7.3 |
tilelang(*) | 0.1.4, 0.1.5 |
colmap(*) | 3.10 |
mirage(*) | 0.2.4 |
Block-Sparse-Attention(*) | 0.0.1 |
llama.cpp(*) | master |
cuDF(*) | 25.08 |
k2(*) | master |
MagiAttention(*) | 1.0.2 |
taming-3dgs(*) | master |
dgl | 2.4.0 |
HierarchicalKV(*) | master |
SageAttention(*) | 1.0.6, 2.0.1 |
BitBLAS(*) | 0.1.0 |
mmsegmentation(*) | 1.2.2 |
torchani(*) | 2.2.4 |
pytorch_scatter(*) | 2.1.2 |
Notes:
PyTorch open source support:
PyTorch versions 2.1 and earlier are based on the corresponding NGC releases.
PyTorch versions 2.1.2 and later are based on their corresponding open source community releases.
TensorFlow open source support:
TensorFlow 1.12 from the Google open source community supports only CUDA 9, and version 1.15 supports only CUDA 10. https://www.tensorflow.org/install/source?hl=en#gpu_support_3
Our release of TensorFlow 1.15 is based on the NVIDIA NGC nv22.04 release. https://docs.nvidia.com/deeplearning/frameworks/support-matrix/index.html#unique_1997996242
Our release of TensorFlow 1.12 is based on PAI TF 1.12.
Our release of TensorFlow 2.4 is based on NGC nv21.02.
Our releases of TensorFlow 2.6 and 2.7 are based on Google's official community releases.
Our release of TensorFlow 2.8 is based on NGC nv22.04.
Our releases of TensorFlow 2.10 and later are based on Google's official community releases.
Items marked with an asterisk (*), such as FlashAttention(*) and cutlass(*), are based on their open source community versions. Our support for these items covers functionality but not performance optimization.
Most other open source frameworks and libraries are based on their community releases, with some exceptions based on NGC releases. See the user guide for each item for more details.
The PPU SDK ensures that all listed open source frameworks and libraries compile correctly, provide basic functionality, and pass unit tests. However, due to resource constraints, some issues found during testing remain unresolved in the v1.5 release and are documented in the Known Issues section.
2.3.2 Open-source framework compatibility
Framework | Version | Test type | Pass rate |
PyTorch | 1.7 | Unit Test | 98.5% |
PyTorch | 1.8 | Unit Test | 97.6% |
PyTorch | 1.9 | Unit Test | 93.5% |
PyTorch | 1.10 | Unit Test | 94.7% |
PyTorch | 1.11 | Unit Test | 92.9% |
PyTorch | 1.12 | Unit Test | 95.2% |
PyTorch | 2.1 | Unit Test | 95.7% |
PyTorch | 2.3 | Unit Test | 96.9% |
PyTorch | 2.4 | Unit Test | 97.6% |
PyTorch | 2.5.1 | Unit Test | 98.7% |
PyTorch | 2.6 | Unit Test | 95.8% |
PyTorch | 2.7 | Unit Test | 97.4% |
TensorFlow | 1.15 | Unit Test | 97.6% |
TensorFlow | 2.7 | Unit Test | 89% |
TensorFlow | 2.8 | Unit Test | 91.3% |
TensorFlow | 2.12 | Unit Test | 81.3% |
TensorFlow | 2.14 | Unit Test | 83.6% |
TensorFlow | 2.16 | Unit Test | 83.8% |
TensorFlow | 2.17 | Unit Test | 89.81% |
Megatron-Core | 0.8.0 | Unit Test | 99.7% |
Megatron-Core | 0.7.0 | Unit Test | 97.5% |
DeepSpeed | 0.15.2 | Unit Test | 93.1% |
DeepSpeed | 0.14.4 | Unit Test | 89% |
Horovod | 0.24.2 | E2E Test | 100% |
VLLM | 0.4.1 | Unit Test | 99% |
VLLM | 0.4.2 | Unit Test | 99% |
VLLM | 0.4.3 | Unit Test | 99.98% |
VLLM | 0.5.0 | Unit Test | 100% |
VLLM | 0.5.1 | Unit Test | 99.9% |
VLLM | 0.5.2 | Unit Test | 99.9% |
VLLM | 0.5.3 | Unit Test | 100% |
VLLM | 0.6.0 | Unit Test | 99.3% |
VLLM | 0.7.2 | Unit Test | 80.66% |
VLLM | 0.7.3 | Unit Test | 90.61% |
VLLM | 0.8.3 | Unit Test | 94.65% |
VLLM | 0.8.5 | Unit Test | 86.61% |
VLLM | 0.9.1 | Unit Test | 74.52% |
sglang | 0.4.3 | Unit Test | 85.44% (A800: 85.25%) |
lmdeploy | 0.3.0 | E2E Test | 100% |
lmdeploy | 0.4.0 | Unit Test | 99% |
lmdeploy | 0.4.1 | Unit Test | 98.5% |
lmdeploy | 0.4.2 | Unit Test | 97.7% |
lmdeploy | 0.5.0 | Unit Test | 99% |
lmdeploy | 0.5.1 | Unit Test | 100% |
lmdeploy | 0.5.2 | Unit Test | 97.9% |
lmdeploy | 0.5.3 | Unit Test | 98.5% |
ONNX Runtime | 1.19.2 | Unit Test | 94.9% |
ONNX Runtime | 1.18.0 | Unit Test | 90% |
TransformerEngine | 1.11 | Unit Test | 98.69% |
TransformerEngine | 1.5 | Unit Test | 93.7% |
TransformerEngine | 1.7 | Unit Test | 94.3% |
TransformerEngine | 1.8 | Unit Test | 95.2% |
TransformerEngine | 1.9 | Unit Test | 96.1% |
TransformerEngine | 2.0 | Unit Test | 98.69% |
rtp-llm | 0.2.0 | Unit Test | 100% |
torch XLA | 2.3 | E2E Test | 100% |
xformers | 0.0.27 | Unit Test | 99.9% |
xformers | 0.0.26 | Unit Test | 99.9% |
xformers | 0.0.26 | Unit Test | 99.9% |
xformers | 0.0.25 | Unit Test | 99.9% |
xformers | 0.0.24 | Unit Test | 99.9% |
xformers | 0.0.23 | Unit Test | 99.9% |
xformers | 0.0.22 | Unit Test | 99.8% |
xformers | 0.0.21 | Unit Test | 98% |
flash_attention | 2.4.2 | Unit Test | 99% |
flash_attention | 2.4.3 | Unit Test | 99% |
flash_attention | 2.5.0 | Unit Test | 100% |
flash_attention | 2.5.1 | Unit Test | 100% |
flash_attention | 2.5.2 | Unit Test | 100% |
flash_attention | 2.5.3 | Unit Test | 100% |
flash_attention | 2.5.4 | Unit Test | 100% |
flash_attention | 2.5.5 | Unit Test | 99.9% |
flash_attention | 2.5.6 | Unit Test | 99.9% |
flash_attention | 2.5.7 | Unit Test | 100% |
flash_attention | 2.5.8 | Unit Test | 100% |
flash_attention | 2.5.9 | Unit Test | 100% |
flash_attention | 2.6.0 | Unit Test | 100% |
flash_attention | 2.6.1 | Unit Test | 100% |
flash_attention | 2.6.2 | Unit Test | 100% |
flash_attention | 2.6.3 | Unit Test | 100% |
flash_attention | 2.7.2 | Unit Test | 100% |
vllm-flash-attention | 2.6.2 | Unit Test | 100% |
vllm-flash-attention | 2.7.2.post1 | Unit Test | 100% |
flashinfer | 0.1.0 | Unit Test | 97.9% |
flashinfer | 0.1.1 | Unit Test | 99% |
flashinfer | 0.1.2 | Unit Test | 99.9% |
flashinfer | 0.1.6 | Unit Test | 99.9% |
flashinfer | 0.2.2.post1 | Unit Test | 99.9% |
text embedding inference | 1.5.0 | Unit Test | 99% |
Apex | 24.04.01 | Unit Test | 91% |
auto_gptq | 0.7.1 | Unit Test | 94.3% |
bitsandbytes | 0.40.0 | Unit Test | 99.9% |
bitsandbytes | 0.41.0 | Unit Test | 99.9% |
bitsandbytes | 0.42.0 | Unit Test | 100% |
bitsandbytes | 0.43.0 | Unit Test | 100% |
bitsandbytes | 0.43.1 | Unit Test | 100% |
byte-flux | 1.0.2 | Unit Test | 92.1% |
byte-flux | 1.0.3 | Unit Test | 95.1% |
cupy | 13.1.0 | Unit Test | 95% |
faiss | 1.7.3 | Unit Test | 100% |
faiss | 1.7.4 | Unit Test | 100% |
faiss | 1.8.0 | Unit Test | 100% |
grouped_gemm | 1.1.4 | Unit Test | 92.5% |
mamba_ssm | 2.1.0 | Unit Test | 94.5% |
mamba_ssm | 2.2.0 | Unit Test | 93.9% |
mamba_ssm | 2.2.1 | Unit Test | 99% |
mamba_ssm | 2.2.2 | Unit Test | 100% |
mmcv | 2.2.0 | Unit Test | 99.9% |
nvidia_dali_cuda110 | 1.20.0 | Unit Test | 94.7% |
nvidia_dali_cuda120 | 1.20.0 | Unit Test | 94.7% |
onnxruntime_gpu | 1.15.1 | Unit Test | 92.1% |
onnxruntime_gpu | 1.16.3 | Unit Test | 97.4% |
onnxruntime_gpu | 1.17.1 | Unit Test | 91% |
onnxruntime_gpu | 1.17.3 | Unit Test | 93% |
onnxruntime_gpu | 1.18.0 | Unit Test | 92.4% |
onnxruntime_gpu | 1.18.1 | Unit Test | 95.7% |
onnxruntime_gpu | 1.19.0 | Unit Test | 96% |
pytorch3d | 0.7.6 | Unit Test | 91.2% |
pytorch3d | 0.7.7 | Unit Test | 93% |
torchao | 0.2.0 | Unit Test | 99.9% |
torchao | 0.3.0 | Unit Test | 99.9% |
torchao | 0.4.0 | Unit Test | 99.9% |
torchaudio | 2.0.2 | Unit Test | 99.9% |
torchaudio | 2.1.0 | Unit Test | 91.8% |
torchaudio | 2.1.2 | Unit Test | 92.7% |
torchaudio | 2.2.0 | Unit Test | 93% |
torchaudio | 2.2.1 | Unit Test | 99.9% |
torchaudio | 2.3.0 | Unit Test | 99.9% |
torchaudio | 2.3.1 | Unit Test | 99.9% |
torchaudio | 2.4.0 | Unit Test | 99.9% |
torchaudio | 2.0.2 | Unit Test | 99.9% |
torchdata | 0.6.1 | Unit Test | 100% |
torchdata | 0.7.0 | Unit Test | 100% |
torchdata | 0.7.1 | Unit Test | 100% |
torchdata | 0.8.0 | Unit Test | 100% |
torchmetrics | 1.4.0 | Unit Test | 95% |
torchrl | 0.5.0 | Unit Test | 93.9% |
torchtext | 0.15.2 | Unit Test | 96.9% |
torchtext | 0.16.0 | Unit Test | 97% |
torchtext | 0.16.2 | Unit Test | 97% |
torchtext | 0.17.0 | Unit Test | 96.8% |
torchtext | 0.17.1 | Unit Test | 98% |
torchtext | 0.18.0 | Unit Test | 98% |
torchvision | 0.15.2 | Unit Test | 99.9% |
torchvision | 0.16.0 | Unit Test | 99.9% |
torchvision | 0.16.2 | Unit Test | 97% |
torchvision | 0.17.0 | Unit Test | 100% |
torchvision | 0.17.1 | Unit Test | 100% |
torchvision | 0.18.0 | Unit Test | 98.9% |
torchvision | 0.18.1 | Unit Test | 99.9% |
torchvision | 0.19.0 | Unit Test | 99.9% |
transformer_engine_torch | 1.8 | Unit Test | 92.7% |
transformer_engine_torch | 1.9 | Unit Test | 93.4% |
transformers | 4.30.2 | Unit Test | 94% |
transformers | 4.31.0 | Unit Test | 92.1% |
transformers | 4.32.1 | Unit Test | 93.4% |
transformers | 4.33.2 | Unit Test | 93% |
transformers | 4.34.1 | Unit Test | 93% |
transformers | 4.35.2 | Unit Test | 92.7% |
transformers | 4.36.2 | Unit Test | 92.6% |
transformers | 4.37.2 | Unit Test | 94% |
transformers | 4.38.1 | Unit Test | 94% |
transformers | 4.38.2 | Unit Test | 94% |
transformers | 4.39.3 | Unit Test | 94% |
transformers | 4.40.2 | Unit Test | 95.2% |
transformers | 4.41.2 | Unit Test | 94.9% |
transformers | 4.42.4 | Unit Test | 96% |
transformers | 4.43.0 | Unit Test | 96.7% |
transformers | 4.43.3 | Unit Test | 98% |
3. Known issues
3.1 Driver
For a list of unsupported CUDA APIs, see Unsupported CUDA APIs.
3.2 Compiler
Most CUDA C++ extension APIs and related inline PTX for textures and surfaces are not supported, causing a compilation error.
CUDA C++ extension APIs and inline PTX instructions related to Dynamic Parallelism are not supported, causing a compilation error.
For new instructions in PTX 8.7 and later, some features are not supported by the hardware architecture. This does not affect compilation but causes a runtime error.
The 3-operand min/max instructions in inline PTX are not currently supported and may cause a compilation error. This will be fixed in a future release.
The 128-bit atomic instructions in inline PTX are not supported. This does not affect compilation but causes a runtime error.
The multimem instructions in inline PTX are not supported. This does not affect compilation but causes a runtime error.
The griddepcontrol instruction in inline PTX is not supported. The compiler ignores this instruction, which does not affect compilation or runtime.
The {.level::eviction_priority} and {.level::prefetch_size} properties for ld/st instructions in inline PTX are not supported. The compiler ignores their definitions, which does not affect compilation or runtime. However, .L2::evict_first may cause a compilation error. This will be fixed in a future release.
Instructions and operands related to cache eviction policy in inline PTX are not supported. The compiler ignores their definitions, which does not affect compilation or runtime.
The device file compilation process converts CUDA Device C++ code to LLVM (hgvm) IR, and then to a device binary. This process does not output PTX-format files. For code compilation or codegen on other platforms that involves a PTX generation step, code adaptation is required.
Most CUDA MMA and related data movement PTX instructions are compatible. This includes dense and sparse MMA instructions for specific data types, such as .u8, .s8, .tf32, .bf16, and .f16. However, this results in a performance loss compared to using PPU-specific Tensor Core PTX instructions. If a kernel's performance is critical to the end-to-end process, refactor its algorithm. See the PPU Tensor Core PTX user programming manual and algorithm refactoring guide for details. Unsupported data types and features, such as u4, f64, and sp::ordered_metadata, do not affect compilation but cause a runtime error.
3.3 Acceleration libraries
The libraries' performance across various use cases requires further improvement.
aublas:
Only the APIs listed in CUBLAS APIs Support Status are supported. We continuously add support for more APIs based on demand.
Complex data types are not supported.
Gemm: FP32 Tensor Core is enabled by default. Because the computation order differs, precision may not align with FP32 FMA, causing the matrixMulCUBLAS sample to fail.
Gemv: Only host pointer mode is supported.
BlasLt: Specifying attributes such as 'algo' and 'perf' is not supported.
audnn:
Only the APIs listed in CUDNN APIs Support Status are supported. We continuously add support for more APIs based on demand.
Conv: INT64 and BOOLEAN data types are not supported. A combination of FP16 input with FP32 output is not supported.
3DConv: Performance requires further optimization.
depthwise: Performance for some dgrad use cases requires further improvement.
BN: 1) Only parameters alpha=1 and beta=0 are supported. 2) The ACDNN_BATCHNORM_PER_ACTIVATION mode is not supported.
Pooling: ACDNN_PROPAGATE_NAN is not supported.
RNN: Only acdnnRNNBiasMode_t DOUBLE, FP16/F32 data types, and ACDNN_RNN_ALGO_STANDARD are supported.
Activation: ACDNN_PROPAGATE_NAN and the SWISH Op are not supported.
Softmax: SoftmaxAlgorithm_t FAST is not supported.
TensorOp: acdnnReduceTensor does not support MUL_NO_ZEROS.
MultiHeadAttn: Only the forward op is supported.
Backend: 1) Pre-processing fusion is not supported. 2) A maximum of four pointwise post-processing operations can be fused. 3) Only fp16, fp32, and bf16 data types are supported. 4) Fused pointwise operations only support alpha1 = 1 and alpha2 = 1.
ausolver:
Only the APIs listed in CUSOLVER APIs Support Status are supported. We continuously add support for more APIs based on demand.
Complex data types are not supported.
aufft:
Only the APIs listed in CUFFT APIs Support Status are supported. We continuously add support for more APIs based on demand.
Link-time optimization (LTO) is not supported.
aurand:
Only the APIs listed in CURAND APIs Support Status are supported. We continuously add support for more APIs based on demand.
Only the following generator types are supported: XORWOW, MRG32K3A, and PHILOX4_32_10.
Only legacy order is supported.
Only the following distribution types are supported: default, uniform, uniform double, normal, normal double, lognormal, and lognormal double.
3.4 Interconnect library
Collective operation performance: When using a 16 x Zhenwu 810E server with a tensor parallelism (TP) mode of 2, 4, or 8, check the ICN topology of your machine to select the optimal device placement.
Only v7 of the nccl netplugin is supported.
Executing alltoallV operations with imbalanced send and receive sizes may occasionally cause a deadlock. When this occurs, "ERR_FAB_REQ_TO" exceptions appear in dmesg. You must perform a device reset to restore normal operation.
When multiple pccl communicators run concurrently on the same PPU, a deadlock may occasionally occur. To avoid this issue, do not launch multiple pccl kernels on the same PPU device simultaneously. Setting
NCCL_MIN_NCHANNELSto a value no greater than 16 can help prevent this problem.
3.5 Video and image hardware acceleration
Video decoding does not support raw nvdec mode.
Video decoding does not support legacy formats such as MPEG1, MPEG2, MPEG4, VC1, and VP8.
JPEG decoding does not support lossless JPEG or JPEG2000.
NPP currently supports only Image Process interfaces, not Signal Process interfaces.
3.6 Tools
For known issues related to PPU-SMI, see PPU-SMI Known Issues.
For known issues related to Asight Systems, see Asight Systems Known Issues.
For known issues related to Asight Compute, see Asight Compute Known Issues.
For known issues related to the DCGM monitoring tool, see DCGM Known Issues.
3.7 Frameworks and models
This section describes known issues for open-source frameworks.
Framework | Version | Known issues |
PyTorch | 2.6 |
|
2.7 |
| |
SGLang | 0.4.3 |
|
0.4.7 |
| |
vLLM | 0.7.3 |
|
0.9.1 |
| |
Transformer Engine | 2.0 |
|
FlashInfer | 0.2.6.post1 |
|