acext User Guide (v1.7)
To preserve logical consistency, internal network links in the source code remain unchanged. External users cannot access these links. Contact your account manager (PDSA) if you have questions.
acext provides high-performance operator implementations for PPU devices. These operators, which focus on quantization algorithms, are distributed as Python wheel packages and are open-sourced for customers and partners. You can use these operators during PPU adaptation to accelerate your workloads.
Open-source code repository:
https://code.alibaba-inc.com/ppu_open_source/acext1. Using acext
1.1. Using acext Wheel Package with vLLM/SGLang
Starting with PPU_SDK 1.6, acext is no longer bundled with PPU_SDK. Instead, it is distributed as a Python wheel package. For frameworks that depend on acext, such as vLLM or SGLang, you must first install the acext wheel package by running `pip install acext`. Then, you can use one of the following two methods:
For SGLang ≥ 0.4.10 or vLLM ≥ 0.10.0, the framework loads acext automatically. No extra steps are required.
For SGLang < 0.4.10 or vLLM < 0.10.0, you must set four environment variables to locate the dynamic libraries:
### Append shared library load path
export LD_LIBRARY_PATH="${LD_LIBRARY_PATH}:$(python -c "import sysconfig; print(sysconfig.get_path('purelib'))")/lib"
### Config ACEXT LUT path
export ACEXT_GEMM_CONFIG_DIR="$(python -c "import sysconfig; print(sysconfig.get_path('purelib'))")/include/acext/lut/"
### For vLLM versions < 0.10.0
export ACEXT_OP_PATH="$(python -c "import sysconfig; print(sysconfig.get_path('purelib'))")/lib/libacext_op.so"
### For SGLang versions < 0.4.10
export ACEXT_THOP_LIB_PATH="$(python -c "import sysconfig; print(sysconfig.get_path('purelib'))")/lib/th_op/libth_op.so"
Note: For backward compatibility, current PTG images still include the acext dynamic libraries and header files in PPU_SDK. Therefore, using acext with vLLM or SGLang on PTG images works without issues. However, future releases may switch entirely to a wheel-based installation.
1.2 Supported APIs
acext provides quantization algorithm capabilities through header files and libraries. Its header file structure supports fpAintB mixed-precision quantization, w8a8 quantization, and MoE GEMM. To use acext, you must include the acext.h header file and link against libacext.so.
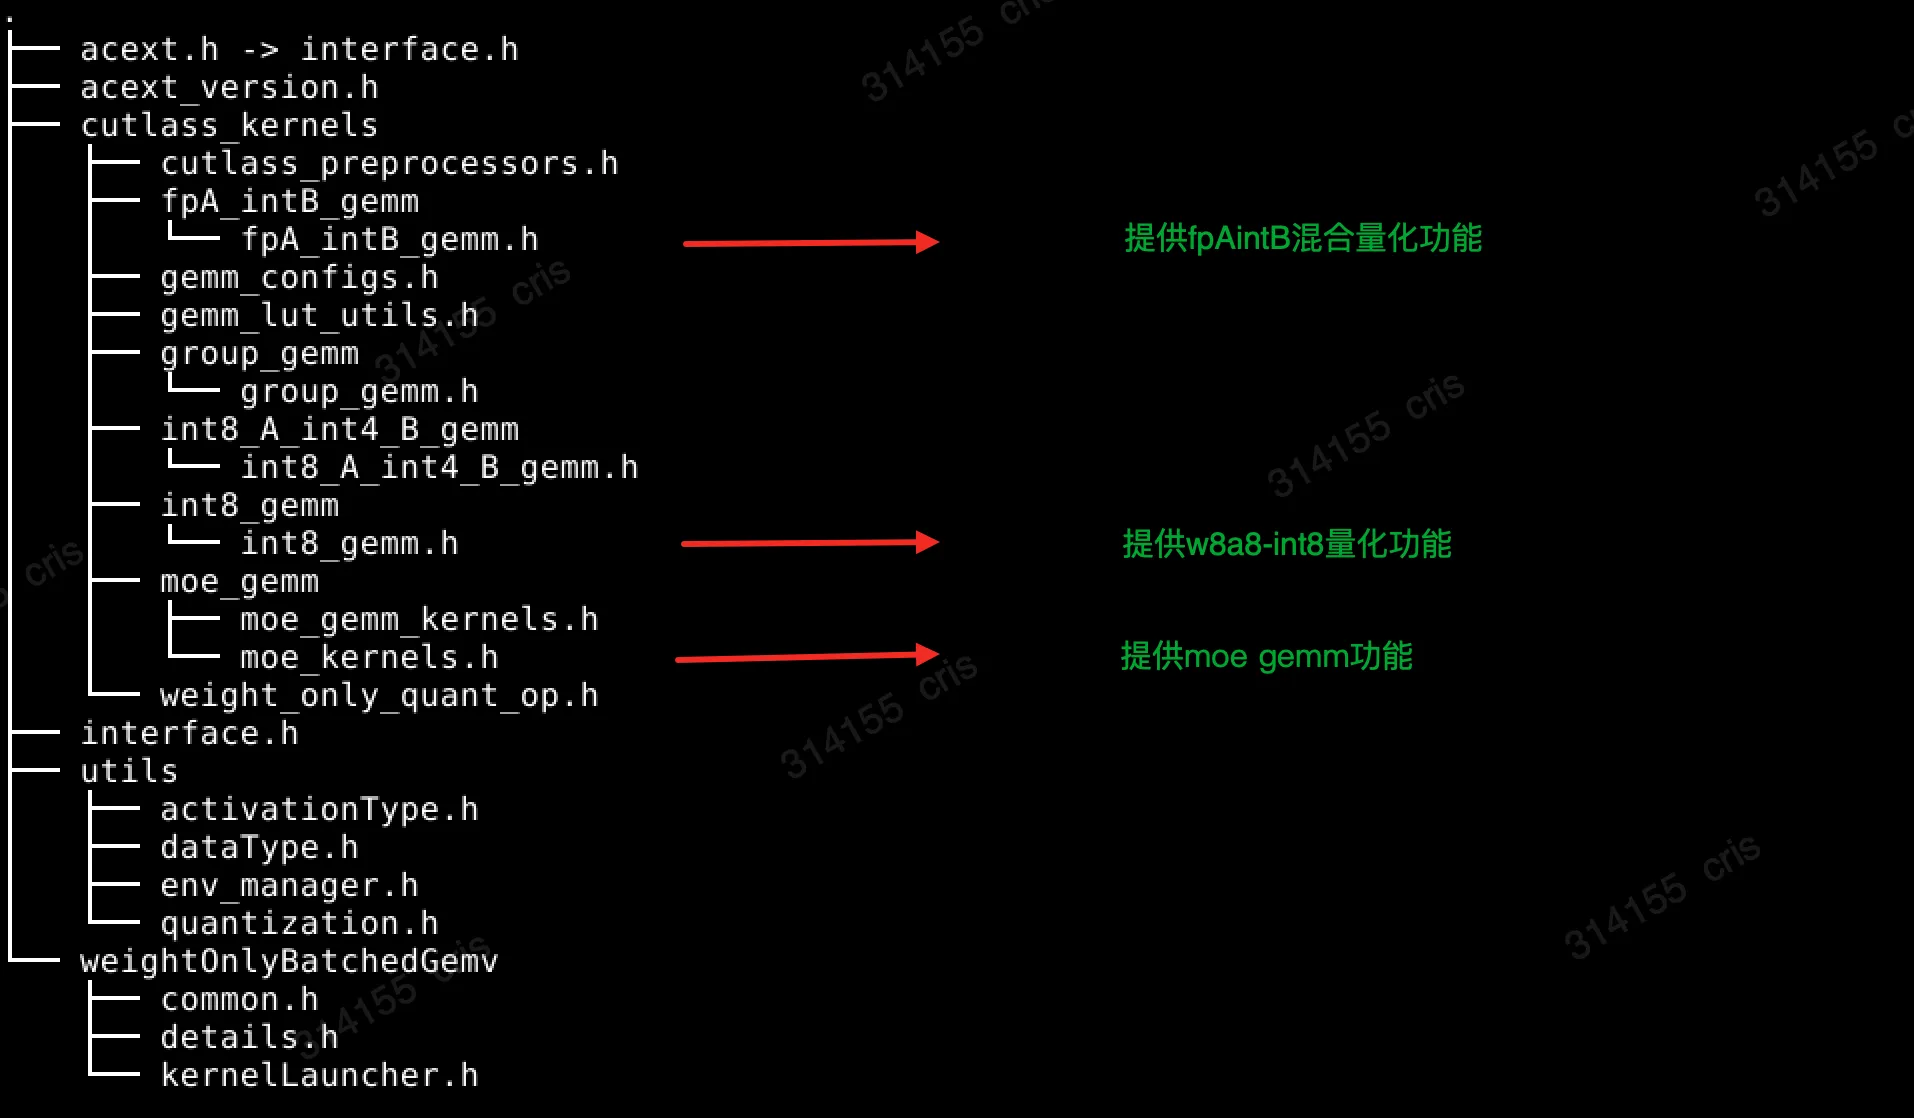
1.2.1 fpAintB GEMM
The fpA_intB_gemm.h header file implements mixed-precision quantization where matrix A is a floating-point type and matrix B is an integer type. Three template parameters are used to define the exact types for A and B, along with the quantization algorithm to use.
template <typename T, typename WeightType, cutlass::WeightOnlyQuantOp QuantOp>
class CutlassFpAIntBGemmRunner : public virtual CutlassFpAIntBGemmRunnerInterface
{
public:
    CutlassFpAIntBGemmRunner();
    ~CutlassFpAIntBGemmRunner();

    void gemm(const void* A, const void* B, const void* weight_scales, void* C, int m, int n, int k,
        tkc::CutlassGemmConfig gemmConfig, char* workspace_ptr, const size_t workspace_bytes,
        cudaStream_t stream) override;

    void gemm(const void* A, const void* B, const void* weight_scales, const void* weight_zero_points,
        const void* biases, void* C, int m, int n, int k, const int group_size, tkc::CutlassGemmConfig gemmConfig,
        char* workspace_ptr, const size_t workspace_bytes, cudaStream_t stream) override;

    // Returns desired workspace size in bytes.
    size_t getWorkspaceSize(const int m, const int n, const int k) override;

    tkc::CutlassGemmConfig getChosenConfig(const void*          A,
                                           const void* B,
                                           const void*          weight_scales,
                                           const void*          weight_zero_points,
                                           const void*          biases,
                                           void*                C,
                                           int               m,
                                           int               n,
                                           int               k,
                                           const int         group_size,
                                           char*             workspace_ptr,
                                           const size_t      workspace_bytes,
                                           cudaStream_t      stream) override;
};

template <typename ActType, WeightOnlyQuantType QType, cutlass::WeightOnlyQuantOp QuantOp>
std::shared_ptr<CutlassFpAIntBGemmRunnerInterface> createFpAIntBGemmRunner();
1.2.2 w8a8 GEMM
The int8_gemm.h header file implements quantization where both matrix A and matrix B are integer types. The template parameter T defines the output data type.
template <typename T>
class CutlassInt8GemmRunner : public virtual CutlassInt8GemmRunnerInterface
{
public:
    CutlassInt8GemmRunner();
    ~CutlassInt8GemmRunner();

    void gemm(const void* A, const void* B, tk::QuantMode quantOption, const float* alphaCol, const float* alphaRow,
        void* C, int m, int n, int k, tkc::CutlassGemmConfig gemmConfig, char* workspacePtr,
        const size_t workspaceBytes, cudaStream_t stream) override;

    // Returns desired workspace size in bytes.
    size_t getWorkspaceSize(const int m, const int n, const int k) override;

    std::vector<tkc::CutlassGemmConfig> getConfigs() const override;

    tkc::CutlassGemmConfig getChosenConfig(const void* A, const void* B, tk::QuantMode quantOption,
        const float* alphaCol, const float* alphaRow, void* C, int m, int n, int k, char* workspacePtr,
        const size_t workspaceBytes, cudaStream_t stream);
};
1.2.3 MoE GEMM
The moe_kernel.h header provides APIs for MoE GEMM operations.
template<typename T,          /*The type used for activations/scales/compute*/
         typename WeightType, /* The type for the MoE weights */
         cutlass::WeightOnlyQuantOp QuantOp,
         typename Enable = void>
class CutlassMoeFCRunner: public CutlassMoeFCRunnerInterface {
public:
    CutlassMoeFCRunner()           = default;
    ~CutlassMoeFCRunner() override = default;
    //for rtp-llm
    void runMoe(const void* input_activations_void, const float* gating_output, const float *gating_output_with_bias,
        const void* fc1_expert_weights_void, const void* fc1_scales_void, const void* fc1_zeros_void, const void* fc1_expert_biases_void,
        ActivationType fc1_activation_type, const void* fc2_expert_weights_void, const void* fc2_scales_void, const void* fc2_zeros_void,
        const void* fc2_expert_biases_void, const int num_rows, const int hidden_size, const int inter_size,
        const int num_experts, const int k, const int group_size, char* workspace_ptr, void* final_output_void, void* fc2_result_void,
        const bool* finished, const int active_rows, void* expert_scales_void,
        int* expanded_source_row_to_expanded_dest_row, int* expert_for_source_row, MOEParallelismConfig parallelism_config,
        MOEExpertScaleNormalizationMode normalization_mode, cudaStream_t stream) override;
    // for vllm
    void fused_moe(const void* input_activations_void, const float* gating_output, const float* gating_output_with_bias,
                   const void* fc1_expert_weights_void, const void* fc1_scales_void, const void* fc1_zeros_void, const void* fc1_expert_biases_void,
                   void* a1_scale_void, ActivationType fc1_activation_type, const void* fc2_expert_weights_void, const void* fc2_scales_void,
                   const void* fc2_zeros_void, const void* fc2_expert_biases_void, void* a2_scale_void, const int num_tokens, const int hidden_size,
                   const int inter_size, const int num_experts, const int k, const int group_size, char* workspace_ptr, void* final_output_void,
                   void* fc2_result_void, const bool* finished, const int active_rows, const void* expert_scales_void,
                   int* expanded_source_row_to_expanded_dest_row, const int* expert_for_source_row, MOEParallelismConfig parallelism_config,
                   MOEExpertScaleNormalizationMode normalization_mode, cudaStream_t stream) override;
acext also provides MoE-related PyTorch operators:
torch.ops.moe_unit_ops.gating_softmax
torch.ops.moe_unit_ops.grouped_gemm_bias
torch.ops.moe_unit_ops.run_moe_fc
For usage examples, see acext/tests/th_moe.py.
1.2.4 DeepGEMM
PyTorch operators:
torch.ops.moe_unit_ops.grouped_gemm_nt_contiguous
torch.ops.moe_unit_ops.grouped_gemm_nt_masked
For usage examples, see acext/tests/th_group_gemm.py.
For the C++ interface, see the corresponding Python implementation.
1.3 Supported Quantization Algorithms
Quantization algorithms reduce memory usage and improve performance by compressing model weights (W) and activations (A) before matrix multiplication. Different kernels target different precision combinations of W and A. The following sections provide a brief overview of each algorithm and its support status in acext.
All code snippets assume a matrix multiplication where A is M×K, W is K×N, and the result is M×N.
1.3.1 Int8 Weight-only (W8A16)
Int8 weight-only is the simplest quantization method. It quantizes weights on a per-column basis, converting them from fp16 to int8. Each column has a single scale factor. Compared to the original fp16 weights, this method reduces memory usage by half. Because less weight data needs to be loaded, performance improves in memory-bound scenarios.
Example code:
// Prepare data: act, weight, scales, and output
......

// Create an FpAIntBGemmRunner with A=half, B=Int8, and PER_COLUMN_SCALE_ONLY quantization
auto runner = createFpAIntBGemmRunner<half, WeightOnlyQuantType::Int8b, cutlass::WeightOnlyQuantOp::PER_COLUMN_SCALE_ONLY>();

// Preprocess weights for mixed-precision GEMM
preprocess_weights_for_mixed_gemm(preprocessed_quantized_weight, row_major_quantized_weight, {k, n}, QuantType::INT8_WEIGHT_ONLY);

// Allocate workspace
char* ws_ptr = nullptr;
const int ws_bytes = runner->getWorkspaceSize(m, n, k);
cudaMalloc(&ws_ptr, ws_bytes);

// Choose kernel config
gemmConfig = runner->getChosenConfig(p_act, p_weight, p_scales, nullptr, nullptr,
                                    p_out, m, n, k, k, reinterpret_cast<char*>(ws_ptr),
                                    ws_bytes, stream);

// Run quantized kernel; result stored in out
runner->gemm(p_act, p_weight, p_scales, p_out, m, n, k, gemmConfig, ws_ptr, ws_bytes, stream);
1.3.2 Int4 Weight-only (W4A16)
Int4 weight-only uses the same algorithm as Int8 weight-only but stores weights using only 4 bits. This reduces memory usage to one-quarter of the fp16 format and further boosts performance, but at the cost of lower accuracy.
Example code:
// Prepare data: act, weight, scales, and output
......

// Create an FpAIntBGemmRunner with A=half, B=Int4, and PER_COLUMN_SCALE_ONLY quantization
auto runner = createFpAIntBGemmRunner<half, WeightOnlyQuantType::Int4b, cutlass::WeightOnlyQuantOp::PER_COLUMN_SCALE_ONLY>();

// Preprocess weights for mixed-precision GEMM
preprocess_weights_for_mixed_gemm(preprocessed_quantized_weight, row_major_quantized_weight, {k, n}, QuantType::PACKED_INT4_WEIGHT_ONLY);

// Allocate workspace
char* ws_ptr = nullptr;
const int ws_bytes = runner->getWorkspaceSize(m, n, k);
cudaMalloc(&ws_ptr, ws_bytes);

// Choose kernel config
gemmConfig = runner->getChosenConfig(p_act, p_weight, p_scales, nullptr, nullptr,
                                    p_out, m, n, k, k, reinterpret_cast<char*>(ws_ptr),
                                    ws_bytes, stream);

// Run quantized kernel; result stored in out
runner->gemm(p_act, p_weight, p_scales, p_out, m, n, k, gemmConfig, ws_ptr, ws_bytes, stream);
1.3.3 Int4 Groupwise (W4A16)
While Int4 weight-only saves memory and boosts speed, its low accuracy makes it unusable for many models. Group-wise quantization solves this issue by splitting each column into groups, such as groups of size 64 or 128. Each group has its own scale factor instead of sharing one per column.
In practice, for methods such as AWQ and GPTQ, you can fine-tune the model weights on a dataset to produce int4 weights. If asymmetric quantization is used, zero points (zeros and bias) are also required.
Example code:
// Prepare data: act, weight, scales, and output
......

// Create an FpAIntBGemmRunner with A=half, B=Int4, and FINEGRAINED_SCALE_ONLY quantization
auto runner = createFpAIntBGemmRunner<half, WeightOnlyQuantType::Int8b, cutlass::WeightOnlyQuantOp::FINEGRAINED_SCALE_ONLY>();

// Preprocess weights for mixed-precision GEMM
preprocess_weights_for_mixed_gemm(preprocessed_quantized_weight, row_major_quantized_weight, {k, n}, QuantType::PACKED_INT4_WEIGHT_ONLY);

// Allocate workspace
char* ws_ptr = nullptr;
const int ws_bytes = runner->getWorkspaceSize(m, n, k);
cudaMalloc(&ws_ptr, ws_bytes);

// Choose kernel config
gemmConfig = runner->getChosenConfig(p_act, p_weight, p_scales, p_zeros, p_bias,
                                    p_out, m, n, k, groupsize, reinterpret_cast<char*>(ws_ptr),
                                    ws_bytes, stream);

// Run quantized kernel; result stored in out
runner->gemm(p_act, p_weight, p_scales, p_zeros, p_bias, p_out, m, n, k, groupsize, gemmConfig, ws_ptr, ws_bytes, stream);
1.3.4 SmoothQuant (W8A8)
fpAintB uses mixed-precision quantization where weights are integers but are dequantized back to floating-point numbers before computation. In contrast, W8A8 keeps both weights and inputs as integers, which enables integer TensorCore operations for better compute throughput.
SmoothQuant is the quantization algorithm that uses W8A8 kernels. For more information, see the SmoothQuant repository on GitHub.
W8A8 supports four variants based on whether per-token (per-row) or per-channel (per-column) quantization is used for matrices A and B:
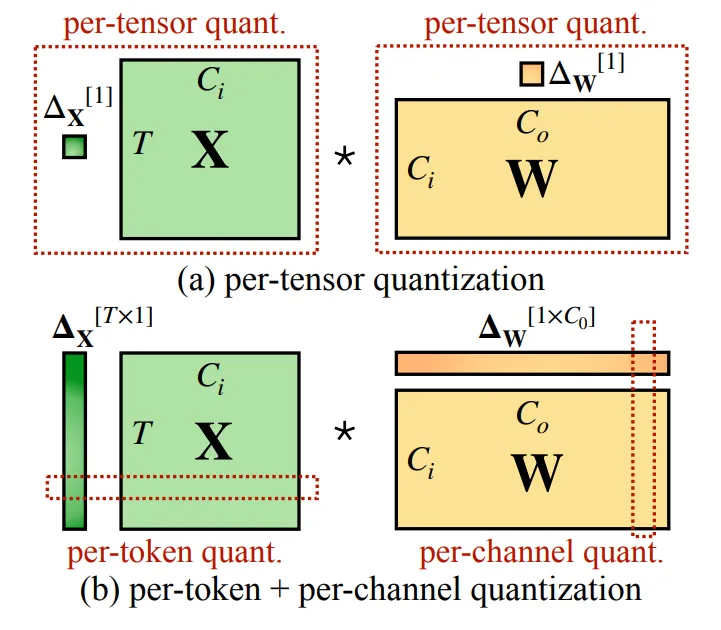
acext implements all four W8A8 variants. You can use them as follows:
// Choose one of the four W8A8 variants:
QuantMode quant_mode = QuantMode::fromDescription(false, false, false, false);  // A_PerTensor_W_PerTensor
QuantMode quant_mode = QuantMode::fromDescription(false, false, false, true);  // A_PerTensor_W_PerChannel
QuantMode quant_mode = QuantMode::fromDescription(false, false, true, false);  // A_PerToken_W_PerTensor
QuantMode quant_mode = QuantMode::fromDescription(false, false, true, true);   // A_PerToken_W_PerChannel

// Prepare data: act, weight, scales, and output
......

// Create W8A8 runner
auto runner = std::make_shared<acext::kernels::cutlass_kernels::CutlassInt8GemmRunner<half>>();

// Allocate workspace
int ws_bytes = runner->getWorkspaceSize(m, n, k);
char* ws_ptr = nullptr;
if (ws_bytes)
    cudaMalloc(&ws_ptr, ws_bytes);

// Choose kernel config
const auto gemmConfig = runner->getChosenConfig(p_act, p_weight, quant_mode,
                    reinterpret_cast<const float*>(p_scales_channels),
                    reinterpret_cast<const float*>(p_scales_tokens),
                    p_out, m, n, k, ws_ptr, ws_bytes, stream);

// Run kernel; result stored in out
runner->gemm(p_act, p_weight, quant_mode,
                    reinterpret_cast<const float*>(p_scales_channels),
                    reinterpret_cast<const float*>(p_scales_tokens),
                    p_out, m, n, k, gemmConfig, ws_ptr, ws_bytes, stream);
1.4 Quantization Kernel Performance
We measured the performance across 22 large language models using various N and K dimensions. We varied M to compute the matrix multiplication time and report the speedup over the baseline cuBLAS fp16.
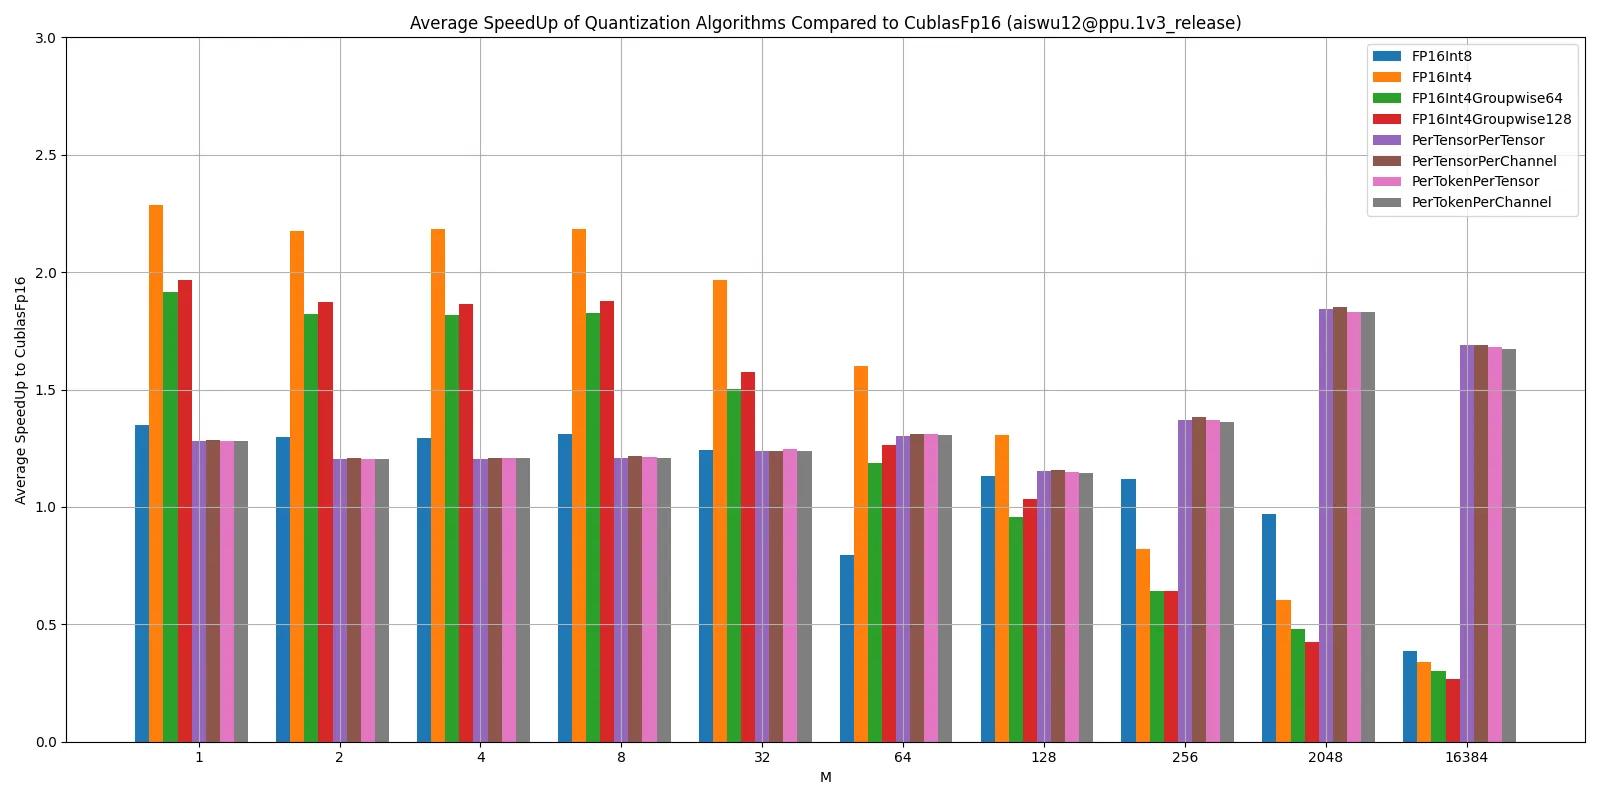
Performance notes:
FpAintB is a weight-only quantization method that reduces weight memory bandwidth, which improves performance in memory-bound cases. However, it adds a dequantization step. In compute-bound scenarios, such as with large batch sizes, this overhead can make quantized kernels slower than non-quantized ones.
W8A8 uses int8 Tensor Cores. With large batch sizes, it can leverage the full compute power of the int8 Tensor Cores.
2. acext Quantization Support in vLLM
We added support for multiple quantization algorithms to vLLM using the PPU-acext library.
vLLM 0.4.2 implementation:
https://code.alibaba-inc.com/ppu_open_source/vllm/tree/v0.4.2/vLLM 0.3.3 implementation:
https://code.alibaba-inc.com/ppu_open_source/vllm/tree/v0.3.3/All performance and accuracy results in the following sections come from running large language models on vLLM 0.4.2.
2.1 Adding Int8 Weight-only Quantization Support
2.1.1 AutoWOQ
To use quantization, you must convert the model weights from fp16 or bf16 to int8.
We provide AutoWOQ for this conversion. Weight-Only Quantization (WOQ) consists of:
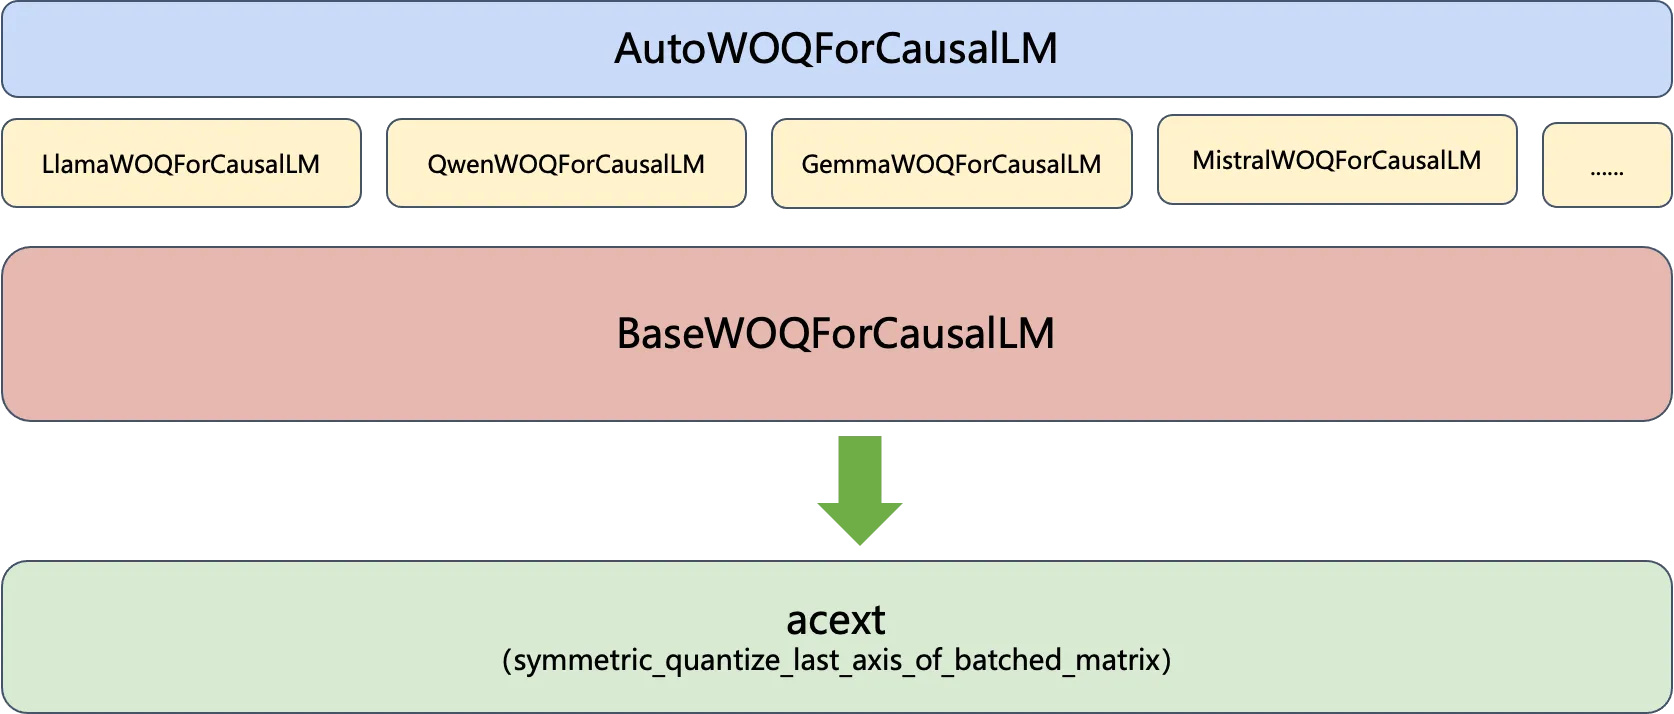
AutoWOQForCausalLM offers a unified entry point for all large language models, similar to the Auto classes in Hugging Face. If you pass the model weight path, AutoWOQForCausalLM detects the model type and initializes the correct WOQForCausalLM instance. All instances inherit from BaseWOQForCausalLM. The core quantization logic resides in BaseWOQForCausalLM and uses symmetric quantization from acext.
You can use AutoWOQ as follows:
# Set quantization parameters (8-bit or 4-bit)
quantize_config = BaseQuantizeConfig(
    bits=8,  # Quantize model to 8-bit
)

# Load unquantized weights (Hugging Face format)
model = AutoWOQForCausalLM.from_pretrained(model_path, quantize_config, trust_remote_code=args.trust_remote_code)
tokenizer = AutoTokenizer.from_pretrained(model_path, trust_remote_code=True)

# Quantize the model. Applies symmetric quantization to linear layers.
model.quantize()

# Save quantized model and tokenizer
quant_path = args.output
model.save_quantized(quant_path)
tokenizer.save_pretrained(quant_path)
2.1.2 Enabling WOQ Quantization
After you quantize weights with WOQ, you must add weight-only quantization support to vLLM. When you use WOQ weights, you must explicitly set the quantization method to `weightonly`. You can initialize the LLM object as follows:
# Create an LLM.
llm = LLM(model=model_path, quantization="weightonly")
vLLM then creates quantized tensor parameters for linear layers and calls the mixed-precision kernels at runtime.
As shown in the following figure, a Transformer block in vLLM contains green linear layers that use WeightOnlyQuant.
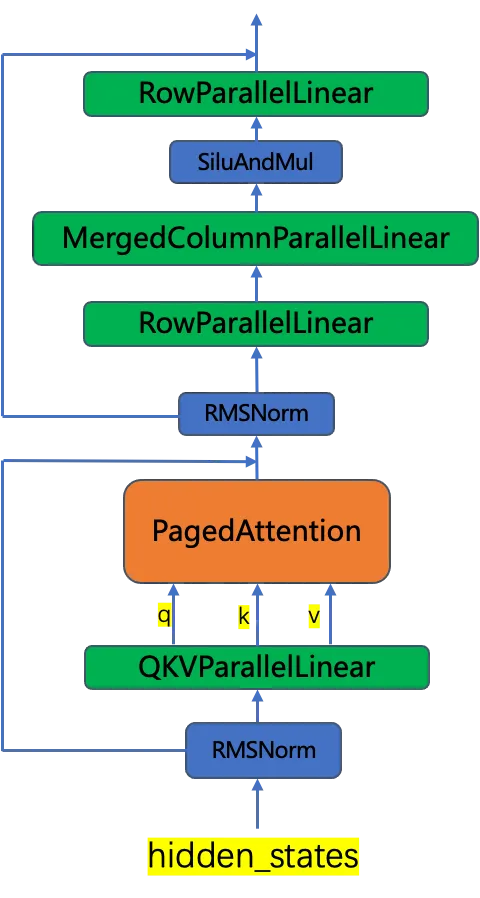
These linear layers use WeightOnlyLinearMethod to initialize weights, load quantized weights, and call acext kernels at runtime. Because acext relies on CUTLASS, the weights require reordering. Currently, this reordering occurs once at system startup.
class WeightOnlyLinearMethod(LinearMethodBase):
    # Set quantization config
    def __init__(self, quant_config: WeightOnlyConfig):
        self.quant_config = quant_config

    # Initialize weights: create int8 weight tensors and load quantized weights
    def create_weights(self, input_size_per_partition: int,
                       output_size_per_partition: int, input_size: int,
                       output_size: int,
                       params_dtype: torch.dtype) -> Dict[str, Any]:
        qweight = Parameter(
            torch.empty(
                input_size_per_partition,
                output_size_per_partition,
                device="cuda",
                dtype=torch.int8,
            ),
            requires_grad=False,
        )
        scales = Parameter(
            torch.empty(
                output_size_per_partition,
                device="cuda",
                dtype=params_dtype,
            ),
            requires_grad=False,
        )

        # Instantiate acext's WeightOnlyQuantMatmul class to call mixed-precision kernels
        try:
            self.weightOnlyMatmul = ops.WeightOnlyQuantMatmul()
        except AttributeError as e:
            raise AttributeError(
                "WeightOnlyQuantMatmul kernels could not be imported. If you built vLLM "
                "from source, ensure BUILD_WEIGHTONLY_KERNELS=1 was set.") from e
        woq_state = WOQState.UNINITIALIZED
        ......

    # Apply weights at runtime using acext quantization kernels
    def apply_weights(self,
                      weights: Dict[str, torch.Tensor],
                      x: torch.Tensor,
                      bias: Optional[torch.Tensor] = None) -> torch.Tensor:
        # Online weight preprocessing (done once at startup)
        if weights["woq_state"] == WOQState.UNINITIALIZED:
            qweight_cpu = weights["qweight"].cpu()
            qweight_cpu = preprocess_weights_for_mixed_gemm(qweight_cpu, torch.int8, False, False)
            weights["qweight"] = qweight_cpu.cuda()
            weights["woq_state"] = WOQState.READY
        qweight = weights["qweight"]
        scales = weights["scales"]
        return self.weightOnlyMatmul.weightonly_gemm(x, qweight, scales, bias)
2.1.3 Running WOQ Models
You can build vLLM with BUILD_WEIGHTONLY_KERNELS=1 to enable weight-only quantization.
# Build vLLM
cd vllm
BUILD_WEIGHTONLY_KERNELS=1 python setup.py develop

# Run offline inference with a quantized model
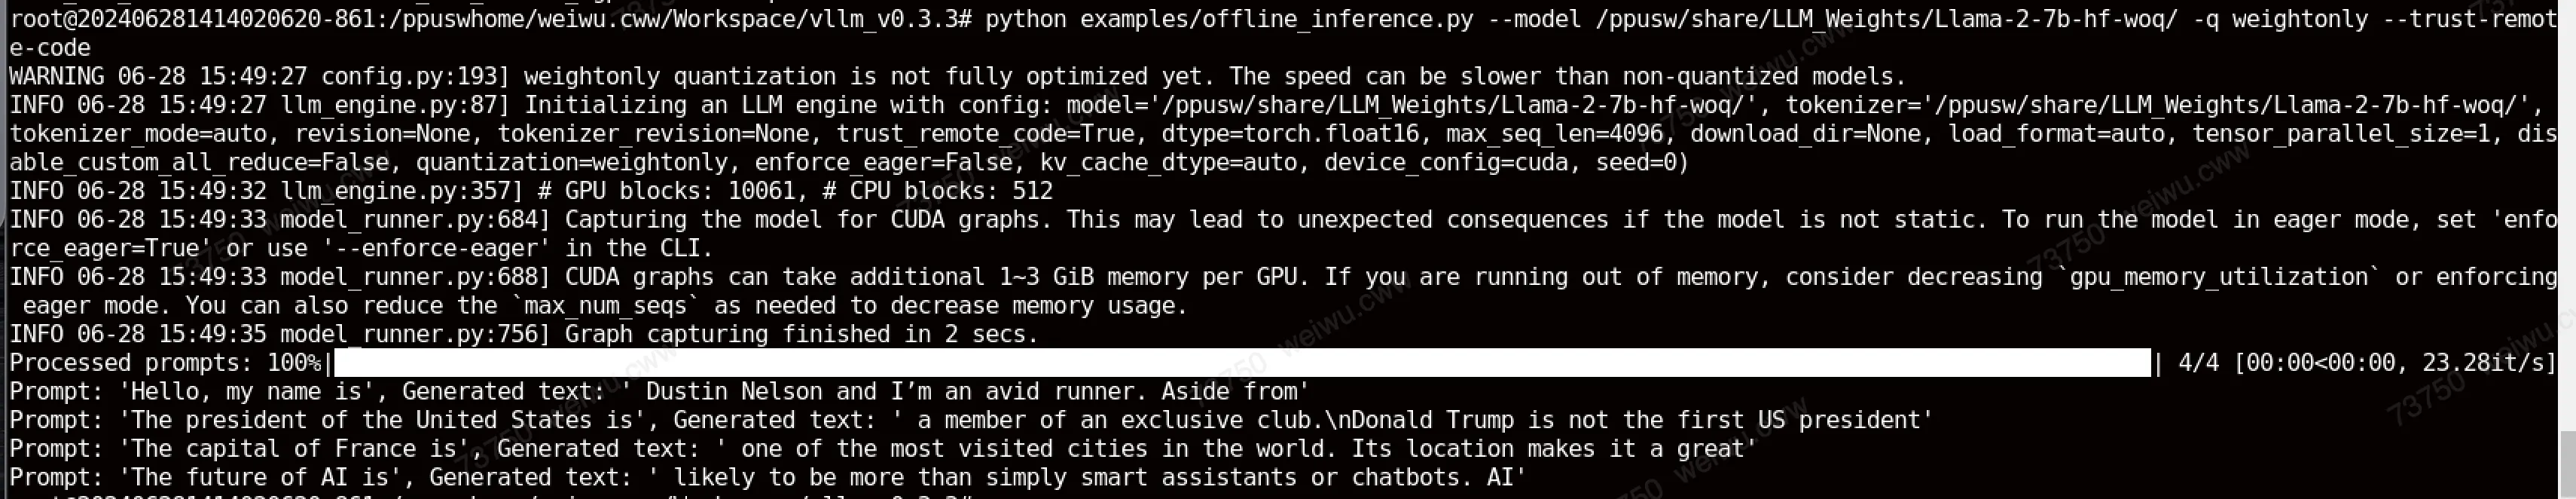
python examples/offline_inference.py --model /path/to/Llama-2-7b-hf-woq/ -q weightonly --trust-remote-code
Results:
2.2 AWQ/GPTQ Quantization Support (Optimized)
2.2.1 Optimizing AWQ/GPTQ Inference
AWQ and GPTQ are native vLLM quantization methods. Both use int4 quantization.
For more information, see AutoAWQ Quantization.
However, the native AWQ/GPTQ implementation in vLLM only reduces memory usage. Its performance is often worse than that of fp16.
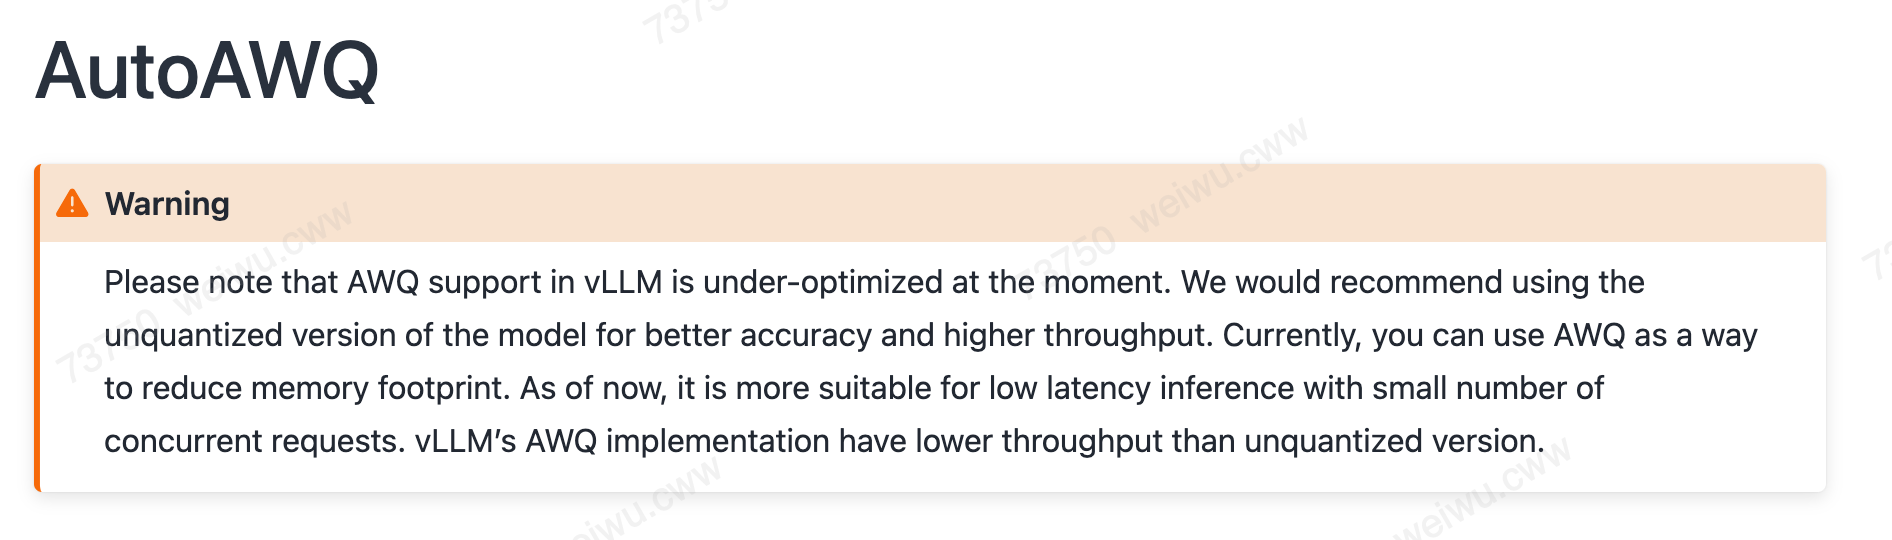
The mixed-precision quantization of acext on vLLM provides more efficient quantization kernels and improves performance compared to the original AWQ/GPTQ. However, because acext's mixed-precision quantization requires a specific weight arrangement, you must pre-process the original AWQ weights before calling acext.
By adding support for `acext weightonly_groupwise_gemm` to `vllm`, you can accelerate the quantized inference of AWQ. This method uses the original AWQ weights, which must be pre-processed before use. The specific flow is as follows:
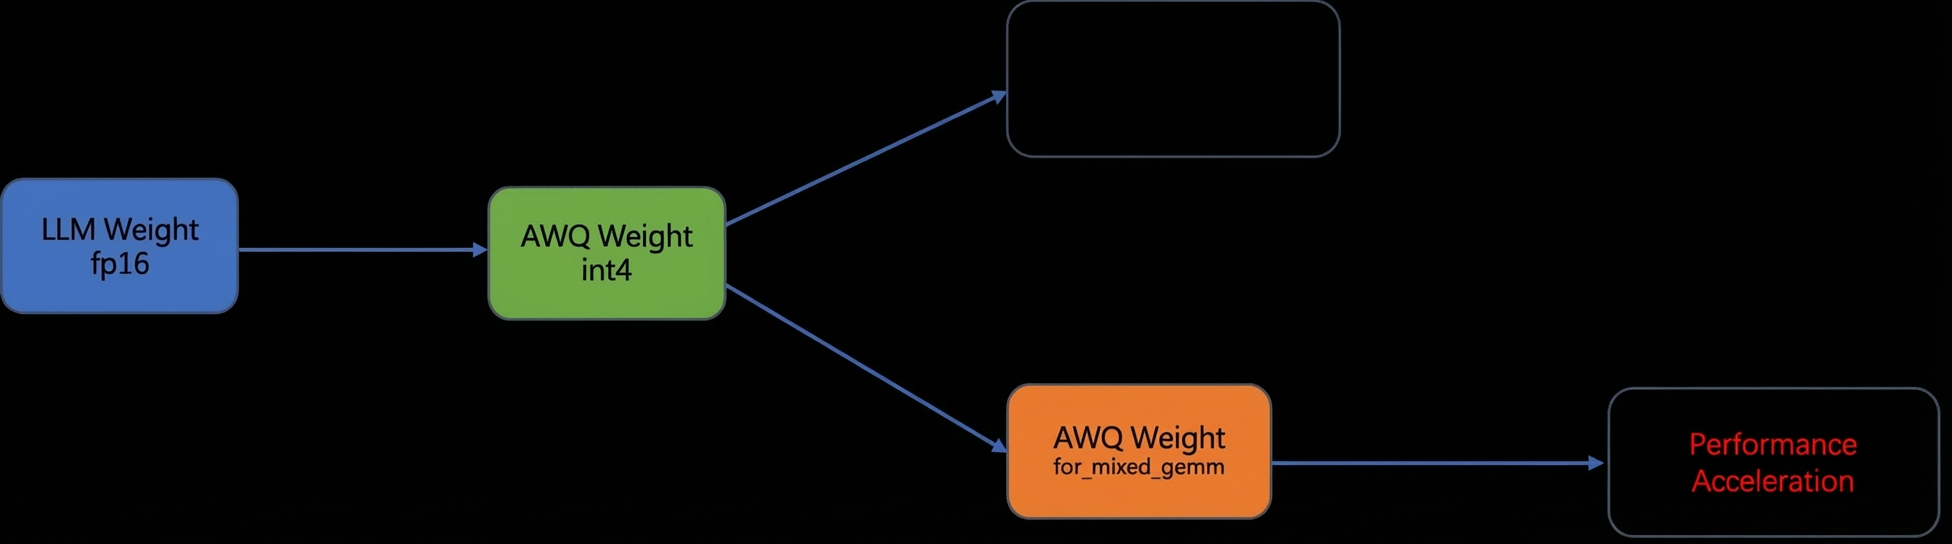
The same flow also applies to GPTQ quantization.
This also applies to GPTQ. Currently, weight processing occurs online at startup, which causes delays. Offline preprocessing will be added in a future release.
2.2.2 Fast AWQ/GPTQ Inference
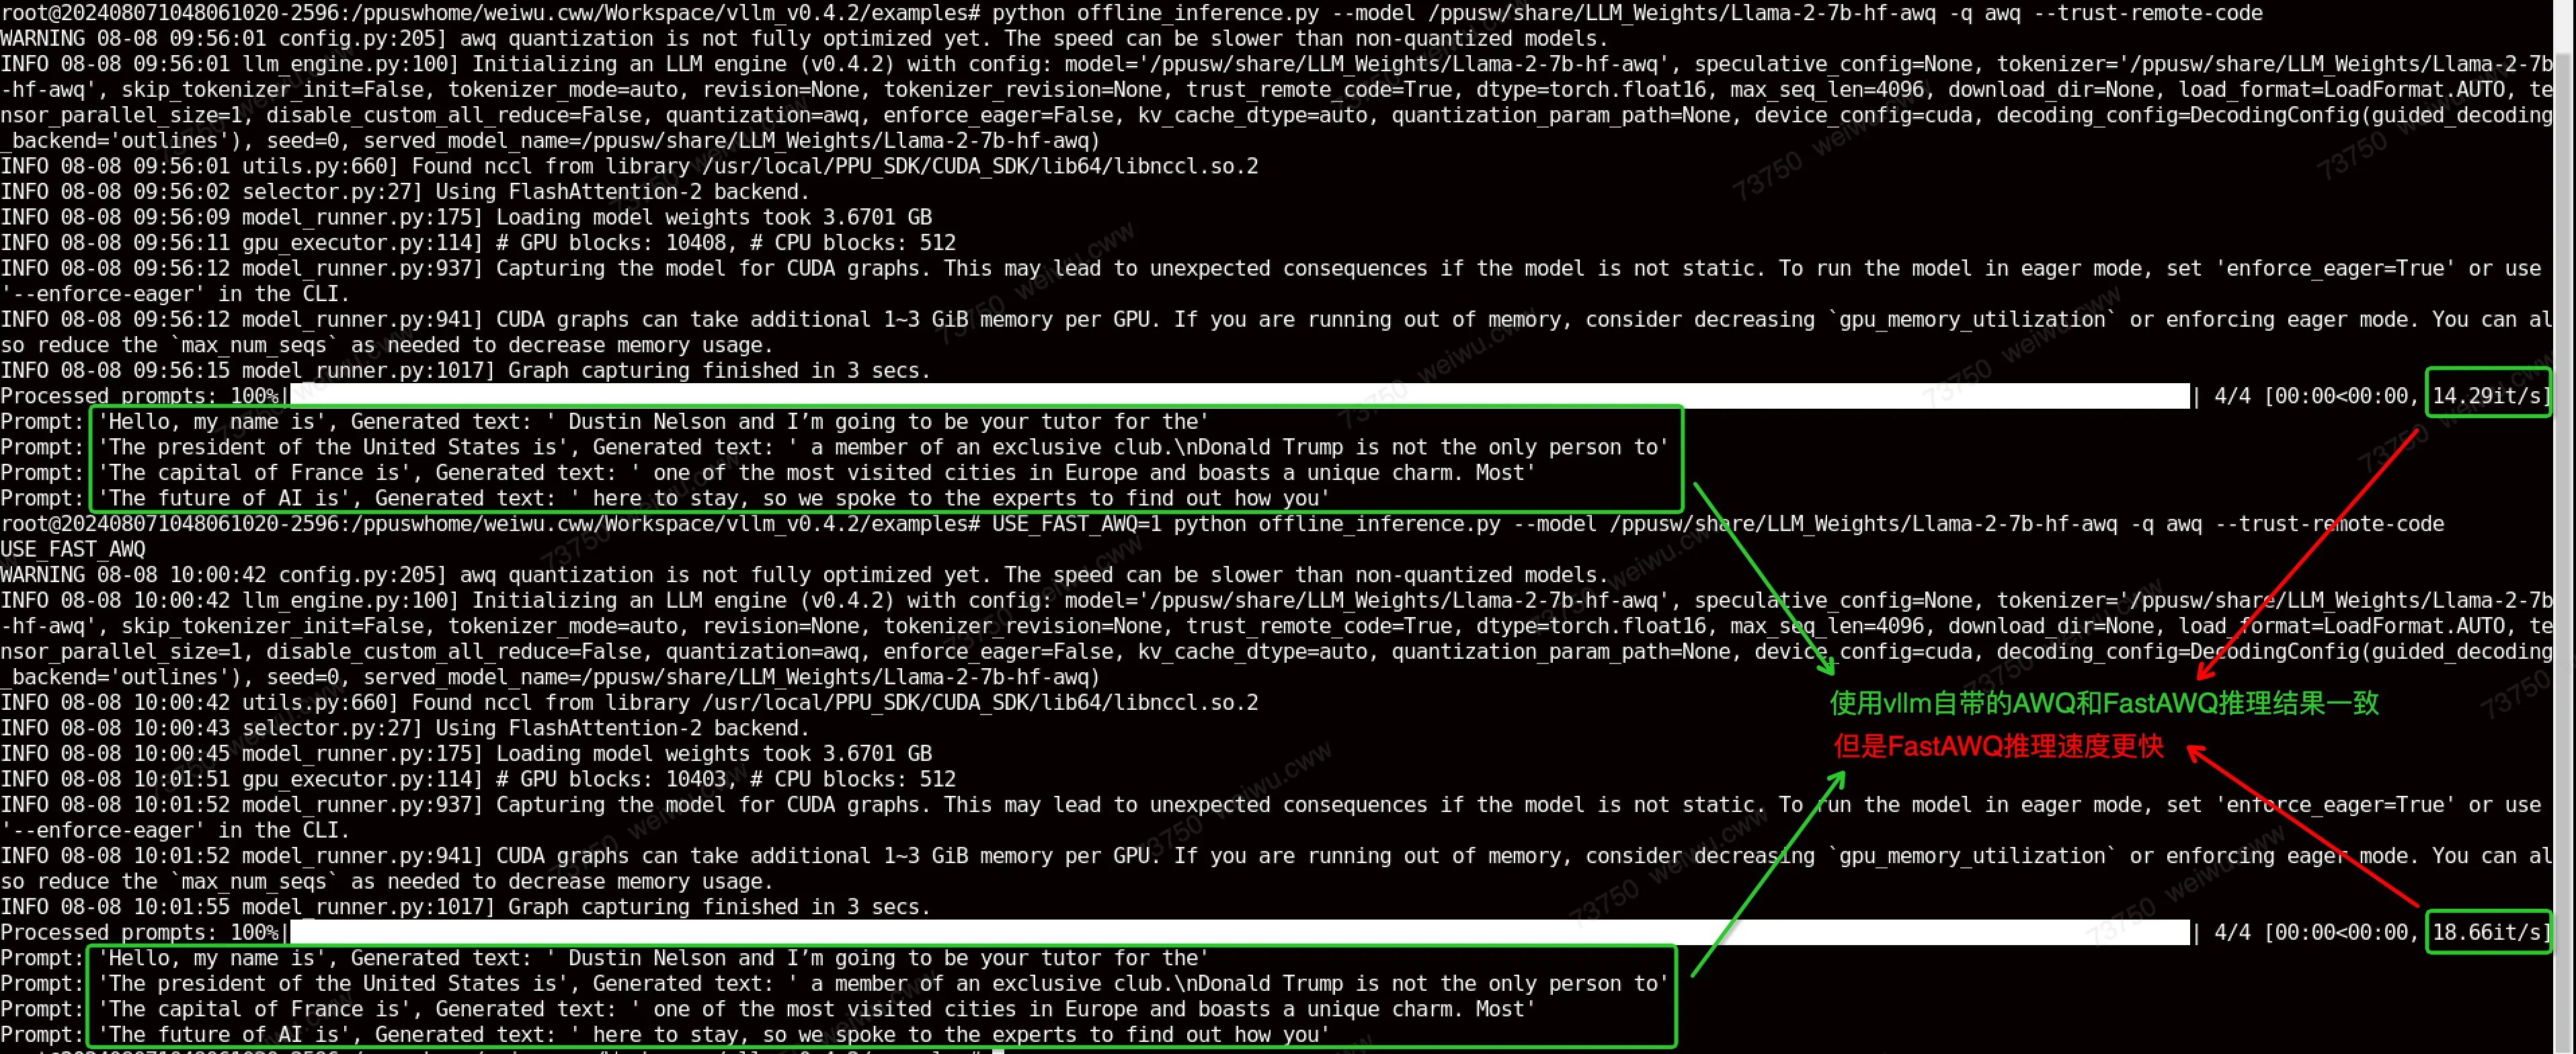
Because this optimization is still under active development, vLLM does not enable acext acceleration for AWQ/GPTQ by default. To activate it, you must set the `USE_FAST_AWQ=1` or `USE_FAST_GPTQ=1` environment variable. If you do not set these variables, vLLM uses its native quantization.
You can use the following command line to invoke the FastAWQ flow, which accelerates AWQ quantization using acext.
USE_FAST_AWQ=1 python offline_inference.py --model /ppusw/share/LLM_Weights/Llama-2-7b-hf-awq -q awq --trust-remote-codeFastAWQ produces identical outputs to AWQ but runs faster.
2.3 acext Support for fused_moe
We added acext backend support to vLLM 0.8.3 and 0.8.5 for bf16 and w8a8-int8-channel modes. For a code reference, see the following:
https://code.alibaba-inc.com/ppu_open_source/vllm/tree/v0.8.5_ppu_1v5.1_releaseThis includes the following three changes:
2.3.1 Building the acext Backend
In acext_moe_func.cu, we added the acext backend using the `AcextFusedMoe` class to call acext APIs. We then register these APIs as Python functions using csrc/moe/moe_ops.h and csrc/torch_bindings.cpp.
API | Features |
acext_fusedmoe_warpper | Call acext backend to execute fusedmoe |
get_acext_fusedmoe_status_wrapper | Check if the current model config supports acext backend. Returns 0 if supported. |
acext_get_version | Return acext library version (int). Current version is 1050100. |
2.3.2 Modifying the fused MoE Layer
In fused_moe.py, we added acext calls inside `fused_experts_impl`. First, you can check for support using ops.get_acext_fusedmoe_status(). If it is unsupported, the system falls back to Triton. If acext_fusedmoe_status = 0, you can call acext using ops.acext_fusedmoe_warpper().
2.3.3 Adding W8A8Int8MoEMethod (for w8a8-int8-channel)
In compressed_tensors_moe.py, we added `CompressedTensorsW8A8Int8MoEMethod` to load w8a8-int8-channel weights and run the MoE layer.
2.4 Supported Large Language Models
Model | WeightOnly | AWQ | GPTQ | N_K Shape |
Llama-2-7b-hf | Y | Y | Y | 12288 4096 4096 11008 22016 4096 4096 4096 |
Llama-2-13b-hf | Y | Y | Y | 5120 5120 27648 5120 5120 13824 15360 5120 |
Llama-2-70b-hf (8GPUS) | Y | Y | Y | 8192 3584 8192 1024 1280 8192 7168 8192 |
Meta-Llama-3-8B | Y | Y | Y | 6144 4096 4096 14336 28672 4096 4096 4096 |
Meta-Llama-3-70B (8GPUS) | N | Y | N | 8192 3584 8192 1024 1280 8192 7168 8192 |
Baichuan-7b | Y | Y | Y | 12288 4096 4096 11008 22016 4096 4096 4096 |
Baichuan-13b | Y | Y | Y | 5120 5120 5120 13696 27392 5120 15360 5120 |
Baichuan2-7b | Y | Y | Y | 12288 4096 4096 11008 22016 4096 4096 4096 |
Baichuan2-13b | Y | Y | Y | 5120 5120 5120 13696 27392 5120 15360 5120 |
Chatglm2-6b | Y | N | N | 4608 4096 4096 13696 27392 4096 4096 4096 |
Chatglm3-6b | Y | N | N | 4608 4096 4096 13696 27392 4096 4096 4096 |
Qwen-7b | Y | Y | Y | 12288 4096 4096 11008 22016 4096 4096 4096 |
Qwen-14b | Y | Y | Y | 5120 5120 5120 13696 27392 5120 15360 5120 |
Qwen-72b (8GPUS) | Y | Y | Y | 6144 8192 8192 1024 8192 3072 3072 8192 |
Falcon-7b | Y | N | N | 4544 4544 4672 4544 18176 4544 4544 18176 |
Falcon-40b (8GPUS) | Y | N | Y | 8192 4096 8192 1024 1152 8192 4096 8192 |
Gemma-7b | Y | N | N | 49152 3072 12288 3072 3072 24576 3072 4096 |
Mistral-7b | Y | Y | Y | 6144 4096 4096 14336 28672 4096 4096 4096 |
Mpt-7B | Y | N | Y | 12288 4096 4096 16384 4096 4096 16384 4096 |
Mixtral-8x7b (8GPUS) | Y | Y | N | 4096 512 8 4096 768 4096 |
Mixtral-8x22b (8GPUS) | Y | Y | N | 8 6144 1024 6144 6144 768 |
2.4.1 Known Issues
2.4.1.1 Weight Conversion Issues
WOQ model conversion issues:
model | Comments |
Chatglm2-6b | When AutoWOQ quantizes ChatGLM weights, the generated tokenizer_config.json must be replaced with the original model’s tokenizer_config.json to avoid compatibility issues. This is a known community issue. Manually replace it after conversion. |
Chatglm3-6b |
AWQ model conversion issues:
model | Comments |
Chatglm2-6b | TypeError: chatglm isn't supported yet. |
Chatglm3-6b | TypeError: chatglm isn't supported yet. |
Falcon-7b | TypeError: FalconDecoderLayer.forward() missing 1 required positional argument: 'alibi' |
Falcon-40b | TypeError: FalconDecoderLayer.forward() missing 1 required positional argument: 'alibi' |
Mpt-7B | AttributeError: 'NoneType' object has no attribute 'bool' |
GPTQ model conversion issues:
model | Comments |
Chatglm2-6b | TypeError: chatglm isn't supported yet. |
Chatglm3-6b | TypeError: chatglm isn't supported yet. |
Falcon-7b | AssertionError assert infeatures % self.group_size == 0 |
Meta-Llama-3-70B | torch._C._LinAlgError: linalg.cholesky: The factorization could not be completed because the input is not positive-definite (the leading minor of order 27024 is not positive-definite). |
Mixtral-8x7b | ZeroDivisionError: float division by zero |
Mixtral-8x22b | ZeroDivisionError: float division by zero |
2.4.1.2 Runtime Issues
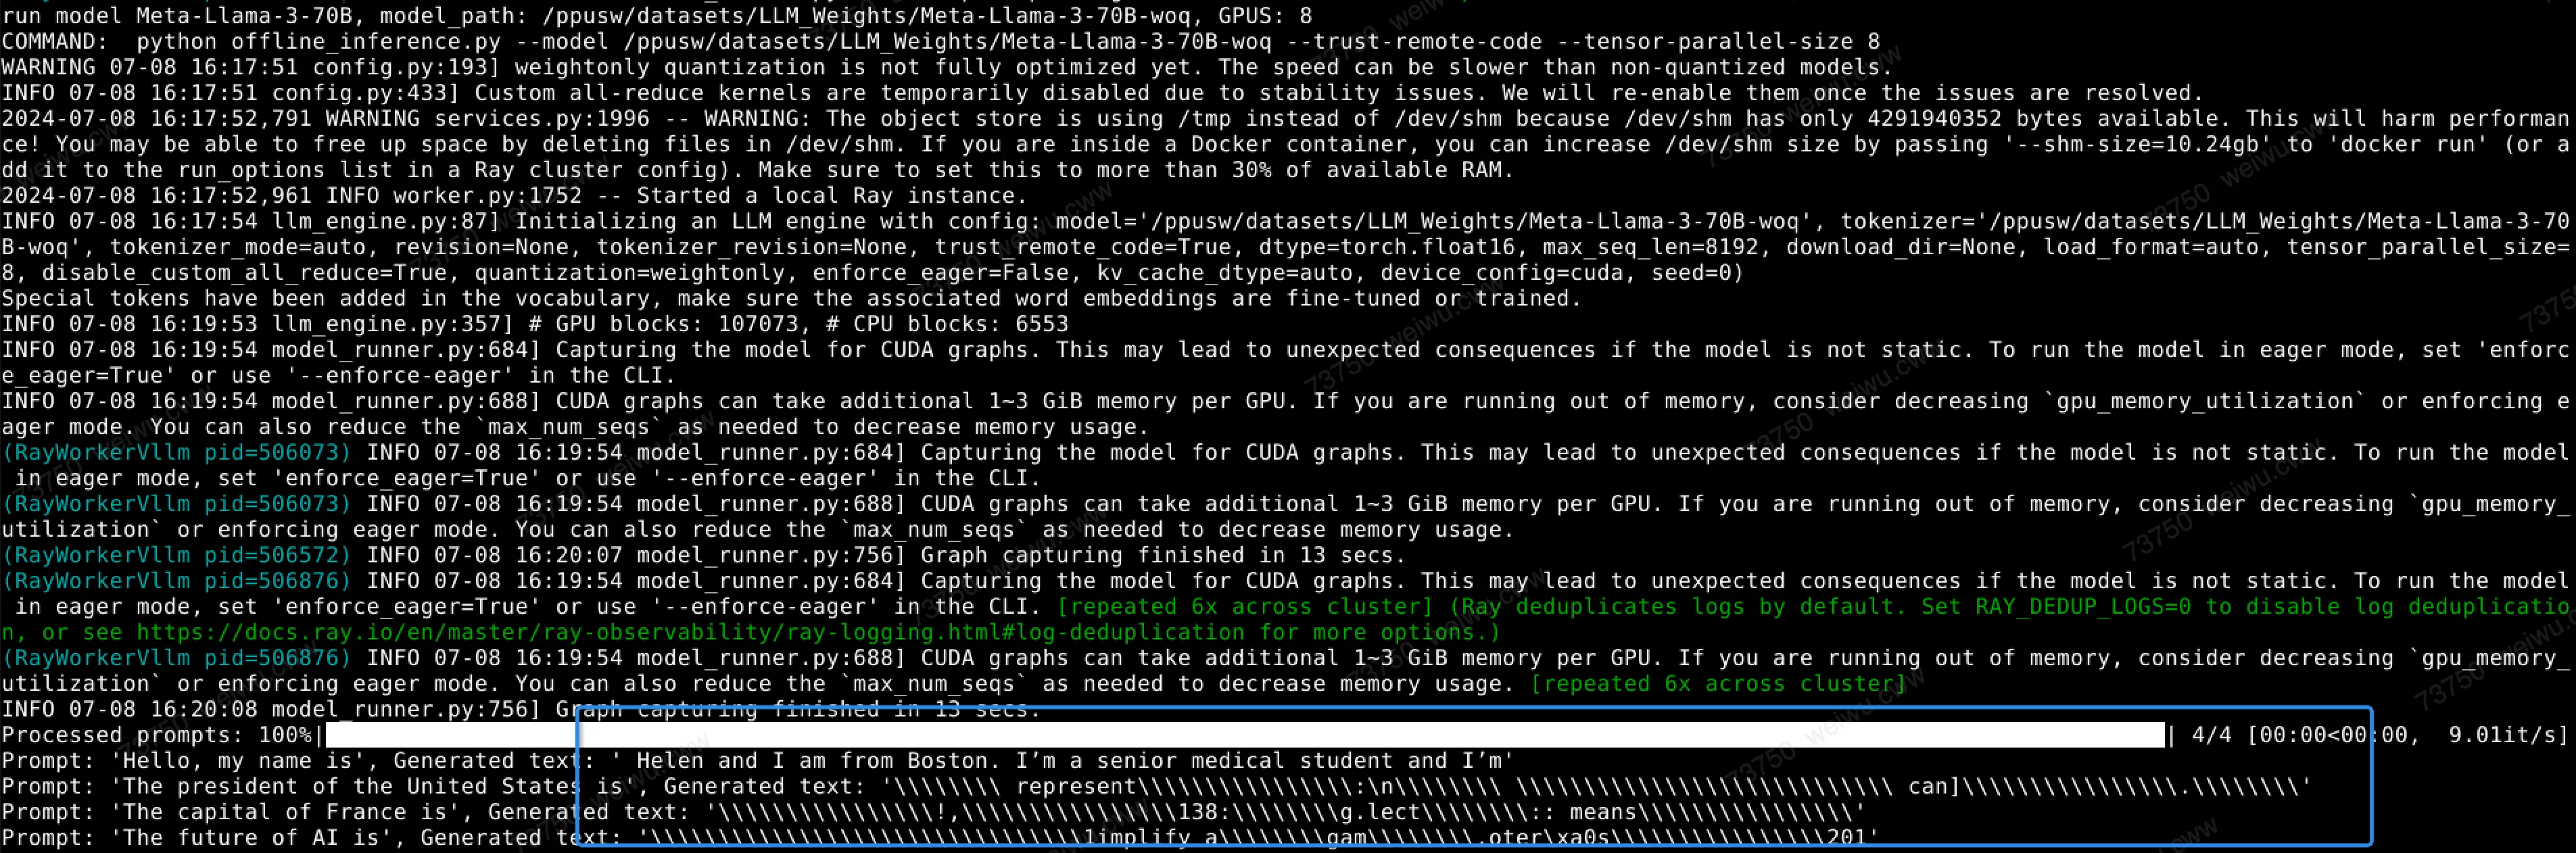
Running Meta-Llama-3-70B-woq results in unexpected behavior.
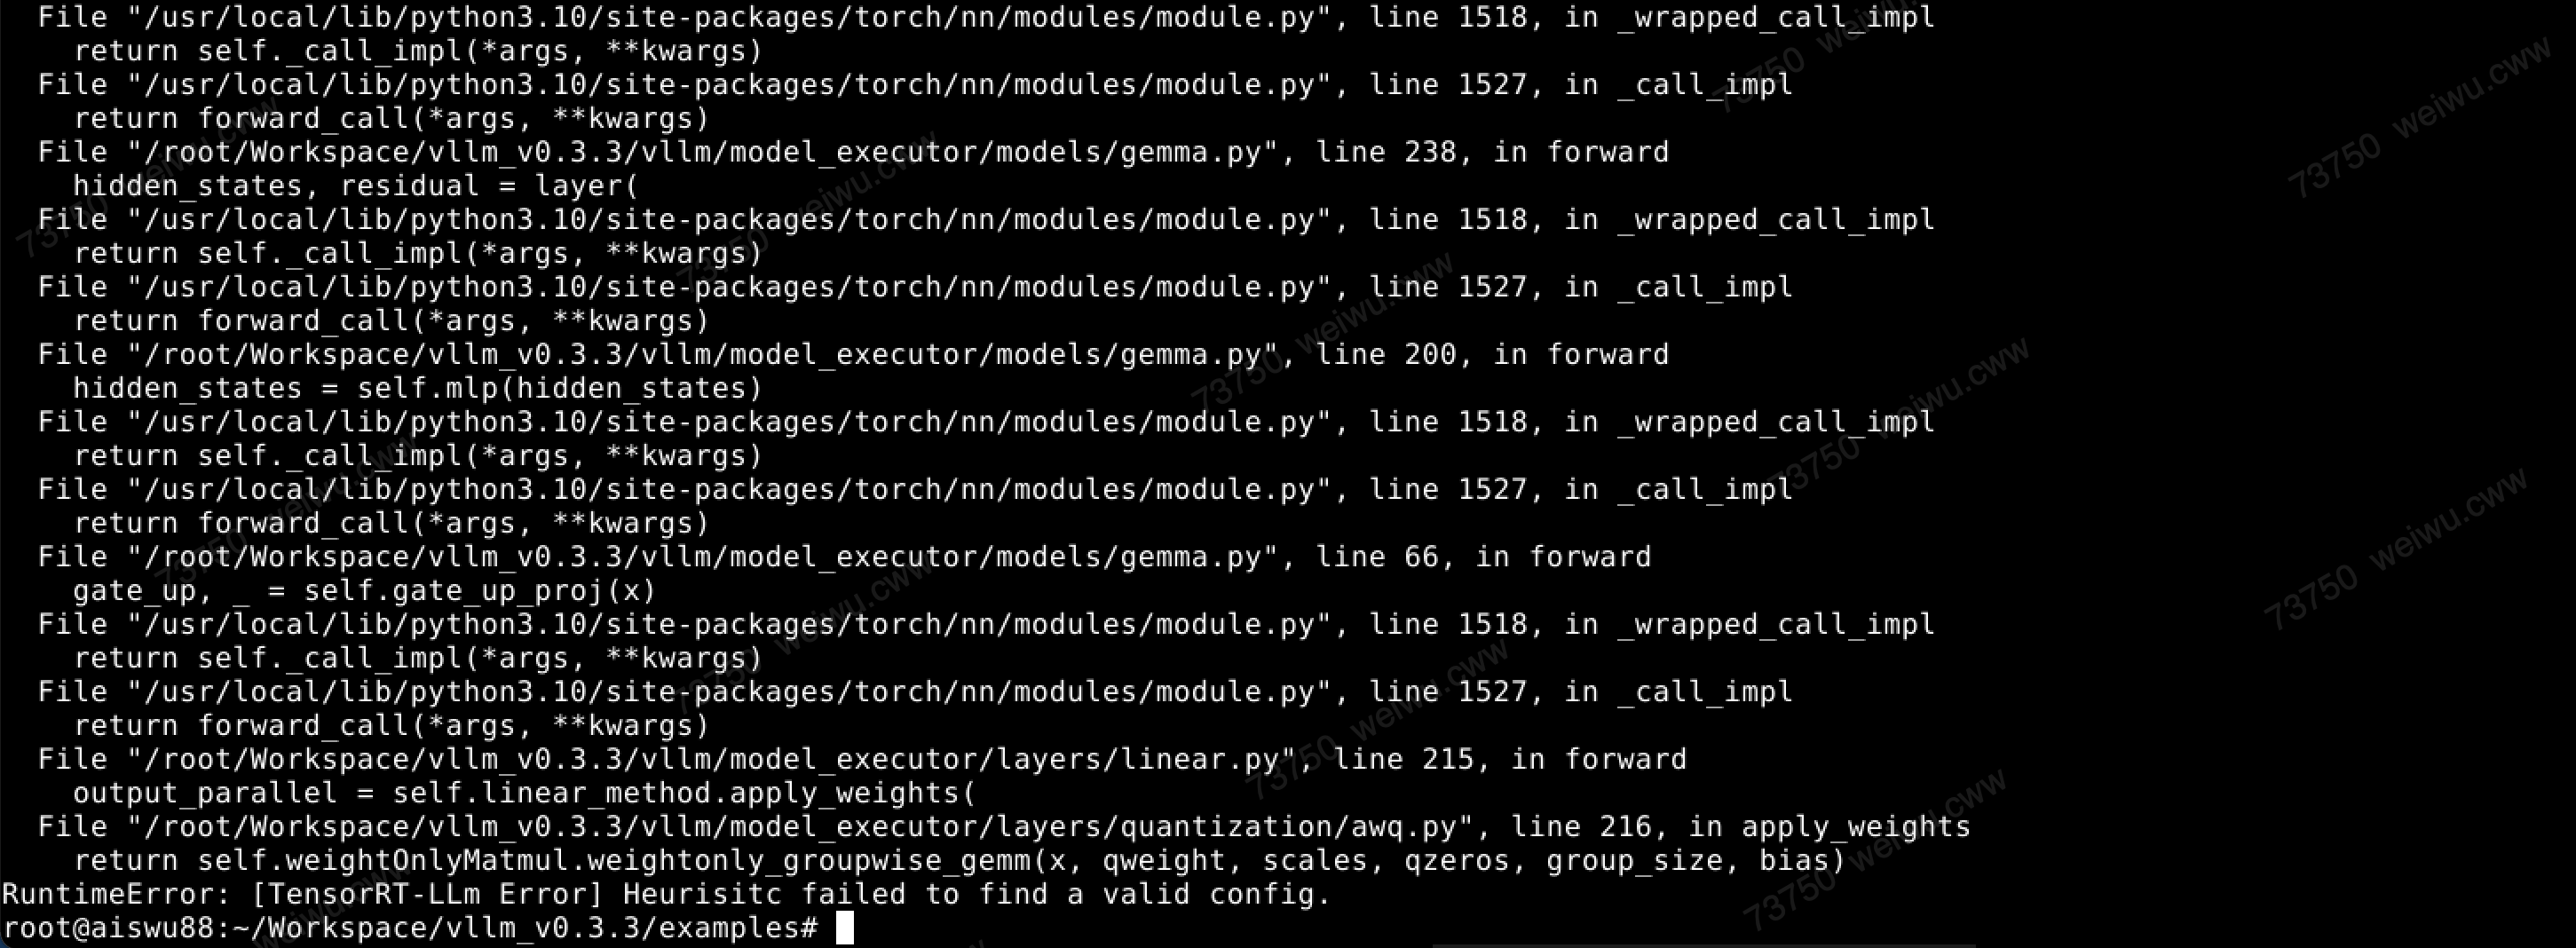
Running Gemma-7b-awq fails.
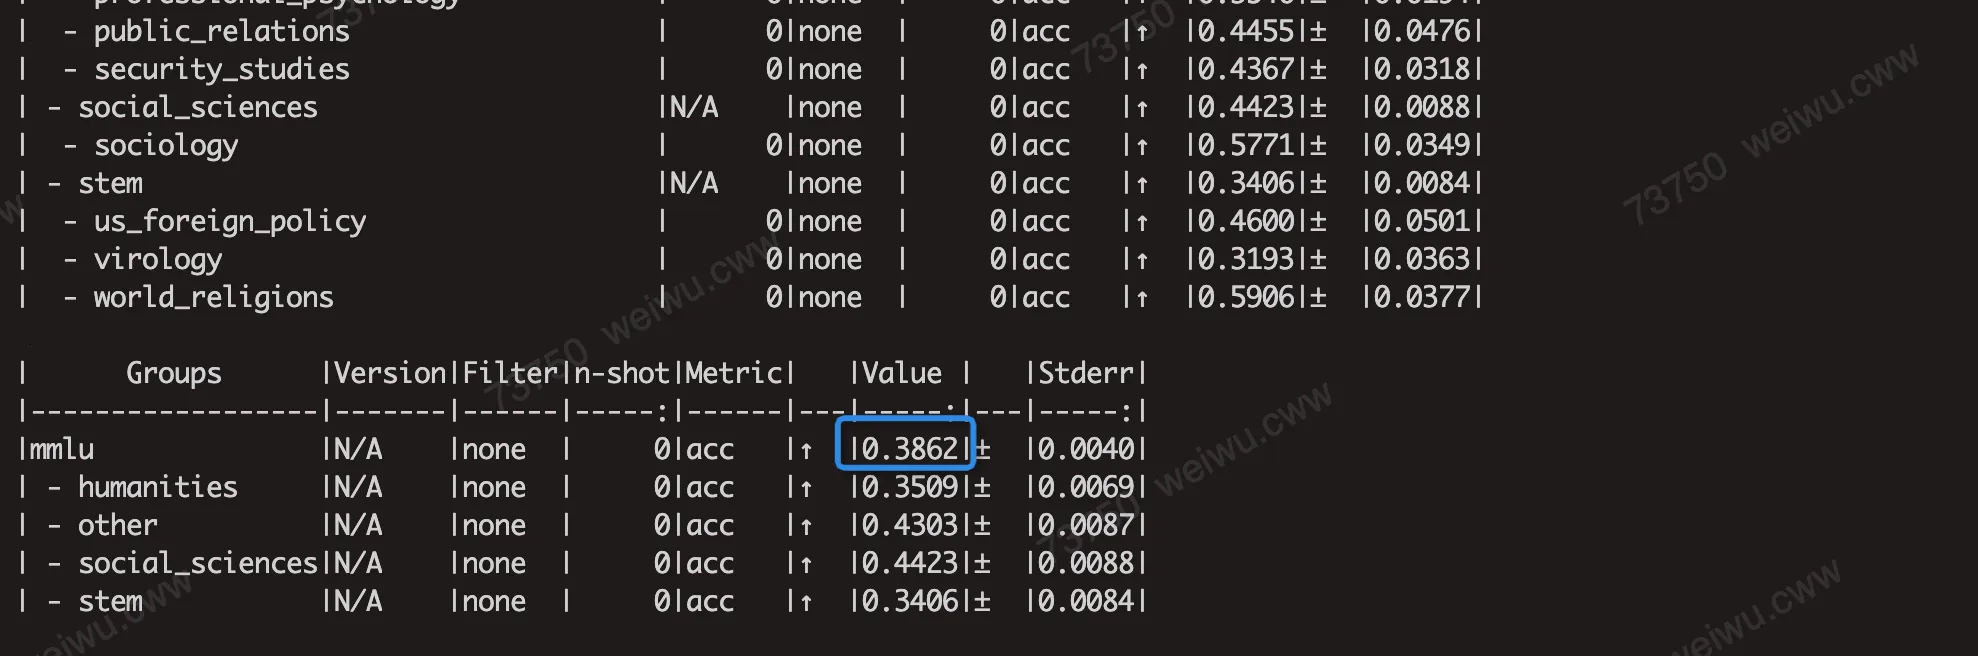
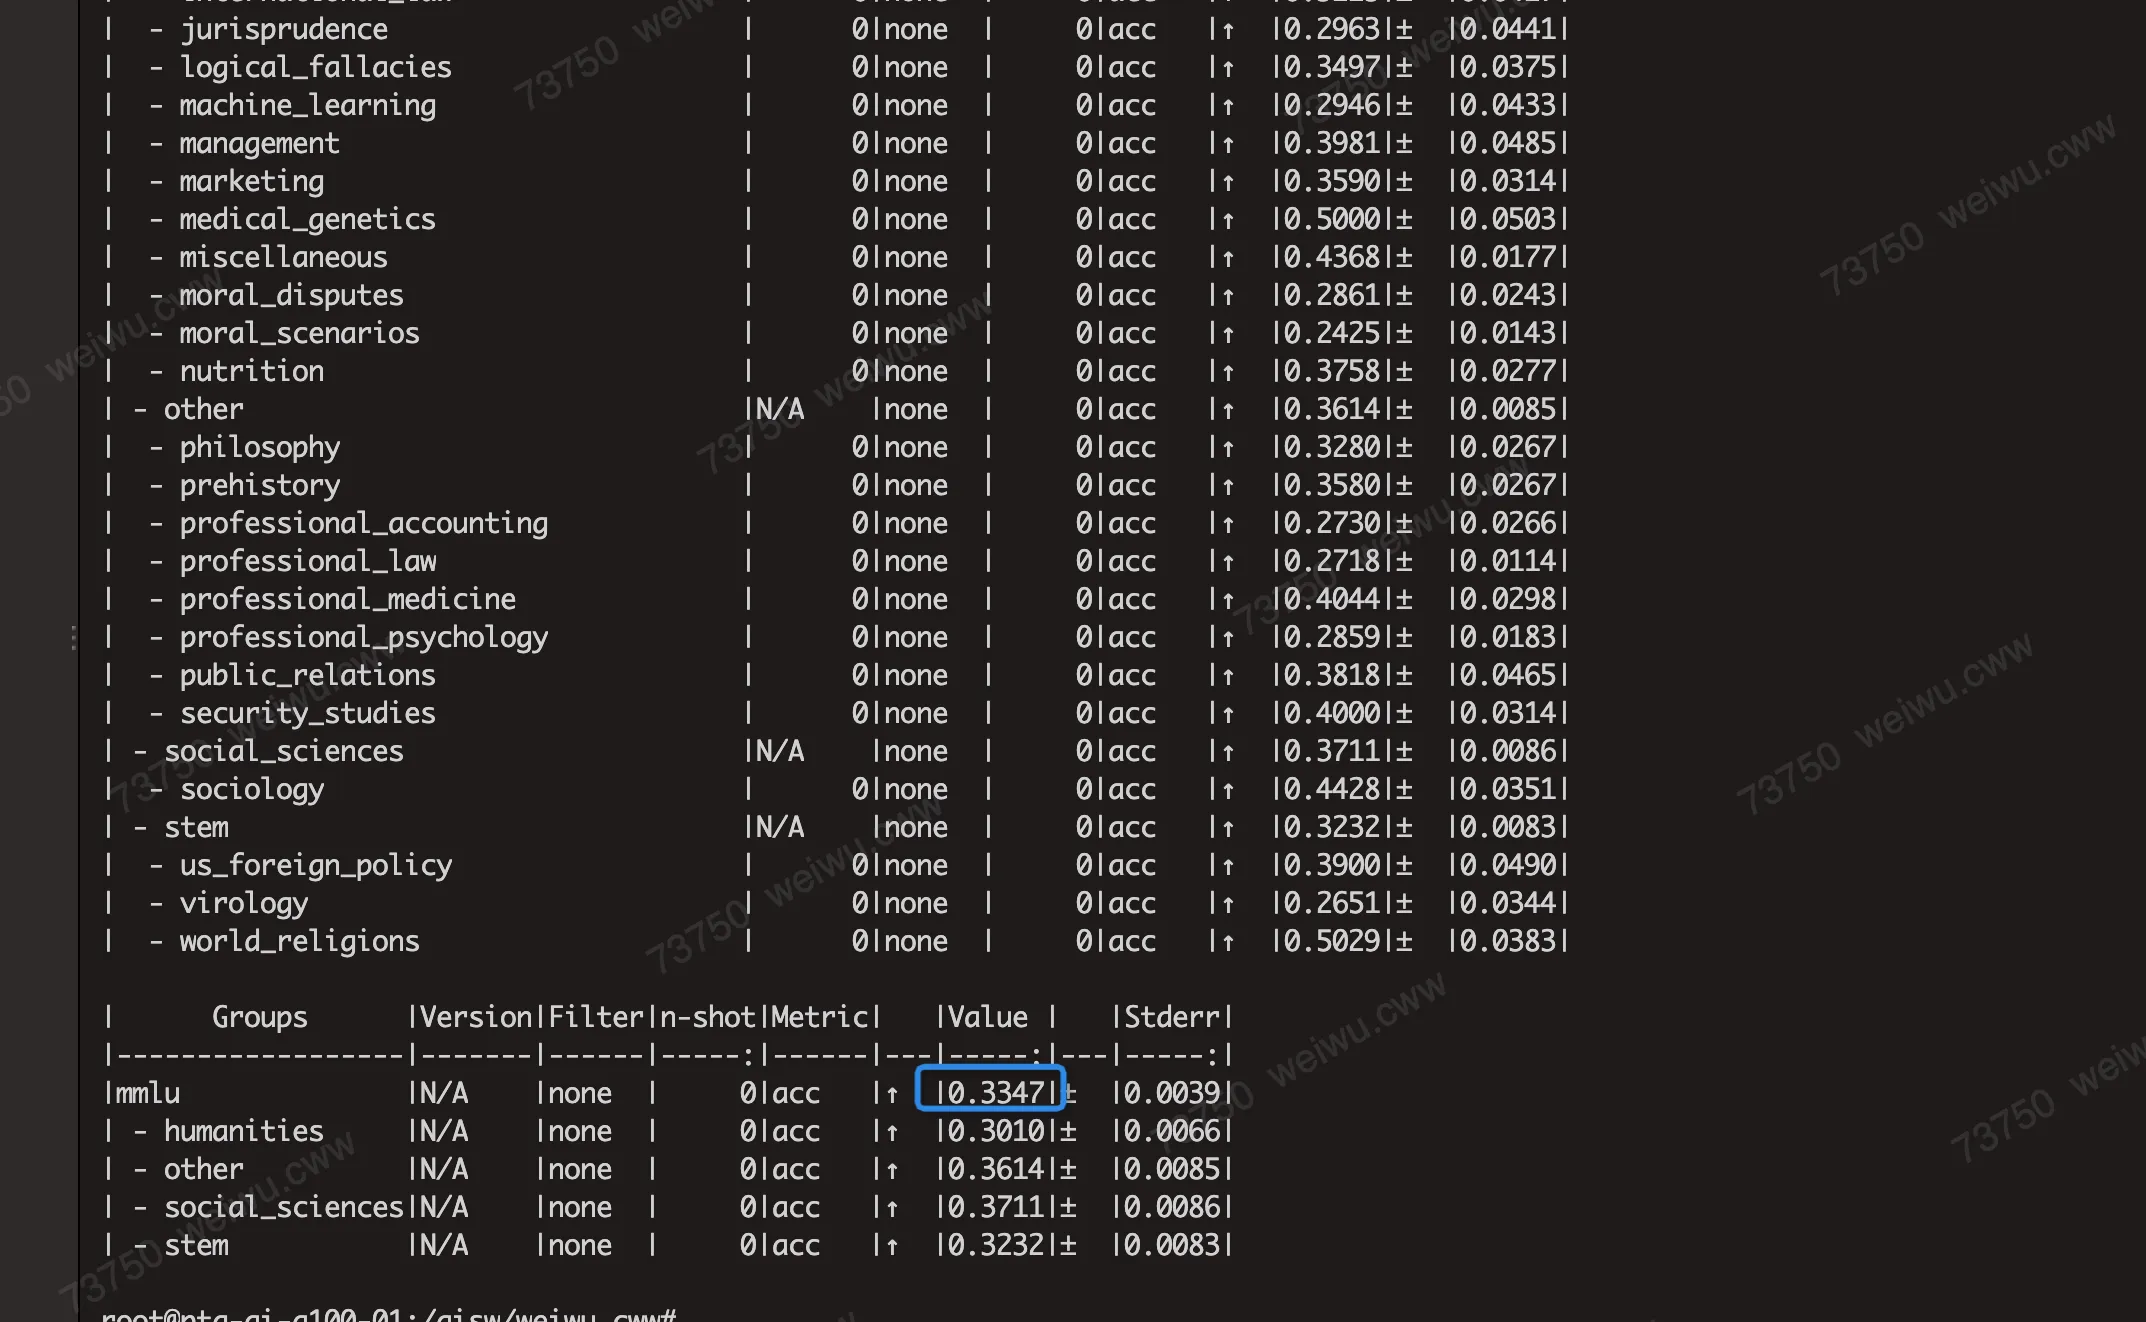
Some models show a large accuracy loss on MMLU with AWQ/GPTQ quantization. For example, LLaMA2-7B shows a large loss:
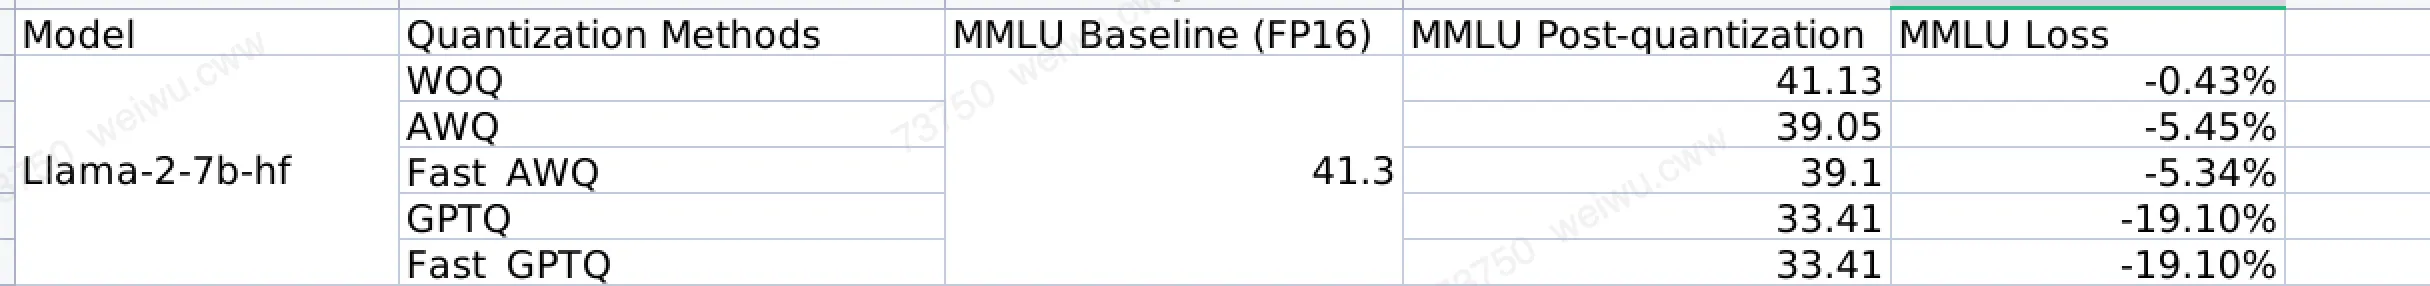
Validation on an A100 confirms that this issue stems from the poor performance of the AWQ and GPTQ quantization algorithms on these models, as evidenced by the precise MMLU scores measured on the A100. For example, the MMLU scores from running Llama-2-7b with AWQ and GPTQ on an A100 are consistent with the PPU scores.
2.5 Model Quantization Performance
There are various methods and metrics for measuring the inference performance of large language models (LLMs).
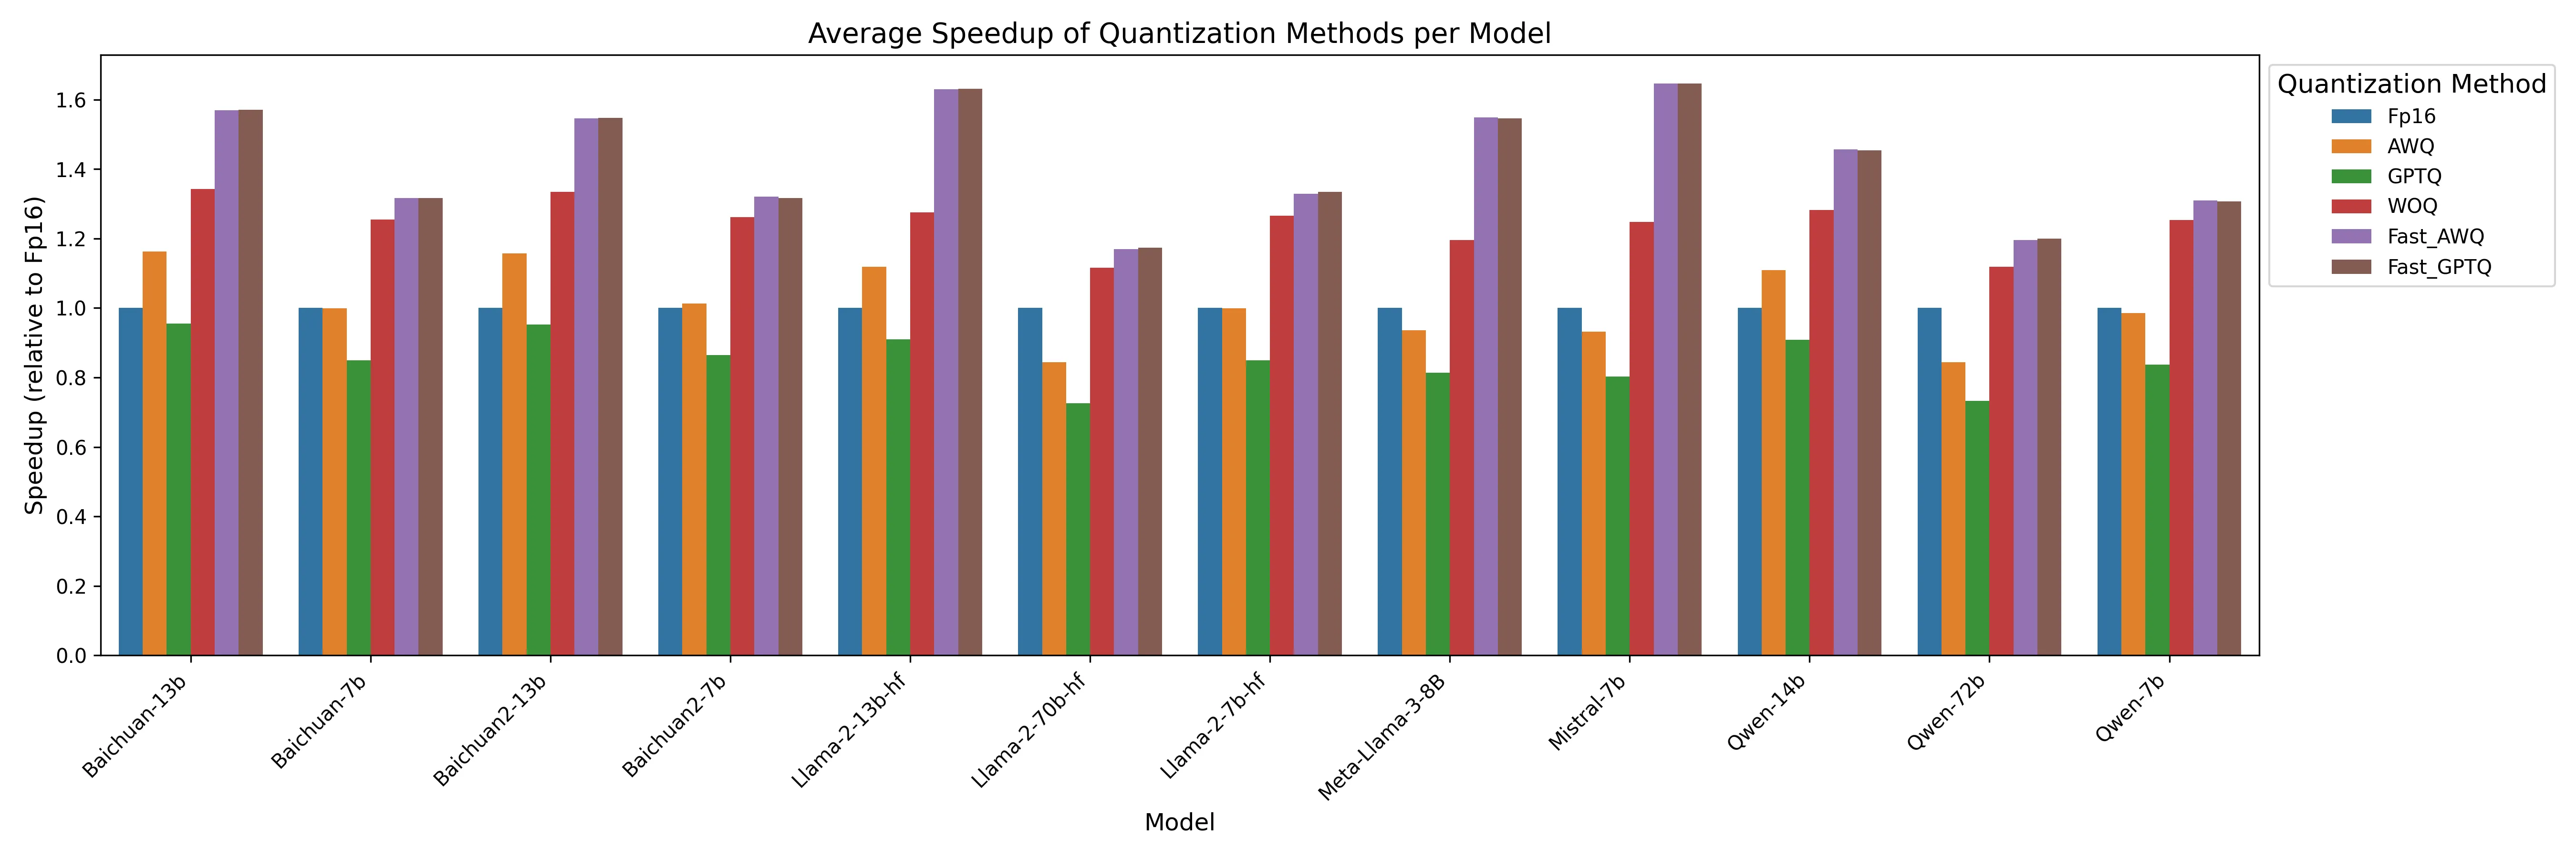
We measure the generation throughput during inference with a fixed output length of 128 tokens and varying batch sizes (1, 2, 4, and 8), input lengths (32, 512, 1024, and 2048), and an output length of 128. This reflects real-world benefits, such as reduced latency in online inference.
The following table shows the throughput speedups relative to fp16 for each quantization method.
2.5.1 Detailed Performance Data
2.6 Model Quantization Accuracy (MMLU)
We use the lm-evaluation-harness framework to run large model inference and test MMLU scores to evaluate post-quantization accuracy.
https://github.com/EleutherAI/lm-evaluation-harness
2.6.1 Steps
# If setuptools is too old, upgrade it first
# pip3 install --upgrade pip setuptools
# For the following reason, we need to pin setuptools to 69.5.1
# https://github.com/vllm-project/vllm/issues/4961

git clone https://github.com/EleutherAI/lm-evaluation-harness
# If you encounter issues with the MMLU test, it might be version-related. Try checking out this commit:
# git reset --hard e5e5ee0cb629c9c88165292d1b4bf34623392d33
cd lm-evaluation-harness
pip install -e .

# Use Hugging Face mirror
export HF_ENDPOINT=https://hf-mirror.com

# Run MMLU inference with lm_eval
lm_eval --model vllm --model_args pretrained=/ppusw/datasets/huggingface/Llama-2-7b-hf --tasks mmlu --batch_size auto --num_fewshot 5

# If you still have trouble downloading datasets after setting the proxy, it's because this file hardcodes the Hugging Face URL:
# /root/.cache/huggingface/modules/datasets_modules/datasets/hails--mmlu_no_train/b7d5f7f21003c21be079f11495ee011332b980bd1cd7e70cc740e8c079e5bda2/mmlu_no_train.py
# Modify the URL in this file to point to hf-mirror.
2.6.2 Inference Results
You can set `num-fewshot` to control the few-shot parameters. Higher values run slower but may yield better scores.
Without `num_fewshot`, the test runs quickly, in minutes, and scores 41.3.
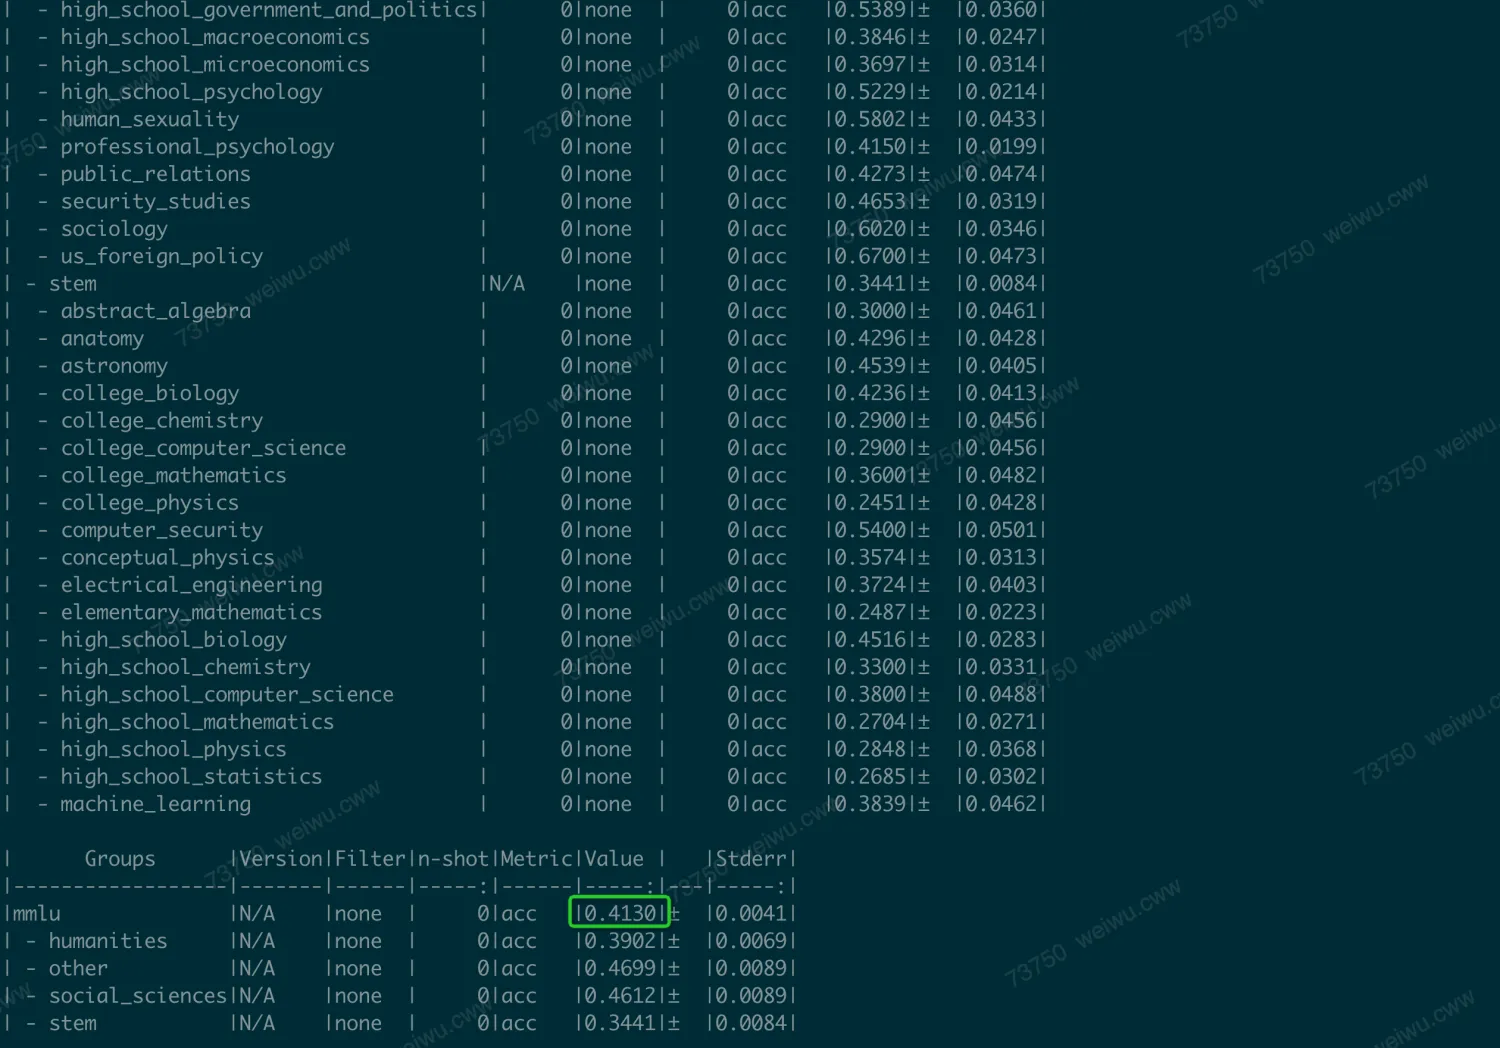
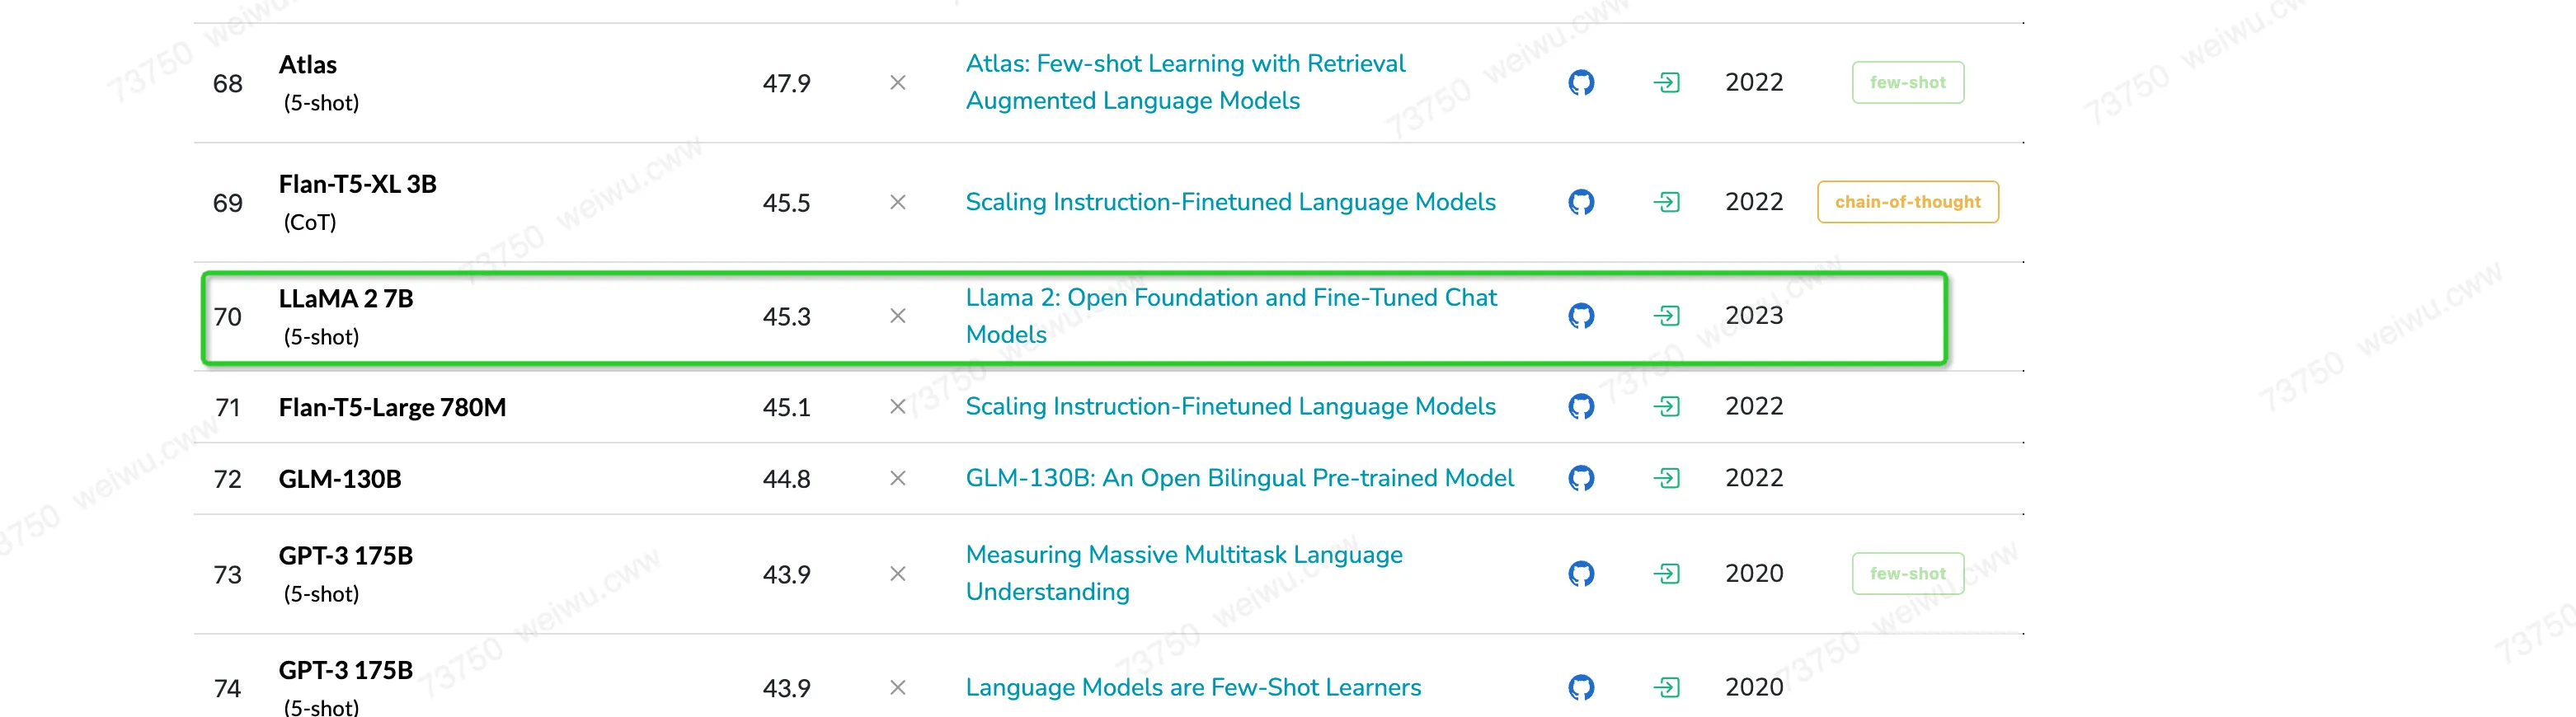
With `num_fewshot=5`, it runs slower, in hours, but scores higher at 45.9.
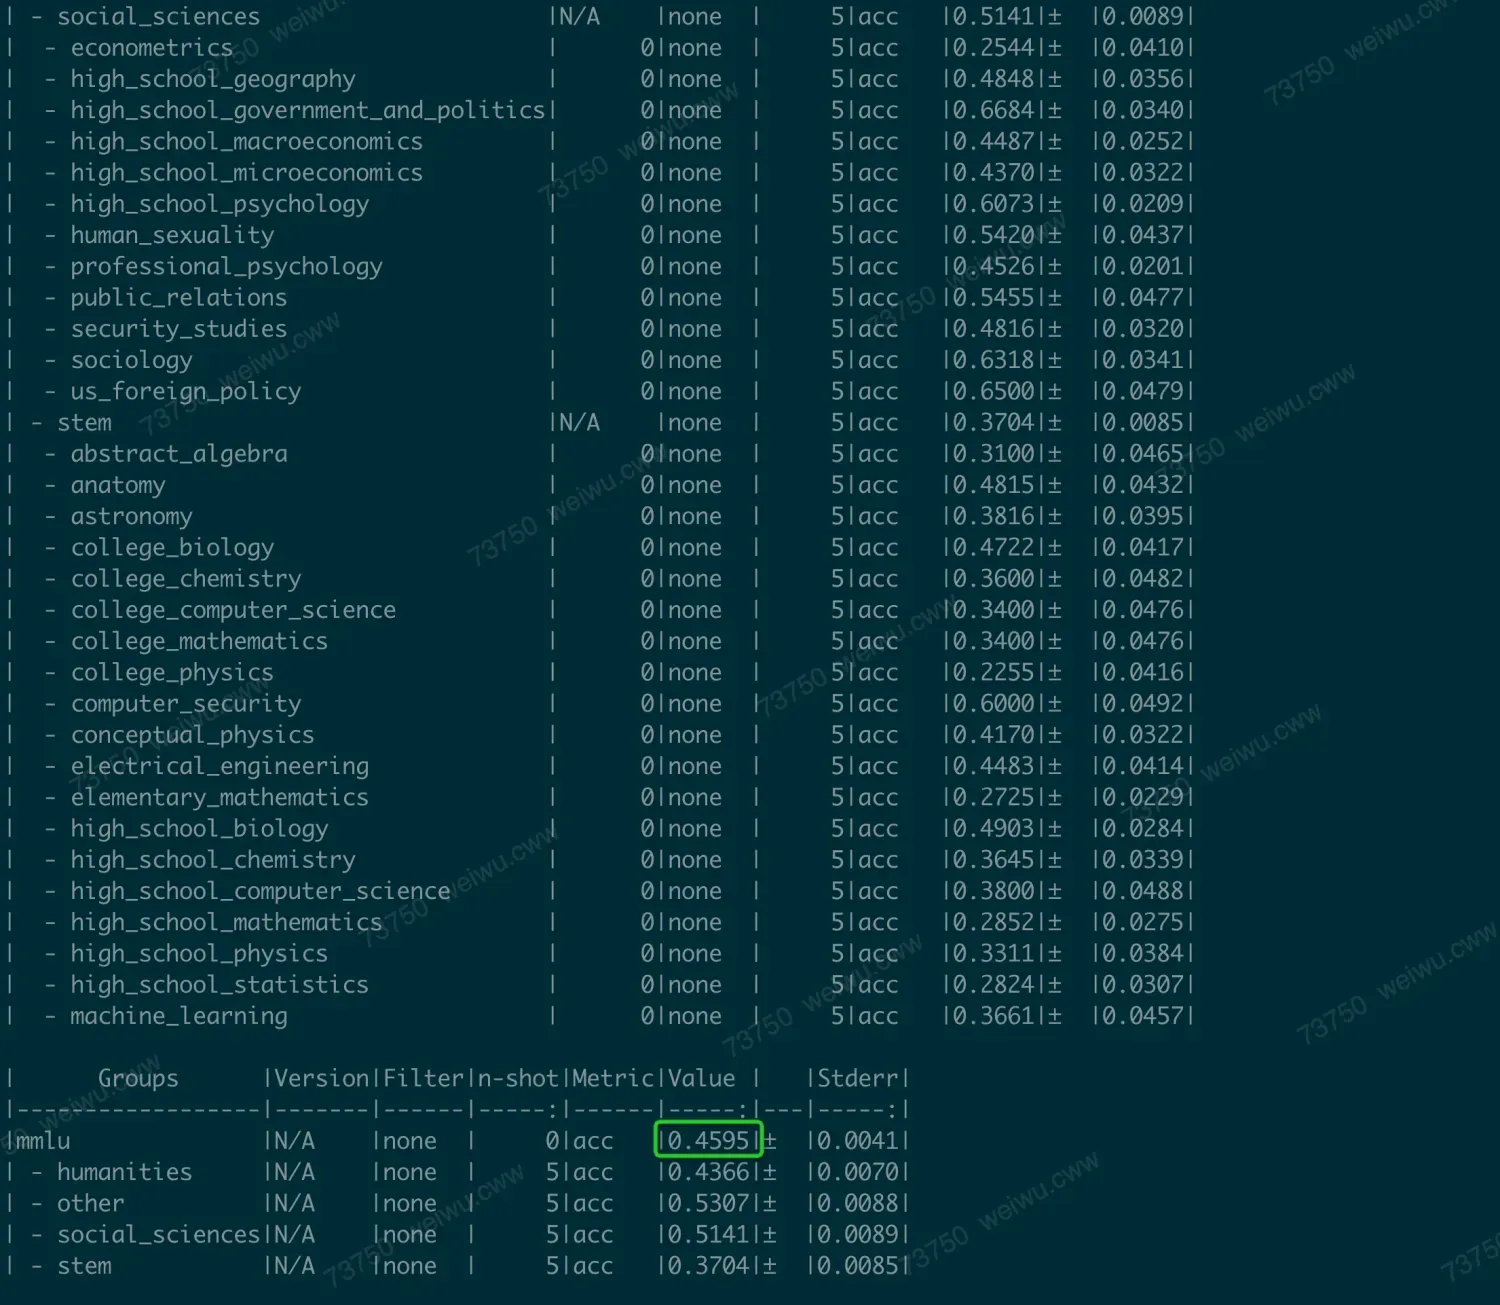
This matches the results on the website.
2.6.3 MMLU Accuracy for Different Quantization Methods
We use the MMLU score of the unquantized fp16 model as a baseline. By running inference with different quantization methods, we can measure the post-quantization MMLU score and calculate the accuracy loss.
The following table shows the MMLU scores (few-shot 0) and accuracy loss relative to fp16 for various models and quantization methods.
Gray indicates methods that are not supported in the current version (PPU Release 1.3). Red indicates methods that have inference bugs.
3. Build and Run from Source
3.1 Build
acext depends on the PPU version of CUTLASS. You must first download acext, and then download the PPU version of CUTLASS.
# Fetch code from ppu_open_source
git clone -b sail_v1.6.1 https://code.alibaba-inc.com/ppu_open_source/acext
cd acext
git clone -b sail_v1.6.1 https://code.alibaba-inc.com/ppu_open_source/cutlass
You can use one of the following two methods to build and install acext.
Build and install acext separately.
# Compile & install: in acext
rm -rf build && mkdir build && cd build
cmake .. -DCMAKE_BUILD_TYPE=Release -DBUILD_PYT=ON
cmake --build . -- -j${nproc}
cmake --build . --target install -j${nproc}
Build and install the acext wheel package.
python -m build --wheel --no-isolation -v
pip install dist/*.whl
If you choose the wheel package installation and need to build vLLM/sgl_kernel, you must run the following commands to copy the acext dynamic library and header files to the PPU_SDK directory. This ensures that the vLLM/SGLang cmake can find them:
cp $(python -c "import sysconfig; print(sysconfig.get_path('purelib'))")/lib/libacext.so $PPU_SDK/lib/
cp -r $(python -c "import sysconfig; print(sysconfig.get_path('purelib'))")/include/acext $PPU_SDK/include/
3.2 Run
3.2.1 Run Unit Tests
cd build

# Unit tests for a16w8/a16w4 quant gemm
python ../tests/test_woq_gemm.py

# Unit tests for a8w8 quant gemm
python ../tests/th_int8_gemm.py

# Unit tests for MoE
python ../tests/th_moe.py
3.2.2 Run Performance Tests
cd build
# Run FpAintB benchmark separately. Default mnk is (1, 5120, 5120). Specify M, N, K as command-line arguments.
./benchmark/benchmark_fpAintB

# Run a8w8 benchmark separately. Default mnk is (1, 5120, 5120). Specify M, N, K as command-line arguments.
./benchmark/benchmark_w8a8

# Run benchmarks for all M, N, K and generate a unified CSV report.
cd benchmark
python run_benchmark.py