Overview of federated modeling
The Federated Modeling console is a development platform for federated learning. It is designed for developers of federated models, such as federated algorithm engineers.
The Federated Modeling console encapsulates the basic capabilities of federated learning and integrates features from common machine learning libraries, such as TensorFlow, to provide out-of-the-box functionality. This lets you focus on the model itself instead of the implementation details of the federated algorithm, enabling fast and efficient model development. The federated modeling process involves creating, editing, and executing scripts. Scripts are divided into five types based on the development stage: Federated Table, Pre-processing Rule, Pre-processing Application, Model Training, and Model Evaluation. For more information, see Script input/output configurations. A complete federated learning project contains multiple types of scripts that are connected by their input and output data, as shown in the following figure.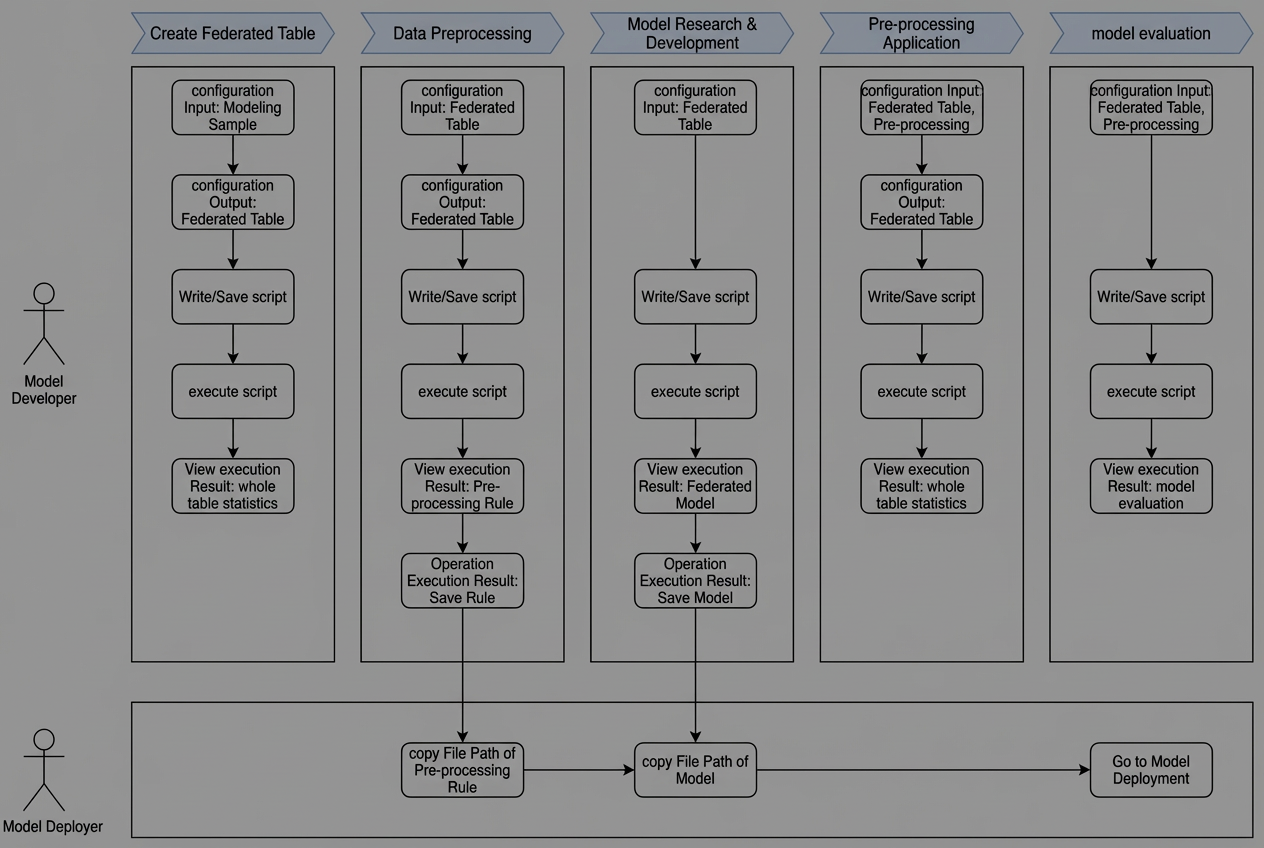 Federated model development includes:
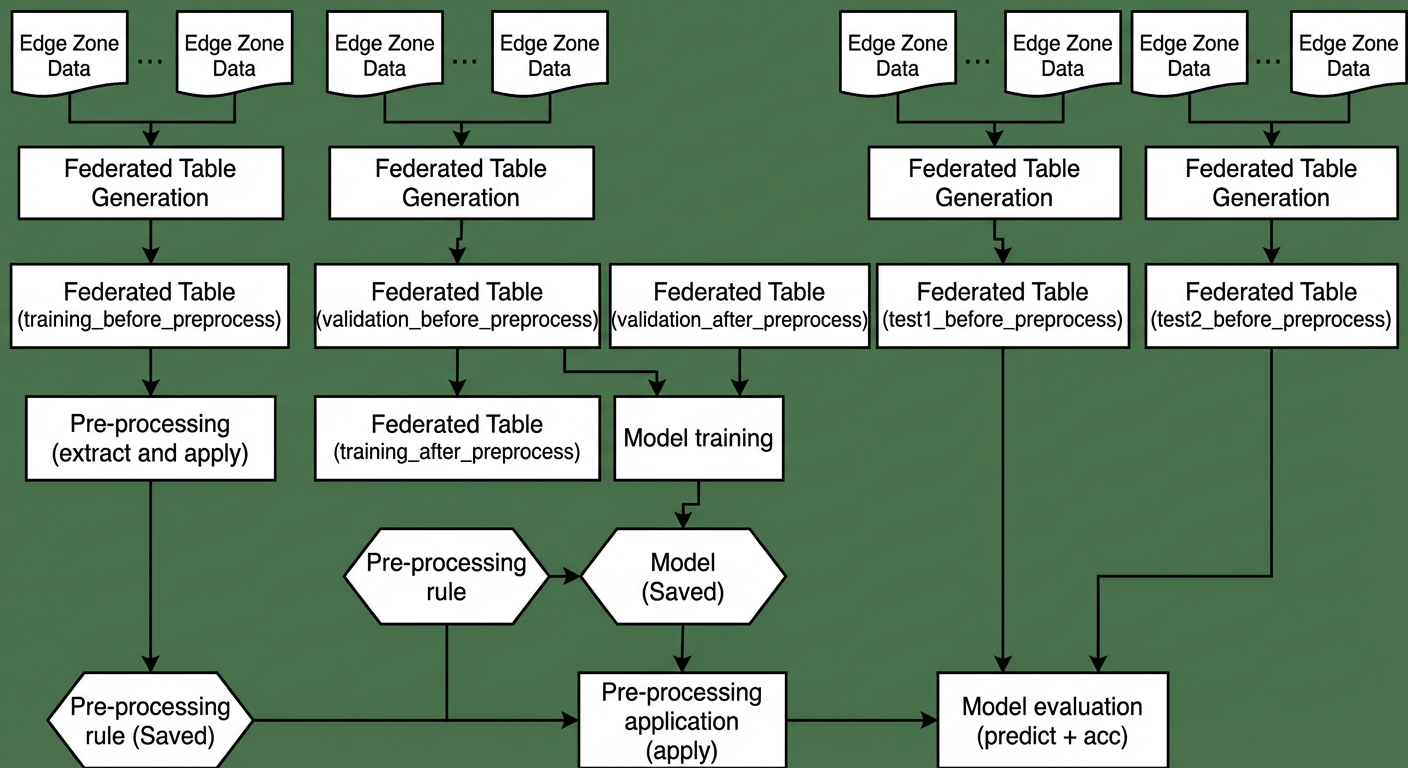
Data processing: This includes sample data processing and federated data processing.
Sample data processing: Creates a federated table by logically combining data with the same properties from each node.
Federated data processing: Pre-processes the data in the federated table. This stage includes both data pre-processing and pre-processing application.
Model training: Uses the pre-processed training dataset to train the model.
Model evaluation: Uses the pre-processed test dataset to evaluate the model performance.
A typical model development workflow is shown in the figure below. Three federated tables are generated from offline samples to serve as the training set, validation set, and test set. They are used as inputs for pre-processing, pre-processing application, and model evaluation, respectively.