Synchronize data from PolarDB for MySQL to DataHub
Alibaba Cloud DataHub is a platform for processing streaming data. It provides services to publish, subscribe to, and distribute data streams, allowing you to easily build analytics and applications based on streaming data. You can use Data Transmission Service (DTS) to synchronize data from a PolarDB for MySQL cluster to DataHub. This enables you to perform real-time data analysis by using big data products such as Realtime Compute for Apache Flink.
Prerequisites
The DataHub instance is in the China (Hangzhou), China (Shanghai), China (Beijing), or China (Shenzhen) region.
You have created a project in the DataHub instance to receive the synchronized data. For more information, see Create a project.
Binary logging is enabled for the PolarDB for MySQL cluster. For more information, see Enable binary logging.
Each table you synchronize from the PolarDB for MySQL cluster must have a primary key or a unique constraint.
Billing
|
Synchronization type |
Pricing |
|
Schema synchronization and full data synchronization |
Free of charge. |
|
Incremental data synchronization |
Charged. For more information, see Billing overview. |
Limitations
Initial full data synchronization is not supported. DTS does not synchronize the historical data of the selected objects from the source PolarDB for MySQL cluster to the destination DataHub instance.
Only table-level data synchronization is supported.
If you add a column to a source table, DTS does not synchronize data from the new column to the destination DataHub instance.
Do not perform data definition language (DDL) operations on the tables being synchronized in the source database during data synchronization. Otherwise, the synchronization task fails.
SQL operations that can be synchronized
Operation type | SQL statement |
DML | INSERT, UPDATE, and DELETE |
DDL | ADD COLUMN |
Procedure
Purchase a data synchronization task. For more information, see Purchase process.
NoteOn the purchase page, set the source instance to PolarDB and the destination instance to DataHub. For Synchronization Topology, select One-way Synchronization.
- Log on to the Data Transmission Service console.
Note
If you are automatically redirected to the Data Management (DMS) console, you can click the
 icon in the lower-right corner and then click
 to return to the classic DTS console.
- In the navigation pane on the left, click Data Synchronization.
- In the top navigation bar of the Data Synchronization page, select the region where the destination instance is located.
- Find the purchased data synchronization instance and click Configure Synchronization Channel.
Configure the source and destination instances for the data synchronization task.
Category
Parameter
Description
N/A
Synchronization Task Name
DTS automatically generates a task name, but we recommend specifying a descriptive one for easier identification. The name does not have to be unique.
Source Instance Details
Instance Type
The value is fixed at PolarDB Instance and cannot be changed.
Instance Region
The region of the source instance that you selected during purchase. This setting cannot be changed.
PolarDB Instance ID
Select the cluster ID of the source PolarDB for MySQL cluster.
Database Account
Enter the database account of the PolarDB for MySQL cluster.
Database Password
Enter the password for the database account.
Destination Instance Details
Instance Type
The value is fixed at DataHub and cannot be changed.
Instance Region
The region of the destination instance that you selected during purchase. This setting cannot be changed.
Project
Select the Project in the DataHub instance.
-
In the lower-right corner of the page, click Set Whitelist and Next.
If the source or destination database is an Alibaba Cloud database instance, such as an ApsaraDB RDS for MySQL or ApsaraDB for MongoDB instance, DTS automatically adds the CIDR blocks of DTS servers to the IP address whitelist of the instance. If the source or destination database is a self-managed database hosted on an Elastic Compute Service (ECS) instance, DTS automatically adds the CIDR blocks of DTS servers to the security group rules of the ECS instance, and you must make sure that the ECS instance can access the database. If the self-managed database is hosted on multiple ECS instances, you must manually add the CIDR blocks of DTS servers to the security group rules of each ECS instance. If the source or destination database is a self-managed database that is deployed in a data center or provided by a third-party cloud service provider, you must manually add the CIDR blocks of DTS servers to the IP address whitelist of the database to allow DTS to access the database. For more information, see Whitelist DTS server IP addresses.
WarningAdding the public IP address blocks of the DTS service, either automatically or manually, may pose security risks. Using this product, you acknowledge that you understand and accept the potential security risks and that you must implement basic security measures. These measures include, but are not limited to, strengthening password security, limiting the ports open to each CIDR block, using authentication for internal API calls, and regularly checking and restricting unnecessary CIDR blocks. Alternatively, you can connect through a private network using a leased line, VPN Gateway, or Smart Access Gateway.
Configure the synchronization policy and objects.
Parameter
Description
Initial synchronization
Select Initial Schema Synchronization. DTS synchronizes the schemas of the selected objects to the destination DataHub project.
Objects to synchronize
In the Available section, select tables and click
 to move them to the Selected section. To rename synchronized objects in the destination, use the object name mapping feature. See Rename an object to be synchronized.
Enable new naming rules for additional columns
Select Yes or No. Before configuring this parameter, check whether the additional column names conflict with existing columns in the destination topic. Otherwise, the data synchronization task may fail or data may be lost. See Naming rules for additional columns.
Rename databases and tables
Use the object name mapping feature to rename synchronized objects in the destination. See Object name mapping.
Replicate temporary tables when DMS performs DDL operations
Controls whether DTS synchronizes temporary tables generated by online DDL operations in DMS. Yes: DTS synchronizes temporary tables. Large online DDL operations may increase synchronization latency. No: DTS skips temporary tables and synchronizes only the original DDL from the source. Destination tables may be locked.
Retry time for failed connections
Default: 720 minutes (12 hours). If DTS reconnects within this period, synchronization resumes. Otherwise, the task fails. DTS charges apply during retry periods. Set this value based on your business needs, and release the instance if the source and destination instances are released.
(Optional) In the Selected section, hover over a table name and click Edit to configure a shard key for table partitioning.
After you complete the preceding configurations, click Precheck and Start in the lower-right corner of the page.
NoteBefore the synchronization task is officially started, a precheck is performed. The synchronization task can only be started after the precheck passes.
If the precheck fails, click the
 icon next to a specific check item to view the failure details.
Follow the prompt to fix the issue and run the precheck again.
If you do not need to fix the warning check items, you can also select Ignore, Ignore Warning Items and Rerun Precheck to skip the warning check items and run the precheck again.
- After Precheck Passed is displayed in the Precheck dialog box, close the dialog box. The synchronization task starts automatically.
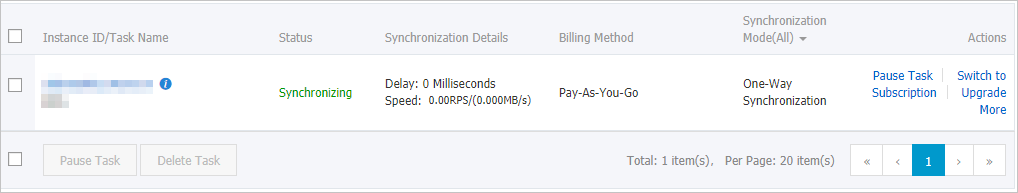
- Wait until the synchronization channel is initialized and the task enters the Synchronizing state.
The Data Synchronization page displays the status of data synchronization jobs.
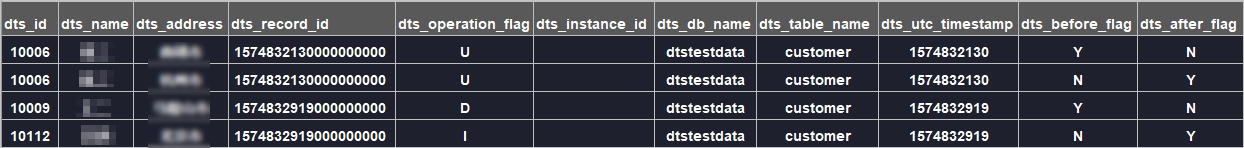
DataHub topic schema
When DTS synchronizes incremental data to a DataHub topic, it adds metadata columns to the topic.
In this example,id,name, andaddressare data fields. When the previous naming rules are used, DTS adds thedts_prefix to all fields, including the original fields from the source. When the new naming rules are used, DTS does not add a prefix to the original source fields.
Previous column name | New column name | Type | Description |
|
| String | Unique ID of the incremental log entry. Auto-increments for each new entry. In disaster recovery scenarios, rollback may cause ID duplication. For UPDATE operations, both log entries (pre-update and post-update) share the same |
|
| String | The operation type. Valid values: |
|
| String | The server ID of the database. |
|
| String | The database name. |
|
| String | The table name. |
|
| String | The operation timestamp in UTC. This is also the timestamp of the log file. |
|
| String | Indicates whether the row values are pre-update values. Valid values: |
|
| String | Indicates whether the row values are post-update values. Valid values: |
Before and after flag values
The dts_before_flag and dts_after_flag columns indicate whether a row in the topic represents the state before or after a data change.
Operation | Log entries generated | dts_before_flag | dts_after_flag | Row content |
INSERT | 1 |
|
| The newly inserted values. |
DELETE | 1 |
|
| The deleted values. |
UPDATE (first entry) | 2 (same |
|
| Pre-update values. |
UPDATE (second entry) | 2 (same |
|
| Post-update values. |
INSERT operation
The log entry contains the newly inserted values. dts_before_flag is N and dts_after_flag is Y.
UPDATE operation
DTS generates two log entries with the same dts_record_id, dts_operation_flag, and dts_utc_timestamp values. The first entry captures the pre-update values (dts_before_flag=Y, dts_after_flag=N). The second entry captures the post-update values (dts_before_flag=N, dts_after_flag=Y).

DELETE operation
The log entry contains the deleted values. dts_before_flag is Y and dts_after_flag is N.

Before and after flag values
The dts_before_flag and dts_after_flag columns indicate whether a row in the topic represents the state before or after a data change.
Operation | Log entries generated | dts_before_flag | dts_after_flag | Row content |
INSERT | 1 |
|
| The newly inserted values. |
DELETE | 1 |
|
| The deleted values. |
UPDATE (first entry) | 2 (same |
|
| Pre-update values. |
UPDATE (second entry) | 2 (same |
|
| Post-update values. |
INSERT operation
The log entry contains the newly inserted values. dts_before_flag is N and dts_after_flag is Y.
UPDATE operation
DTS generates two log entries with the same dts_record_id, dts_operation_flag, and dts_utc_timestamp values. The first entry captures the pre-update values (dts_before_flag=Y, dts_after_flag=N). The second entry captures the post-update values (dts_before_flag=N, dts_after_flag=Y).
DELETE operation
The log entry contains the deleted values. dts_before_flag is Y and dts_after_flag is N.
What's next
After the synchronization task is running, use Alibaba Cloud Realtime Compute for Apache Flink to analyze the data in the DataHub project. For more information, see What is Alibaba Cloud Realtime Compute for Apache Flink?