Overview
When you migrate an HPC environment to the cloud, your on-premises scheduler often comes with it. E-HPC integrates mainstream open source schedulers, but some third-party schedulers—particularly licensed tools such as electronic design automation (EDA) software—cannot connect to E-HPC directly due to compatibility constraints. Scheduler plug-ins solve this: they let you build a custom scheduler and connect it to the E-HPC console, so you can manage nodes, jobs, and auto scaling from a single interface.
What is a scheduler plug-in?
E-HPC is a platform as a service (PaaS) tool that integrates mainstream open source schedulers. When the built-in schedulers don't meet your requirements—because of scheduler type or version—a scheduler plug-in provides an alternative path.
For example, EDA software requires a purchased license to run its scheduler. Because E-HPC does not provide such licenses, you build a custom scheduler and connect it to E-HPC using the plug-in mechanism.
A scheduler plug-in includes templates, configuration files, and modularized features. After building a custom plug-in, create a cluster in the E-HPC console and deploy the plug-in on the cluster. This gives you console-based control over nodes, jobs, and auto scaling.
How it works
The following describes how E-HPC processes a job submission request through a scheduler plug-in.
Log on to the E-HPC console, select a cluster, and submit a job.
E-HPC receives the request and sends a command to the cluster.
The scheduling node identifies the plug-in type, downloads the plug-in to a local path, and parses the
JobSubmitparameter:If
JobSubmitisfalse, an error is returned. The plug-in cannot submit jobs.If
JobSubmitistrue, the plug-in proceeds.
Call the job submission command of the plug-in. For PBS, this is
qsub. For LSF, this isbsub. The plug-in returns a result after the job is submitted.
Scheduler plug-in files
The following figure shows the directories of scheduler plug-in files.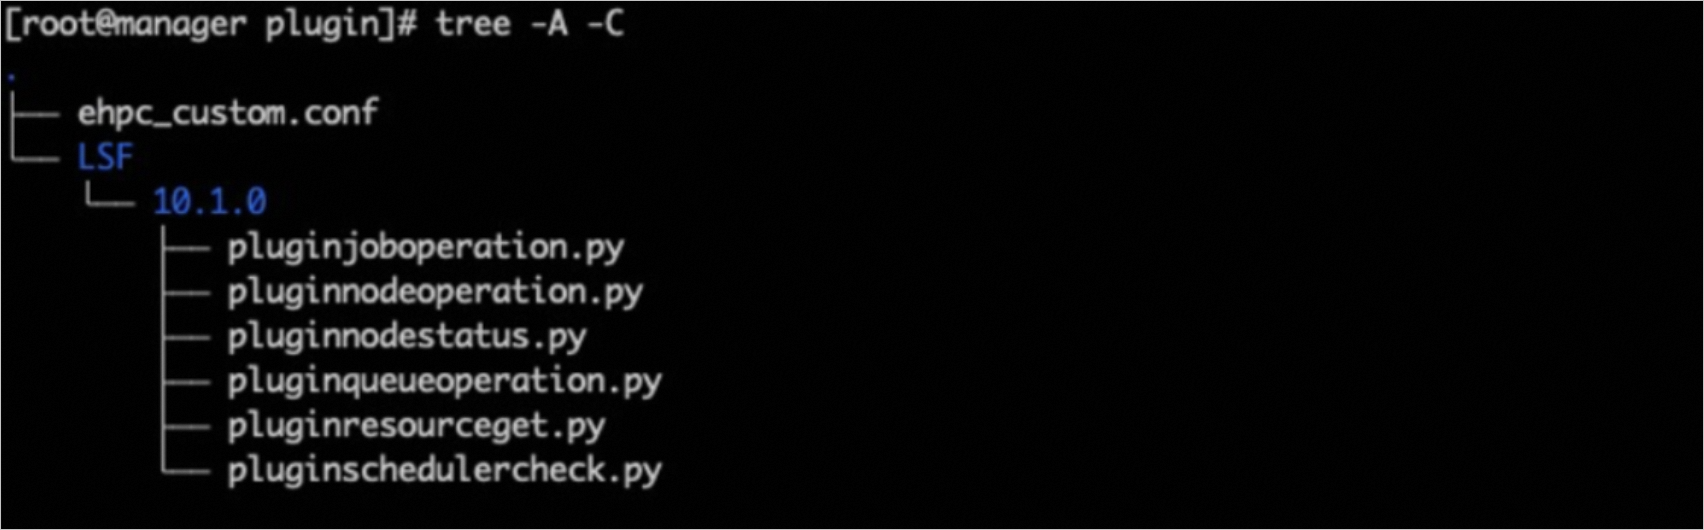
A scheduler plug-in consists of two types of files:
`ehpc_custom.conf`: The configuration file. It specifies the scheduler information and the features the plug-in supports. For more information, see Configuration files.
**
*.py**: Script files that implement specific scheduler features based on the plug-in template. Store these files in the second-level directory under/<scheduler name>/<scheduler version>—for example,/LSF/10.1.0.
Configuration files
The configuration file defines what the plug-in is and what it can do. The following figure shows the features.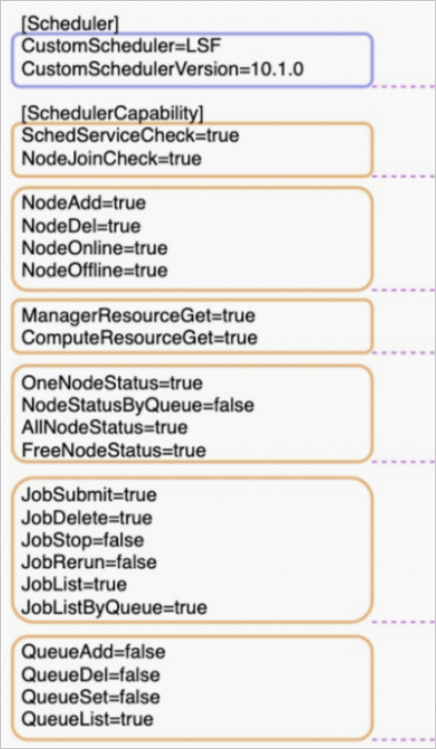
The file has two sections:
`[Scheduler]`: Specifies the scheduler name and version number.
`[SchedulerCapability]`: Lists the features the plug-in supports. Each item is a feature flag that enables or disables a specific capability.
Capability overview
Scheduling service detection (priority 3) is the prerequisite for all other capabilities. None of the features listed below work unless it is enabled. The higher the priority value, the more significant the feature.
| Capability | Priority | What it does |
|---|---|---|
| Scheduling service detection | 3 | Configures the statuses of cluster nodes shown in the console |
| Node operations | 2 | Adds or removes nodes in the console for manual scale-in or scale-out |
| Resource query | 2 | Gets resources based on node information and visualizes them in the console |
| Node status query | 1 | Monitors node statuses to support auto scaling in the console |
| Job operations | 1 | Submits or queries jobs in the console |
| Queue operations | 1 | Adds or queries queues in the console |