Routine Load
Routine Load continuously ingests data from Apache Kafka into StarRocks on EMR. Once a load job is running, StarRocks polls the Kafka topic automatically — you control the job lifecycle with SQL statements (pause, resume, or stop).
Basic concepts
- RoutineLoadJob: a routine load job that you submit.
- JobScheduler: the routine load job scheduler, which schedules a RoutineLoadJob and splits it into multiple tasks.
- Task: a subtask into which the JobScheduler splits a RoutineLoadJob based on specific rules.
- TaskScheduler: the task scheduler, which schedules the execution of tasks.
How it works
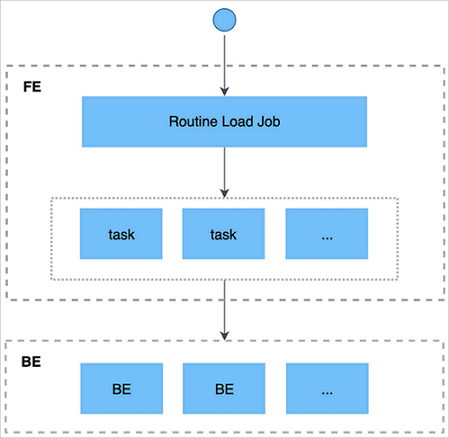
- You submit a Kafka load job to an FE by using a client that supports the MySQL protocol.
- The FE splits the load job into multiple tasks. Each task loads a specified portion of the data.
- Each task is assigned to a specified BE for execution. On the BE, a task is processed as a regular load job and is loaded by using the Stream Load mechanism.
- After the BE completes the load, it reports the result to the FE.
- Based on the reported result, the FE continues to generate new tasks or retries failed tasks.
- The FE continuously generates new tasks to load data without interruption.
Import process
Environment requirements
-
Supports Kafka clusters with no authentication or SSL-based authentication.
-
Supported message formats:
-
CSV text format, where each message is one line without a trailing line feed.
-
JSON text format.
-
-
Does not support Array types.
-
Only supports Kafka version 0.10.0.0 or later.
Create an import task
-
Syntax
CREATE ROUTINE LOAD <database>.<job_name> ON <table_name>
    [COLUMNS TERMINATED BY "column_separator" ,]
    [COLUMNS (col1, col2, ...) ,]
    [WHERE where_condition ,]
    [PARTITION (part1, part2, ...)]
    [PROPERTIES ("key" = "value", ...)]
    FROM [DATA_SOURCE]
    [(data_source_properties1 = 'value1',
    data_source_properties2 = 'value2',
    ...)]
Parameters:
Parameter Required Description job_name Yes The name of the load job. The prefix can contain the name of the database to which data is loaded. A common naming convention is a timestamp followed by the table name. Job names must be unique within a database. table_name Yes The name of the destination table to which data is loaded. COLUMNS TERMINATED clause No Specifies the column delimiter in the source data file. Default value: \t. COLUMNS clause No Specifies the mapping between the columns in the source data and the columns in the table. - Mapped columns: For example, the destination table contains three columns col1, col2, and col3, and the source data contains four columns in which the first, second, and fourth columns correspond to col2, col1, and col3 respectively. In this case, write
COLUMNS (col2, col1, temp, col3). The temp column does not exist and is used to skip the third column in the source data. - Derived columns: In addition to directly reading the column content of the source data, StarRocks supports processing data columns. For example, a fourth column col4 is added to the destination table and its value is generated from col1 + col2. In this case, you can write
COLUMNS (col2, col1, temp, col3, col4 = col1 + col2)。
WHERE clause No Specifies the filter conditions that are used to filter out unnecessary rows. The filter conditions can specify mapped columns or derived columns. For example, to load only the rows in which k1 is greater than 100 and k2 is equal to 1000, write
WHERE k1 > 100 and k2 = 1000。PARTITION clause No Specifies the partitions of the destination table to which data is loaded. If you do not specify this clause, data is automatically loaded to the corresponding partitions. PROPERTIES clause No Specifies the common parameters of the load job. desired_concurrent_number No The load concurrency, which specifies the maximum number of subtasks into which a load job can be split. The value must be greater than 0. Default value: 3. max_batch_interval No The maximum execution duration of each subtask. Valid values: 5 to 60. Unit: seconds. Default value: 10. In versions later than 1.15, this parameter specifies the scheduling interval of subtasks, that is, how often a task is executed. The data consumption duration of a task is specified by fe.conf in routine_load_task_consume_second, which is 3s by default. The execution timeout period of a task is fe.conf in routine_load_task_timeout_second, which is 15s by default.
max_batch_rows No The maximum number of rows that each subtask can read. The value must be greater than or equal to 200000. Default value: 200000. In versions later than 1.15, this parameter is used only to define the range of the error detection window. The range of the window is 10 * max-batch-rows。
max_batch_size No The maximum number of bytes that each subtask can read. Unit: bytes. Valid values: 100 MB to 1 GB. Default value: 100 MB. In versions later than 1.15, this parameter is deprecated. The data consumption duration of a task is specified by fe.conf in routine_load_task_consume_second, which is 3s by default.
max_error_number No The maximum number of error rows that are allowed within the sampling window. The value must be greater than or equal to 0. The default value is 0, which indicates that no error rows are allowed. Important Rows that are filtered out by the WHERE condition are not counted as error rows.strict_mode No Specifies whether to enable the strict mode. This mode is enabled by default. If this mode is enabled and the column type of non-null raw data is converted to NULL, the data is filtered out. To disable this mode, set this parameter to false.
timezone No Specifies the time zone that is used by the load job. By default, the timezone parameter of the session is used. This parameter affects the results of all time zone-related functions that are involved in the load.
DATA_SOURCE Yes Specifies the data source. Set this parameter to KAFKA. data_source_properties No Specifies the information about the data source. The following parameters are included: - kafka_broker_list: the connection information of the Kafka brokers, in the
ip:hostformat. Separate multiple brokers with commas (,). - kafka_topic: specifies the Kafka topic to subscribe to.Note If you specify the information about the data source, kafka_broker_list and kafka_topic are required.
- kafka_partitions and kafka_offsets: specifies the Kafka partitions to subscribe to and the start offset of each partition.
- property: the Kafka-related properties, which are equivalent to the
"--property"parameter in the Kafka shell. To view the detailed syntax for creating a load job, run theHELP ROUTINE LOAD;command.
- Mapped columns: For example, the destination table contains three columns col1, col2, and col3, and the source data contains four columns in which the first, second, and fourth columns correspond to col2, col1, and col3 respectively. In this case, write
-
Example: Create a non-authenticated Routine Load task named example_tbl2_ordertest that consumes messages from the ordertest2 topic in a Kafka cluster, starting from the earliest offset in the specified partitions.
CREATE ROUTINE LOAD load_test.example_tbl2_ordertest ON example_tbl COLUMNS(commodity_id, customer_name, country, pay_time, price, pay_dt=from_unixtime(pay_time, '%Y%m%d')) PROPERTIES ( "desired_concurrent_number"="5", "format" ="json", "jsonpaths" ="[\"$.commodity_id\",\"$.customer_name\",\"$.country\",\"$.pay_time\",\"$.price\"]" ) FROM KAFKA ( "kafka_broker_list" ="<kafka_broker1_ip>:<kafka_broker1_port>,<kafka_broker2_ip>:<kafka_broker2_port>", "kafka_topic" = "ordertest2", "kafka_partitions" ="0,1,2,3,4", "property.kafka_default_offsets" = "OFFSET_BEGINNING" ); -
Example: Access Kafka using SSL. Configuration:
-- Set the security protocol to SSL.
"property.security.protocol" = "ssl",
 -- Path to the CA certificate.
"property.ssl.ca.location" = "FILE:ca-cert",
-- If Kafka Server requires client authentication, also set these three parameters:
-- Path to the client's public key.
"property.ssl.certificate.location" = "FILE:client.pem",
-- Path to the client's private key.
"property.ssl.key.location" = "FILE:client.key",
-- Password for the client's private key.
"property.ssl.key.password" = "******"
For details about creating files, see CREATE FILE.
NoteWhen using CREATE FILE, use the HTTP endpoint of OSS as the
url. For usage details, see Access OSS over IPv6.
View task status
-
Show all Routine Load tasks in the load_test database, including stopped and canceled ones.
USE load_test; SHOW ALL ROUTINE LOAD; -
Show the running Routine Load task named example_tbl2_ordertest in the load_test database.
SHOW ROUTINE LOAD FOR load_test.example_tbl2_ordertest; -
In the EMR StarRocks Manager console, click Metadata Management, click the target database name, then click Tasks. View the task execution status on the Kafka Import tab.
Only currently running tasks are visible. Completed or unstarted tasks are not shown.
Run SHOW ALL ROUTINE LOAD to view all active Routine Load tasks. Sample output:
*************************** 1. row ***************************
                  Id: 14093
                Name: routine_load_wikipedia
          CreateTime: 2020-05-16 16:00:48
           PauseTime: N/A
             EndTime: N/A
              DbName: default_cluster:load_test
           TableName: routine_wiki_edit
               State: RUNNING
      DataSourceType: KAFKA
      CurrentTaskNum: 1
       JobProperties: {"partitions":"*","columnToColumnExpr":"event_time,channel,user,is_anonymous,is_minor,is_new,is_robot,is_unpatrolled,delta,added,deleted","maxBatchIntervalS":"10","whereExpr":"*","maxBatchSizeBytes":"104857600","columnSeparator":"','","maxErrorNum":"1000","currentTaskConcurrentNum":"1","maxBatchRows":"200000"}
DataSourceProperties: {"topic":"starrocks-load","currentKafkaPartitions":"0","brokerList":"localhost:9092"}
    CustomProperties: {}
           Statistic: {"receivedBytes":150821770,"errorRows":122,"committedTaskNum":12,"loadedRows":2399878,"loadRowsRate":199000,"abortedTaskNum":1,"totalRows":2400000,"unselectedRows":0,"receivedBytesRate":12523000,"taskExecuteTimeMs":12043}
            Progress: {"0":"13634667"}
ReasonOfStateChanged:
        ErrorLogUrls: http://172.26.**.**:9122/api/_load_error_log?file=__shard_53/error_log_insert_stmt_47e8a1d107ed4932-8f1ddf7b01ad2fee_47e8a1d107ed4932_8f1ddf7b01ad2fee, http://172.26.**.**:9122/api/_load_error_log?file=__shard_54/error_log_insert_stmt_e0c0c6b040c044fd-a162b16f6bad53e6_e0c0c6b040c044fd_a162b16f6bad53e6, http://172.26.**.**:9122/api/_load_error_log?file=__shard_55/error_log_insert_stmt_ce4c95f0c72440ef-a442bb300bd743c8_ce4c95f0c72440ef_a442bb300bd743c8
            OtherMsg:
1 row in set (0.00 sec)
The example above creates an import task named routine_load_wikipedia. The following table describes each output field.
|
Parameter |
Description |
|
State |
Task status. RUNNING indicates the task is actively importing data. |
|
Statistic |
Progress metrics tracking import activity since task creation. |
|
receivedBytes |
Amount of data received, in bytes. |
|
errorRows |
Number of rows with import errors. |
|
committedTaskNum |
Number of Tasks committed by the FE. |
|
loadedRows |
Number of rows successfully imported. |
|
loadRowsRate |
Data import rate, in rows per second (row/s). |
|
abortedTaskNum |
Number of Tasks that failed on BEs. |
|
totalRows |
Total number of rows received. |
|
unselectedRows |
Number of rows filtered out by the WHERE clause. |
|
receivedBytesRate |
Data reception rate, in bytes per second (Bytes/s). |
|
taskExecuteTimeMs |
Import duration, in milliseconds (ms). |
|
ErrorLogUrls |
URLs to error logs showing import errors. |
Pause an import task
The PAUSE statement stops data import and moves the task to PAUSED state. The task remains active and can be resumed with RESUME.
PAUSE ROUTINE LOAD FOR <job_name>;After pausing, the task’s State changes to PAUSED. The Statistic and Progress fields stop updating. The paused task remains visible via SHOW ROUTINE LOAD.
Resume an import task
The RESUME statement reschedules the task. It briefly enters NEED_SCHEDULE state before returning to RUNNING.
RESUME ROUTINE LOAD FOR <job_name>;Stop an import task
The STOP statement permanently stops the import task. Once stopped, it cannot be resumed.
STOP ROUTINE LOAD FOR <job_name>;After stopping, the task’s State becomes STOPPED. The Statistic and Progress fields no longer update. Stopped tasks are not visible via SHOW ROUTINE LOAD.
MySQL [load_test]> SHOW ROUTINE LOAD FOR example_tbl2_ordertest2 \G;
ERROR 1064 (HY000): There is no running job named example_tbl2_ordertest2 in db load_test. Include history? false, you can try `show all routine load job for job_name` if you want to list stopped and cancelled jobs
ERROR: No query specified
Best practices
This example continuously imports CSV-formatted data from a Kafka cluster into StarRocks using Routine Load.
-
On the Kafka cluster:
-
Create a test topic.
kafka-topics.sh --create --topic order_sr_topic --replication-factor 3 --partitions 10 --bootstrap-server "core-1-1:9092,core-1-2:9092,core-1-3:9092" -
Run the following command to generate data.
kafka-console-producer.sh --broker-list core-1-1:9092 --topic order_sr_topic -
Enter test data.
2020050802,2020-05-08,Johann Georg Faust,Deutschland,male,895
2020050802,2020-05-08,Julien Sorel,France,male,893
2020050803,2020-05-08,Dorian Grey,UK,male,1262
2020051001,2020-05-10,Tess Durbeyfield,US,female,986
2020051101,2020-05-11,Edogawa Conan,japan,male,8924
-
-
Perform the following operations in the StarRocks cluster.
-
Create the destination database and table.
Based on the CSV data (importing all columns except the fifth gender column), create the table routine_load_tbl_csv in the load_test database.
CREATE TABLE load_test.routine_load_tbl_csv ( `order_id` bigint NOT NULL COMMENT "Order ID", `pay_dt` date NOT NULL COMMENT "Payment date", `customer_name` varchar(26) NULL COMMENT "Customer name", `nationality` varchar(26) NULL COMMENT "Nationality", `price` double NULL COMMENT "Payment amount" ) ENGINE=OLAP PRIMARY KEY (order_id,pay_dt) DISTRIBUTED BY HASH(`order_id`) BUCKETS 5; -
Create the import task.
CREATE ROUTINE LOAD load_test.routine_load_tbl_ordertest_csv ON routine_load_tbl_csv COLUMNS TERMINATED BY ",", COLUMNS (order_id, pay_dt, customer_name, nationality, temp_gender, price) PROPERTIES ( "desired_concurrent_number" = "5" ) FROM KAFKA ( "kafka_broker_list" ="192.168.**.**:9092,192.168.**.**:9092,192.168.**.**:9092", "kafka_topic" = "order_sr_topic", "kafka_partitions" ="0,1,2,3,4", "property.kafka_default_offsets" = "OFFSET_BEGINNING" ) -
Run the following command to view information about the import task named routine_load_tbl_ordertest_csv.
SHOW ROUTINE LOAD FOR routine_load_tbl_ordertest_csv;If the state is RUNNING, the job is operating normally.
-
Query the destination table to confirm data synchronization.
SELECT * FROM routine_load_tbl_csv;Additional operations:
-
Pause the import task
PAUSE ROUTINE LOAD FOR routine_load_tbl_ordertest_csv; -
Resume the import task
RESUME ROUTINE LOAD FOR routine_load_tbl_ordertest_csv; -
Modify the import task
NoteYou can only modify tasks in PAUSED state.
Example: Change desired_concurrent_number to 6.
ALTER ROUTINE LOAD FOR routine_load_tbl_ordertest_csv PROPERTIES ( "desired_concurrent_number" = "6" ) -
Stop the import task
STOP ROUTINE LOAD FOR routine_load_tbl_ordertest_csv;
-
-