Build a log analytics system with Filebeat, Kafka, Logstash, and Elasticsearch
As log data accumulates, viewing and analyzing it becomes challenging. You can use Filebeat, Message Queue for Apache Kafka, Logstash, and Alibaba Cloud Elasticsearch to collect log data into Alibaba Cloud Elasticsearch, and then use Kibana to visualize and analyze the data.
Background information
Kafka is a distributed, high-throughput, and scalable message queue service. It is widely used in big data for tasks such as log collection, monitoring data aggregation, stream processing, and online and offline analytics, making it an essential part of the big data ecosystem. For more information, see What is Message Queue for Apache Kafka?.
In a typical use case, you can use Filebeat to collect log data and send it to Kafka to meet real-time data retrieval needs. Kafka receives the data from Filebeat and forwards it to Logstash. If the format or content of the data does not meet your requirements, you can use Logstash filter plug-ins to process the data. Finally, Logstash sends the processed data to Alibaba Cloud Elasticsearch for distributed search. You can then visualize and analyze the data in Kibana. The following diagram shows the basic process.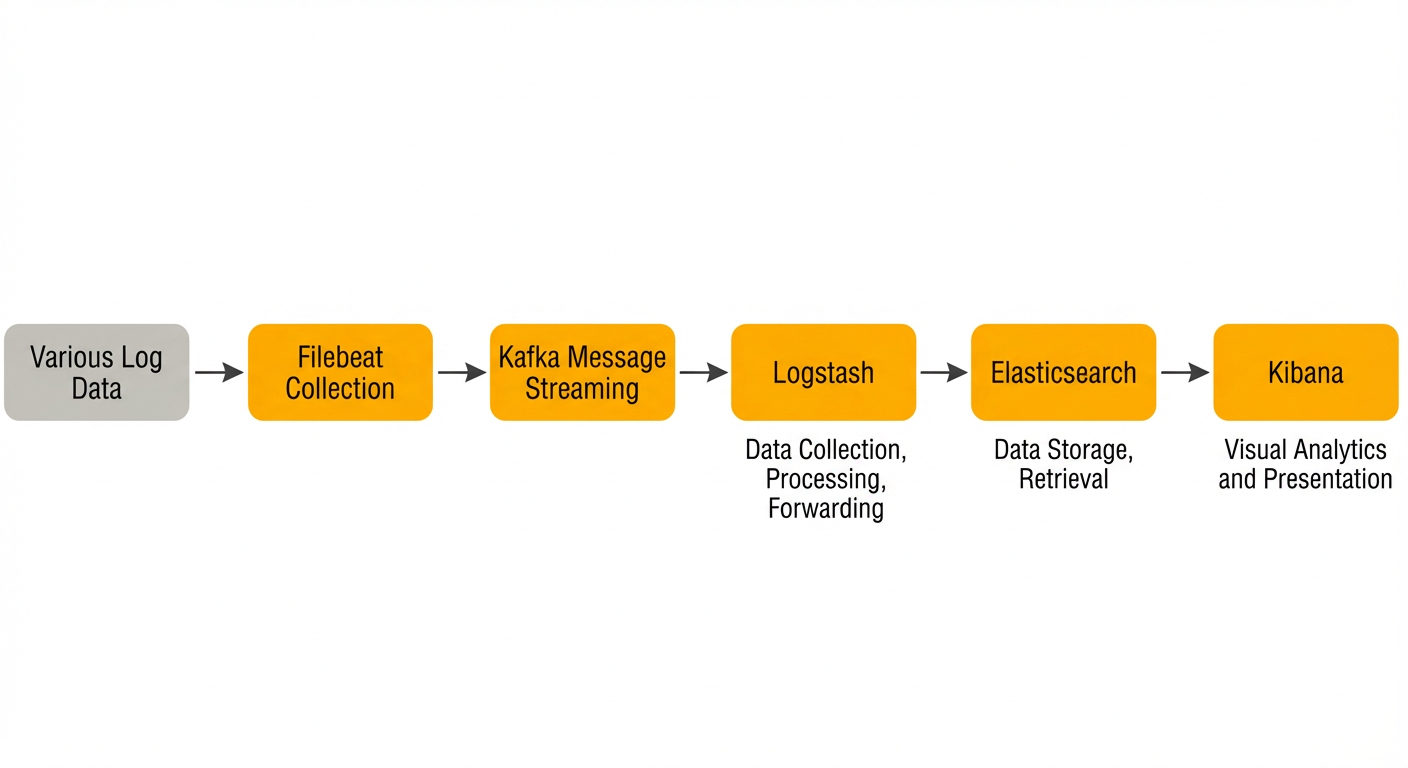
Procedure
-
Prepare the environment by creating Alibaba Cloud Elasticsearch, Logstash, ECS, and Message Queue for Apache Kafka instances. You also need to create a topic and a consumer group.
ImportantWe recommend that you use Alibaba Cloud Elasticsearch, Logstash, ECS, and Message Queue for Apache Kafka instances that are in the same Virtual Private Cloud (VPC).
-
Step 1: Install and configure Filebeat
Install and configure Filebeat. Set the input to system logs and the output to Kafka to collect log data into a specified Kafka topic.
-
Step 2: Configure the Logstash pipeline
Configure the Logstash pipeline by setting the input to Kafka and the output to Alibaba Cloud Elasticsearch. Use Logstash to consume data from the topic and send it to your Alibaba Cloud Elasticsearch instance.
-
Step 3: Check the log consumption status
In Message Queue for Apache Kafka, check the consumption status to verify that the data was collected successfully.
-
Step 4: Filter log data in Kibana
On the Discover page of the Kibana console, use a filter to view Kafka-related logs.
Prerequisites
-
Create an Alibaba Cloud Elasticsearch instance and enable the automatic index creation feature.
For more information, see Create an Alibaba Cloud Elasticsearch instance and Configure YML parameters. This topic uses an instance of version 6.7 as an example.
-
Create an Alibaba Cloud Logstash instance.
For more information, see Create an Alibaba Cloud Logstash instance. The instance must meet the following requirements:
-
Version: The version must be compatible with your Alibaba Cloud Elasticsearch instance. For more information, see Product compatibility. This topic uses the same version as the Elasticsearch instance, which is 6.7.
-
Network: The instance must be in the same VPC as the Alibaba Cloud Elasticsearch instance. Otherwise, you must configure a NAT Gateway to enable public network access. For more information, see Use a NAT Gateway to transfer data over the internet.
-
-
Purchase and deploy a
ApsaraMQ for Kafkainstance, and create a topic and a consumer group.
This topic uses a VPC instance that is in the same VPC as the Alibaba Cloud Elasticsearch instance. For more information, see VPC access.
For more information about how to create a topic and a consumer group, see Step 3: Create resources.
-
Create an ECS instance.
For more information, see Create an instance by using the wizard. The ECS instance in this topic is in the same VPC as the Alibaba Cloud Elasticsearch instance. Otherwise, you need to configure a public access allowlist to enable network communication. For more information, see Configure a public or private IP address allowlist for an instance.
ImportantThis ECS instance is used to install Filebeat. Because Filebeat currently supports only the Alibaba Cloud Linux (Alinux), RedHat, and CentOS operating systems, you must select one of these operating systems when you create the instance.
Step 1: Install and configure Filebeat
-
Connect to your ECS instance.
For more information, see Connect to an instance.
-
Install Filebeat.
This topic uses Filebeat 6.8.5 as an example. For more information, see Install Filebeat. Run the following commands to install Filebeat.
curl -L -O https://artifacts.elastic.co/downloads/beats/filebeat/filebeat-6.8.5-linux-x86_64.tar.gz tar xzvf filebeat-6.8.5-linux-x86_64.tar.gz -
Run the following commands to go to the Filebeat installation directory and create and configure the filebeat.kafka.yml file.
cd filebeat-6.8.5-linux-x86_64
vi filebeat.kafka.yml
The following code shows the content of the filebeat.kafka.yml file.
filebeat.prospectors: - type: log enabled: true paths: - /var/log/*.log output.kafka: hosts: ["alikafka-post-cn-zvp2n4v7****-1-vpc.alikafka.aliyuncs.com:9092"] topic: estest version: 0.10.2ImportantFor Filebeat 7.0 and later, you must replace filebeat.prospectors with filebeat.inputs.
Parameter
Description
type
The input type. Use
logfor log files.enabled
Specifies whether the configuration is enabled:
-
true: enabled
-
false: disabled
paths
The paths of the log files that you want to monitor. To add multiple log files, specify the path of each file on a new line.
hosts
The endpoint of the Message Queue for Apache Kafka instance. You can obtain the endpoint from the instance details page. For more information, see View endpoints. This topic uses a VPC instance, so you can use any of the default endpoints.
topic
The destination topic in Message Queue for Apache Kafka. Use the topic that you created.
version
The version of Kafka. You can find this on the instance details page in the Message Queue for Apache Kafka console.
Important-
An error occurs if you do not configure this parameter.
-
Different versions of Filebeat support different versions of Kafka. For example, Filebeat 8.2 and later support Kafka 2.2.0. You must set the version parameter to a Kafka version that your Filebeat version supports. Otherwise, an error message like the following appears:
Exiting: error initializing publisher: unknown/unsupported kafka version '2.2.0' accessing 'output.kafka.version' (source:'filebeat.kafka.yml'). For more information, see version.
-
-
Start Filebeat.
./filebeat -e -c filebeat.kafka.yml
Step 2: Configure the Logstash pipeline
Go to the Logstash Clusters page.
Navigate to the target cluster.
In the top navigation bar, select the region where the cluster resides.
On the Logstash Clusters page, find the cluster and click its ID.
-
In the left-side navigation pane, click Pipelines.
-
Click Create Pipeline.
-
On the Create pipeline task page, enter a Pipeline ID and configure the pipeline.
This topic uses the following pipeline configuration.
input {
  kafka {
    bootstrap_servers => ["alikafka-post-cn-zvp2n4v7****-1-vpc.alikafka.aliyuncs.com:9092,alikafka-post-cn-zvp2n4v7****-2-vpc.alikafka.aliyuncs.com:9092,alikafka-post-cn-zvp2n4v7****-3-vpc.alikafka.aliyuncs.com:9092"]
    group_id => "es-test"
    topics => ["estest"]
    codec => json
 }
}
filter {

}
output {
  elasticsearch {
    hosts => "http://es-cn-n6w1o1x0w001c****.elasticsearch.aliyuncs.com:9200"
    user =>"elastic"
    password =>"<your_password>"
    index => "kafka‐%{+YYYY.MM.dd}"
 }
}
Table 1. Input parameters
Parameter
Description
bootstrap_servers
The endpoints of the Message Queue for Apache Kafka instance. You can obtain the endpoints from the instance details page. For more information, see View endpoints. This topic uses a VPC instance, so you can use the default endpoints.
group_id
Specify the name of the consumer group that you created.
topics
Specify the name of the topic that you created. This must be the same topic that you configured in Filebeat.
codec
Set the value to json to parse JSON-formatted fields for analysis in Kibana.
Table 2. Output parameters
Parameter
Description
hosts
The endpoint of the Alibaba Cloud Elasticsearch instance, in the format of
http://<private_endpoint_of_your_Alibaba_Cloud_Elasticsearch_instance>:9200.NoteYou can obtain the private endpoint from the basic information page of your Alibaba Cloud Elasticsearch instance. For more information, see View the basic information of an instance.
user
The username to access the Alibaba Cloud Elasticsearch instance. The default username is elastic. You can also create a custom user. For more information, see Use Elasticsearch X-Pack role management to control user permissions.
password
The password to access the Alibaba Cloud Elasticsearch instance. You set this password when you create the instance. If you forget the password, you can reset it. To learn how to reset the password, see Reset the access password of an instance.
index
The index name. The value
kafka‐%{+YYYY.MM.dd}indicates that the index name starts with the prefixkafkaand ends with the date suffix, for example,kafka-2020.05.27.For more information about configuration settings, see Logstash configuration files.
If you need to sync data from multiple topics, add the new topic in Kafka and then add another input block to your Logstash pipeline configuration. For example:
input { kafka { bootstrap_servers => ["alikafka-post-cn-zvp2n4v7****-1-vpc.alikafka.aliyuncs.com:9092,alikafka-post-cn-zvp2n4v7****-2-vpc.alikafka.aliyuncs.com:9092,alikafka-post-cn-zvp2n4v7****-3-vpc.alikafka.aliyuncs.com:9092"] group_id => "es-test" topics => ["estest"] codec => json } kafka { bootstrap_servers => ["alikafka-post-cn-zvp2n4v7****-1-vpc.alikafka.aliyuncs.com:9092,alikafka-post-cn-zvp2n4v7****-2-vpc.alikafka.aliyuncs.com:9092,alikafka-post-cn-zvp2n4v7****-3-vpc.alikafka.aliyuncs.com:9092"] group_id => "es-test-2" topics => ["estest_2"] codec => json } } -
Click Next step and configure the pipeline parameters.
Parameter
Description
Pipeline Workers
Number of worker threads for the filter and output stages. Increase this value if events are backlogged or CPU is underutilized. Default: the number of CPU cores.
Pipeline Batch Size
Maximum events a worker collects before executing filters and outputs. Larger batches increase memory usage and may require a larger JVM heap size (LS_HEAP_SIZE). Default: 125.
Pipeline Batch Delay
Wait time in milliseconds before dispatching an undersized batch to a worker thread. Default: 50 ms.
Queue Type
Internal queuing model for event buffering between stages. Valid values:
-
MEMORY: Default. Uses an in-memory queue.
-
PERSISTED: A disk-based persistent queue.
Queue Max Bytes
The maximum amount of data the queue can store, in
MB. The value must be an integer from1to253-1. Default value:1024.NoteMake sure that this value is less than your total disk capacity.
Queue Checkpoint Writes
Maximum events written before a checkpoint is forced (persistent queue only). 0 means no limit. Default: 1024.
WarningSaving and deploying the configuration triggers an instance restart. Proceed only when this will not affect your business.
-
-
Click Save or Save and Deploy.
-
Save: Saves the pipeline configuration but does not apply it. After saving, you are returned to the Pipelines page. In the Pipelines section, you can click Deploy Now in the Actions column to restart the instance and apply the configuration.
-
Save and Deploy: Saves and deploys the configuration, restarting the instance to apply the changes.
-
Step 3: Check log consumption
-
Go to the Message Queue for Apache Kafka console.
-
For more information, see View consumer status to check the detailed consumption status.
Expected result: On the consumer details page, the consumption offset of each partition is the same as the maximum offset, and the consumer lag is 0. This indicates that all log data has been consumed.
Step 4: Filter logs in Kibana
Log on to the Kibana console of your Elasticsearch cluster.
For instructions, see Log on to the Kibana console.
NoteExamples here use Elasticsearch V6.7.0. Operations may vary slightly for other versions.
-
Create an index pattern.
-
In the left-side navigation pane, click Management.
-
In the Kibana section, click Index patterns.
-
Click Create index pattern.
-
Enter an Index pattern (kafka-* in this topic), and click Next step.
-
Select a Time filter field name (select @timestamp in this topic), and click Create index pattern.
-
-
In the left-side navigation pane, click Discover.
-
From the drop-down list on the left, select the index pattern that you created (kafka-*).
-
In the upper-right corner of the page, select a time range to view the log data collected by Filebeat during that period.
Select the index pattern kafka-*, click the Today button in the upper-right corner to select the time range for the current day. The page displays 714 hits. The logs are concentrated around 14:00 and contain package installation and uninstallation records from
/var/log/yum.log. -
Click Add a filter. In the Add filter panel, set filter conditions to view the matching log data.
For example, set the field to message, the operator to is, enter
javaas the value, and click Save to filter out 4 log records that contain the keyword java.
FAQ
Q: I'm having trouble syncing log data. The pipeline is stuck in the deploying state, and data is not being imported into Elasticsearch. How do I solve this?
A: Check the main logs of the Logstash instance for any errors to determine the cause. For more information, see Query logs. The following table describes common causes and solutions.
|
Cause |
Solution |
|
The Kafka endpoint is incorrect. |
See View endpoints to get the correct endpoint. Then, modify the pipeline configuration to replace the incorrect endpoint. |
|
The Logstash instance and the Kafka instance are not in the same VPC. |
Purchase new instances in the same VPC. Then, modify the existing pipeline configuration. Note
You can access a VPC instance of ApsaraMQ for Kafkaonly from the same VPC. |
|
The specifications of the Kafka or Logstash instance are too low, for example, if you are using a trial instance. |
Upgrade the instance specifications, and then refresh the instance and monitor the progress. For information about how to upgrade a Logstash instance, see Upgrade a cluster. For information about how to upgrade a Kafka instance, see Upgrade instance configurations. |
|
The pipeline configuration includes |
Choose one of the following solutions:
|
For more troubleshooting information, see Troubleshoot Logstash data write issues.