AnimateAnyone: Generate dance videos from images
AnimateAnyone generates videos of a character in motion from a character image and a motion template. It includes three independent models: "AnimateAnyone-detect", "AnimateAnyone-template", and "AnimateAnyone". These models provide capabilities for character image compliance detection, motion template generation, and character video generation.
ImportantThis document applies only to the China (Beijing) region. Use an API key from this region.
Model overview
Introduction
- AnimateAnyone-detect is an image detection model that verifies if an input image meets the requirements for the AnimateAnyone model.
- AnimateAnyone-template is a motion template generation model. It extracts character movements from a video to create a motion template for the AnimateAnyone model.
- AnimateAnyone is a character video generation model that creates a video of a character in motion from a character image and a motion template.
Examples
| Character image | Motion video | Output (image background) | Output (video background) |
|---|---|---|---|
 | |||
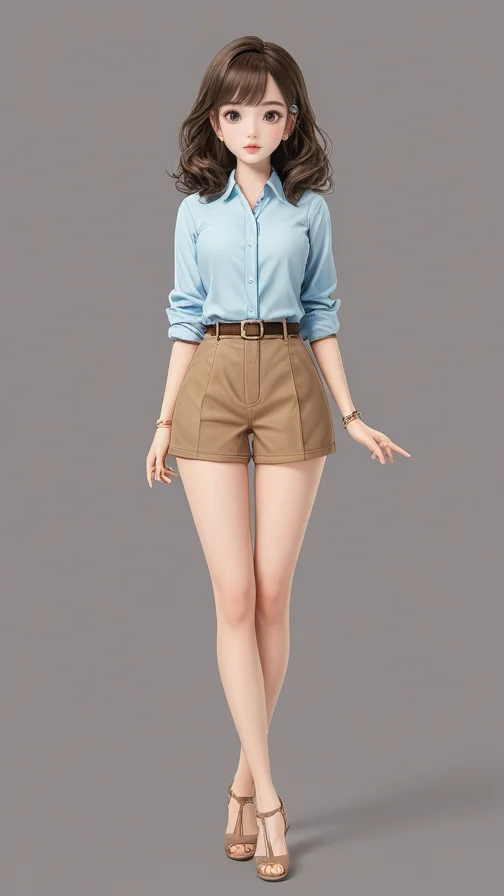 |
Note
- The preceding examples were generated by the Tongyi App, which integrates AnimateAnyone.
- The videos generated by the AnimateAnyone model do not include audio.
Billing and rate limits
Mode | Model name | Unit price | Free quota(View) | Submission QPS limit | Concurrent tasks |
|---|---|---|---|---|---|
Model call | animate-anyone-detect-gen2 | Model call, pay-as-you-go: CNY 0.004/image | 200 images | 5 | No limit for sync API |
animate-anyone-template-gen2 | Model call, pay-as-you-go: CNY 0.08/second | 1,800 seconds | 1 (Only one job runs at a time; others are queued.) | ||
animate-anyone-gen2 | Model call, pay-as-you-go: CNY 0.08/second | 1,800 seconds | |||
Model deployment | animate-anyone-detect | Dedicated deployment, subscription:
Call the model after it is deployed. You are charged only for the deployment. | None | 5 | 1 computing power unit supports a concurrency of 2. |
animate-anyone | 1 computing power unit supports a concurrency of 1. |
Prerequisites
You must have an active service and an API key: Get an API key.
Model calls
-
The AnimateAnyone series of models supports pay-as-you-go calls.
-
To call the models, you must use the correct model name and follow this sequence:
a. Call the "AnimateAnyone-detect" model to validate that the input character image meets the specifications (see AnimateAnyone Image Detection).
b. Call the "AnimateAnyone-template" model and provide a motion video to generate a motion template (see AnimateAnyone Motion Template Generation).
c. Call the "AnimateAnyone" model with the validated character image and the motion template ID to generate a video (see AnimateAnyone Video Generation).
Model deployment and calls
-
The AnimateAnyone series of models also supports dedicated deployment.
-
To deploy the models, go to the Dedicated Deployment page to purchase dedicated instance resources and deploy the "AnimateAnyone-detect-deployment" and "AnimateAnyone-deployment" models separately.
-
After deployment, the model names appear in the Model column of the deployed models list.
-
When calling a deployed model, specify its unique name in the "model" input parameter. Make the calls in the following order:
a. Call the "AnimateAnyone-detect" model to validate that the input character image meets the specifications (see AnimateAnyone Image Detection).
b. Call the "AnimateAnyone" model with the validated character image and a preset motion template file to generate a video (see AnimateAnyone Video Generation).
Note
- "animate-anyone-detect" and "animate-anyone" are aliases for the model capabilities. A model in dedicated deployment is assigned a unique name, such as "animate-anyone-detect-xxx", which you must use for model calls.
- Image detection calls are faster than video generation calls. Based on your workload, you can adjust the deployment ratio between the image detection and video generation models. As a general guideline for queued image processing, one concurrent image detection task supports five concurrent video generation tasks.