Image-to-Singing-and-Acting Video – EMO
EMO generates dynamic portrait videos from a portrait image and human speech audio file. It consists of two models: EMO-detect verifies input image requirements, and EMO generates the video.
ImportantThis document applies only to the China (Beijing) region. Use an API key from this region.
Model overview
About the models
- EMO-detect is an image detection model that verifies whether input images meet EMO's portrait requirements.
- EMO is a portrait video generation model that generates dynamic portrait videos from a portrait image and human speech audio file.
Example outputs
| Input: portrait image + audio file | Output: dynamic portrait video |
|---|---|
Portrait:  Audio: See video on the right | Video: Style intensity: Active ("style_level": "active") |
Portrait:  Audio: See video on the right | Video: Style intensity: Normal ("style_level": "normal") |
Portrait:  Audio: See video on the right | Video: Style intensity: Calm ("style_level": "calm") |
NoteThe examples above were generated by the Qwen app, which integrates EMO.
Pricing and rate limits
Mode | Model name | Unit price | Free quota(View) | QPS limit for job submission | Maximum concurrent jobs |
|---|---|---|---|---|---|
Model call | emo-detect-v1 | Pay-as-you-go: CNY 0.004 per image | 200 images | 5 | No limit for synchronous calls |
emo-v1 | Pay-as-you-go:
| 1,800 seconds | 1 Only one job runs at a time. Other jobs wait in the queue. | ||
Model deployment | emo-detect | On-premises deployment (upfront):
Successful deployment is required to invoke this service. Only deployment fees apply. | None | 5 | One computing unit supports five concurrent requests |
emo | One computing unit supports one concurrent request |
Prerequisites
Enable the service and obtain your API key: Obtain your API key and API host.
Call the models
-
To call the models (pay-as-you-go):
- Call EMO-detect to verify that your input image meets the requirements. See EMO image detection for details.
- Call EMO with the original image, region parameters from EMO-detect, and a clear human speech audio file to generate the video. See EMO video generation for details.
Deploy and call the models
-
EMO models support on-premises deployment.
-
Go to the Model deployment page, purchase dedicated instance resources, and deploy both EMO-detect-deployment and EMO-deployment.
-
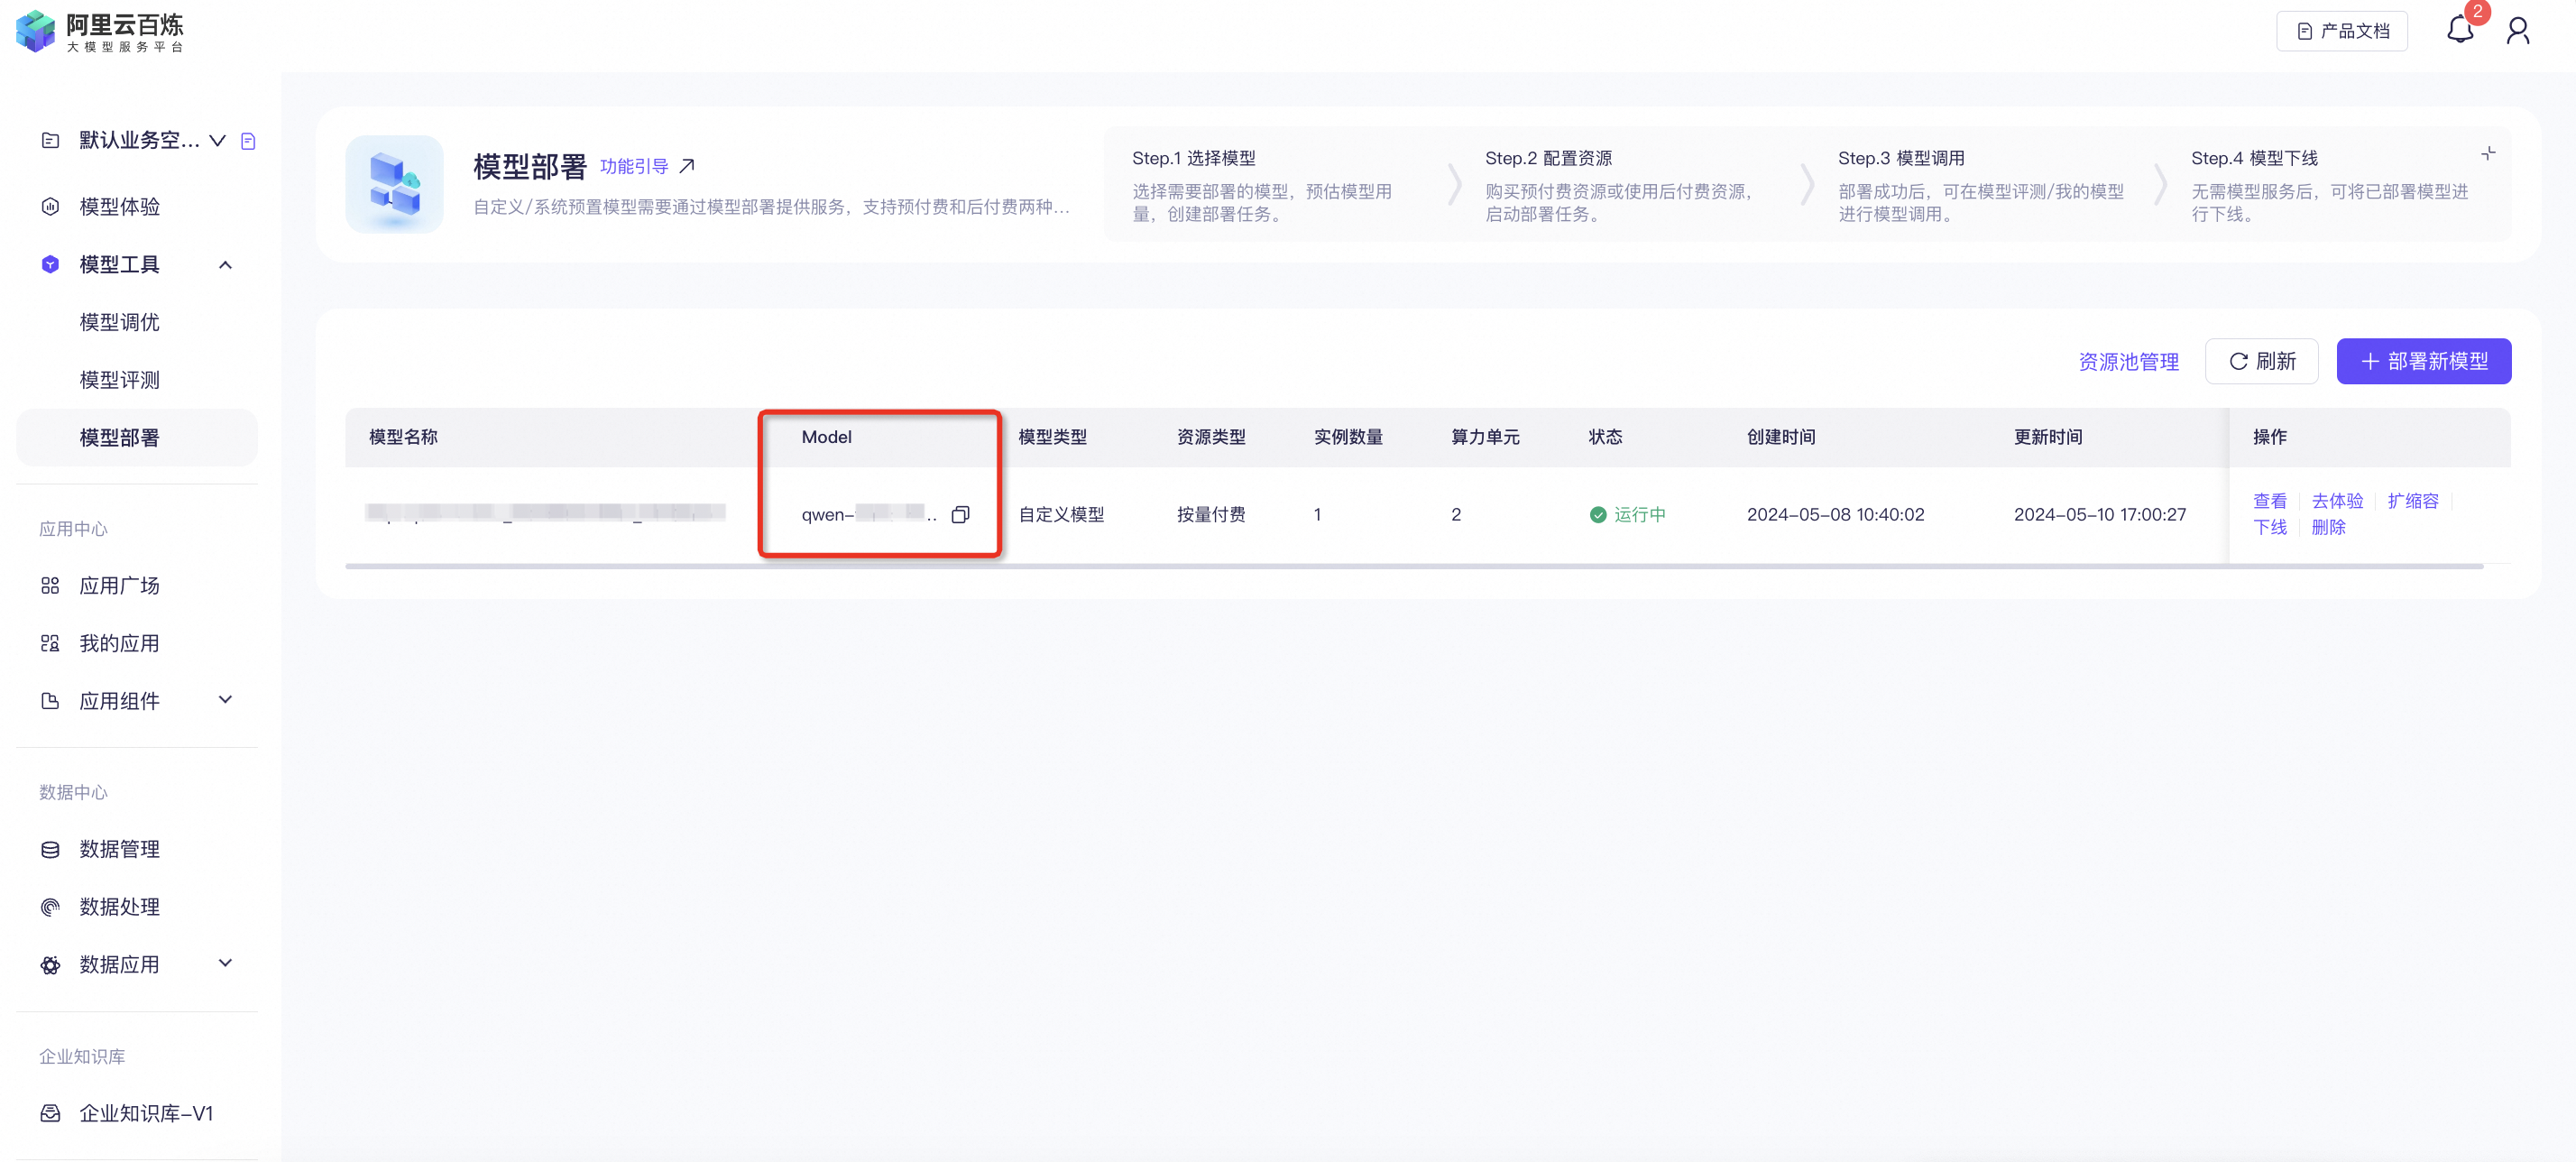
After deployment, view the deployed model names below:
-
Set the model field to the deployed model name, then:
- Call EMO-detect-deployment to verify that your input image meets the requirements. See EMO image detection for details.
- Call EMO-deployment with the original image, region parameters from EMO-detect-deployment, and a clear human speech audio file to generate the video. See EMO video generation for details.
Note
- emo-detect and emo are shorthand names. Deployed models receive unique names (e.g., emo-detect-xxx). Use the full name when calling deployed models.
- Image detection has low latency; video generation has high latency. Adjust the deployment ratio of detection to generation models based on your needs. Typically, one concurrent detection endpoint supports 10+ concurrent generation tasks when images are queued in order.