Introduction to model fine-tuning
You can use model fine-tuning in Alibaba Cloud Model Studio if a model's performance does not meet your expectations after you have tried optimization methods such as prompt engineering and plugin calls. As a core strategy for improving model performance, model fine-tuning can significantly enhance a model's capabilities in specific industries or business scenarios, align its outputs with human preferences, and reduce output latency. Model fine-tuning includes four training methods: supervised fine-tuning (SFT), continual pre-training (CPT), direct preference optimization (DPO), and reinforcement learning (RL).
ImportantThis topic is applicable only to the China (Beijing) region.
Introduction to model fine-tuning
Model fine-tuning is an important method for optimizing model performance. It can:
- Improve model performance in specific industries or for specific business needs
- Reduce model output latency
- Suppress model hallucination
- Align the model with human values or preferences
- Replace larger models with fine-tuned lightweight models
During the fine-tuning process, the model learns business-specific or scenario-specific features from the training data, such as knowledge, tone, expression styles, and self-awareness. Because the model has already learned many examples for specific industries or scenarios during training, its one-shot or zero-shot prompt performance after training is better than its few-shot performance before training. This saves input tokens and reduces model output latency.
Model fine-tuning process

For more information, see:
Supported models
Supported models
Text generation
NoteAfter fine-tuning Qwen3.7-Plus-2026-05-26, contact your account manager for deployment.
Model Service | Model code | CPT Full Parameter Training | SFT Full Parameter Training | SFT Efficient Training | DPO Full Parameter Training | DPO Efficient Training |
|---|---|---|---|---|---|---|
Qwen3.8-27B | qwen3.8-27b | × | ✓ | ✓ | × | × |
Qwen3.7-Plus-2026-05-26 | qwen3.7-plus-2026-05-26 | × | ✓ | × | × | × |
Qwen3.6-27B | qwen3.6-27b | × | ✓ | ✓ | × | × |
Qwen3.6-Flash-2026-04-16 | qwen3.6-flash-2026-04-16 | × | ✓ | × | × | × |
Qwen3.6-Plus-2026-04-02 | qwen3.6-plus-2026-04-02 | ✓ | ✓ | × | × | × |
Qwen3.5-27B | qwen3.5-27b | × | ✓ | ✓ | × | × |
Qwen3.5-9B | qwen3.5-9b | × | ✓ | ✓ | × | × |
Qwen3.5-4B | qwen3.5-4b | × | ✓ | ✓ | × | × |
Qwen3.5-Flash-2026-02-23 | qwen3.5-flash-2026-02-23 | × | ✓ | × | × | × |
Qwen3.5-Plus-2026-02-15 | qwen3.5-plus-2026-02-15 | × | ✓ | × | × | × |
Qwen3-32B | qwen3-32b | ✓ | ✓ | ✓ | ✓ | ✓ |
Qwen3-30B-A3B-Instruct-2507 | qwen3-30b-a3b-instruct-2507 | ✓ | ✓ | ✓ | × | × |
Qwen3-14B | qwen3-14b | × | ✓ | ✓ | ✓ | ✓ |
Qwen3-8B | qwen3-8b | × | ✓ | ✓ | ✓ | ✓ |
Qwen3-4B-Instruct-2507 | qwen3-4b-instruct-2507 | ✓ | ✓ | ✓ | ✓ | ✓ |
Qwen3-1.7B | qwen3-1.7b | ✓ | ✓ | ✓ | ✓ | ✓ |
Qwen3-0.6B | qwen3-0.6b | ✓ | ✓ | ✓ | ✓ | ✓ |
Qwen2.5-72B-Instruct | qwen2.5-72b-instruct | ✓ | ✓ | ✓ | ✓ | ✓ |
Qwen2.5-32B-Instruct | qwen2.5-32b-instruct | ✓ | ✓ | ✓ | ✓ | ✓ |
Qwen2.5-14B-Instruct | qwen2.5-14b-instruct | ✓ | ✓ | ✓ | ✓ | ✓ |
Qwen2.5-7B-Instruct | qwen2.5-7b-instruct | ✓ | ✓ | ✓ | ✓ | ✓ |
Qwen-Plus-Character-2025-11-06 | qwen-plus-character-2025-11-06 | × | ✓ | ✓ | ✓ | ✓ |
NoteThe decision model (decision-model-preview-2026-09-24) does not participate in the standard CPT/SFT/DPO training above, but supports a dedicated fine-tuning workflow; for the fine-tuning method, see Decision model fine-tuning best practices.
Visual understanding (Qwen-VL)
Model Service | Model code | CPT Full Parameter Training | SFT Full Parameter Training | SFT Efficient Training | DPO Full Parameter Training | DPO Efficient Training |
|---|---|---|---|---|---|---|
Qwen3-VL-8B-Instruct | qwen3-vl-8b-instruct | × | ✓ | ✓ | × | × |
Qwen3-VL-8B-Thinking | qwen3-vl-8b-thinking | × | ✓ | ✓ | × | × |
Qwen3-VL-4B-Instruct | qwen3-vl-4b-instruct | × | ✓ | ✓ | × | × |
Qwen2.5-VL-72B-Instruct | qwen2.5-vl-72b-instruct | × | ✓ | ✓ | × | × |
Qwen2.5-VL-32B-Instruct | qwen2.5-vl-32b-instruct | × | ✓ | ✓ | × | × |
Qwen2.5-VL-7B-Instruct | qwen2.5-vl-7b-instruct | × | ✓ | ✓ | × | × |
Comparison of tuning methods
Feature | CPT (Continual Pre-training) | SFT (Supervised Fine-tuning) | DPO (Direct Preference Optimization) |
|---|---|---|---|
Summary | Supplements knowledge (Injects domain knowledge) | Learns to perform tasks (Follows instructions) | Performs tasks better (Aligns with human preferences) |
Input data | 10 million+ tokens Unlabeled domain text | Over 1,000 entries High-quality "question-answer" pairs | 100+ sets "Better-worse" response pairs for the same instruction |
Core objective | Domain adaptation. Learns specialized vocabulary and facts. | Teaches the model conversation formats and task execution capabilities. | Makes model outputs better align with human values and preferences. |
Learning method | Self-supervised learning (Predicts the next word) | Supervised learning (Imitates the ground truth) | Direct preference learning (Increases the probability of good responses and decreases the probability of bad responses) |
Model stage | Typically before SFT | After CPT and before DPO | Typically after SFT, as the final step for alignment. |
In addition to the three methods above, Model Studio also supports RL (Reinforcement Learning) training. RL continuously optimizes model behavior through reward signals, suitable for scenarios that require continuous improvement through human feedback or automated scoring. In the console, the training method column offers "RL - Full-parameter Training". For the complete RL training workflow and configuration details, see Reinforcement Learning.
Comparison of training patterns
Full-parameter training | Efficient training (LoRA, recommended) | |
|---|---|---|
Scenarios | • The model needs to acquire new capabilities • Achieving optimal global performance. | • Optimizing model performance for specific scenarios. • For cost-sensitive and time-sensitive scenarios. |
Training time | Longer, with slower convergence. | Shorter, with faster convergence. |
Billing
| Billing method | The console supports three billing methods: Token-based billing (billed by the number of tokens actually consumed during training), Training Unit (Prepaid) (pre-purchase training units, billed by unit deduction), and Training Unit (Postpaid) (billed by actual usage on a postpaid basis). Training jobs created via API only support Token-based billing. |
| Billing formula | Model training fee = (Total tokens in training data + Total tokens in mixed training data) × Number of epochs × Training unit price (Minimum billing unit: 1 token)
|
Click here to view more usage limits for Qwen-VL models
Usage limits
Input file limits
Image limits
-
Image resolution:
-
Minimum size: The width and height of the image must both be greater than
10pixels. -
Aspect ratio: For both the original and scaled images, the ratio of the long side to the short side must not exceed
200:1.For the image scaling logic, see the
smart_resizefunction in Calculate tokens for images and videos. -
Pixel limits:
- We recommend keeping the image resolution within
8K(7680x4320). Images above this resolution may cause API call timeouts due to excessive file size or long network transmission time. - Automatic scaling mechanism: The model can adjust the image size through
max_pixelsandmin_pixels. Therefore, providing ultra-high-resolution images does not improve recognition accuracy, but increases the risk of call failures. We recommend scaling images to a reasonable size on the client in advance.
- We recommend keeping the image resolution within
-
-
Supported image formats
-
For resolutions below 4K
(3840x2160), the following image formats are supported:Image format
Common extensions
MIME Type
BMP
.bmp
image/bmp
JPEG
.jpe, .jpeg, .jpg
image/jpeg
PNG
.png
image/png
TIFF
.tif, .tiff
image/tiff
WEBP
.webp
image/webp
HEIC
.heic
image/heic
-
For resolutions between
4K(3840x2160)and8K(7680x4320), only the JPEG, JPG, and PNG formats are supported
-
-
Image size:
- When passed via public URL: For the Qwen3.8, Qwen3.7, Qwen3.6, Qwen3.5, and Qwen3-VL series, a single image must not exceed
20MB. For other models, a single image must not exceed10MB. - When passed via local path: A single image must not exceed
10MB. - When passed as Base64-encoded data (OpenAI-compatible interface or DashScope): For the Qwen3.8, Qwen3.7, Qwen3.6, Qwen3.5, and Qwen3-VL series, the original image file before encoding must not exceed
20MB. For other models, it must not exceed10MB. In addition, the encoded Data URI string must not exceed20MB. - When passed as Base64-encoded data (Anthropic-compatible interface): Subject to the limit that the entire request body must not exceed
6MB, multiple images must share this quota.
The preceding limits depend on the selected model and cannot be increased by purchasing premium plans or upgrading the model version.
For information about compressing files, see How to compress an image or video to meet the size requirements.
- When passed via public URL: For the Qwen3.8, Qwen3.7, Qwen3.6, Qwen3.5, and Qwen3-VL series, a single image must not exceed
-
Image quantity limits: When multiple images are input, the maximum number of supported images varies by input method:
-
When passed via public URL or local path:
- Qwen3.8-Max, Qwen3.7-Plus: up to 2048 images
- Qwen3.7-Flash, Qwen3.6-Plus, Qwen3.6-Flash, Qwen3.5-Plus, Qwen3.5-Flash, Qwen3-VL, Qwen-VL, and QVQ series: up to 256 images
-
When passed as Base64-encoded data: up to 250 images
For Qwen-Omni series models, see Omni-modal.
-
Subject to the model's total image-text token limit (that is, the maximum input), the total token count of all images must be less than the model's maximum input.
Video limits
-
When passed as an image list, the number of images in the list is subject to the following limits:
qwen3.8series,qwen3.7series,qwen3.6series, andqwen3.5series: a minimum of 4 images and a maximum of 8000 imagesqwen3-vl-plusseries,qwen3-vl-flashseries,qwen3-vl-235b-a22b-thinking, andqwen3-vl-235b-a22b-instruct: a minimum of 4 images and a maximum of 2000 images- Other
Qwen3-VLopen-source models,Qwen2.5-VL(including both commercial and open-source versions), andQVQseries models: a minimum of 4 images and a maximum of 512 images - Other models: a minimum of 4 images and a maximum of 80 images
-
When passed as a video file:
-
Video size:
-
When passed via public URL:
qwen3.8series,qwen3.7series,qwen3.6series,qwen3.5series,Qwen3-VLseries, andqwen-vl-max: no more than 2GB;qwen-vl-plusseries, otherqwen-vl-maxmodels,Qwen2.5-VLopen-source series, andQVQseries models: no more than 1GB;- Other models: no more than 150MB
-
When passed as Base64-encoded data: the encoded string must be smaller than 10MB;
-
When passed via local file path: the video itself must not exceed 100MB.
For information about compressing files, see How to compress an image or video to meet the size requirements.
-
-
Video duration:
qwen3.8series,qwen3.7series,qwen3.6series, andqwen3.5series: 2 seconds to 2 hours;qwen3-vl-plusseries,qwen3-vl-flashseries,qwen3-vl-235b-a22b-thinking, andqwen3-vl-235b-a22b-instruct: 2 seconds to 1 hour;- Other
Qwen3-VLopen-source series andqwen-vl-max: 2 seconds to 20 minutes; qwen-vl-plusseries, otherqwen-vl-maxmodels,Qwen2.5-VLopen-source series, andQVQseries models: 2 seconds to 10 minutes;- Other models: 2 seconds to 40 seconds.
-
Video format: MP4, AVI, MKV, MOV, FLV, WMV, etc.
-
Video dimensions: No specific limit. The model automatically adjusts the video dimensions through
max_pixelsandmin_pixels, and larger video files do not provide better understanding results. -
Video quantity limit: Up to 64 videos can be passed.
-
Audio understanding: Understanding the audio in video files is not supported.
-
Video size:
File input methods
-
Public URL: Provide a publicly accessible file address that supports the HTTP or HTTPS protocol. For optimal stability and performance, you can upload files to OSS or upload files to obtain a temporary URL to obtain a public URL. Model Studio cannot access OSS internal addresses (endpoints containing
-internal, such ashttps://<bucket>.oss-cn-hangzhou-internal.aliyuncs.com/image.jpg). Passing an internal address causes file download failure, returningInvalidParameterwith the messageFailed to download multimodal content. Use an OSS public domain (such ashttps://<bucket>.oss-cn-hangzhou.aliyuncs.com/image.jpg) or an OSS temporarily signed URL to pass files instead.ImportantTo ensure that the model can successfully download the file, the response headers of the provided public URL must contain Content-Length (file size) and Content-Type (media type, such as image/jpeg). A missing or incorrect field causes file download failure.
-
Base64 encoding: Convert the file into a Base64-encoded string and then pass it.
-
Local file path (DashScope SDK only): Pass the path of a local file.
For advice on file input methods, see How do I choose a file upload method?
Console task list
On the Model Fine-tuning page, you can view all training jobs. The list displays the following columns: job name/ID, priority, base model, training method, training status, billing method, output, job duration, and creation time.
Priority has four levels: L0, L1, L2, and L3, listed from highest to lowest, affecting the scheduling order of training jobs. Higher priority means earlier scheduling.
Billing method supports three options: Token-based billing, Training Unit (Prepaid), and Training Unit (Postpaid) (see the billing section below for details).
The top-right corner provides Training Cost Records, Resource Pool Management (Prepaid), Create Training Task, and Reset buttons. The list supports filtering by priority. Each row's operation column provides Details, Stop, Logs, and Delete buttons, with availability depending on the job status.
Before you fine-tune a model
-
Although text generation model fine-tuning can achieve excellent results in specific business scenarios, it has the following limitations:
- Time-consuming: This includes creating a large-scale CPT dataset (at least 50 million tokens), building an effective SFT dataset (1,000+ entries), collecting enough bad cases (100+) to build an effective DPO dataset, and the slow speed of model optimization iterations.
- High cost: A fine-tuned model can only be used after deployment, and the model deployment billing is high.
-
Alibaba Cloud Model Studio recommends that you first try using Prompt Engineering (Prompt Engineering) orFunction Calling(Function Calling) to customize your application. Model fine-tuning is usually the "last resort" for improving model performance. This is because:
- In many tasks, a model may initially perform poorly, but applying the correct prompt techniques can improve the results without requiring model fine-tuning.
- Iteratively optimizing prompts and plugins is more agile and cost-effective than model fine-tuning iterations, because fine-tuning may require re-collecting, cleaning, and optimizing data, collecting bad cases, and conducting customer surveys.
- Even if you ultimately decide to perform model fine-tuning, the initial work on prompt engineering and plugin optimization will not be wasted. This preliminary work can be fully reused when building the fine-tuning dataset.
Fine-tuning performance examples
-

-
Comparison of model performance on object detection tasks before and after fine-tuning. For more information, see the fine-tuning performance benchmark of each model.
Getting started
Fine-tune a model using the console
-
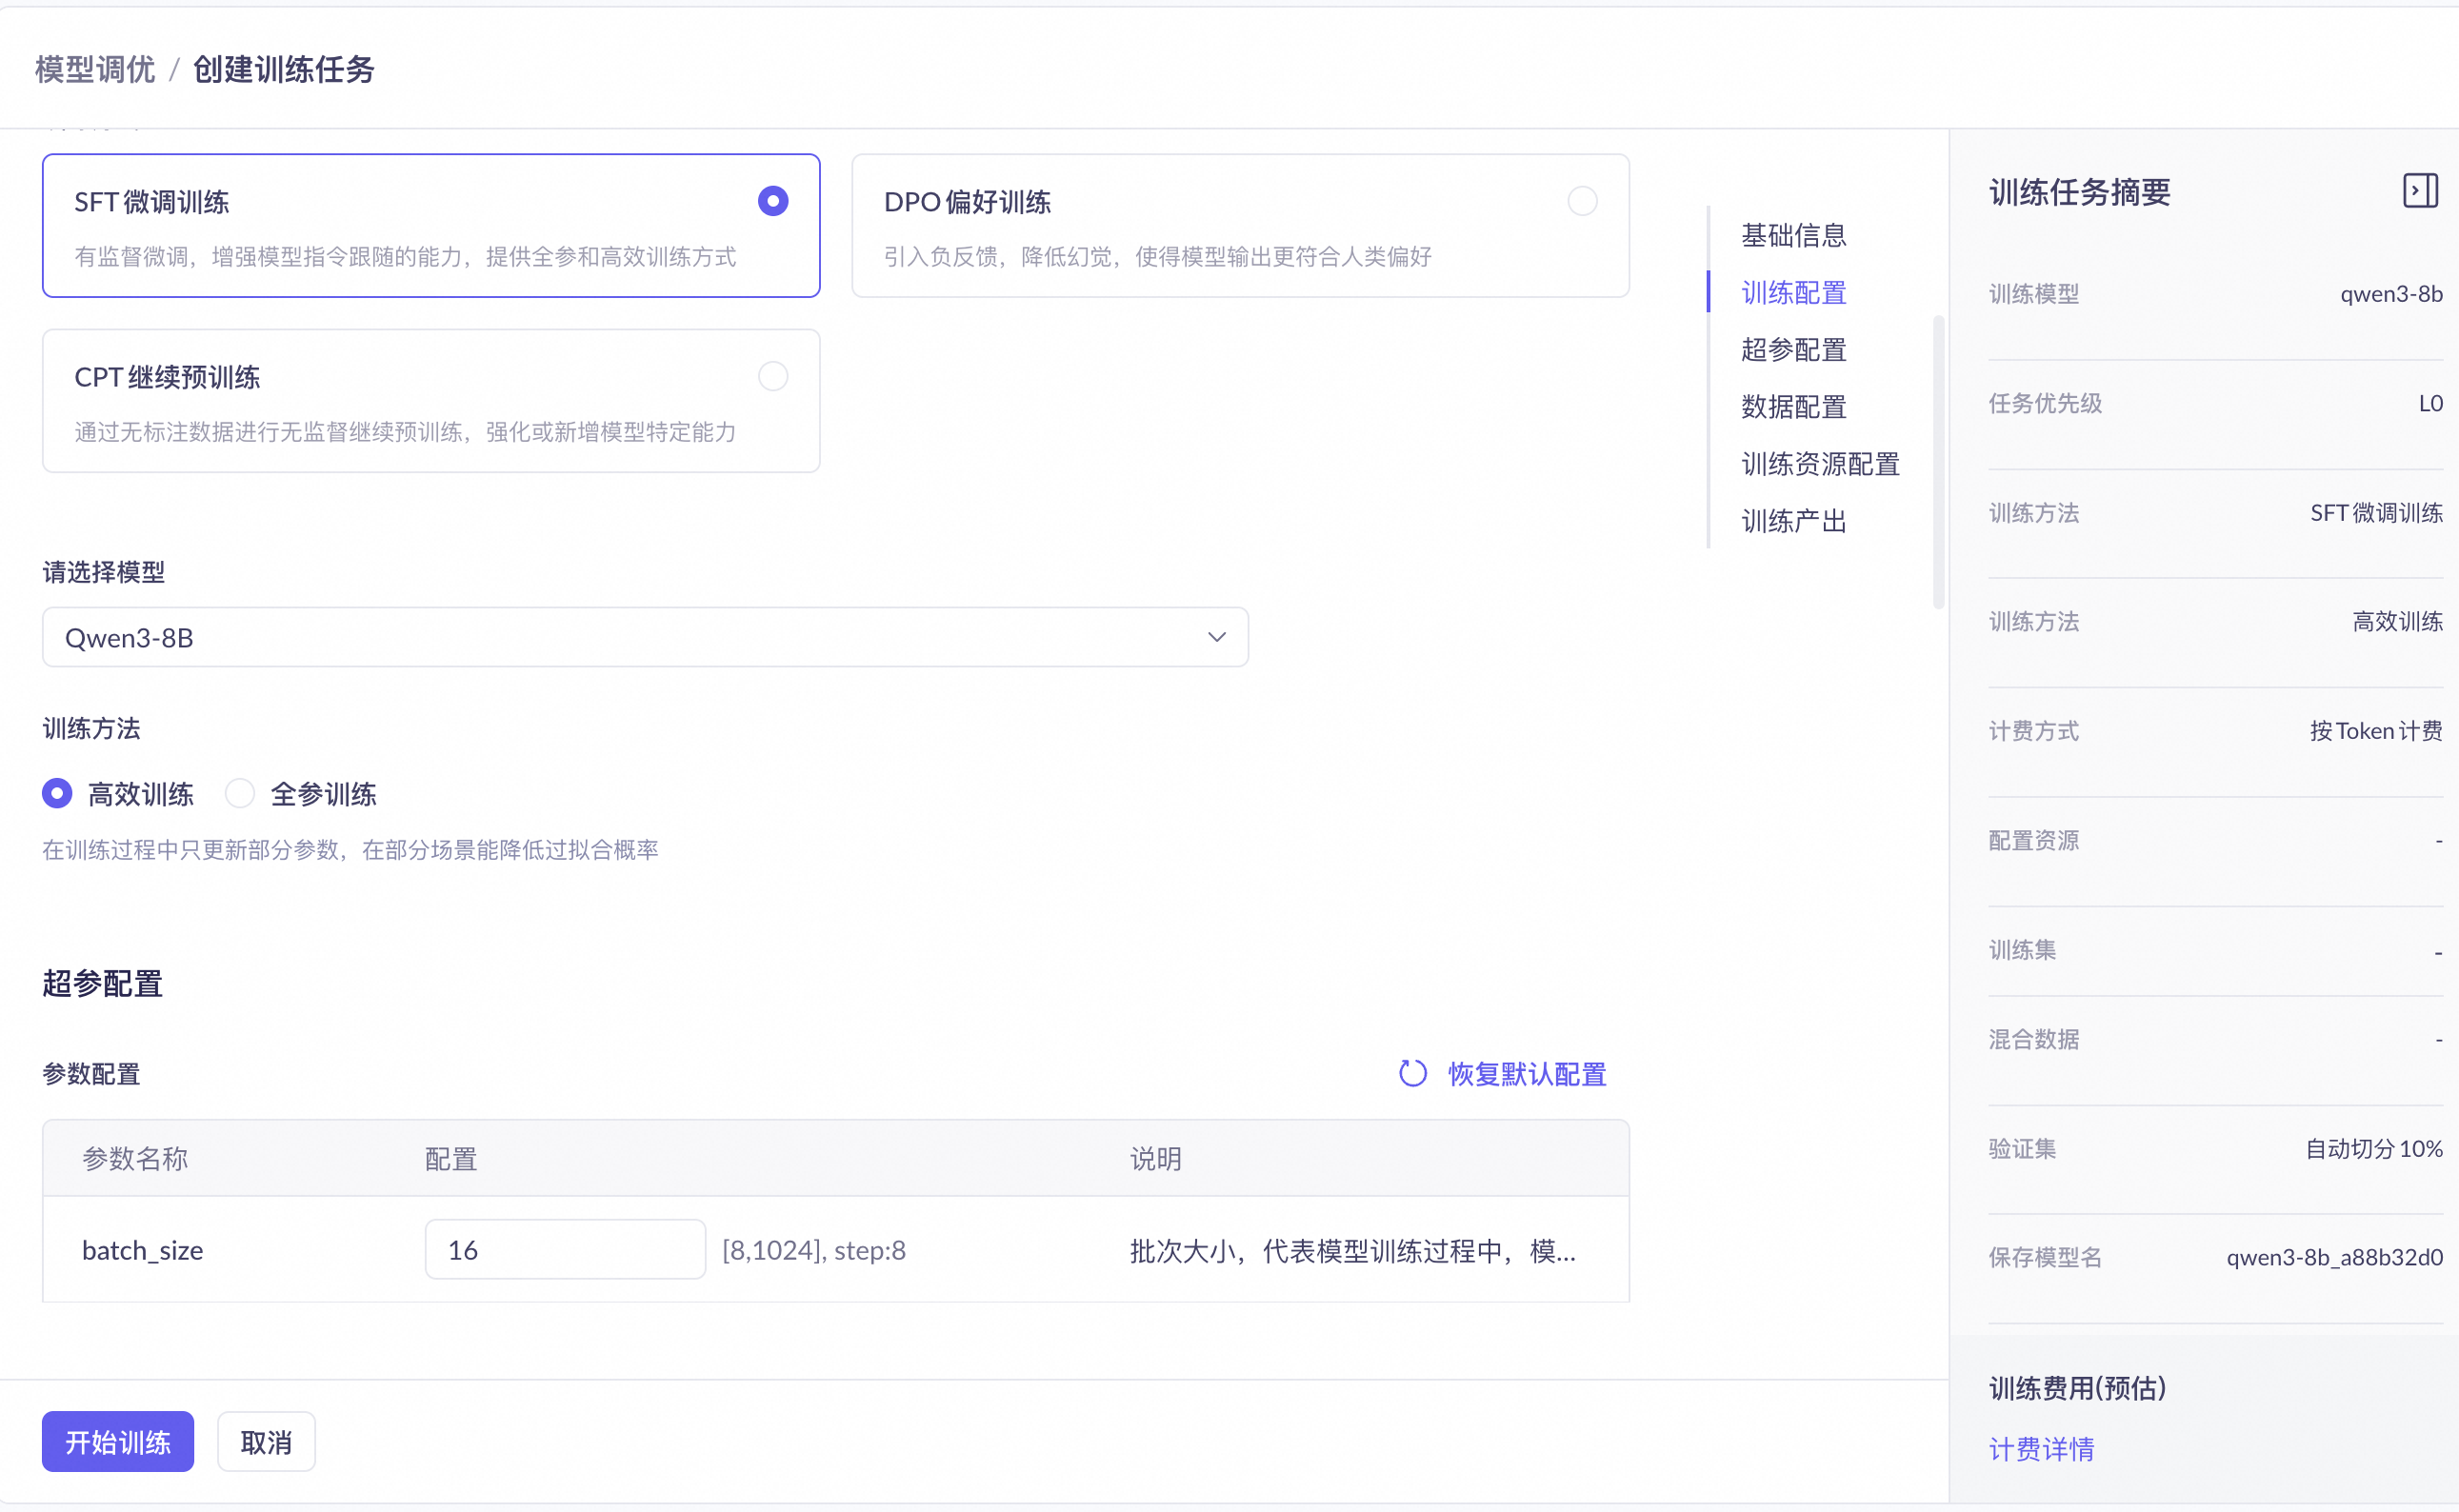
Log on to the Model Studio console. In the left-side navigation pane, choose Model Training > Model Fine-tuning, and then click Create Training Task.
-
In the Training Configuration section, complete the following settings:
- Training Method: Select Supervised Fine-tuning (SFT).
- Select a Model: Select Qwen3-8B.
- Training Method: Select Efficient Training.
This combination requires a short training time and few data records.
-
In the Hyperparameter Settings section, keep the default Parameter Configurations. Model Studio provides recommended configurations for fine-tuning hyperparameters.
-
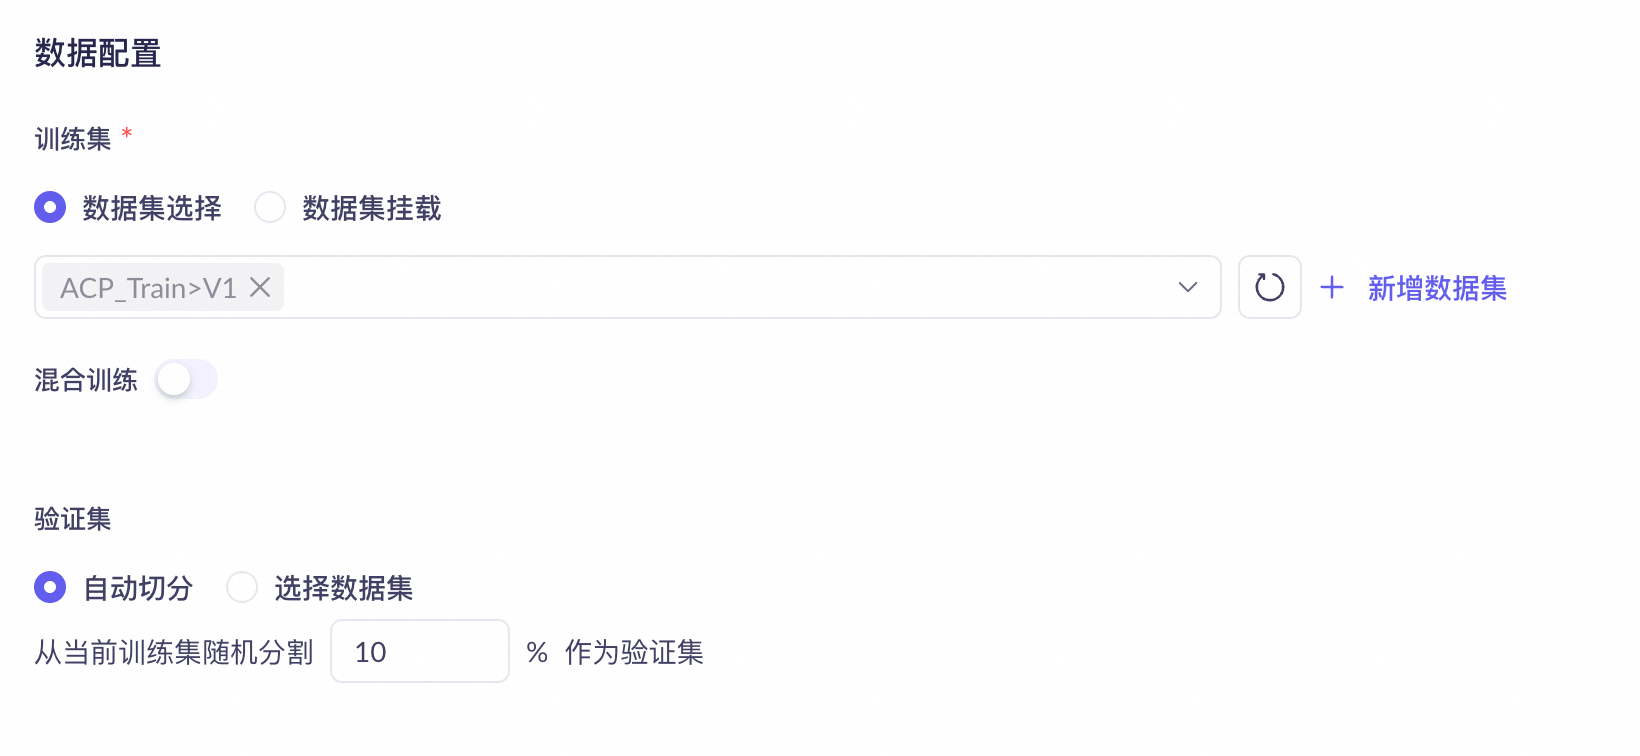
In the Data Configuration section, complete the following settings:
- Training Set: Select an uploaded fine-tuning dataset. Data sample: SFT-ChatML_format_example.jsonl.
- Mixed Training: Keep it disabled.
- Validation Set: Select Automatic Split to split 10% of the training set as the validation set.
-
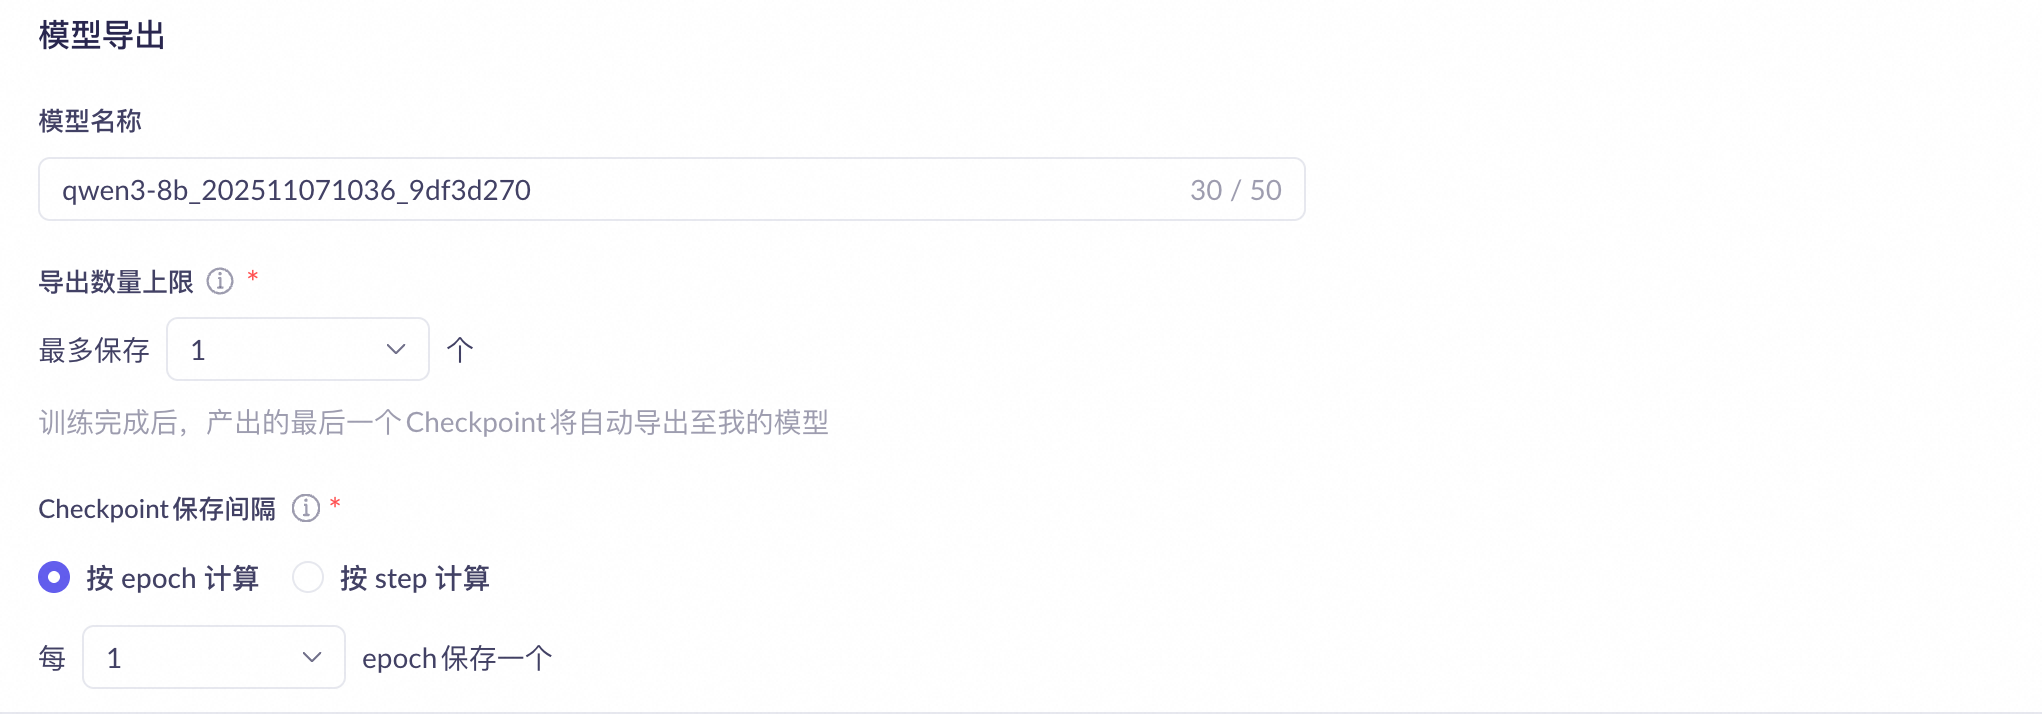
In the Training Output section, configure how model parameter snapshots (checkpoints) are saved. Keep the default values for the following settings:
- Model Name: After the training is complete, the last checkpoint is automatically published to My Models under this name.
- Up to: Sets the number of models that the training task finally exports.
- Checkpoint save interval: You can select Calculated by epoch or Calculated by step.
NoteAfter fine-tuning is complete, you must export a parameter snapshot before you can deploy the model on Model Studio based on that snapshot. Exported parameter snapshots are saved in cloud storage and cannot be accessed or downloaded.
-
Click Start Training and wait for the model training to complete.
-
Choose Model Inference > Dedicated Deployment to deploy the trained custom model. After the deployment is complete, you can evaluate the fine-tuned model. For more information, see Dedicated Deployment Overview.
-
Choose Model Training > Model Evaluation to evaluate the training performance of the custom model. For more information, see Model evaluation.
Typical fine-tuning process
The three fine-tuning methods provided by Model Studio are not mutually exclusive but are progressive and complementary.
CPT (optional) → SFT → DPO (optional)
-
CPT (continual pre-training) - Supplements knowledge (General models have broad but shallow knowledge, which may not meet the depth and precision requirements of professional fields)
- Finance model:
Learns financial terms - Medical model:
Memorizes drug pathology - Legal model:
Understands legal articles and precedents
- Finance model:
-
SFT (supervised fine-tuning) - Learns how to perform tasks
- Customer service bot:
Learns customer service procedures - Code assistant:
Learns programming paradigms - Tool calling (Agent):
Learns to use MCP
- Customer service bot:
-
DPO (direct preference optimization) - Performs tasks better
- Safety and responsibility:
Rejects harmful suggestions - Conciseness and effectiveness:
Provides concise answers - Objectivity and neutrality:
Evaluates fairly and objectively
- Safety and responsibility:
Fine-tuning data format
For data format specifications, packing rules, size and quantity limits, and API upload quotas for each training method (SFT/DPO/CPT), see Fine-tuning data upload rules. The following is an overview of the file formats supported by each training method:
Training method | File format |
|---|---|
SFT text generation | jsonl (ChatML messages multi-turn structure) |
SFT multimodal (image/video) | zip (data.jsonl + image/video files) |
DPO | jsonl (chosen/rejected preference comparison) |
CPT | jsonl (plain text {text}) |
Evaluation set | xlsx (prompt&completion) / jsonl, xls, xlsx (ChatML-messages) |
Dataset building tips
Dataset size requirements
For CPT, the dataset requires at least 50 million tokens of high-quality pre-training data. For SFT, the dataset requires at least 1,000 high-quality fine-tuning data entries. For DPO, the dataset generally requires hundreds of human preference data entries. If the model evaluation results after data fine-tuning are not satisfactory, the simplest way to improve is to collect more data for training.
If you lack data, we recommend building an agent application and using a knowledge base index to enhance the model's capabilities. In many complex business scenarios, you can also use a combination of model fine-tuning and knowledge base retrieval.
For example, in a customer service scenario, you can use model fine-tuning to address issues with the customer service agent's tone, expression styles, and self-awareness. Professional knowledge related to the scenario can be dynamically introduced into the model's context using a knowledge base.
Alibaba Cloud Model Studio recommends that you first build and test a retrieval-augmented generation (RAG) application. After collecting enough application data, you can then use model fine-tuning to further improve the model's performance.
You can also use the following strategies to expand your dataset:
- Use a large language model (LLM) to simulate the generation of content for specific business scenarios to help you generate more data for fine-tuning. (We recommend selecting a larger, high-performing model for generation.)
- Use the data processing feature of Alibaba Cloud Model Studio to perform data cleaning and data augmentation on your dataset.
- Acquire more data through various methods, such as collecting from application scenarios, web scraping, social media and online forums, public datasets, partners and industry resources, and user contributions.
Data diversity and balance
The requirements for model fine-tuning vary by scenario. For example, professionalism is critical for specific business scenarios, whereas versatility is more important for Q&A scenarios. You need to design data use cases based on the business modules or usage scenarios the model is responsible for. Therefore, the training effectiveness depends not only on the data volume but also on the professionalism and diversity of the data for the specific scenario.
For example, in an intelligent AI conversation scenario, a professional and diverse dataset should include the following business scenarios:
Specific business | Diverse scenarios/businesses |
|---|---|
E-commerce customer service | Promotion pushes, pre-sales consultation, in-sales guidance, after-sales service, after-sales follow-up, complaint handling, etc. |
Financial services | Loan consultation, investment and wealth management advice, credit card services, bank account management, etc. |
Online healthcare | Symptom consultation, appointment registration, visit instructions, drug information inquiry, health tips, etc. |
AI secretary | IT information, administrative information, HR information, employee benefit inquiries, company calendar queries, etc. |
Travel assistant | Travel planning, entry and exit guides, travel insurance consultation, destination customs and culture introductions, etc. |
Corporate legal counsel | Contract review, intellectual property protection, compliance checks, labor law Q&A, cross-border transaction consultation, individual case legal analysis, etc. |
It is also important to note that the amount of data for each scenario/business should be relatively balanced, and the data proportion should match the actual scenario proportion. This avoids having too much data of one type, which could cause the model to be biased towards learning those features and affect its generalization ability.
Splitting the training and validation sets
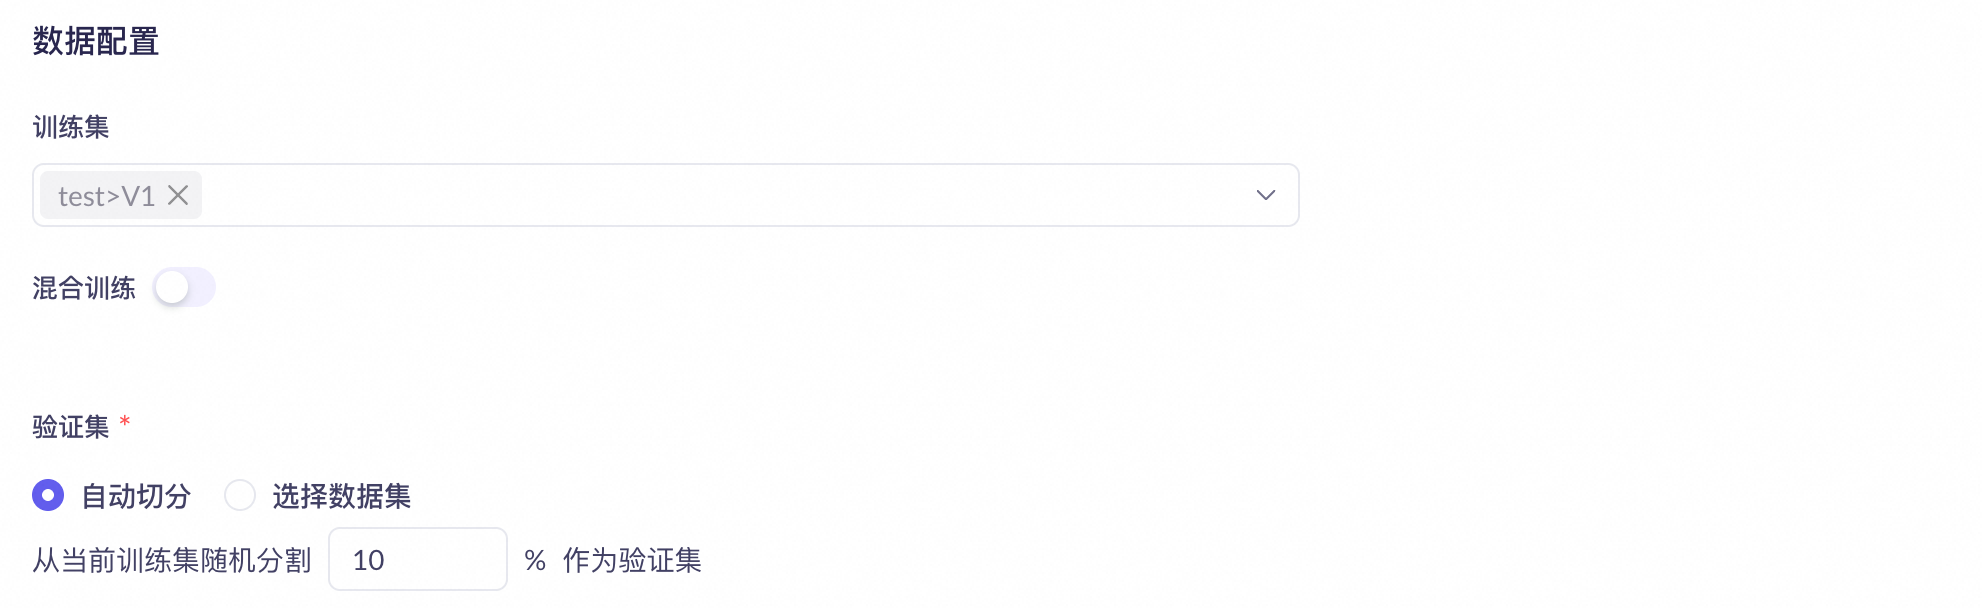
When you use the console to fine-tune a model, you can:
- Automatically split a complete training dataset and randomly sample a small amount of data to form a validation set.
- Choose to upload a separate dataset.
The console can conveniently display the validation set loss and Token Accuracy in real time during training.
FAQ
Can I fine-tune my own model?
Model Studio does not support fine-tuning your own models. However, you can import open source Qwen series models in safetensor format using My Models (Beijing region). For more information, see Model import. After a model is imported, you can deploy and use it on the Model Studio platform.