Build conversational search with OpenSearch Vector Search Edition and an LLM
Background
Generative AI has shown remarkable capabilities with general tasks. However, when applied to specialized business domains, it often fails to provide precise answers due to a lack of domain-specific knowledge. To build a reliable enterprise Q&A system, you must ground the AI model in your private data to ensure the generated content is accurate and controllable.
OpenSearch is a one-stop intelligent search platform that includes a high-performance vector search engine. By combining vector search with an LLM, you can build a robust and intelligent Q&A solution for your specific business domain and quickly deploy it in production.
This topic explains how to use OpenSearch Vector Search Edition with an LLM to quickly build an intelligent Q&A system.
-
This document applies only to legacy instances of Vector Search Edition, which have engine version numbers starting with
ha3, such asha3_3.10.0. These instances are no longer available for purchase.You can identify your instance type by checking the Current Engine Version field on the Basic Information page of your instance.
-
Currently available instances are an enhanced version of Vector Search Edition with engine version numbers starting with
vector_service, such asvector_service_1.4.2. For the conversational search solution that supports these instances, see Build a conversational search system with the enhanced Vector Search Edition and an LLM.
Enterprise-specific model solution
1. How it works
The OpenSearch and LLM solution follows the Retrieval-Augmented Generation (RAG) pattern. It consists of two main stages: offline data preprocessing and online search and generation.
1.1. Data preprocessing (offline)
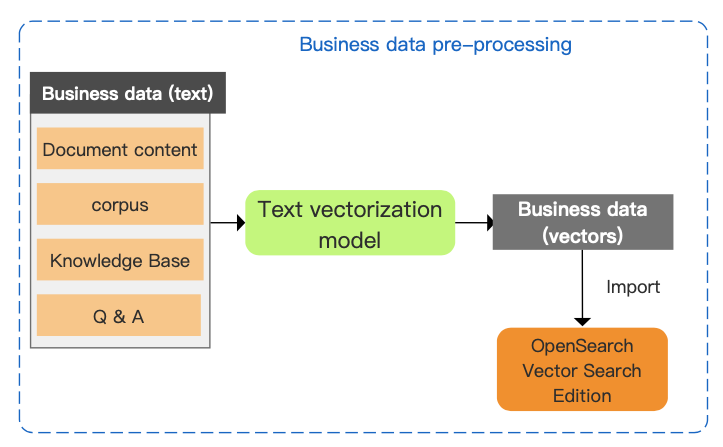
First, you process your business data into vectors to build a vector index.
Step 1: Convert your text-based business data into vector embeddings using a text embedding model.
Step 2: Ingest the vector embeddings into OpenSearch Vector Search Edition to build a vector index.
1.2. Search and generation (online)
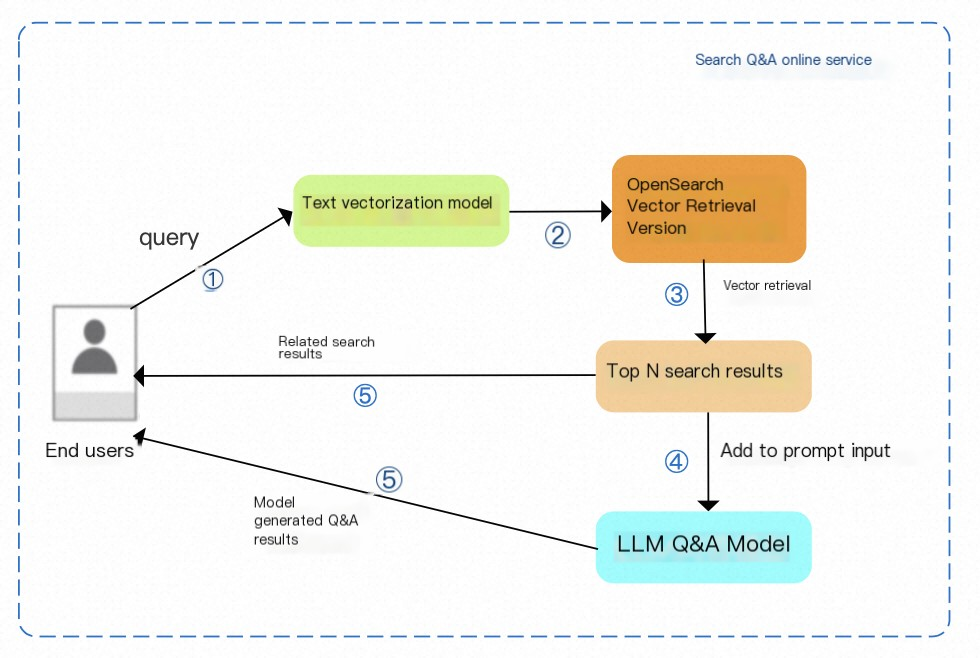
After you set up the search service, the system retrieves relevant information and uses an LLM to generate an answer.
Step 1: Convert the user's query into a vector embedding using the same text embedding model.
Step 2: Send the query vector to OpenSearch Vector Search Edition.
Step 3: The OpenSearch vector search engine retrieves the top-N most relevant results from your business data.
Step 4: Combine the retrieved results into a prompt and send it to the LLM.
Step 5: The LLM generates a final answer, which is returned to the user along with the search results.
2. Benefits
Benefit 1: High performance with a proprietary vector search engine
-
OpenSearch Vector Search Edition delivers millisecond-level responses for hundred billion-scale data, with real-time data updates appearing within seconds.
-
Its retrieval performance is several times higher than that of open source vector search engines, and it achieves a significantly higher recall rate in high QPS scenarios.
Performance comparison: OpenSearch Vector Search Edition vs. open source engine (medium dataset)
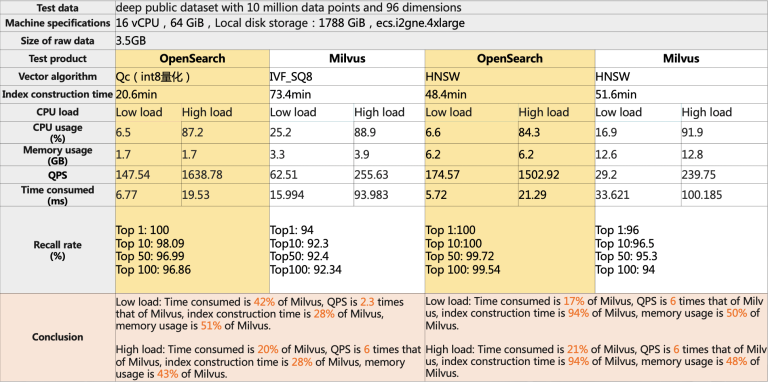
Source: Alibaba Intelligent Engine Business Unit team, November 2022.
Performance comparison: OpenSearch Vector Search Edition vs. open source engine (large dataset)
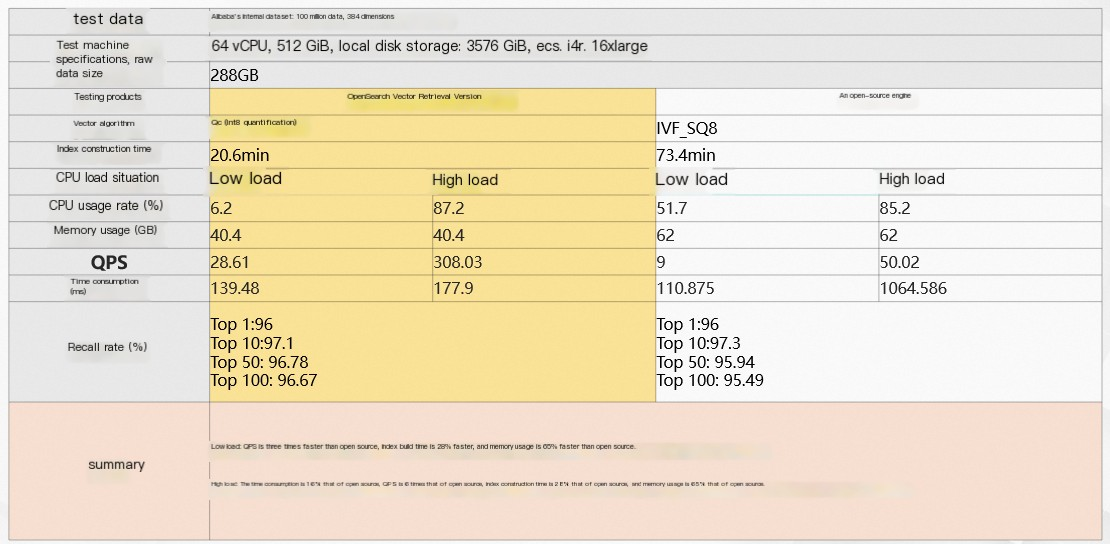
Source: Alibaba Intelligent Engine Business Unit team, November 2022.
Benefit 2: Low cost with multiple optimization methods
-
Data compression: Raw data can be converted to float format for storage and compressed using efficient algorithms like zstd to optimize storage costs.
-
Fine-grained index schema design: Apply different optimization strategies for various index types to reduce index size.
-
Partial index loading: You can load an index using a non-locking mmap method to reduce memory overhead.
-
Engine advantages: The OpenSearch Vector Search Edition engine is optimized for index size and GPU resource consumption. For the same amount of data, it uses only about 50% of the memory required by open source vector search engines.
Benefit 3: Flexible and fast implementation
-
Reliable and stable: The system generates content based on your private business data instead of public data, producing more reliable and stable results.
-
Upgraded interaction: Replaces traditional search with a conversational interface to meet user needs for both search and Q&A.
Procedure
1. Purchase a Vector Search Edition instance
To create an OpenSearch Vector Search Edition instance, see Quick Start for General-purpose Edition. Remember the username and password you set during the purchase, as you will need them later.
2. Configure the instance
A newly purchased instance has the "Pending Configuration" status. An empty cluster is automatically deployed with the number and specifications of query and data nodes that you purchased. Before you can perform searches, you must configure a data source, define an index schema, and perform an index rebuild.
On the Instance Management page, find your target instance and click Configure in the Actions column.
2.1 Configure an API push data source.
On the Data Source Configuration page, select API push data source for Data Source Type and set a Data Source Name, such as ha-cn-wwo38nf8q01_data. The Incremental swift topic under API Push Configuration is automatically generated.
After the data source is configured, click Next to configure the index schema.
2.2 Add an index table.
On the Index Schema configuration page, click Add an index table.
2.3 Select the data source you just created, configure the index table, and select the general-purpose template.
Set the Index Table name to llm, select the previously created data source, set Number of Data Shards to 1, and select Administrator Mode for Editing Method.
2.4 Define fields. You must define at least a primary key field and a vector field. The vector field must be of the multi-value FLOAT type.
In Field Settings, configure the following five fields: pk (STRING type, set as the primary key), embedding (FLOAT type, multi-value enabled, separator: ^]), content (STRING type), source_id (STRING type), and url (STRING type). For all fields, select Attribute Field and Display in Search Results. For Data Compression, select No Compression.
Note: You must configure the field names and types exactly as shown. Otherwise, data cannot be pushed automatically.
2.5 Configure indexes. Set the index type of the primary key field to PRIMARYKEY64. For the vector index, select CUSTOMIZED.
Note: The vector index name must be embedding_index.
Add included fields to the vector index.
Set the Index Name to embedding_index. In the Included Fields section, select pk for the Primary Key Field and embedding for the Vector Field.
2.6 Configure advanced vector index settings. You can use the following parameters as a reference. For more information, see Vector indexes.
Configure the parameters as follows: set distance_type to SquaredEuclidean and vector_index_type to Qc. In build_index_params, set proxima.qc.builder.quantizer_class to Int8Quantizer. In search_index_params, set proxima.qc.searcher.scan_ratio to 0.01.
Configure the dimension parameter based on the embedding model you use. This example uses the text-embedding-ada-002 model from OpenAI, so set dimension to 1536. Set enable_rt_build to true to enable real-time index building.
2.7 After the configuration is complete, click Save Edition. In the dialog box that appears, enter a description (optional) and click Publish.
After the index is published, click Next to start the index rebuild.
2.8 Configure the index rebuild parameters and click Next.
On the Index Rebuild page, confirm the Data Source Name and Data Source Type (API push data source). The Associated Index Table is llm. Select Empty Data for Data Source. Set a Timestamp and click Next.
2.9 You can monitor the progress of the index rebuild by navigating to O&M Center > Change History > Data Source Changes. You can perform query tests after the rebuild is complete.
On the Data Source Changes page, you can view the detailed progress of the index rebuild, including stages like init, trigger, scan, bs_submit, build, suez_submit, and switch. After all steps are marked with a green checkmark, you can proceed with query testing.
3. Build the system
3.1 Set up the OpenSearch-LLM tool.
3.2 Configure the .env file.
-
Use OpenAI
LLM_NAME=OpenAI

OPENAI_API_KEY=***
OPENAI_API_BASE=***

OPENAI_EMBEDDING_ENGINE=text-embedding-ada-002
OPENAI_CHAT_ENGINE=gpt-3.5-turbo

VECTOR_STORE=OpenSearch
# OpenSearch information
OPENSEARCH_ENDPOINT=ha-cn-wwo38nf8q01.ha.aliyuncs.com
OPENSEARCH_INSTANCE_ID=ha-cn-wwo38nf8q01
OPENSEARCH_TABLE_NAME=llm
OPENSEARCH_DATA_SOURCE=ha-cn-wwo38nf8q01_data
OPENSEARCH_USER_NAME=opensearch         # The username that you specified when you purchased the Vector Search Edition instance.
OPENSEARCH_PASSWORD=chat001 # The password that you specified when you purchased the Vector Search Edition instance.-
Use Microsoft Azure OpenAI
LLM_NAME=OpenAI

OPENAI_API_KEY=***
OPENAI_API_BASE=***
OPENAI_API_VERSION=2023-03-15-preview
OPENAI_API_TYPE=azure

# Specify the deployment ID of the OpenAI model in Azure.
OPENAI_EMBEDDING_ENGINE=embedding_deployment_id
OPENAI_CHAT_ENGINE=chat_deployment_id

VECTOR_STORE=OpenSearch
# OpenSearch information
OPENSEARCH_ENDPOINT=ha-cn-wwo38nf8q01.ha.aliyuncs.com
OPENSEARCH_INSTANCE_ID=ha-cn-wwo38nf8q01
OPENSEARCH_TABLE_NAME=llm
OPENSEARCH_DATA_SOURCE=ha-cn-wwo38nf8q01_data
OPENSEARCH_USER_NAME=opensearch      # The username that you specified when you purchased the Vector Search Edition instance.
OPENSEARCH_PASSWORD=chat001          # The password that you specified when you purchased the Vector Search Edition instance.
Note:
-
The OpenSearch information must match the instance you purchased earlier.
-
The
OPENSEARCH_ENDPOINTfor public access must be a public domain name. You also need to add the IP address of the machine that accesses the service to the IP address whitelist. Do not include thehttp://prefix.
3.3 Process and push data
Use the embed_files.py script in the llm directory to process your data files. The script supports Markdown and PDF files. After processing, the data is automatically pushed to the OpenSearch instance you configured. The following example pushes documents from the ${doc_dir} directory to the ha-cn-wwo38nf8q01 instance and automatically builds the index.
python -m script.embed_files -f ${doc_dir}-
Use the
-foption to specify the directory that contains the documents to be processed.
3.4 Start the Q&A service
cd ~/llm
python api_demo.py
3.5 Test with the curl command
Send a test request:
curl -H "Content-Type: application/json" http://127.0.0.1:8000/chat -d '{"query": "What is OpenSearch?"}'Output:
{
    "success": true,
    "result": "OpenSearch is a distributed search engine developed by Alibaba. It can be used to store, process, and analyze large-scale data and features high availability, scalability, and high performance.",
    "prompt": "Human: Answer the question based on the search results.    Search Results: OpenSearch is a distributed search engine developed by Alibaba. It supports SQL queries and provides a built-in User-Defined Function (UDF) feature, allowing customers to develop their own UDFs as plug-ins. OpenSearch can be used to store, process, and analyze large-scale data and features high availability, scalability, and high performance. It can be deployed using distributed O&M tools, supporting distributed clusters on physical machines or cloud-native architectures on cloud platforms.\n\n Based on the information provided, answer the user's question concisely and professionally. If the answer cannot be found in the provided text, say 'I don't know'. Do not add any fabricated information to the answer. Please use English for the answer.\n    Query: What is OpenSearch?    Assistant:   "
}
4. Reference prompt
{
    "prompt": "Human: Answer the question based on the search results. Search Results: Comparison of OpenSearch edition types: 1. Difference between Industry Algorithm Edition and High-performance Search Edition: Product Overview: Introduction to OpenSearch. OpenSearch is a one-stop intelligent search service development platform built on Alibaba's proprietary large-scale distributed search engine. It delivers millisecond-level responses for hundred billion-scale data in big data scenarios and provides search solutions for orders, logistics, and insurance policies. Product Architecture: As a SaaS platform, it allows developers to interact with the system through the console or API. With scenario-based configuration, developers only need to create an application instance, configure a data source, define the field structure and search attributes, and wait for the index rebuild to complete. Then, they can perform search tests using the SDK or console. Big data retrieval: Compared to the Industry Algorithm Edition, the High-performance Search Edition removes heavy industry algorithm capabilities. While supporting general search features (analyzers, sorting), it focuses on business query and write throughput, providing developers with second-level response and real-time query capabilities for large dataset retrieval scenarios. Product Features: High throughput, with a single table supporting tens of thousands of write TPS and second-level updates. Secure and stable: Provides 7x24 O&M and technical support through online tickets and phone calls. It has a complete set of fault emergency response mechanisms, including fault monitoring, automatic alerts, and rapid positioning. Based on Alibaba Cloud's AccessKeyId and AccessKeySecret security pair, it controls and isolates permissions at the access interface level, ensuring user-level data isolation and security. Data is backed up redundantly to prevent data loss. Query: What editions does OpenSearch have? Assistant: ",
}
Demo
Summary and outlook
This topic describes how to build an enterprise-specific conversational search system using OpenSearch Vector Search Edition and an LLM. For more search solutions, visit the OpenSearch product page.
In the future, OpenSearch will launch an Intelligent Q&A Edition for conversational search scenarios. It will provide a one-stop, SaaS-based solution for training enterprise-specific models and building intelligent conversational search systems. Stay tuned for updates.
The open source vector models and LLMs mentioned in this solution are from third parties ("Third-Party Models"). Alibaba Cloud cannot guarantee the compliance or accuracy of Third-Party Models and assumes no responsibility for the models themselves, or for any actions taken or results obtained from using them. Please exercise caution before accessing and using Third-Party Models. We also remind you that Third-Party Models are subject to agreements such as "Open Source License" or "License", which you must read carefully and strictly adhere to.