Best practices for large model deployment
ossfs 2.0 significantly optimizes the download, storage, and deployment of large models in the cloud with its high-throughput sequential writes and intelligent caching. It supports efficient model loading in both single-GPU and multi-GPU concurrent deployment scenarios. This topic describes how to download models using ossfs 2.0, provides optimization practices for deploying safetensors models in vllm/sglang frameworks, and includes notes for deploying other model types.
Download models to OSS
ossfs 2.0 supports high-throughput sequential writes, which is ideal for uploading large files, such as large models. You can use tools such as ModelScope to write models from a repository directly into an OSS Bucket through ossfs 2.0.
-
Mount an OSS Bucket to a specified folder using the standard ossfs 2.0 configuration. For configuration examples, see Common configuration examples.
-
Download the model.
You can use the following ModelScope command to download the DeepSeek-R1-0528 model to the ossfs 2.0 mount target.
modelscope download
--model deepseek-ai/DeepSeek-R1-0528 --local_dir /mnt/oss/DeepSeek-R1-0528
--max-workers=32
When you download a model with ModelScope on an ECS instance, the download is first attempted from an internal repository. If the ECS instance has sufficient network bandwidth, ossfs 2.0 efficiently uses network resources to reach the default OSS upstream bandwidth limit of 20 Gbps.
Deployment scenarios
AI models today come in many types and file formats. Common formats include safetensors (secure and efficient), PyTorch (highly versatile), and GGUF (suitable for local inference). To maximize model loading performance from OSS, you can configure ossfs 2.0 according to your deployment architecture.
In typical deployment scenarios based on the number of GPUs, the recommended ossfs 2.0 configurations are as follows:
-
Single-GPU deployment scenario
For model deployment on a single GPU, the default mount configurations for ossfs 2.0 already provide good loading performance.
-
Single-machine, multi-GPU concurrent deployment scenario
When multiple processes concurrently load the same model on a single machine with multiple GPUs, they read different shards of the same model file at the same time. This can cause bandwidth amplification. To address this, you can enable a fixed-size memory cache in ossfs 2.0 using the
--memory_data_cache_sizemount option. When enabled, the model file is downloaded from OSS only once, and multiple processes share the local cached data. This significantly reduces network load and loading latency.NoteThe memory cache mode in ossfs 2.0 is mainly used to optimize the bandwidth amplification issue when multiple processes access the same file concurrently. The cached data within a process is released synchronously after the last file handle is closed. This mode does not affect the cached data loaded into the operating system's PageCache after data is read. The caching behavior for this data is consistent with the standard mode. For more information, see Mount option descriptions.
Properly configuring ossfs 2.0 improves the loading efficiency and deployment stability for various large models in the cloud. For more information, see Deploy safetensors models and Deploy models in other formats.
Deploy safetensors models
Models in the safetensors format are secure and load quickly. This makes it a mainstream storage format for large models. ossfs 2.0 provides optimized deployment solutions for these models.
Staging environment
-
Staging environment: Lingjun 8-GPU node, 192 vCPUs, 2 TiB memory, 200 Gbps bandwidth, OSS download bandwidth limited to 100 Gbps
-
Software versions: ossfs 1.91.8, ossfs2 2.0.5, Python 3.12, SGLang 0.5.5
Mounting methods
-
ossfs 1.0 mount command
ossfs <bucket> /mnt/oss -o url=http://<endpoint> -o parallel_count=64 -
ossfs 2.0 configuration file and mount command
-
Configuration file
Create the
/etc/ossfs2.confconfiguration file, add the following content, and then save the file. Replace the bucket name, Endpoint, and AccessKey information in the example with your actual information.--oss_bucket=<bucket> --oss_endpoint=http://<endpoint> --oss_access_key_id=<ak> --oss_access_key_secret=<sk> # Configure a 16 GiB memory cache to reduce bandwidth amplification from concurrent reads --memory_data_cache_size=16g -
Mount command
ossfs2 mount /mnt/oss -c /etc/ossfs2.conf
-
Deployment methods
You can deploy safetensors models by starting the model service directly or using the PageCache prefetch method.
Direct deployment
This method is suitable for scenarios with limited memory resources. You can use the following test command to specify the model file path and start the model service:
python -m sglang.launch_server --model-path <model> --tensor-parallep-size <tp>(Recommended) PageCache prefetch deployment
This method is suitable for production environments with sufficient memory. The prefetch mechanism preloads model files into the operating system's PageCache. This method changes the original random (out-of-order) reads into a mixed mode of sequential read preloading and random access within the cache. This significantly reduces the number of OSS network requests and latency.
You can use the following commands to prefetch data and start the model service:
# Prefetch the data. This command starts 16 concurrent processes to cat the files in the model folder. After the cat operation is complete, the data resides in the operating system's PageCache.
find "<model>" -type f -print0 | xargs -0 -I {} -P "16" sh -c 'cat "{}" > /dev/null && cat "{}" > /dev/null'
# Start the service
python -m sglang.launch_server --model-path <model> --tensor-parallep-size <tp>-
The PageCache is managed by the operating system. If the node has insufficient free memory, or if the container's memory is limited in a container environment, the prefetched data may be reclaimed and released prematurely. Ensure that the available memory exceeds the total model size. Also, reserve some extra memory for the model service process and the ossfs 2.0 process. This cached data is automatically managed by the operating system after the data is loaded and does not permanently occupy system resources.
-
Ensure that no other services are reading large numbers of files on the node where the model service is deployed. Otherwise, system memory pressure might cause the prefetched data to be reclaimed and released prematurely.
Loading time comparison
These results record only the model loading time during deployment (lower is better). The test results do not include steps such as service initialization or subsequent model prefetching.
When loading the DeepSeek-R1-0528 model, ossfs 1.0 fills up the system disk, causing the system to freeze. An additional 800 GiB of local disk space is required to support the write operations.
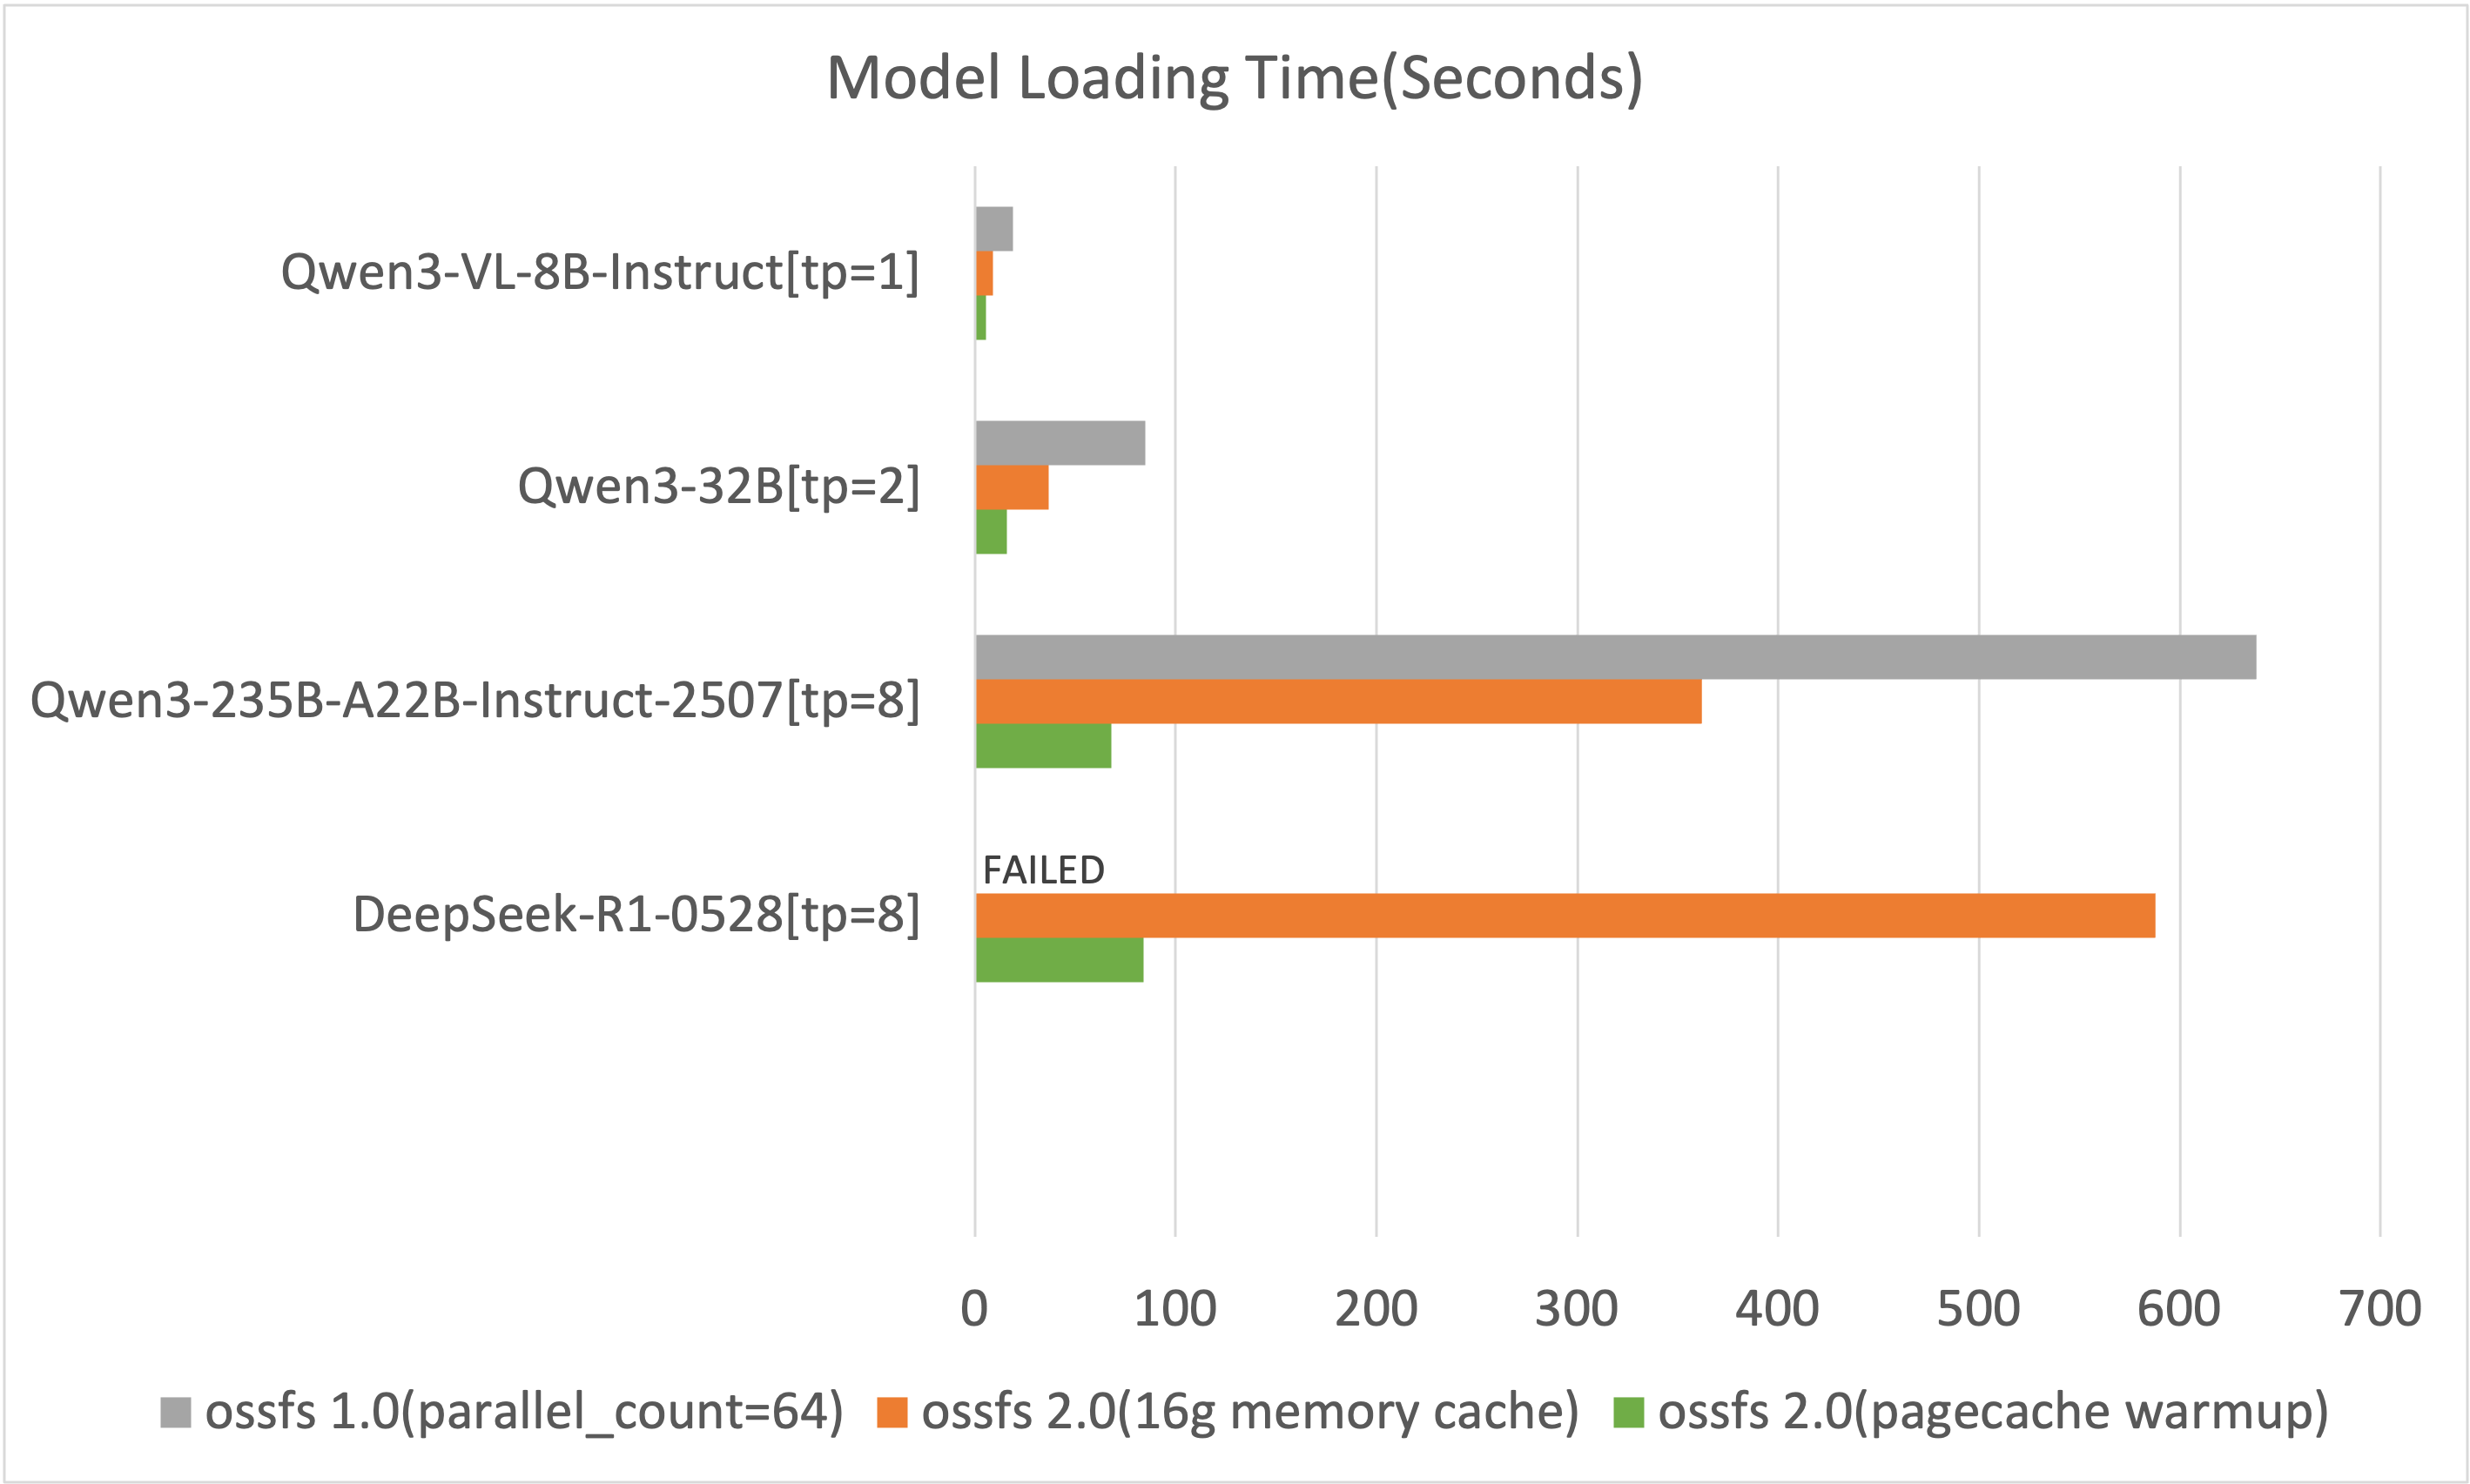
The figure above shows that ossfs 2.0 significantly improves model loading time compared to version 1.0.
Deploy models in other formats
Notes for GGUF model deployment
When a file is opened, ossfs 2.0 pre-allocates some memory for data prefetching. This memory is returned after the file is closed. However, the llama.cpp framework currently does not close file handles after reading is complete. For model repositories with many files, subsequent files do not have corresponding memory resources for prefetching. This leads to a decrease in loading efficiency.
When you load this type of model with ossfs 2.0, two optimization methods are available:
-
PageCache prefetch method: For more information, see PageCache prefetch deployment.
-
Unlimited prefetch memory method: Configure
--prefetch_chunks=-1. With default configurations, this uses up to approximatelynumber of model files × 1.5 GiBof additional memory.
If the GGUF model is large and the two methods above cannot be used, you can use OSS Connector for AI/ML to load the model.
Notes for PyTorch model deployment
When you deploy a PyTorch model with EasyRec in a multi-GPU scenario, each GPU sequentially loads the entire model file once. Configuring the --memory_data_cache_size=4g mount option effectively reduces bandwidth amplification from concurrent reads and speeds up the overall model loading efficiency.