Predict student exam scores
Designer provides a preset logistic regression template to quickly build a model that predicts final exam scores based on student family backgrounds and school behaviors. This helps you identify the key factors that affect academic performance. This topic describes how to use the preset logistic regression template.
Background
After you obtain the student score prediction model from this pipeline, you can upload data for prediction to a MaxCompute table to perform offline predictions.
Prerequisites
-
You have created a workspace. For more information, see Create and manage workspaces.
-
You have associated MaxCompute resources with your workspace. For more information, see Create and manage workspaces.
Dataset
The dataset for this pipeline consists of 25 feature columns and one target column. The following table describes the fields.
|
Parameter |
Type |
Description |
|
sex |
STRING |
Gender. F indicates female, and M indicates male. |
|
address |
STRING |
Address. U indicates city, and R indicates rural. |
|
famsize |
STRING |
Number of family members. LE3 indicates three or fewer people, and GT3 indicates more than three people. |
|
pstatus |
STRING |
Specifies whether you live with your parents. T indicates living with your parents, and A indicates living apart from your parents. |
|
medu |
DOUBLE |
The mother's education level, on a scale of 0 to 4. A higher value indicates a higher education level. |
|
fedu |
DOUBLE |
The father's education level, on a scale of 0 to 4. A higher value indicates a higher education level. |
|
mjob |
STRING |
The mother's job, including jobs in education, healthcare, and the service industry. |
|
fjob |
STRING |
The father's job, including jobs in education, healthcare, and the service industry. |
|
guardian |
STRING |
The student's guardian. Valid values are |
|
traveltime |
DOUBLE |
The travel time from home to school, in minutes. |
|
studytime |
DOUBLE |
The weekly study time, in hours. |
|
failures |
DOUBLE |
The number of past class failures. |
|
schoolsup |
STRING |
Specifies whether additional learning assistance is available. The value can be yes or no. |
|
fumsup |
STRING |
Specifies whether a private tutor is hired. The value can be yes or no. |
|
paid |
STRING |
Specifies whether assistance is provided for related exam subjects. The value can be yes or no. |
|
activities |
STRING |
Indicates whether the user is enrolled in extracurricular classes. The value can be yes or no. |
|
higher |
STRING |
Specifies whether to pursue further education. The value is yes or no. |
|
internet |
STRING |
Specifies whether the home is connected to the internet. The value can be yes or no. |
|
famrel |
DOUBLE |
The quality of family relationships, on a scale of 1 (very bad) to 5 (excellent). |
|
freetime |
DOUBLE |
The amount of free time after school, on a scale of 1 (very low) to 5 (very high). |
|
goout |
DOUBLE |
The frequency of going out with friends, on a scale of 1 (very low) to 5 (very high). |
|
dalc |
DOUBLE |
Workday alcohol consumption, on a scale of 1 (very low) to 5 (very high). |
|
walc |
DOUBLE |
Weekend alcohol consumption, on a scale of 1 (very low) to 5 (very high). |
|
health |
DOUBLE |
The current health status, on a scale of 1 (very bad) to 5 (very good). |
|
absences |
DOUBLE |
The number of school absences, from 0 to 93. |
|
g3 |
STRING |
The final exam score, on a 20-point scale. |
The following figure shows a sample of the pipeline data.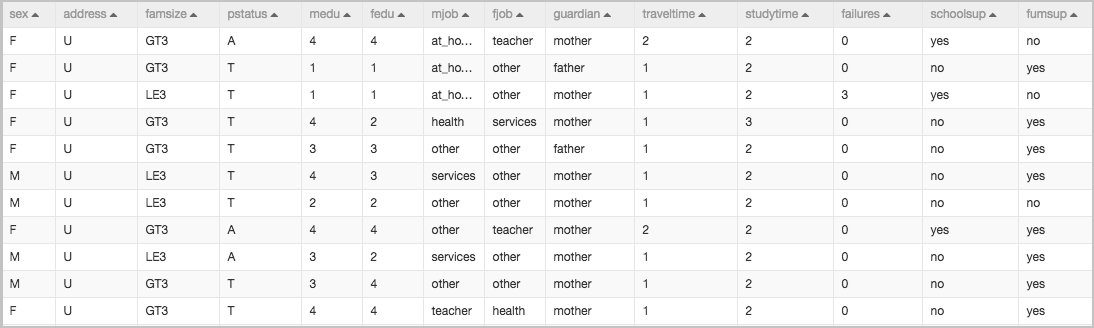
Procedure
Go to the Machine Learning Designer page.
Log on to the PAI console.
In the left-side navigation pane, click Workspaces. On the Workspaces page, click the name of the workspace that you want to manage.
In the left-side navigation pane, choose .
-
Build the pipeline.
-
On the Designer page, click the Preset Templates tab.
-
In the template list, find the Online Prediction - Student Score Prediction section and click Create.
-
In the Create Pipeline dialog box, configure the parameters. You can use the default settings for all parameters.
The Data Storage parameter specifies an OSS Bucket path to store temporary data and models generated during the pipeline run.
-
Click Confirm.
It takes about 10 seconds to create the pipeline.
-
On the Pipelines tab, double-click the Online Prediction - Student Score Prediction pipeline to open it.
-
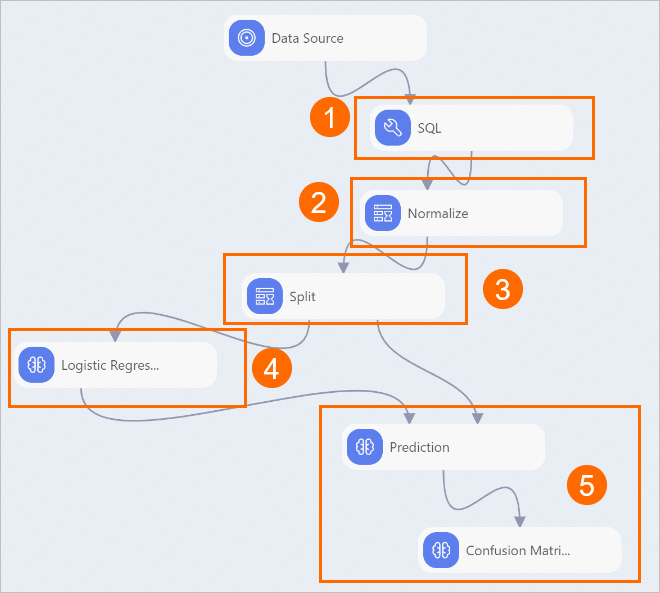
Designer automatically builds a pipeline based on the preset template, as shown in the following figure.
Area
Description
①
Data preprocessing. The SQL Script component is used to structure the text data:
-
Convert yes and no in the source data to 0 and 1, respectively.
-
For text fields that contain multiple categories, abstract the data based on your business scenario. For example, for the Mjob field, you can represent the value teacher as 1 and all other values as 0. In this case, the abstracted feature indicates whether the job is related to education.
-
For the target column, set values greater than 18 to 1 and all other values to 0.
②
The Normalize component performs normalization to scale all fields to a range of 0 to 1. This eliminates the impact of differing value scales.
③
The input dataset is split into a training dataset and a prediction dataset at an 8:2 ratio.
④
This step uses a logistic regression algorithm to train and generate an offline model.
⑤
The Confusion Matrix component evaluates the model's accuracy.
-
-
-
Run the pipeline and view the results.
-
Above the canvas, click the Run icon
 to run the pipeline.
-
After the pipeline finishes running, right-click the Confusion Matrix component on the canvas and click Visual Analysis in the shortcut menu.
-
In the Confusion Matrix dialog box, click the Summary tab to view the model's prediction accuracy, which is over 80%.
-
Related documents
For more information about the algorithm components, see the following topics: