Optimize batch inserts
This topic explains how to optimize batch insert statements.
A batch insert statement is a common method for writing data to a database. PolarDB-X is compatible with the MySQL protocol and syntax. The batch insert syntax is as follows:
INSERT [IGNORE] [INTO] table_name(column_name, ...) VALUES (value1, ...), (value2, ...), ...;The following factors affect batch insert performance:
-
Batch size
-
Degree of parallelism (DOP)
-
Number of shards
-
Number of columns
-
Number of global secondary indexes (GSIs)
-
Number of sequences
You configure the number of shards, columns, global secondary indexes, and sequences based on your business requirements. These configurations often create a trade-off between read and write performance. For example, a higher number of global secondary indexes improves read performance at the cost of write performance. This article does not cover these factors in detail but focuses on configuring the batch size and the degree of parallelism.
Test environment
The following table describes the test environment.
|
Environment |
Parameter |
|
PolarDB-X version |
polarx-kernel_5.4.11-16279028_xcluster-20210802 |
|
Node specifications |
16 cores, 64 GB memory |
|
Number of nodes |
4 |
The test table is defined by the following statement:
CREATE TABLE `sbtest1` (
    `id` int(11) NOT NULL,
    `k` int(11) NOT NULL DEFAULT '0',
    `c` char(120) NOT NULL DEFAULT '',
    `pad` char(60) NOT NULL DEFAULT '',
    PRIMARY KEY (`id`),
    KEY `k_1` (`k`)
) ENGINE = InnoDB DEFAULT CHARSET = utf8mb4;
Batch feature: BATCH_INSERT_POLICY=SPLIT
To improve concurrency for bulk data inserts, PolarDB-X optimizes batch insert statements. If a single batch insert statement exceeds 256 KB, PolarDB-X dynamically splits it into multiple smaller batches and executes them serially. This process is called SPLIT.
The BATCH_INSERT_POLICY=SPLIT mechanism ensures optimal performance, reduces overhead from parallel batch insert statements in PolarDB-X, and helps prevent load imbalance across distributed nodes.
Parameters:
-
BATCH_INSERT_POLICY: Specifies the batch insert policy. Valid values areSPLITandNONE. The default value isSPLIT, which enables the dynamic splitting feature. -
MAX_BATCH_INSERT_SQL_LENGTH: Specifies the SQL length threshold in kilobytes (KB) that triggers dynamic splitting. The default value is256. -
BATCH_INSERT_CHUNK_SIZE_DEFAULT: Specifies thebatch sizefor each smaller batch after a split occurs. The default value is200.
To disable the BATCH_INSERT_POLICY=SPLIT mechanism, use the following hint: /*+TDDL:CMD_EXTRA(BATCH_INSERT_POLICY=NONE)*/. Disabling this policy ensures that PolarDB-X does not automatically split batches during execution. This allows you to validate performance at various batch sizes, such as 2,000, 5,000, or 10,000. However, test results indicate that performance gains are not significant when the batch size exceeds 1,000.
Single-table performance baseline
In distributed mode, a single table resides on a single data node. Its performance can serve as a performance baseline to evaluate the horizontal scaling capability of sharded tables, which distribute data evenly across multiple data nodes.
The test performs batch insert operations on a single table in PolarDB-X. The data for a single table is stored on a single data node. PolarDB-X writes data to the corresponding data node according to the table definition.
Scenario 1: batch size
Parameters:
-
Degree of parallelism (DOP): 16
-
Columns: 4
-
gsi: None
-
sequence: None
|
Test item |
batch size |
1 |
10 |
100 |
500 |
1,000 |
2,000 |
5,000 |
10,000 |
|
PolarDB-X (single table) |
Performance (rows/sec) |
5,397 |
45,653 |
153,216 |
211,976 |
210,644 |
215,103 |
221,919 |
220,529 |
Scenario 2: Degree of parallelism (DOP)
Parameters:
-
batch size: 1,000
-
Columns: 4
-
gsi: None
-
sequence: None
|
Test item |
Threads |
1 |
2 |
4 |
8 |
16 |
32 |
64 |
128 |
|
PolarDB-X (single table) |
Performance (rows/sec) |
22,625 |
41,326 |
76,052 |
127,646 |
210,644 |
223,431 |
190,138 |
160,858 |
Test summary
For single table tests, optimal performance is achieved with a batch size of 1,000 and a degree of parallelism (DOP) between 16 and 32. To test with a batch size of 2,000, 5,000, or 10,000, add a hint to disable the SPLIT feature. Test results show that performance does not improve significantly when the batch size exceeds 1,000. Example:
/*+TDDL:CMD_EXTRA(BATCH_INSERT_POLICY=NONE)*/Performance benchmark for sharded tables
Both the batch size and the degree of parallelism (DOP) affect the performance of batch insert operations. This section tests and analyzes these two factors.
Scenario 1: batch size
When performing a batch insert on a sharded table, the sharding function splits the VALUES clause. This changes the batch size that is pushed down to the data nodes, as illustrated in the following diagram.
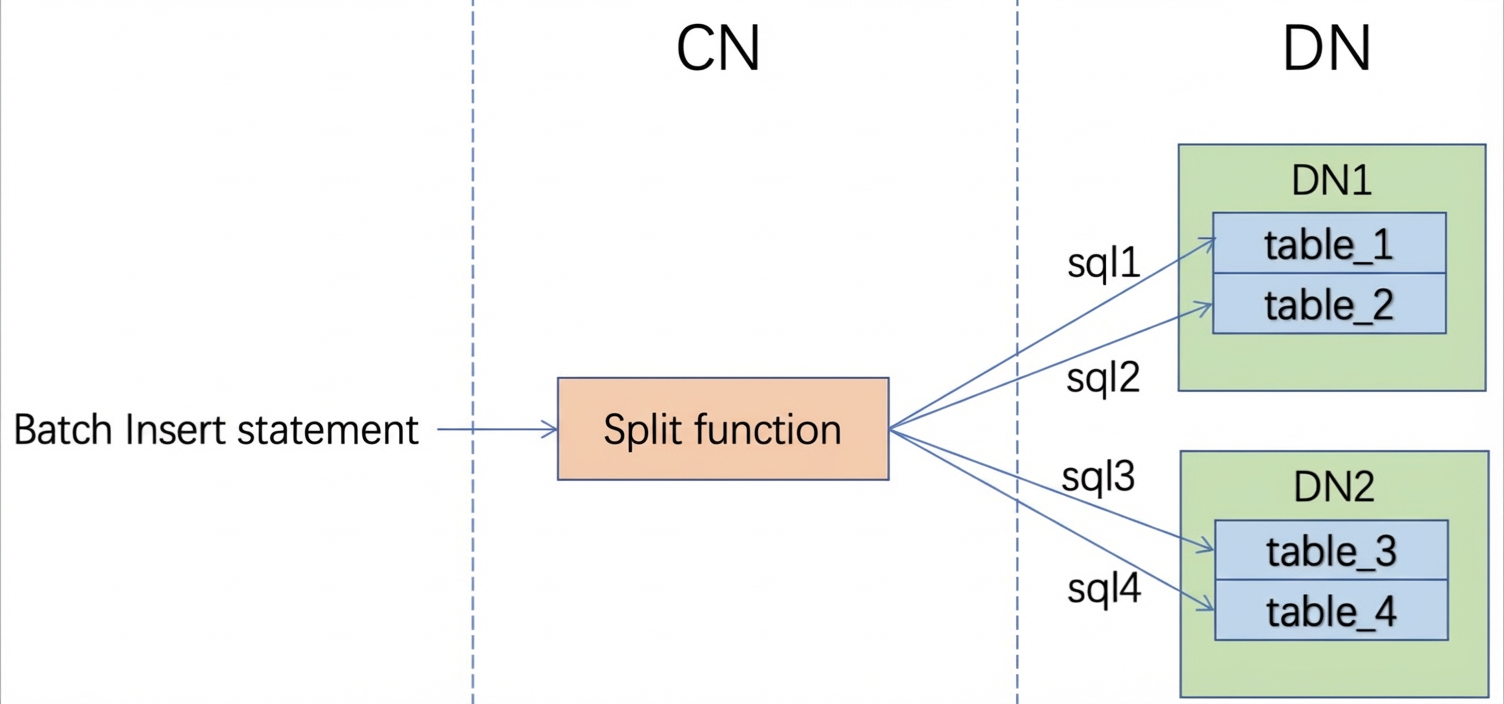
Therefore, with data sharding, you can use larger Batch Insert statements in PolarDB-X or try to place data for the same physical table into a single Batch Insert statement. This ensures that after the sharding function separates the values, the batch size pushed down to a single data shard is appropriate, which improves the performance of storage nodes.
-
Sub-scenario 1:
BATCH_INSERT_POLICY=SPLITParameters:
-
BATCH_INSERT_POLICY: Enabled
-
DOP: 32
-
Shards: 32
-
Columns: 4
-
GSI: None
-
Sequence: None
Test item
Batch size
1
10
100
500
1000
2000
5000
10000
PolarDB-X (32 shards)
Performance (rows/s)
12804
80987
229995
401215
431579
410120
395398
389176
NoteThe
BATCH_INSERT_POLICYstrategy is triggered when the batch size is 2,000 or greater. -
-
Sub-scenario 2:
BATCH_INSERT_POLICY=NONEParameters:
-
BATCH_INSERT_POLICY: Disabled
-
DOP: 32
-
Shards: 32
-
Columns: 4
-
GSI: None
-
Sequence: None
Test item
Batch size
1000
2000
5000
10000
20000
30000
50000
PolarDB-X (32 shards)
Performance (rows/s)
431579
463112
490350
526751
549990
595026
685500
Summary:
-
With
BATCH_INSERT_POLICY=SPLITand a batch size of 1,000, the overall performance is approximately 430,000 rows per second, double the performance of a non-sharded table. -
With
BATCH_INSERT_POLICY=NONE, the values in this test are randomly distributed by a Hash sharding function, resulting in an almost even data distribution across each shard. With a maximum batch size of 50,000, the overall performance reaches 680,000 rows per second.
-
Scenario 2: DOP
The optimal DOP fully utilizes the CPU or maximizes the IOPS of the PolarDB-X data nodes. Because batch insert statements involve minimal computation, PolarDB-X compute nodes have low overhead, and the main workload is on the PolarDB-X data nodes. A DOP that is too low or too high can reduce performance. The optimal value depends on factors such as the number of nodes, node specifications (such as CPU cores), and thread pool pressure. Therefore, no single value is universally optimal. Run tests in a production-like environment to determine the best DOP for your workload.
-
Sub-scenario 1: Test different DOPs on a 4-node cluster with a batch size of 1,000.
Parameters:
-
batch size: 1,000
-
Columns: 4
-
GSI: None
-
Sequence: None
Test item
Threads
1
2
4
8
16
32
64
80
96
PolarDB-X (32 shards)
Performance (rows/s)
40967
80535
151415
246062
367720
431579
478876
499918
487173
Summary: For this configuration, peak performance occurs at a concurrency of 64 to 80 threads, reaching approximately 500,000 rows per second.
-
-
Sub-scenario 2: Test DOP with different numbers of nodes
Parameters:
-
2 nodes: 2 CNs × 2 DNs
-
batch size: 20,000
-
Column: 4
-
GSI: None
-
Sequence: None
Test item
Threads
4
8
12
16
PolarDB-X (16 shards)
Performance (rows/s)
159794
302754
296298
241444
Parameters:
-
3 nodes: 3 CNs × 3 DNs
-
batch size: 20,000
-
Columns: 4
-
GSI: None
-
Sequence: None
Test item
Threads
9
12
15
18
PolarDB-X (24 shards)
Performance (rows/s)
427212
456050
378420
309052
Parameters:
-
4 nodes: 4 CNs × 4 DNs
-
batch size: 20,000
-
Columns: 4
-
GSI: None
-
Sequence: None
Test item
Threads
16
32
40
64
PolarDB-X (32 shards)
Performance (rows/s)
464612
549990
551992
373268
Summary: As the number of nodes increases, the optimal DOP also needs to increase. Peak performance is 300,000 rows/s with a DOP of 8 on 2 nodes, 450,000 rows/s with a DOP of 12 on 3 nodes, and 550,000 rows/s with a DOP of 32 on 4 nodes. The performance scales almost linearly with the number of nodes, at a rate of approximately 0.9 to 1.0.
-
-
Sub-scenario 3: Test DOP with different node specifications
Parameters:
-
batch size: 20,000
-
Columns: 4
-
GSI: None
-
Sequence: None
Test item
Threads
4
8
10
12
16
PolarDB-X (4-core, 16 GB)
Performance (rows/s)
165674
288828
276837
264873
204738
Test item
Threads
8
10
12
16
PolarDB-X (8-core, 32 GB)
Performance (rows/s)
292780
343498
315982
259892
Test item
Threads
16
32
40
64
PolarDB-X (16-core, 64 GB)
Performance (rows/s)
464612
549990
551992
373268
Summary: As node specifications are upgraded, the optimal DOP also increases. Peak performance is 280,000 rows/s with a DOP of 8 on 4-core, 16 GB nodes; 340,000 rows/s with a DOP of 10 on 8-core, 32 GB nodes; and 550,000 rows/s with a DOP of 32 on 16-core, 64 GB nodes. The performance scales with the node specifications at a rate of approximately 0.5 to 0.6.
-
Summary
-
We recommend a
batch sizeof 1,000 and aDOPbetween 16 and 32. This configuration optimizes concurrency and balances the resource load on the instance. -
To maximize data import throughput, increase the
batch size. As a best practice, thebatch sizeshould be between(number of shards) × 100and(number of shards) × 1,000, for example, 20,000 to 50,000. Keep the size of each batch insert statement between 2 MB and 8 MB, as the default maximum packet size is 16 MB. You must also setBATCH_INSERT_POLICY=NONEusing ahint.ImportantAn oversized SQL statement can overload a single
compute nodein a distributed system. This increases the risk of excessivememoryconsumption and can lead to an unbalanced load acrossnodes. -
Batch insert operations are primarily
IOPS-intensive;CPUandmemoryare typically not the main bottlenecks. Therefore, when scaling resources to improve performance, prioritizescaling outby adding morenodes overscaling upindividualnodes. -
For batch imports of
on-premisestext data, useBatch Tool, the dedicated import and export utility for PolarDB-X. For more information, see Import and export data using the Batch Tool.