Best practices and optimization for analytical scenarios
PolarDB-X is a Hybrid Transactional/Analytical Processing (HTAP) database primarily designed for Transaction Processing (TP), but it also supports analytical workloads. Typical analytical scenarios have the following characteristics:
-
Workloads consist of mostly read requests with few write or update operations.
-
Queries read a large number of rows but only a small number of columns.
-
Most queries are complex, with low concurrency but high throughput per query.
-
Some latency is acceptable for simple queries.
-
A distributed transaction is not always necessary for analytical workloads.
-
Most queries involve joins between a large fact table and a smaller dimension table.
-
The result set is significantly smaller than the source data, allowing the filtered or aggregated data to fit into the memory of a single server.
-
The data being analyzed is typically recent business data, while historical data can be deleted or archived.
Based on these characteristics, optimizing performance for analytical scenarios requires strategies different from those for TP databases. The main focus is on schema design and query optimization.
Schema design
Schema design involves selecting the optimal table type, partition key, primary key, and clustered index to maximize table performance.
Use partitioned tables or broadcast tables
-
A broadcast table stores a full copy of its data on every data node in the cluster. Best practice: Keep the data volume in a broadcast table small, with no more than 200,000 rows per table. This allows join operations between a large table and a broadcast table to be pushed down to the data layer for processing, which avoids pulling large amounts of data to the compute nodes.
-
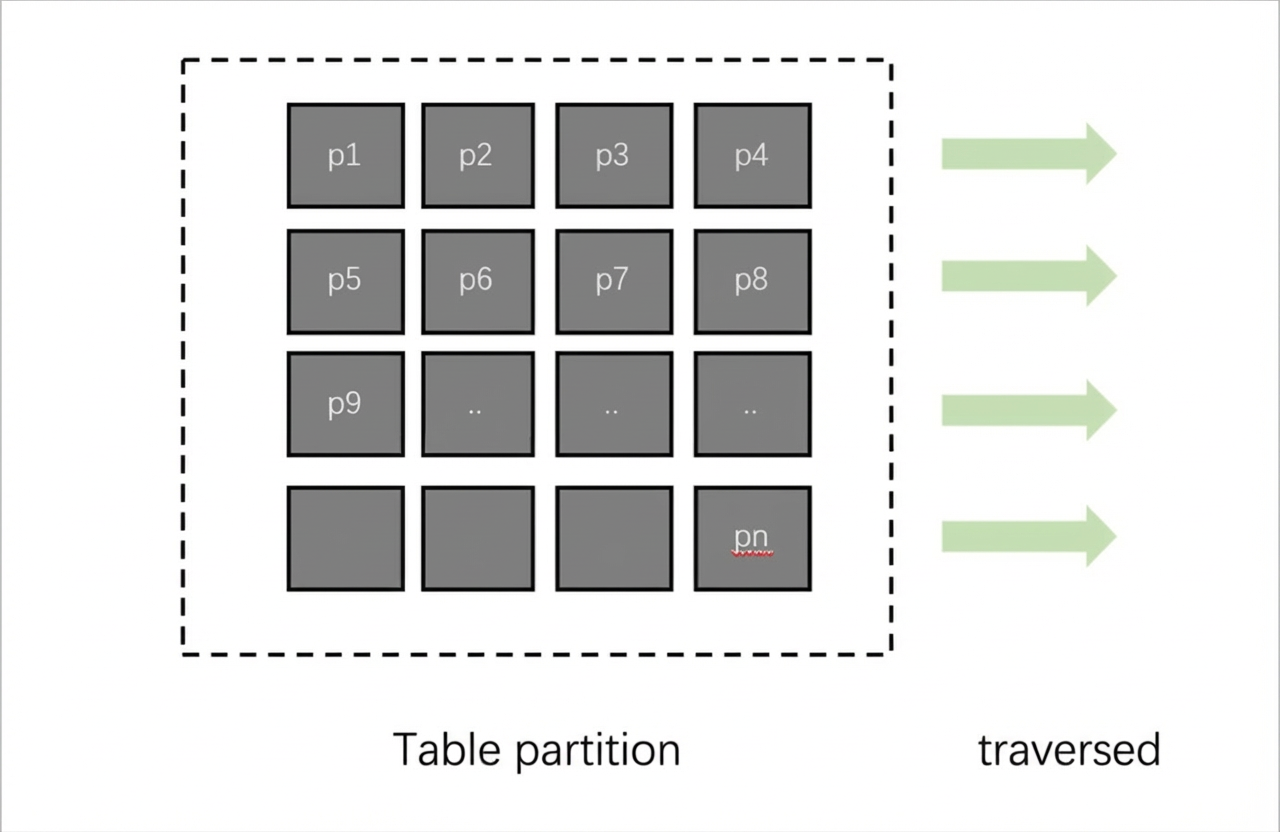
For other business data, use a partitioned table whenever possible to fully leverage the query capabilities of a distributed system. In theory, more partitions lead to better performance because multiple partitions can be scanned in parallel. This also simplifies horizontal scaling for the storage layer, which can then store tens or hundreds of millions of records. In practice, we recommend that each partition contain between 5 million and 50 million rows.
Choose an appropriate partition key
By default, PolarDB-X partitions tables by the primary key to reduce the complexity of using a distributed database. However, you can also create a partitioned table by specifying a partition key. For analytical scenarios, we recommend that you choose a partition key based on the following guidelines:
-
Whenever possible, choose a column that is used in join operations as the partition key. This allows join conditions to be pushed down, which prevents data from being pulled to the compute nodes for processing.
-
Choose a column with an even value distribution as the partition key. This helps prevent performance bottlenecks caused by data skew, which can significantly slow down large queries.
Design subpartitions effectively
When dealing with large data volumes or data skew, selecting the right subpartition is critical. Poorly designed or missing subpartitions in large tables can degrade performance. PolarDB-X in DRDS mode supports the subpartition feature. If your business requires incremental data imports and mainly runs reports on recent data, we recommend that you use a date-based column to create a subpartition. This helps avoid scanning historical or expired data.
// Create a primary partition on the col column.
PARTITION BY HASH(col)
SUBPARTITION BY LIST (ds)
// Create a subpartition by month based on the ds column.
SUBPARTITION TEMPLATE (
   PARTITION p1 VALUES LESS THAN ('2021-08-00'),
   PARTITION p2 VALUES LESS THAN ('2021-09-00'),
)
Design indexes properly
If you have already designed a suitable partition key based on join columns, but some complex queries still involve joins on other columns, a join pushdown is not possible. In this case, consider creating a global secondary index (GSI) on the non-partition key column. This transforms the query to use a join with the GSI instead of the original table. To avoid the overhead of a table lookup, we recommend that you create all GSIs as a clustered index for analytical scenarios.
Query optimization
In analytical scenarios that involve large datasets and can tolerate some latency for simple queries, we recommend that you use the massively parallel processing (MPP) mode. This mode utilizes the resources of multiple compute nodes (CNs) to handle complex computations. By default, MPP is enabled only on a read-only instance. If you need to run analytical workloads on your primary instance, contact Alibaba Cloud technical support.
During a query, PolarDB-X uses its optimizer to select an appropriate distributed execution plan and then dispatches the plan to compute nodes, using the cluster's full computational power to accelerate the query. The optimizer's choice of a distributed execution plan is entirely cost-based and relies on statistics. Therefore, collecting timely statistics is crucial. Since the plan generated by the optimizer may not always be optimal, this article also provides best practices for writing and optimizing SQL queries.
Collect statistics
If a distributed execution plan from PolarDB-X is not optimal, you can manually collect statistics for a specific table by using the ANALYZE TABLE command. PolarDB-X automatically collects statistics on a regular basis.
Follow SQL writing best practices
-
Remove unnecessary columns
Analytical queries are often high-throughput, so you should remove unnecessary columns from the result set to reduce network bandwidth pressure. When you write SQL queries, specify only the columns that your business requires instead of using a wildcard (
*) to select all columns.// Inefficient query select * from T1 where a1>100 and a2<1000; // Better query, returns only the required columns select a1, a2 from T2 where a1>100 and a2<1000; -
Filter data by using a local secondary index (LSI)
Many analytical use cases benefit from creating a subpartition on a time-based column. When you scan large amounts of data, you can use this column as a filter condition to exclude most of the historical data.
select a1,c2 from T1 where time >='2010-01-01 00:00:00';To avoid a full table scan, a local secondary index (LSI) is created on this partition column by default. Similarly, for other high-throughput scanning scenarios, consider creating an LSI based on your filter conditions.
-
Avoid inefficient SQL syntax
If a table contains a very large number of records, scanning can be slow, which directly leads to slow queries. Pay attention to the following points when you write SQL queries:
-
Avoid invalidating indexes
-
Do not perform operations on an indexed column, such as calculations, functions, or automatic or manual type conversions. These operations can invalidate the index, which results in a full table scan.
explain execute select * from staffs where name= 'hu'; +----+-------------+--------+------------+------+-----------------------+-----------------------+---------+-------+------+----------+-------+ | id | select_type | table | partitions | type | possible_keys | key | key_len | ref | rows | filtered | Extra | +----+-------------+--------+------------+------+-----------------------+-----------------------+---------+-------+------+----------+-------+ | 1 | SIMPLE | staffs | NULL | ref | idx_staffs_nameAgePos | idx_staffs_nameAgePos | 74 | const | 1 | 100 | NULL | +----+-------------+--------+------------+------+-----------------------+-----------------------+---------+-------+------+----------+-------+ 1 row in set , 1 warning (0.00 sec) // Operations on the indexed column cause the index to become invalid. explain execute select * from staffs where left(name,4)= 'hu'; +----+-------------+--------+------------+------+---------------+------+---------+------+------+----------+-------------+ | id | select_type | table | partitions | type | possible_keys | key | key_len | ref | rows | filtered | Extra | +----+-------------+--------+------------+------+---------------+------+---------+------+------+----------+-------------+ | 1 | SIMPLE | staffs | NULL | ALL | NULL | NULL | NULL | NULL | 198 | 100 | Using where | +----+-------------+--------+------------+------+---------------+------+---------+------+------+----------+-------------+ 1 row in set , 1 warning (0.00 sec) -
Using inequality operators (
!=or<>) prevents the use of an index and leads to a full table scan. -
IS NULLandIS NOT NULLconditions also prevent the use of an index.explain execute select * from staffs where name is null ; +----+-------------+-------+------------+------+---------------+------+---------+------+------+----------+------------------+ | id | select_type | table | partitions | type | possible_keys | key | key_len | ref | rows | filtered | Extra | +----+-------------+-------+------------+------+---------------+------+---------+------+------+----------+------------------+ | 1 | SIMPLE | NULL | NULL | NULL | NULL | NULL | NULL | NULL | NULL | NULL | Impossible WHERE | +----+-------------+-------+------------+------+---------------+------+---------+------+------+----------+------------------+ 1 row in set -
A
LIKEcondition with a leading wildcard (%) in MySQL causes the index to be ignored, which results in a full table scan.explain exeucte select * from staffs where name like '%hu' ; +----+-------------+--------+------------+------+---------------+------+---------+------+------+----------+-------------+ | id | select_type | table | partitions | type | possible_keys | key | key_len | ref | rows | filtered | Extra | +----+-------------+--------+------------+------+---------------+------+---------+------+------+----------+-------------+ | 1 | SIMPLE | staffs | NULL | ALL | NULL | NULL | NULL | NULL | 198 | 11.11 | Using where | +----+-------------+--------+------------+------+---------------+------+---------+------+------+----------+-------------+ 1 row in set explain execute select * from staffs where name like 'hu%' ; +----+-------------+--------+------------+-------+-----------------------+-----------------------+---------+------+------+----------+-----------------------+ | id | select_type | table | partitions | type | possible_keys | key | key_len | ref | rows | filtered | Extra | +----+-------------+--------+------------+-------+-----------------------+-----------------------+---------+------+------+----------+-----------------------+ | 1 | SIMPLE | staffs | NULL | range | idx_staffs_nameAgePos | idx_staffs_nameAgePos | 74 | NULL | 1 | 100 | Using index condition | +----+-------------+--------+------------+-------+-----------------------+-----------------------+---------+------+------+----------+-----------------------+ 1 row in set
-
-
Minimize the use of
LIKE.LIKEoperations are generally inefficient. Use range conditions, such asBETWEEN ... AND ..., whenever possible. -
In multi-table join scenarios:
-
Always try to include a condition on the partition column. If this is not possible, use the WHERE clause to filter out as much data as possible.
-
In an
OUTER JOIN, theONandWHEREclauses have different scopes. TheONclause is applied during the join process, while theWHEREclause is applied to the result of the join. Therefore, place any conditions that can filter data early in the join process in theONclause or in a subquery on the joined table. This reduces the amount of data in the original tables that needs to be joined.
-
-
Check for and handle data skew
If a query is unexpectedly slow or if resource utilization is uneven across nodes, you may be experiencing data skew. There are three common strategies to resolve data skew:
-
Use the
show info from tablecommand to check the data distribution of a shard across different nodes. If the data is not evenly distributed, consider changing the partition key of the table. -
If you encounter a severe hotspot issue with a join key, process the skewed key with separate logic. For example, if a large number of
NULLvalues in the key column causes data skew, filter out theNULLvalues or append a random number to them before performing the join. The following example shows how to do this:SELECT * FROM A JOIN B ON CASE WHEN A.value IS NULL THEN CONCAT('value',RAND() ) ELSE A.value END = B.value;In a real-world scenario, if you detect data skew but cannot identify the key that is causing it, you can use the following method to investigate:
-- Execute the following statement to query the data skew. SELECT * FROM a JOIN b ON a.key=b.key; -- You can execute the following SQL to view the key distribution and determine if a join operation will cause data skew. SELECT left.key, left.cnt * right.cnt FROM (select key, count(*) AS cnt FROM a GROUP BY key) LEFT JOIN (SELECT key, COUNT(*) AS cnt FROM b GROUP BY key) RIGHT ON left.key=right.key; -
If a hotspot issue occurs in a
GROUP BYkey, you can rewrite the SQL query to split the long-tail key by adding a random number. For example:SELECT Key,COUNT(*) AS Cnt FROM TableName GROUP BY Key; // Optimize the SQL by first splitting and pre-aggregating the hotspot, and then performing the final aggregation. -- Assume that the long-tail key is 'KEY001'. SELECT a.Key , SUM(a.Cnt) AS Cnt FROM ( SELECT Key , COUNT(*) AS Cnt FROM TableName GROUP BY Key, CASE WHEN Key = 'KEY001' THEN rand() % 50 ELSE 0 END ) a GROUP BY a.Key;
Execution strategy
If query performance is still not ideal after you apply the preceding strategies, and neither your compute nor storage resources have reached their limits, you can try adjusting the execution strategy. There are two main ways to do this:
-
Increase the degree of parallelism (DOP). You can use the
/*+TDDL:MPP_PARALLELISM=4*/hint to specify the DOP for the MPP executor./*+TDDL:MPP_PARALLELISM=4*/ select a.k, count(*) cnt from sbtest1 a, sbtest1 b where a.id = b.k and a.id > 1000 group by k having cnt > 1300 or der by cnt limit 5, 10; -
Use a hint to specify a particular algorithm. For more information about how to choose better aggregation and join algorithms, see Aggregation and Join.