Structure and data allocation of stress testing scenarios
This topic describes the logical structure of common stress testing scenarios and explains how data is allocated during stress testing.
Terms
Stress testing API: A client-side request that is triggered by a user behavior. This is a required element for stress testing.
Trace: An ordered set of stress testing APIs, similar to a transaction, that represents a business process.
Associated data file: A data file becomes associated with a stress testing API when the API uses parameters from that file. If an API uses file parameters from different data files, it is associated with multiple data files.
Data configuration node: A node used to configure or define file parameters before they are used in a trace. This is required if any API in the trace needs to use file parameters or redefine them, such as using MD5 encoding.
Data exporting instruction: An instruction used to export data from a trace. For example, you can export cookies. The exported data can be used by other traces to enable global data sharing.
Checkpoint (assertion): An assertion used to mark the success or failure of a business process by verifying whether the response to a stress testing request meets expectations.
Single data polling: A method of using file parameters where the data file is polled only once to ensure that request information is not repeated.
Response parameter: A parameter that uses part of the response information from a preceding API within the same trace.
Common stress testing scenario structures and data allocation rules
The following figure shows the details.
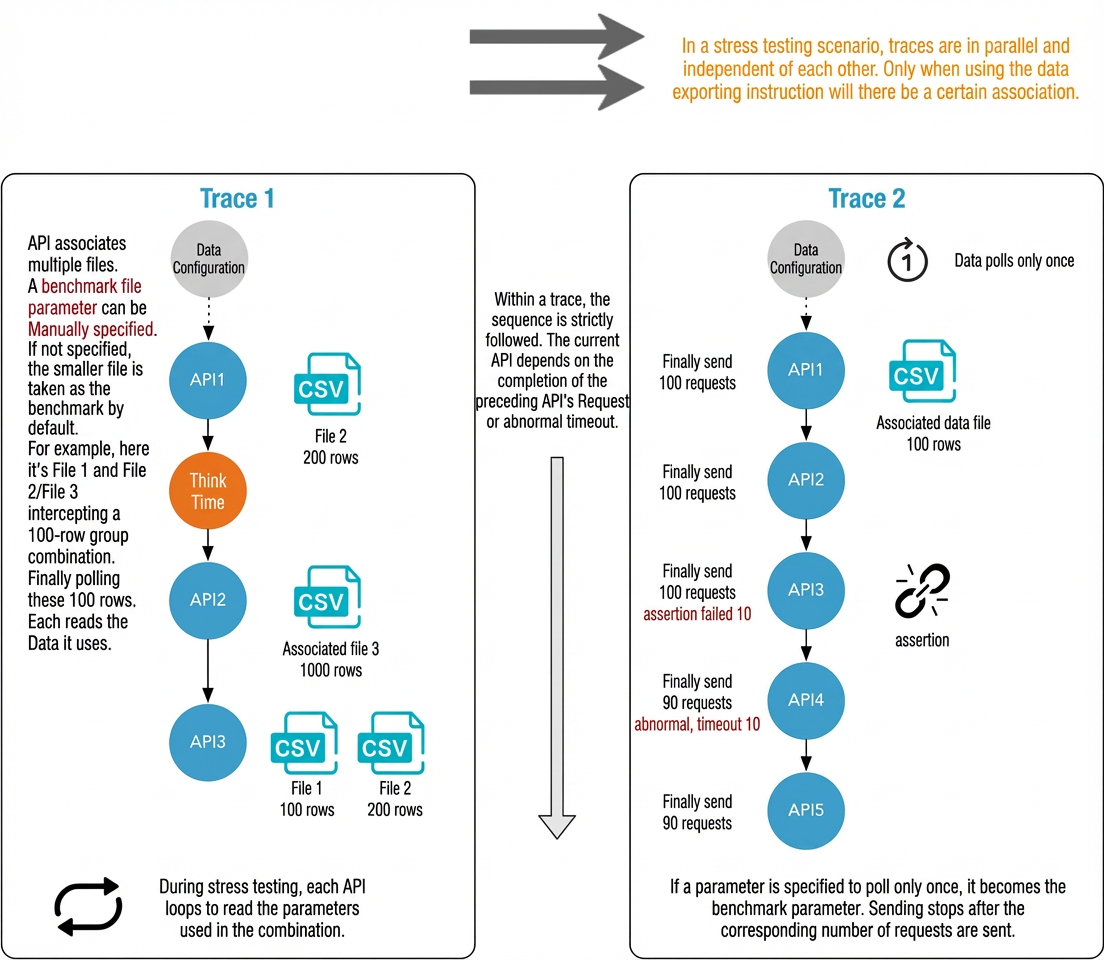
The legend is as follows:
Trace 1 and Trace 2 run in parallel.
A trace is similar to a transaction. All stress testing APIs within a trace are executed in a strict sequential order. The request for an API is sent only after the request for the preceding API is processed or times out.
NoteThe number of requests sent by later APIs is less than the number sent by earlier APIs. This is because when the stress test stops, some requests are still being processed by intermediate APIs in the trace and have not yet been completed.
Within a trace, all file parameters used by APIs must be configured in a data configuration node before they can be used. For more information, see Add a data configuration node.
In Trace 1, API 1 uses a parameter from File 2 (200 rows), API 2 uses a parameter from File 3 (1,000 rows), and API 3 uses parameters from File 2 (200 rows) and File 1 (100 rows). If no base file is specified, the number of parameter combinations is determined by the file with the fewest rows, which in this case is File 1 with 100 rows. The system takes the first 100 rows from File 2 and File 3, combines them, and then loops through the combined data repeatedly.
If you select the Single data polling option for a parameter, that parameter's source file is set as the base file. The number of rows in the combined data will equal the number of rows in the base file. After all requests are sent using the combined data, the API is no longer tested, and the entire trace stops.
If a checkpoint (assertion) is set and it fails for the current request, subsequent APIs or instructions in that run are not executed. Runs in which the assertion succeeds are not affected.
Structure of stress testing scenarios that require logon
In the following figure, API 1 in Trace 1 is a logon API. The following is a typical configuration:
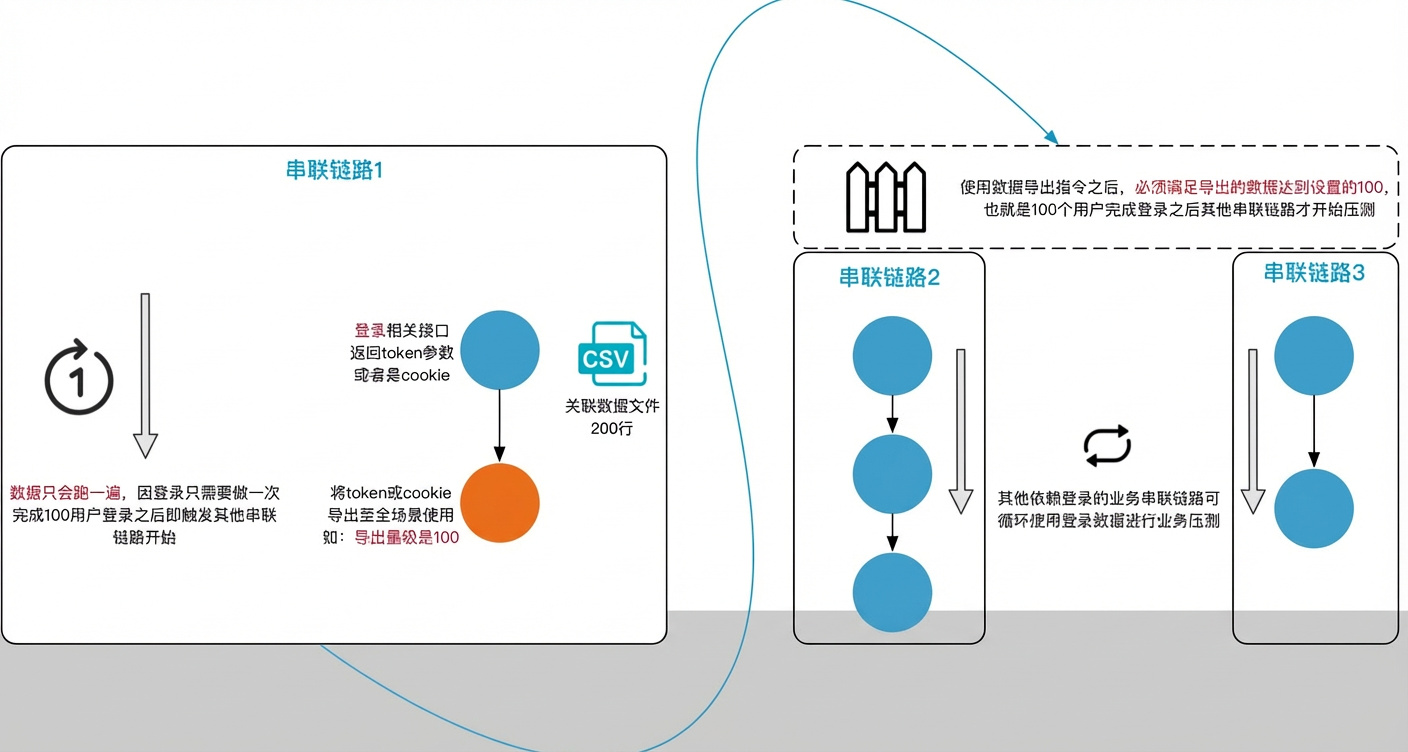
The legend is as follows:
Data exporting instruction is typically used when you need to run stress tests on multiple business traces in parallel after logon. It supports standard cookie exporting or exporting custom response parameters. You can export up to five parameters. The export volume for each parameter is based on its configured value.
Trace 1 uses the Data exporting instruction. Other traces can begin stress testing only after this data is exported. Therefore, Trace 1 does not run in parallel with the other traces.
NoteThe use of the data exporting instruction is the only case where traces do not run in parallel.
To ensure that user logon information is not repeated, you can set the Single data polling option for a parameter in the Data Configuration of the stress testing API. In the example figure, a parameter in Trace 1 is configured to poll data only once.
After a batch of users logs on, their logon information is shared with other business traces in the scenario. The remaining traces are triggered for stress testing only after the number of exported records reaches the specified Export Volume.
The export volume must be less than or equal to the number of rows in the logon API's data file. For example, if the associated data file has 200 rows, you can set the export volume to 100.
NoteIf the specified volume is not reached (for example, because some stress testing agents go offline unexpectedly during the test), you can click Release Global Preparation at the bottom of the stress testing page to continue testing the other traces.