Sensitive data protection for observability
Protect AI Agent logs against plaintext leakage while preserving their value for troubleshooting, analysis, and auditing. Alibaba Cloud observability builds a sensitive data protection system across the collection, ingestion, and data transformation stages using masking, symmetric encryption, and envelope encryption. In AI Agent scenarios, logs contain sensitive data of greater variety and complexity: beyond phone numbers, IP addresses, and API keys, AI Coding Agents, RAG applications, and Ops Agents read source code, configuration files, environment variables, and database connection strings, and write tool calling results, terminal output, and model responses into audit logs. This data serves as critical evidence for troubleshooting, auditing, and governance, so it cannot simply be discarded. To balance security and availability, data can be masked or encrypted before ingestion, and further transformed after ingestion to produce secure datasets suitable for long-term retention and shared analysis.
All names, phone numbers, email addresses, public keys, and private keys in this topic are fictitious generated data.
Overall solution
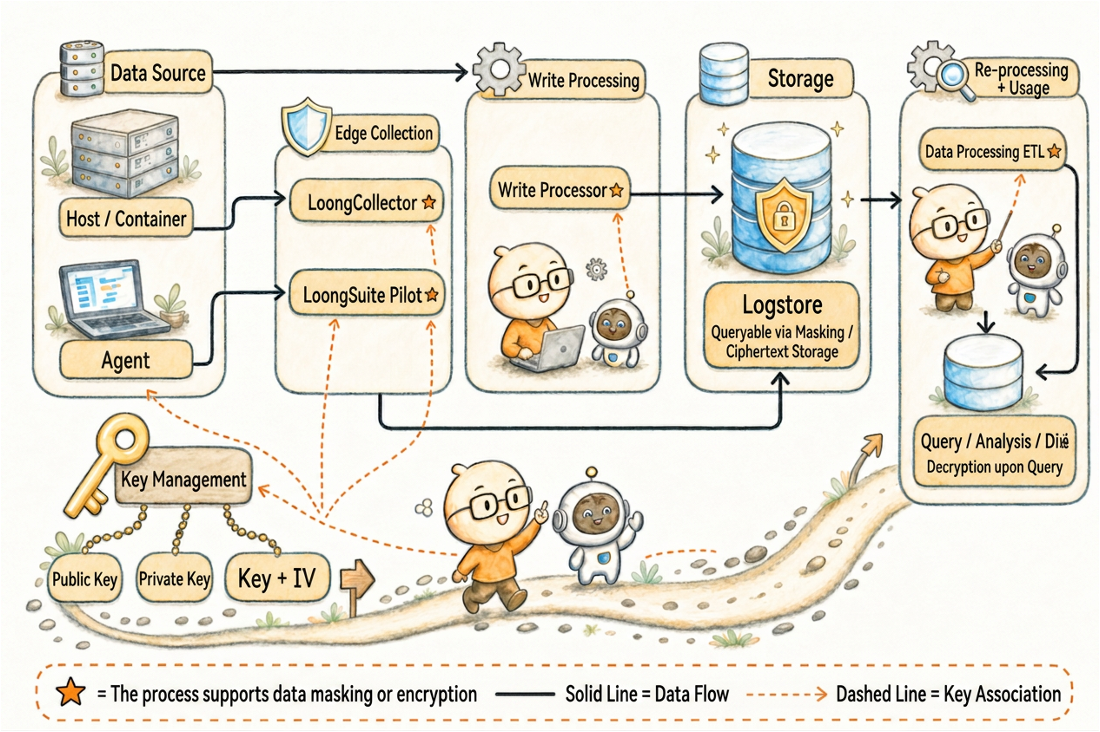
The Simple Log Service sensitive data protection solution can be broken down into two questions:
What method should be used to protect sensitive content?
At which stage in the data link should the protection action be performed?
The first question corresponds to masking, symmetric encryption, and envelope encryption. The second question corresponds to client-side processing, write processors, and data transformation. These two choices can be combined flexibly: the same protection method can be applied at the collection side, before ingestion, or after ingestion; the same processing stage can use masking or encryption depending on data risk. For a full mapping of scenarios to recommended stages and methods, see Selection guide.
Protection methods
Different types of sensitive data do not need to be handled in the same way. Simple Log Service provides three types of SPL functions for data processing — masking, symmetric encryption, and envelope encryption — corresponding to the security requirements of "preserving readability", "authorized restoration", and "separation of duties".
Masking: preserve readability, reduce privacy risk
mask is suitable for processing PII or credential fields scattered in text. It supports two matching modes:
buildin: built-in rules for phone numbers, email addresses, ID card numbers, bank card numbers, IP addresses, landline numbers,AccessKeypairs, license plates, International Mobile Subscriber Identity (IMSI), and VIN numbers.
The masking method can use a placeholder or preserve prefixes and suffixes. For example, a phone number can retain the first three and last four digits, which protects privacy while allowing fuzzy matching for troubleshooting on the business side. Masked logs remain readable, searchable, and aggregatable, so this is the default choice for most log scenarios. For detailed usage, see Use the mask function for data masking.keyword: matches by field name or key name, such aspassword,token,authorization, andapi_key.
Typical scenarios include:
Phone numbers, email addresses, and ID card numbers scattered in AI gateway prompts.
Client IP addresses and authentication tokens in application access logs.
Bank card numbers, addresses, and user identifiers in LLM application logs.
Symmetric encryption: ciphertext storage, authorized restoration
aes_encrypt is suitable for scenarios where data needs to be restored later and key ownership is clear. For example, internal RAG Q&A, model requests, and customer solutions can be stored as ciphertext and restored by a team that holds the Key + IV during authorized audits.
If collection, analysis, and auditing are all within the same team, the Key + IV can be managed centrally, which makes symmetric encryption a simple and high-performance option. Its boundary is also clear: once the key is shared, all holders have decryption capability, so it fits use within the same organization or security domain, and not broad distribution across teams.
Envelope encryption: public-private key separation for high-sensitivity collaboration
envelope_encrypt is suitable for scenarios where the collection side and decryption side are separated. It uses an envelope encryption mechanism: a random DEK is generated to encrypt business data, and then an asymmetric public key encrypts the DEK. The collection side only needs the public key configured; the private key is held separately by the security or audit team.
This pattern is suitable for highly sensitive fields, such as:
Complete returns after an AI Coding tool reads files.
Command execution output.
Entire log segments containing keys, connection strings, and configuration files.
The DEK is generated at the pipeline level, so business data is still processed by AES; only the DEK is encrypted asymmetrically, which limits the impact on collection throughput.
Practice cases
Protection methods and processing stages are not fixed combinations. The following sections cover three stages in order of data stream flow. Each stage uses one representative method as an example, but this does not mean the stage supports only that method.
Client-side protection: keep plaintext from leaving the collection side
In stricter compliance scenarios, sensitive data protection must be pushed down to the collection side: logs are processed immediately upon collection, so plaintext does not leave the host or container, and does not enter subsequent transport links.
Client-side protection has two implementations: LoongCollector for host/container log processing at collection time, and LoongSuite Pilot for client-side privacy control in AI Coding Agent scenarios. They solve different problems but share the same goal: control plaintext propagation before data leaves the collection side.
LoongCollector: process at collection time, no application changes required
For applications deployed on ECS instances, ACK clusters, IDC hosts, or containers, LoongCollector collects data and can also execute SPL at collection time. AI gateways, Alibaba Cloud Model Studio applications, RAG services, model proxy layers, and other components typically output large volumes of access logs and interaction logs that contain both structured fields and natural-language content from user input. With LoongCollector, sensitive fields are processed before leaving the collection host.
Using AI gateway access logs as an example, a raw log entry may contain the caller IP, API key, and user prompt:
model=qwen-max client_ip=192.0.2.55 prompt="I am Zhang, phone number 138xxxxxxxx, email zhangwei@xxxx.com, help me check my recent orders" tokens=128In the LoongCollector collection configuration, you can use mask to simultaneously process built-in PII patterns and keyword fields:
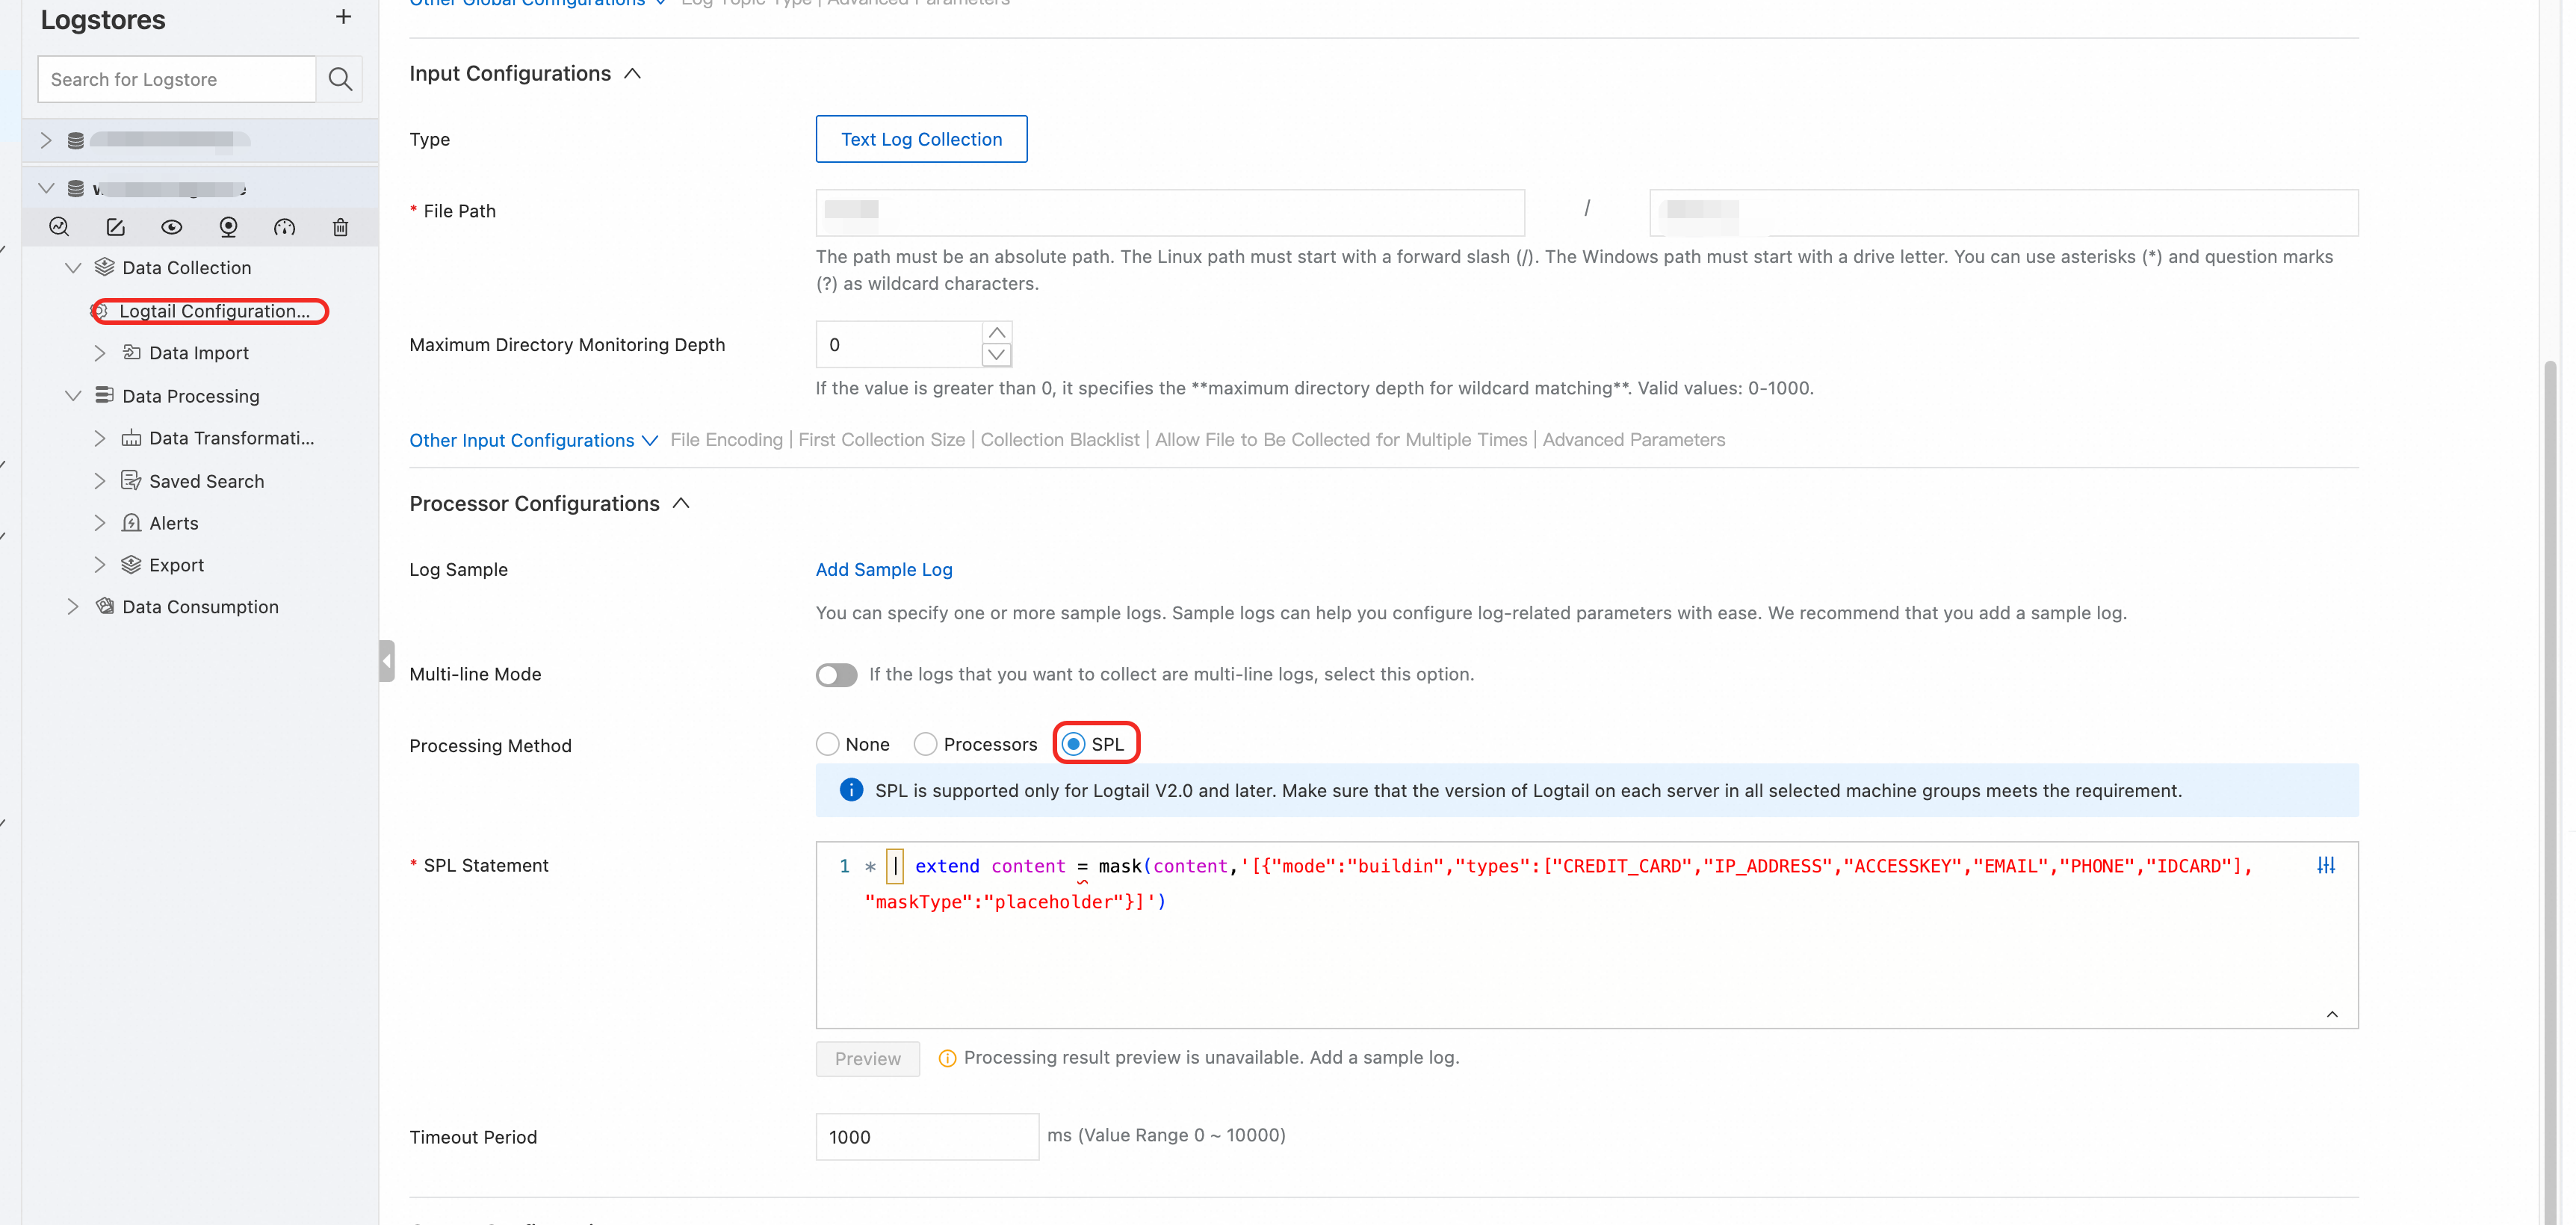
After the data is written to Simple Log Service, logs can still be used for model call volume, token usage, and gateway access trend analysis, but the sensitive values have been replaced:

This approach applies to application logs, gateway logs, model proxy logs, and other host/container-side data. No business code changes are required — processing is completed in the collection configuration, and logs are already in a masked form when written to Simple Log Service.
LoongSuite Pilot: mask AI Coding data before distribution
Another typical scenario for client-side protection is AI Coding auditing. Coding Agents running on developer machines frequently access project source code, configuration files, and local environment variables. When developers paste a configuration snippet in a question, or when an Agent reads a .env file and writes the content into tool calling parameters, API keys, cloud provider AK/SK pairs, and private keys can enter the collection pipeline.
LoongSuite Pilot targets these client-side AI Coding scenarios. It discovers and collects activity data from tools such as Claude Code, Cursor, Codex, and Qoder, and normalizes it into sessions, tool calling events, model invocations, token usage, and other audit events. Pilot has a built-in rule-based automatic masking engine that scans and replaces sensitive content before data is distributed to any output channel. Once enabled, masking rules take effect uniformly regardless of whether data is output to Simple Log Service, JSONL, HTTP, or OTLP.
Pilot automatic masking covers the following common credential types:
| Masking type | Coverage | Replacement marker |
Cloud AccessKey | Alibaba Cloud LTAI, AWS AKIA/ASIA, Tencent Cloud AKID | [ACCESSKEY_MASKED] |
| API key | OpenAI-compatible sk-, GitHub PAT ghp_/gho_/ghs_ | [APIKEY_MASKED] |
| Database connection string | MySQL/PostgreSQL/MongoDB/Redis URI, JDBC with password | [DATABASEURL_MASKED] |
| Private key | PEM / OpenSSH private key blocks | [PRIVATEKEY_MASKED] |
For example, during an AI Coding session, an Agent reads a local .env file and produces the following tool return:
DB_URL=mysql://root:Abc@2025!@10.0.0.12:3306/prod
ALIYUN_AK=<REDACTED_AK>
-----BEGIN RSA PRIVATE KEY-----
MIIEvQIBADANBgkqh...
-----END RSA PRIVATE KEY-----
After Pilot completes automatic masking before output, the content written to Simple Log Service becomes:
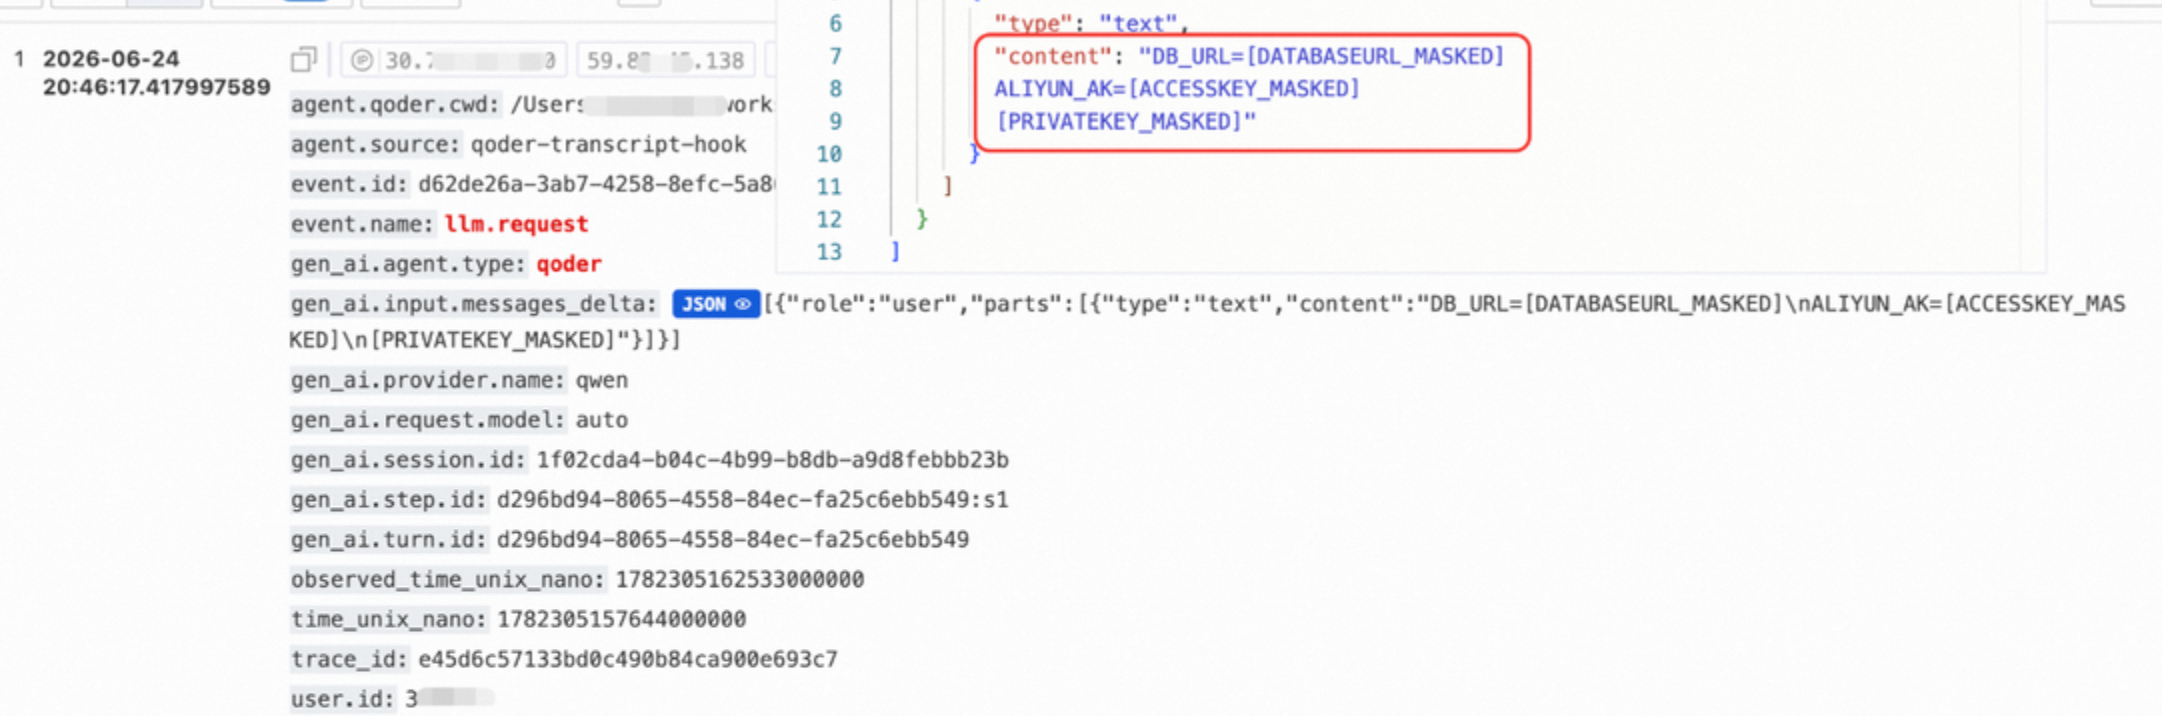
Masking is controlled by the mask.mode configuration switch, which supports three modes: none, all, and custom. It is disabled by default. Once enabled, sensitive credentials are not passed as-is to downstream output channels, while session_id, tool_name, token usage, execution duration, and other audit metadata are preserved. R&D management and security teams can continue to analyze AI Coding usage patterns, tool calling risks, and cost distribution.
Client-side protection therefore suits the following three typical scenarios:
Plaintext must not leave the business host or developer machine.
The collection pipeline crosses networks or teams, and plaintext transmission risk is unacceptable.
You want to push sensitive data protection to the first station of log generation without modifying business code.
Pre-ingestion protection: centralized governance for direct-write data before storage
Not all data passes through LoongCollector. Many systems write directly to Simple Log Service through SDKs, web tracking, OpenAPI, or third-party collection pipelines. For this data, write processors provide server-side centralized governance: after data arrives at Simple Log Service and before it is written to a LogStore, SPL is executed to complete masking or encryption.
Write processor rules are placed on the Simple Log Service side, and clients do not need to be upgraded individually. When processing policies change, adjust the processor configuration to cover all direct-write data. For scenarios involving multiple business lines, multi-language SDKs, or third-party system reporting, this approach is easier to implement.
Using AI gateway access logs as an example, the gateway concatenates each model call into a single line separated by ## and writes it directly to Simple Log Service. The request field is the complete model request body and may contain user prompts, ID card numbers, and other arbitrary sensitive content. The remaining fields are structured call metadata:
2026-06-25 11:17:25.471##c9d7ab4c-b312-9d08-9243-c7f7475905be##5000000276111136##API_KEY##qwen-max##text-generation##{"input":{"prompt":"My ID card number is 530102********011X, help me check my insurance policy status"}}##chat-app##3de69809a9d0fd22773f33c77dab12a8The request field here is an unstructured request body. This example uses symmetric encryption on the request field to demonstrate how write processors uniformly process direct-write data before ingestion: first split the fields by separator, then execute aes_encrypt on the highly sensitive body.
Encrypt the highly sensitive request body in the write processor
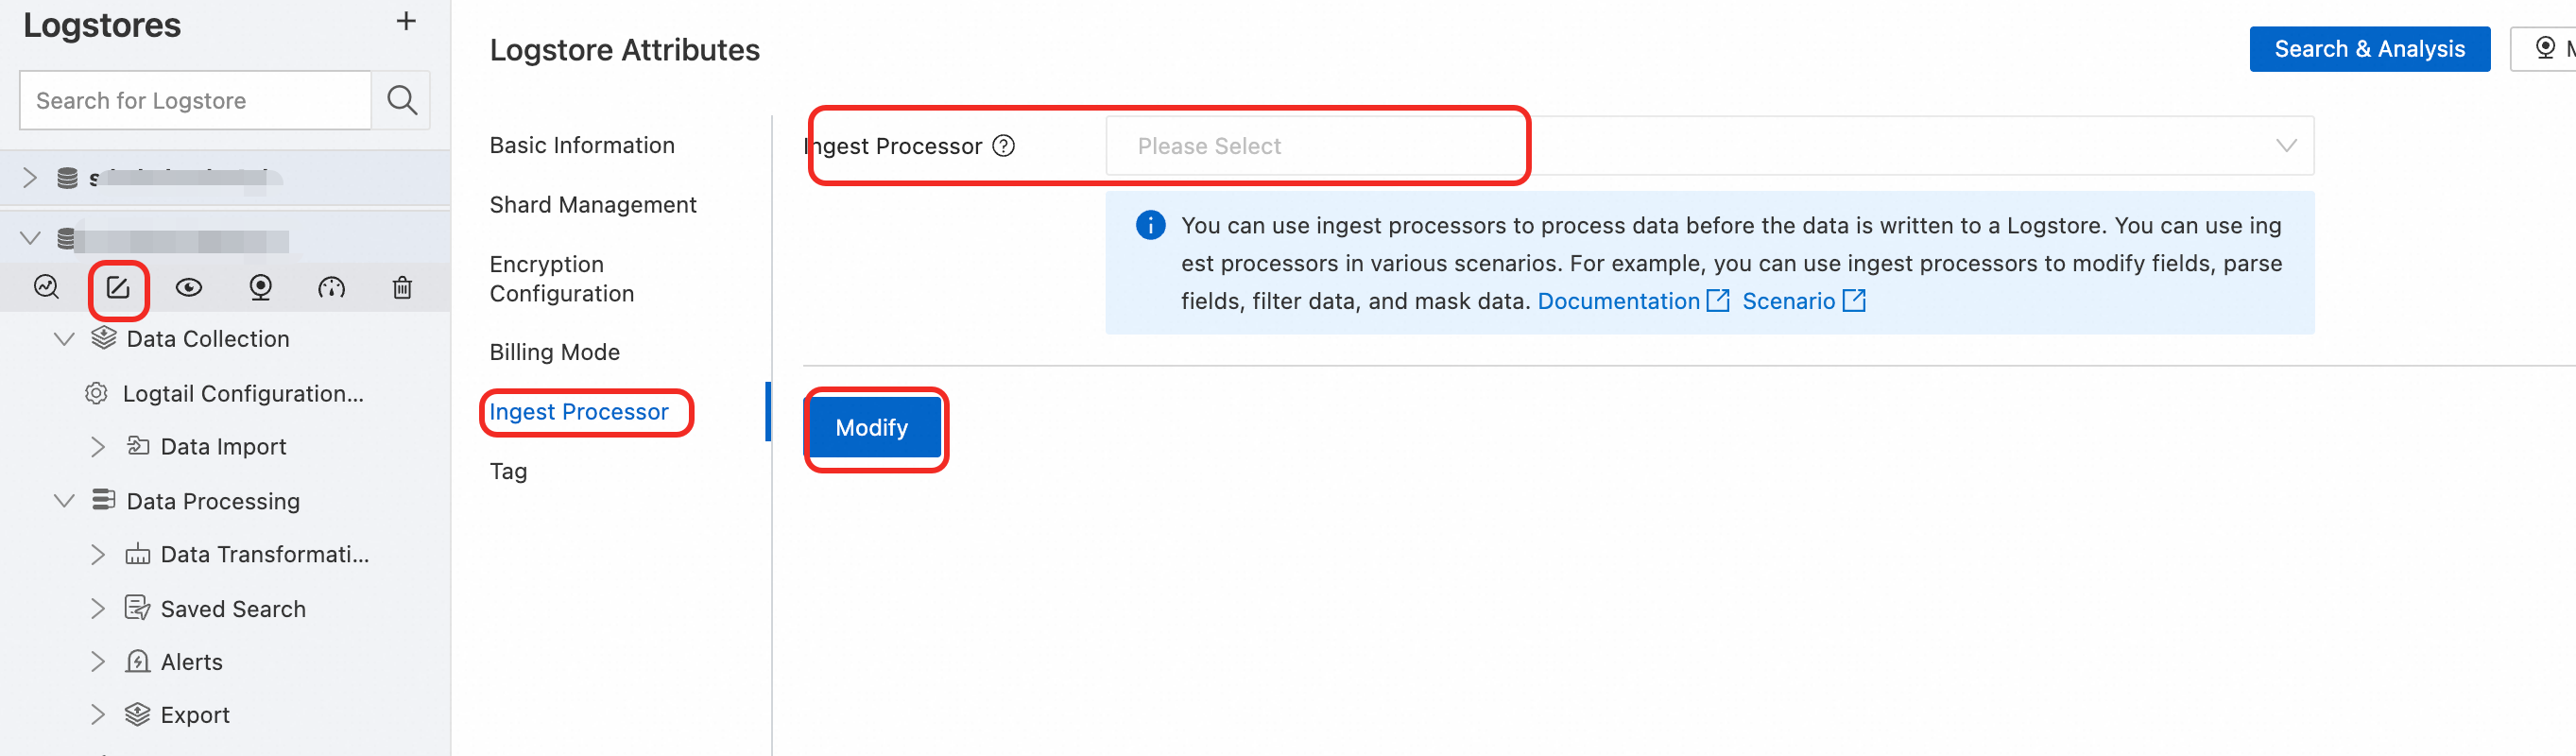
Write processor SPL configuration:
* | extend temp = split(content, '##')
| extend time          = temp[1],
           request_id    = temp[2],
           caller_uid    = temp[3],
           source        = temp[4],
           model         = temp[5],
           api_type      = temp[6],
           request       = temp[7],
           service_name  = temp[8],
           trace_id      = temp[9]
| extend request = to_base64(aes_encrypt(
        cast(request as binary),
        cast('aZ4kP9mX2qL7nR1t' as binary),
        cast('Gh8dW3sB6vN0cT5e' as binary)))
| project-away content, temp
After ingestion, the request field becomes Base64 ciphertext, while request_id, region, model, service_name, trace_id, and other call metadata remain in plaintext:
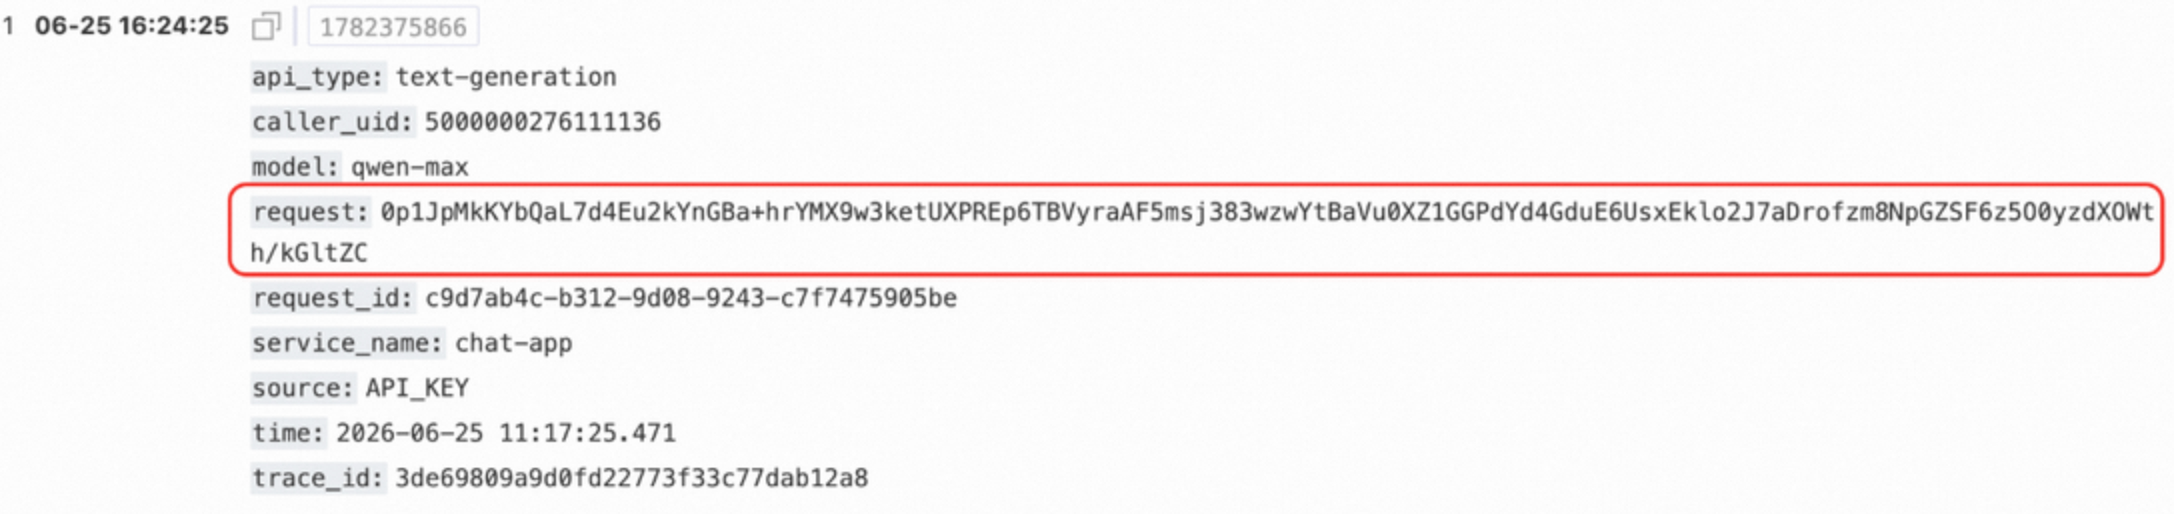
Operations teams can use request_id and trace_id to trace the call chain, business teams can generate call volume statistics by model and service_name, and the actual request body is already ciphertext.
Restore on demand in authorized scenarios
When restoration is needed, a team member who holds the Key + IV decrypts at query time using aes_encrypt:
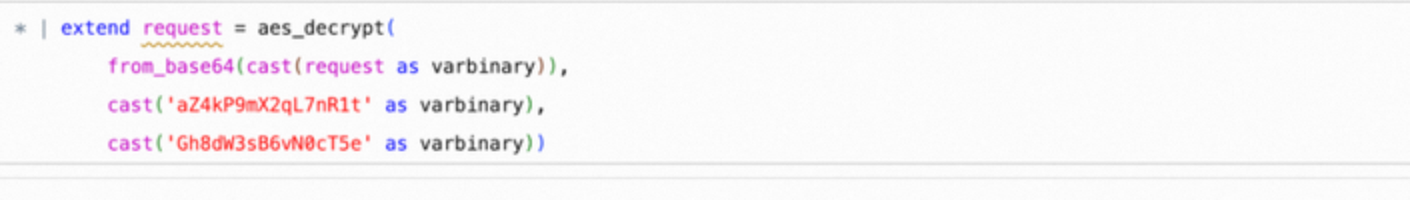
Post-ingestion data transformation: generate secure datasets for shared analysis
Client-side processing and write processors address "pre-ingestion protection". Data transformation addresses a different problem: how to reorganize data that has already entered a LogStore into a more secure dataset suitable for long-term analysis.
In practice, many teams maintain two LogStores:
Raw LogStore: short retention period, strict access permissions, used only for emergency troubleshooting or security investigations.
Protected LogStore: generated by a data transformation job, with sensitive fields masked or encrypted, longer retention period, and available for broader analysis and auditing.
This pattern is particularly suitable for AI observability data. Using AI Coding (such as Qoder) activity logs collected byLoongSuite Pilotas an example, eachllm.responseevent carries a set of structured metadata (session ID, model, user ID, etc.) and agen_ai.output.messagesfield — the complete text of the model response for that turn, which may contain arbitrary sensitive content such as internal system names, host information, configurations, or keys:
{
  "event.name": "llm.response",
  "gen_ai.session.id": "58bf461a-285f-468e-963c-00cd1706a9d9",
  "gen_ai.provider.name": "qwen",
  "gen_ai.response.model": "auto",
  "user.id": "1",
  "gen_ai.output.messages": "[{\"role\":\"assistant\",\"parts\":[{\"type\":\"text\",\"content\":\"Candidate salary table prepared: Zhang (phone number 138xxxxxxxx)...\"}],\"finish_reason\":\"end_turn\"}]",
  "trace_id": "a58ed78ac2573159b4fa8b38ab4c2697",
  "__time__": "1782367255"
}
The gen_ai.output.messages field is an unstructured model response of variable format. Field-by-field masking is difficult to cover all risks, yet the original text may need to be restored for in-depth investigation. This example uses envelope encryption to demonstrate how data transformation first derives analysis fields (here, the response length msg_len) and then encrypts the highly sensitive body before writing to the protected LogStore:
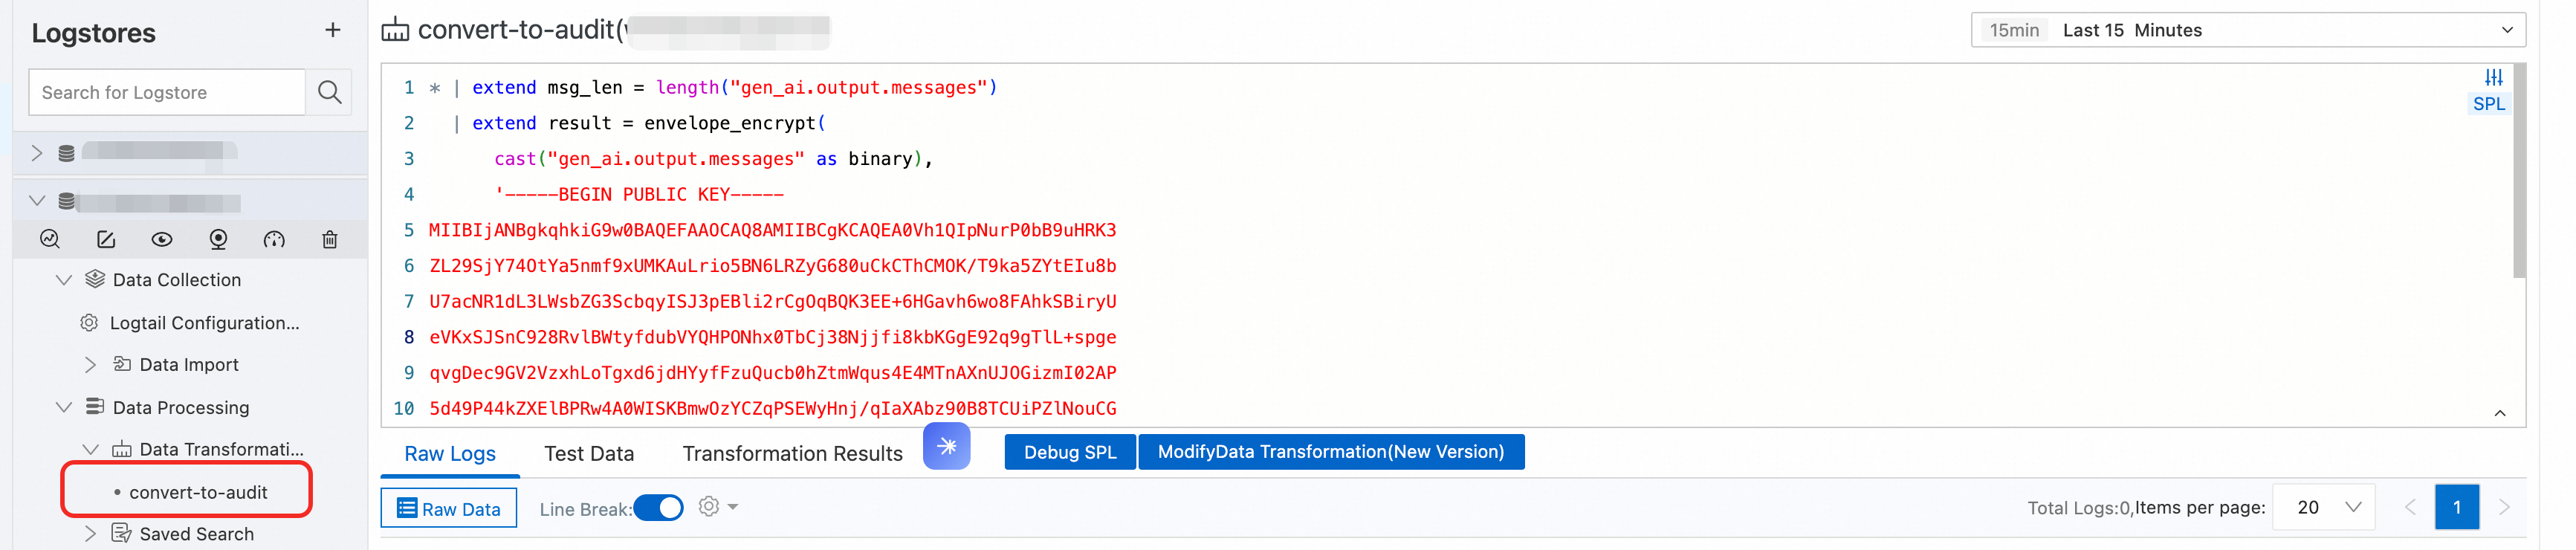
* | extend msg_len = length("gen_ai.output.messages")
| extend result = envelope_encrypt(
      cast("gen_ai.output.messages" as binary),
      '-----BEGIN PUBLIC KEY-----
MIIBIjANBgkqhkiG9w0BAQEFAAOCAQ8AMIIBCgKCAQEA0Vh1QIpNurP0bB9uHRK3
ZL29SjY74OtYa5nmf9xUMKAuLrio5BN6LRZyG680uCkCThCMOK/T9ka5ZYtEIu8b
U7acNR1dL3LWsbZG3ScbqyISJ3pEBli2rCgOqBQK3EE+6HGavh6wo8FAhkSBiryU
eVKxSJSnC928RvlBWtyfdubVYQHPONhx0TbCj38Njjfi8kbKGgE92q9gTlL+spge
qvgDec9GV2VzxhLoTgxd6jdHYyfFzuQucb0hZtmWqus4E4MTnAXnUJOGizmI02AP
5d49P44kZXElBPRw4A0WISKBmwOzYCZqPSEWyHnj/qIaXAbz90B8TCUiPZlNouCG
TwIDAQAB
-----END PUBLIC KEY-----',
      '{"mode":"RSA"}',
      '{"mode":"CTR"}')
| extend encrypted_dek = result['encrypted_dek'],
           enc_output_messages = result['encrypted_data']
| project-away "gen_ai.output.messages"
After data transformation writes to the protected LogStore, gen_ai.output.messages has been removed and replaced by the ciphertext enc_output_messages and the public-key-encrypted encrypted_dek. All other metadata remains in plaintext:
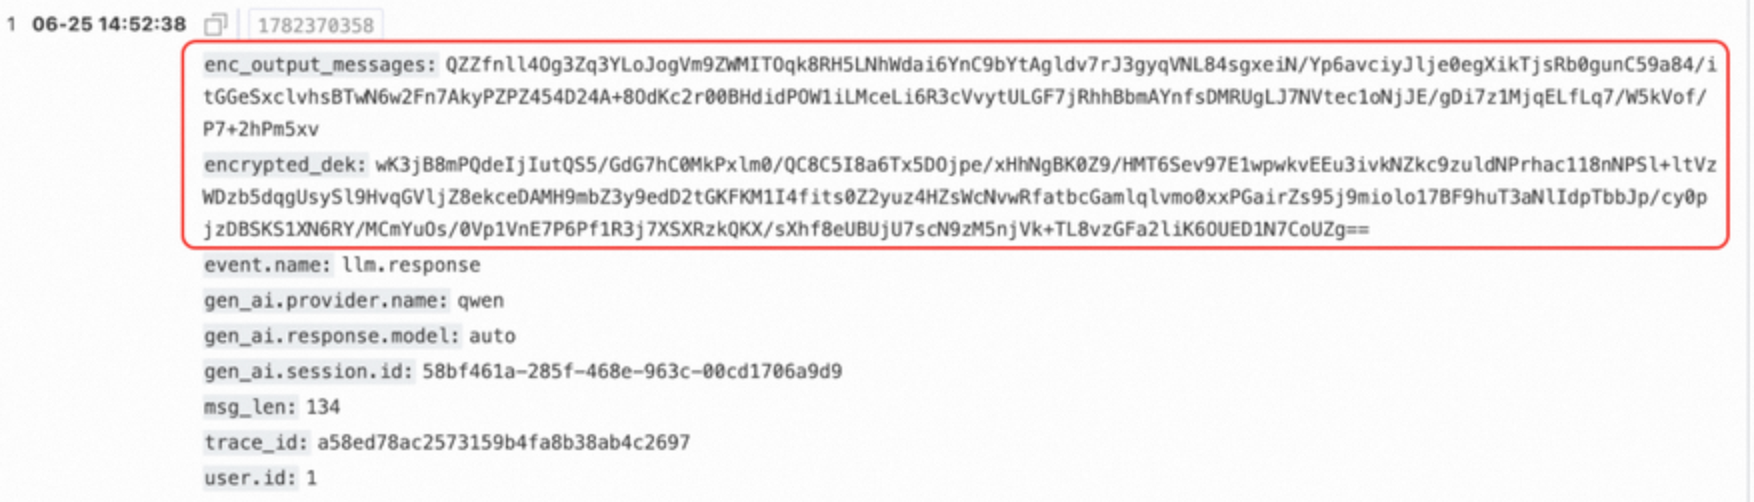
With this approach, the protected LogStore retains the event type, session ID, model, user ID, response length, and other analysis fields for alerting, trend analysis, and risk investigation. The actual model response body has become ciphertext. When an in-depth investigation is needed, security personnel with the private key decrypt the specified records.
Do not encrypt all fields indiscriminately. Instead, extract the necessary analysis metadata before encryption, and encrypt only the highly sensitive body. Day-to-day analysis then relies on metadata, while sensitive original text is accessed through authorized decryption under controlled conditions.
Selection guide: consider plaintext boundaries, analysis requirements, and decryption permissions
Make your selection based on three questions during implementation.
First, can plaintext leave the collection side? If not, prioritize processing at the client side.
Second, do logs still need to be read and analyzed on a daily basis? If so, prioritize preserving readability. Consider encryption only when the content is highly sensitive overall and reliable partial processing is not feasible.
Third, who has decryption permission? Within the same team or security domain, keys can be managed centrally. In cross-team or separation-of-duties scenarios, decryption permissions should be independently held by the security or audit team.
The strategy is summarized in the following table:
| Scenario | Recommended stage | Recommended method |
| AI gateway logs on hosts/containers where plaintext must not leave the host | LoongCollector client-side | mask for masking, encrypt critical fields as needed |
SDKs or third-party systems write directly to Simple Log Service | Write processor | mask or encrypt before ingestion |
| Existing historical logs require remediation | Data transformation | Consume from the source LogStore, then mask/encrypt and write to a new LogStore |
| Internal RAG Q&A content that needs controlled restoration | Client-side or write processor | aes_encrypt symmetric encryption |
| Entire highly sensitive content such as tool returns and configuration files | Client-side or data transformation | envelope_encrypt envelope encryption |