Troubleshoot container log collection issues
If you have issues collecting logs from standard or Kubernetes containers with Logtail, use this topic to troubleshoot the problem, check the running status, and perform other maintenance operations.
Check the machine group heartbeat
If the Machine Groups list in the Simple Log Service console shows zero machine groups, or if you cannot select a source machine group when you create a Logtail configuration after you install the log plugin (LoongCollector or Logtail-ds) in an ACK or ACS cluster, check the machine group heartbeat in the following order. A machine group uses a UID, such as the Alibaba Cloud account ID, as its custom ID. Each server in the machine group reports an IP address to the Simple Log Service backend.
-
Check the project: A machine group is visible only in the project to which it belongs and cannot be accessed across projects. The project that is automatically created for an ACK or ACS cluster is usually named in the
k8s-log-${cluster_id}format. Make sure that you have opened this project, and look for the machine group in the same project. -
Check the component installation status: On the cluster details page of the ACK console, choose Component Management and verify that the LoongCollector or Logtail-ds component is installed and running. If the installation failed, reinstall the component as prompted.
-
Check permissions and verify manually: Make sure that the current account has the permissions to view machine groups in this project. Go to Simple Log Service Console > Resources > Machine Groups and check whether a machine group named
k8s-group-${cluster_id}exists. The machine group configuration uses a custom ID to identify the cluster. Make sure that the custom ID in the machine group matches the one in the Logtail collection configuration. If the machine group does not exist, reinstall the log component in the ACK cluster.
Check the machine group heartbeat to verify that Logtail is installed correctly in your containers.
-
Check the heartbeat status of the machine group.
Log on to the Simple Log Service console.
In the Projects section, click the one you want.
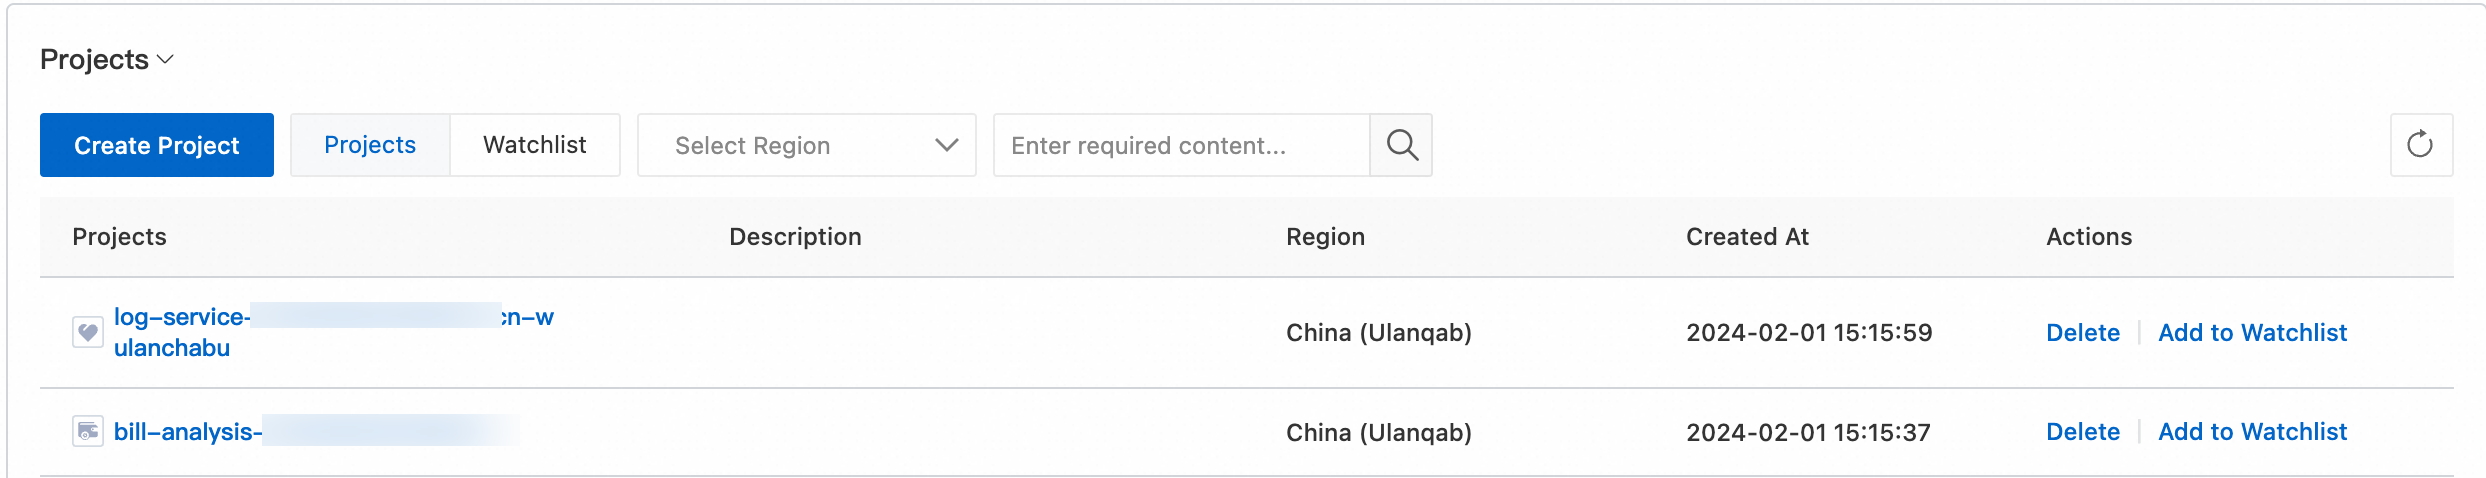
-
In the left-side navigation pane, choose .
-
In the list of machine groups, click the target machine group.
-
Click Check Status in the Actions column of the machine group. In the View Machine Group Status dialog box, view the heartbeat status and note the number of nodes with an OK heartbeat status.
-
Check the number of worker nodes in the container cluster.
-
Run the following command to view the number of worker nodes in the cluster.
kubectl get node | grep -v masterThe output is similar to the following:
NAME                                 STATUS    ROLES     AGE       VERSION
cn-hangzhou.i-bp17enxc2us3624wexh2   Ready     <none>    238d      v1.10.4
cn-hangzhou.i-bp1ad2b02jtqd1shi2ut   Ready     <none>    220d      v1.10.4
-
Compare the number of nodes with an OK heartbeat status to the number of worker nodes in the container cluster. Troubleshoot the issue based on the result.
-
The heartbeat status of all nodes in the machine group is Failed.
-
If you collect logs from standard Docker containers, see Collect logs from Docker containers (standard output and files) to verify that the
${your_region_name},${your_aliyun_user_id}, and${your_machine_group_user_defined_id}parameters are correct. -
If you use a self-managed Kubernetes cluster, see Collect text logs from Kubernetes containers by using a sidecar to verify that the
{regionId},{aliuid},{access-key-id}, and{access-key-secret}parameters are correct.If the parameters are incorrect, run the
helm del --purge alibaba-log-controllercommand to delete the installation package, and then reinstall it.
-
-
The number of nodes with an OK heartbeat status is less than the number of worker nodes in the cluster.
-
Check whether a DaemonSet was manually deployed by using a YAML file.
-
Run the following command. If a result is returned, it means a DaemonSet was manually deployed by using a YAML file.
kubectl get po -n kube-system -l k8s-app=logtail -
Set parameters such as ${your_region_name}, ${your_aliyun_user_id}, and ${your_machine_group_name} to their actual values.
-
Run the following command to apply the updated file.
kubectl apply -f ./logtail-daemonset.yaml
-
-
-
FAQ: Why is there no heartbeat after deploying Docker/LoongCollector?
If LoongCollector or Logtail shows no heartbeat or fails to register with the machine group after Docker deployment, the root cause is usually a missing user identifier (AliUID) configuration.
Solution:
-
On the host machine, create the
/etc/ilogtail/users/directory.mkdir -p /etc/ilogtail/users/ -
In the
/etc/ilogtail/users/directory, create an empty file named after your Alibaba Cloud account ID.touch /etc/ilogtail/users/<your-alibaba-cloud-account-id> -
When starting the LoongCollector or Logtail container, mount the directory as read-only by adding the following flag:
-v /etc/ilogtail/users:/etc/ilogtail/users:ro -
Restart the LoongCollector or Logtail container.
Verification: Log on to the SLS console, go to Resources > Machine Groups, and find the target machine group. Click Check Status in the Actions column. In the View Machine Group Status dialog box, confirm that the heartbeat status of the machine group has changed to OK.
FAQ: Why does the machine group show only one server when multiple Docker Swarm servers are reporting the same IP?
Cause: In a Docker Swarm cluster, multiple servers may report the same internal IP address through the container network. If those servers also share the same ALIYUN_LOGTAIL_USER_DEFINED_ID environment variable value, the system cannot distinguish between them, and the Machine Groups displays only one entry.
Solution 1: Set a unique ALIYUN_LOGTAIL_USER_DEFINED_ID environment variable for the Logtail container on each server.
Set a different value on each server and ensure the value matches the corresponding Machine Groups configuration. For example:
-e ALIYUN_LOGTAIL_USER_DEFINED_ID=<unique-id-for-this-server>Solution 2: Set the ALIYUN_LOGTAIL_WORKING_IP environment variable to manually specify a unique IP address for each server.
Use a value that uniquely identifies each host, such as the host's public IP address or an internal network IP address that is unique across all servers:
-e ALIYUN_LOGTAIL_WORKING_IP=<unique-ip-for-this-server>Troubleshoot container log collection
If you cannot find any logs on the Preview page or the Logstore query page in the Simple Log Service console, Simple Log Service may not be collecting your container logs. Check the container status and then perform the following checks.
-
When you collect logs from files in containers, take note of the following items:
-
After you apply a Logtail configuration, Logtail does not collect logs from a file unless the file is updated. For more information, see Read logs.
-
Logtail can collect logs only from files that are stored in the default container storage or mounted to a local path. Other storage methods are not supported.
-
-
After logs are collected, you must create an index to query and analyze them in the Logstore. For more information, see Create an index.
-
Check for machine group heartbeat issues. For more information, see Check the machine group heartbeat.
-
Check whether the Logtail configuration is correct.
Check whether the IncludeLabel (Label Whitelist), ExcludeLabel (Label Blacklist), IncludeEnv (Environment Variable Whitelist), and ExcludeEnv (Environment Variable Blacklist) settings in the Logtail configuration meet your log collection requirements.
Note-
The labels specified here are container labels from the
docker inspectoutput, not Kubernetes labels. -
You can temporarily remove the IncludeLabel (Label Whitelist), ExcludeLabel (Label Blacklist), IncludeEnv (Environment Variable Whitelist), and ExcludeEnv (Environment Variable Blacklist) settings to check whether logs can be collected. If logs are collected, the parameter settings are incorrect.
NoteIf you are using a self-managed Docker node (non-Kubernetes) with a legacy Logtail configuration, note the following:
-
The
_container_name_field does not support regular expression matching for multiple values. You cannot use a single regular expression to filter multiple specific container names. -
If you need to collect logs from multiple specific containers (for example, containers named
aandb), create two separate Logtail configurations, each with its own allowlist, and bind both to the same Machine Groups. -
Duplicate label names in a single Logtail configuration are not recognized. If you need to match different values for the same label name, use a regular expression or create multiple independent Logtail configurations.
NoteFields such as
_image_nameand_container_name_that are shown on the preview or query page of the Simple Log Service console are container metadata preview fields, not container labels. You cannot use them directly as IncludeLabel (whitelist) or ExcludeLabel (blacklist) filter values. Filter values support regular expression matching. To filter based on container labels, run the following command on the node where the container runs to obtain the actual container labels:docker inspect <container_id> --format='{{json .Config.Labels}}'The output is similar to the following:
{"com.docker.compose.service":"my-svc","maintainer":"..."}Use the actual label key-value pairs in the output, for example,
com.docker.compose.service=my-svc, as the IncludeLabel or ExcludeLabel values in the Logtail configuration. -
Machine group does not cover all container nodes
Symptom: The machine group heartbeat is normal, but log collection from some containers has stopped.
This issue may occur when the containers are running on servers that are not included in the Machine Groups.
Troubleshooting steps:
-
On all relevant servers, run the following command to identify which nodes the containers are actually running on:
docker ps -a | grep <container-name> -
If a container is running on a server that has not been added to the machine group, add the IP address of that server to the Machine Groups in the SLS console.
FAQ: Why can't I find the Pod in the container metadata preview, or why can't logs be collected from emptyDir?
Cause: Logtail running in DaemonSet mode cannot directly access the emptyDir temporary storage inside a container. This prevents Logtail from reading log files and extracting container metadata, so the Pod cannot be found in the container metadata Preview.
Solution 1 (Recommended): Redirect application log output to standard output (stdout/stderr).
-
Modify your application to write logs to stdout or stderr instead of files.
-
In the SLS console, configure the collection path to use the standard Kubernetes log path:
/logtail_host/var/log/pods/<namespace>_<pod-name>-<uid>/<container-name>/*.log
Solution 2: If your application must write logs to files, change the log volume mount from emptyDir to a hostPath or PVC.
-
In your Pod specification, replace the
emptyDirvolume with ahostPathor PVC definition so that logs are persisted at a path accessible from the host. -
Adjust the SLS collection path to point to the actual mount path on the host, for example:
/logtail_host/var/log/your-app/*.log
FAQ: How do I handle file creation failures or permission errors when collecting container logs?
Symptom: An error message indicates that Logtail needs to create a specific empty file inside the container, but file creation fails or a permission error is reported.
Solution:
-
Manually create the empty file specified in the error message inside the container.
-
Set the file permissions to
-rw-r--r--(644):chmod 644 <file-path> -
Restart the container.
Alternative: If the issue persists after the steps above, mount the container log directory to the host machine and configure SLS to collect logs from the corresponding host path. This approach is more stable than in-container file collection.
FAQ: How do I handle the error "parse cri docker line error: invalid CRI log, timestamp not found"?
Cause: Log parsing fails. This error is commonly caused by an incorrect multiline log configuration.
Solution:
-
Check and adjust the start-of-line regular expression, or disable multiline mode:
-
In the YAML configuration: Comment out the
multilineconfiguration section. -
In the SLS console: Open the Logtail configuration and disable multiline mode.
-
-
Verify that the K8s Namespace Regex and other format fields are correct. If you need to specify multiple namespaces, ensure they are separated by the correct delimiter.
-
After modifying the YAML configuration, reapply it to make the changes take effect:
kubectl apply -f <your-config-file>.yaml
FAQ: What do I do if a red exclamation mark appears next to the JSON parse plugin and the Logtail configuration cannot be saved?
Symptom: After you add a JSON parse plugin to a Logtail configuration, a red exclamation mark appears next to the plugin icon, and the configuration cannot be saved in the dialog box.
Cause: The red exclamation mark usually indicates that the plugin is not configured, or that the configuration is changed but not applied.
Solution:
-
On the Logtail configuration edit page, delete the JSON parse plugin that is added by default.
-
Manually add a JSON parse plugin again and complete all required fields, such as the log sample and parsing rules.
-
After the configuration is complete, the red exclamation mark disappears and you can save the Logtail configuration.
Adding a time parse plugin after the JSON parse plugin is a standard practice. You can use the time parse plugin to extract the time field from the log content as the log time.
FAQ: What do I do if no data is collected because multiple Logtail configurations match the same file (MULTI CONFIG MATCH ALARM)?
Symptom: The MULTI CONFIG MATCH ALARM alert appears in the Logtail operational logs, and no data is collected from the target file.
Cause: By default, a log file can match only one Logtail configuration. When multiple Logtail configurations match the same file, only one of them takes effect. The other configurations cannot collect data and trigger the MULTI CONFIG MATCH ALARM alert.
Solution:
-
Delete redundant Logtail configurations: In the Simple Log Service console, check all Logtail configurations that are bound to the Machine Groups. Delete duplicate or unused configurations so that each file is matched by only one configuration.
-
Split matching by pod name: If you need multiple configurations for the same file, for example, to split collection by pod name, modify the configurations as described in the official documentation. Make sure that each Logtail configuration matches only its own target file through a more precise path or label filter, and avoid overlapping paths.
-
After the modification, check the Logtail operational logs and confirm that the MULTI CONFIG MATCH ALARM alert disappears and that data is collected as expected.
FAQ: How do I handle the Logtail error no such file or directory when collecting container logs?
Symptom: The Logtail operational logs contain the no such file or directory error, and the target container logs cannot be collected. Make sure that an index is created for the LogStore so that logs can be queried and analyzed after collection.
Cause: The target collection path does not exist on the node. This issue is usually related to the Kubernetes pod lifecycle or the log rotation mechanism.
Solution:
-
Check whether the pod still exists: If the pod has been deleted, the corresponding log path no longer exists and you can ignore the error. If the pod is still running, log on to the server (node) and check whether the actual log path exists.
-
Use container stdout collection when possible: When you create a log collection configuration in the ACK console, select the Container Stdout type and match the target container by container label or container name, instead of relying on the container-internal file path.
-
Configuration suggestions when file collection is required: Use a wildcard path, for example,
/logtail_host/var/log/pods/*/*.log, and enable the automatic discovery of new files in the Logtail configuration so that Logtail can track new paths after log rotation or pod recreation. -
Verify that the Logtail configuration is applied to the machine group: Make sure that the Logtail configuration is bound to the Machine Groups that contains the target pod.
-
Check the Logtail operational logs: If a large number of errors are concentrated on pods that have already been destroyed, you can ignore them. If the errors persist and the pod is still running, correct the collection path or check the node mount.
FAQ: How do I handle collection interruption caused by Logtail skipping files due to logfiletoobig?
Symptom: The logfiletoobig alert appears in the Logtail operational logs, the target file is skipped, and log collection is interrupted.
Cause: The size of the target log file exceeds the default limit of Logtail. Logtail skips the file to protect its stability.
Solution:
-
Adjust the Logtail collection parameters: In the Logtail configuration or in the global parameters of the Machine Groups, make the following changes:
-
Increase
MaxLogFileSize, for example, to1GB, to prevent large files from being skipped. -
Increase
MaxLogFileInodeCacheSize, for example, to2000, to improve the tracking of rotated files. -
Set
EnableContainerDiscoverytotrueso that Logtail can automatically discover container log paths and automatically create tracking entries for new pods.
-
-
Trigger a rescan: In the ACK cluster, run the following command to delete the loongcollector-ds (or Logtail-ds) pod. The DaemonSet automatically recreates the pod and rescans all container log paths:
kubectl delete pod -n kube-system -l k8s-app=loongcollector-ds -
Verify the result or use an alternative: Check the log reception status in the Simple Log Service console and check whether residual errors remain in the Logtail pod. If the preceding methods do not work, try the K8s-Stdout-New configuration and enable the container metadata preview to collect logs through the stdout path instead of the file path.
Supplementary troubleshooting for ACK
In an ACK cluster, if log collection still returns no data after the preceding checks, check the following two items:
-
Check the ACK CRD collection configuration: Run the following command to view the CRD collection configurations of the ACK cluster:
kubectl get ClusterAliyunPipelineConfig -AVerify that the LogStore and collection rules in the output match your expectations.
-
Check the volume declaration of the container image: Run the
docker inspectcommand on the container image and check theConfig.Volumesfield:docker inspect <image-name> | grep -A5 VolumesIf
Config.Volumesis not empty, the image declares aVOLUMEthat may overwrite the log file path. Remove theVOLUMEdeclaration or mount the volume toemptyDir.
Other maintenance operations
Log on to a Logtail container
-
Standard Docker
-
On the host, run the following command to find the Logtail container.
docker ps | grep logtailThe output is similar to the following:
223****6e registry.cn-hangzhou.aliyuncs.com/log-service/logtail "/usr/local/ilogta..." 8 days ago Up 8 days logtail-iba -
Run the following command to start a bash shell in the Logtail container.
docker exec -it 223****6e bashReplace
223****6ewith the actual container ID.
-
-
Kubernetes
-
Run the following command to find the Logtail pod.
kubectl get po -n kube-system | grep logtailThe output is similar to the following:
logtail-ds-****d 1/1 Running 0 8d logtail-ds-****8 1/1 Running 0 8d -
Run the following command to log on to the pod.
kubectl exec -it -n kube-system logtail-ds-****d -- bashReplace
logtail-ds-****dwith the actual pod ID.
-
View Logtail runtime logs
Logtail stores its logs in the /usr/local/ilogtail/ directory of the Logtail container. The log files are ilogtail.LOG and logtail_plugin.LOG.
-
Log on to the Logtail container. For more information, see Log on to a Logtail container.
-
Go to the /usr/local/ilogtail/ directory.
cd /usr/local/ilogtail -
View the ilogtail.LOG and logtail_plugin.LOG files.
cat ilogtail.LOG
cat logtail_plugin.LOG
Logtail container standard output (stdout)
The standard output of a Logtail container does not provide useful information for troubleshooting. You can ignore the following content.
start umount useless mount points, /shm$|/merged$|/mqueue$
umount: /logtail_host/var/lib/docker/overlay2/3fd0043af174cb0273c3c7869500fbe2bdb95d13b1e110172ef57fe840c82155/merged: must be superuser to unmount
umount: /logtail_host/var/lib/docker/overlay2/d5b10aa19399992755de1f85d25009528daa749c1bf8c16edff44beab6e69718/merged: must be superuser to unmount
umount: /logtail_host/var/lib/docker/overlay2/5c3125daddacedec29df72ad0c52fac800cd56c6e880dc4e8a640b1e16c22dbe/merged: must be superuser to unmount
......
xargs: umount: exited with status 255; aborting
umount done
start logtail
ilogtail is running
logtail status:
ilogtail is running
Check Kubernetes component status
Run the following command to view the status and information of the Simple Log Service deployment.
kubectl get deploy -n kube-system | grep -E 'alibaba-log-controller|loongcollector-operator'The following output is returned:
NAME                     READY   UP-TO-DATE   AVAILABLE   AGE
alibaba-log-controller   1/1     1            1           11d
Run the following command to view the status information of the DaemonSet resource.
kubectl get ds -n kube-system | grep -E 'logtail-ds|loongcollector-ds'The following output is returned:
NAME         DESIRED   CURRENT   READY   UP-TO-DATE   AVAILABLE   NODE SELECTOR  AGE
logtail-ds   2         2         2       2            2           **ux           11d
Logtail version, IP address, and startup time
-
On the host, run the following command to view the version, IP address, and startup time of Logtail.
The information is stored in the
/usr/local/ilogtail/app_info.jsonfile of the Logtail container.kubectl exec logtail-ds-****k -n kube-system cat /usr/local/ilogtail/app_info.jsonThe output is similar to the following:
{
   "UUID" : "",
   "hostname" : "logtail-****k",
   "instance_id" : "0EB****_172.20.4.2_1517810940",
   "ip" : "172.20.4.2",
   "logtail_version" : "0.16.2",
   "os" : "Linux; 3.10.0-693.2.2.el7.x86_64; #1 SMP Tue Sep 12 22:26:13 UTC 2017; x86_64",
   "update_time" : "2018-02-05 06:09:01"
}
Get troubleshooting information for Pod logs in an ACK cluster
If log collection for a Pod in an ACK cluster is abnormal, you can use the following steps to obtain the basic information needed for self-troubleshooting or for providing to technical support.
Step 1: Find the Logtail or LoongCollector Pod name.
kubectl get pods -n kube-system | grep loongcollectorStep 2: Get the IP address of the Logtail or LoongCollector instance from the app_info.json file.
kubectl exec <pod-name> -n kube-system cat /usr/local/ilogtail/app_info.jsonThe ip field in the returned JSON output is the Logtail instance IP address.
When seeking support, provide the following information to help with troubleshooting:
SLS Project name
Logtail collection configuration name
Target Pod name
Target container name
Handling accidentally deleted CRD Logstores
If you delete a Logstore automatically created by a Custom Resource Definition (CRD), the collected data is unrecoverable and the CRD configuration for the Logstore becomes invalid. To prevent log collection issues, choose one of the following solutions:
-
In the CRD configuration, use a different Logstore instead of the one that you deleted.
-
Restart the alibaba-log-controller pod.
Run the following command to find the pod.
kubectl get po -n kube-system | grep alibaba-log-controller
FAQ
FAQ: Does running docker pull to pull the LoongCollector or Logtail image affect other services on the host?
Conclusion: Running only the docker pull command to pull the LoongCollector or Logtail image does not affect other services that run on the host. This applies to both Alibaba Cloud ECS instances and on-premises servers. The docker pull command only downloads image layers to the local image repository. It does not start a container or consume additional CPU or memory resources.
Precautions:
-
When you later run
docker runto start a container, make sure that the host has sufficient CPU and memory resources so that the new container does not compete with existing workloads. -
Check whether the container port mapping conflicts with ports that are already used by existing services on the host.
-
If you want to run the log collection component in Kubernetes for the long term, install LoongCollector in DaemonSet mode through Component Management in the ACK console (Recommended). This allows the cluster to schedule resources in a unified manner.
FAQ: What do I do if the K8s-Stdout-New option is missing from the ACK cluster log access page in the Simple Log Service console?
Symptom: The K8s-Stdout-New entry is missing on the ACK cluster log access page of the Simple Log Service console.
Cause: The entry may be temporarily unavailable because the backend feature is taken offline for repair.
Solutions / Alternatives:
-
Use the legacy access method temporarily: In the console, select the legacy K8s-Stdout entry to complete the access. The legacy version has reached end of maintenance and should be used only as a temporary workaround.
-
Use a CRD instead of the console entry (Recommended): Use
kubectlin the cluster to create anAliyunPipelineConfigCRD to configure the new-version stdout collection, without relying on the console entry. Refer to the YAML example in the Container Stdout - New Version section of this document, replace the parameters with your actual project, LogStore, and cluster information, and then run the following command:kubectl apply -f aliyun-pipeline-config.yamlThis method is equivalent to the configuration created through the console and is easier to manage in a GitOps manner.