Spark/SparkSQL overview
When you use the Spark compute engine to access Tablestore, you can use E-MapReduce SQL or DataFrame programming to perform complex computations and efficiently analyze your data.
Scenarios
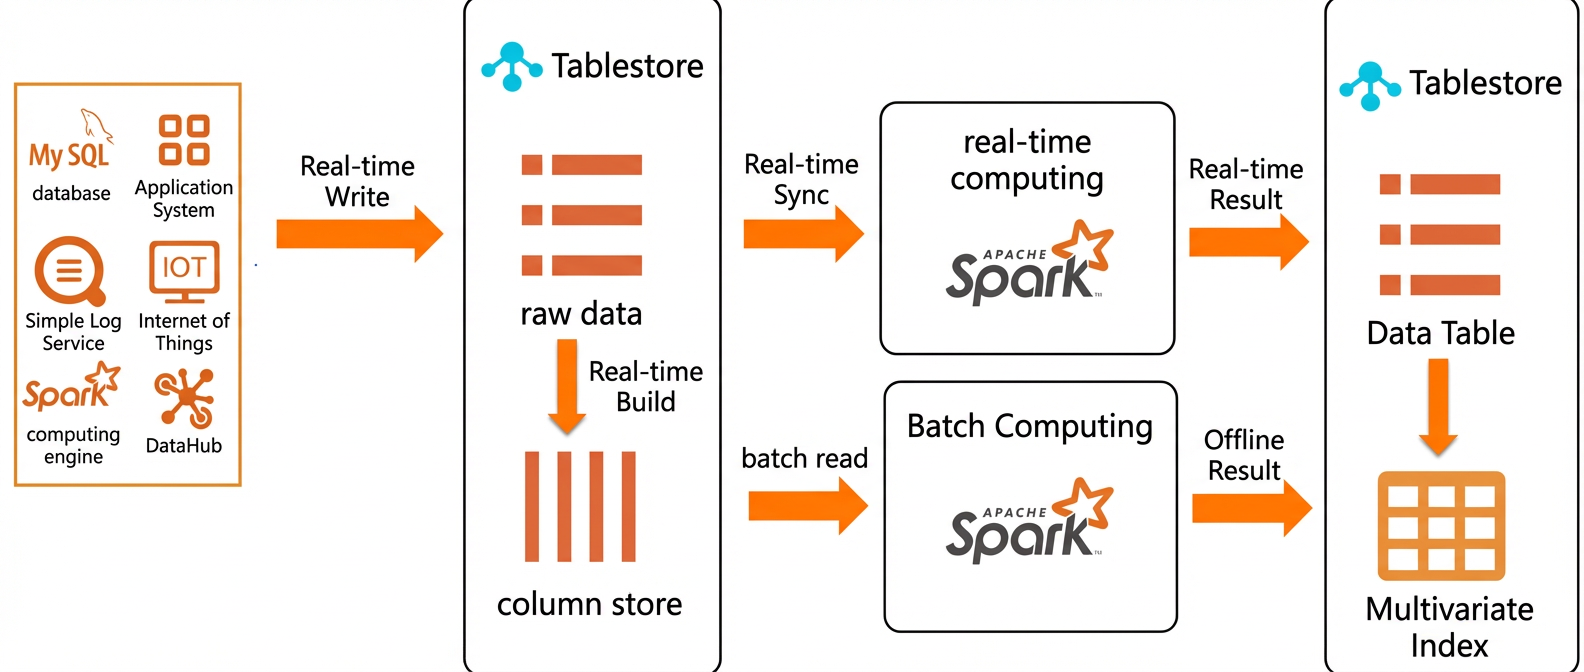
Features
For batch computing, Tablestore on Spark provides the following core optimization features:
-
Index selection: Selecting the right index is key to efficient data queries. Choose the best matching index based on your filter conditions to improve query efficiency. Tablestore provides global secondary indexes and search indexes.
NoteFor more information about global secondary indexes and search indexes, see A deep dive into massive structured data storage technology: Tablestore storage and indexing engines.
-
Table partition pruning: This feature matches logical partitions (Splits) with filter conditions and filters out invalid Splits. This reduces the amount of data transferred from the server-side.
-
Projection and filter pushdown: This feature pushes down projection columns and filter conditions to the server-side. This reduces the amount of data transferred from each partition.
-
Dynamic Split size specification: You can adjust the data volume and the number of partitions in each logical partition (Split). Each Split is attached to a Resilient Distributed Dataset (RDD) partition. This can speed up the execution of Spark tasks.
NoteYou can use the ComputeSplitsBySize API to obtain logical partitions (Splits). This API logically divides a full table into Splits of a specified approximate size. It returns the split points and location hints for the Splits. Compute engines typically use this information for execution planning, such as concurrency planning.
For stream computing, Tablestore on Spark uses Data Change Capture (CDC) technology based on Tunnel Service to implement mini-batch stream consumption and computation for Spark. It also provides at-least-once consistency semantics. In stream computing, each partition is attached to an RDD partition. By extending table partitions, you can achieve linear scaling of data throughput.
Scenario examples
Usage methods
You can choose between E-MapReduce SQL and DataFrame programming to access Tablestore with Spark, depending on your scenario.
-
E-MapReduce SQL method
This method uses standard SQL statements to operate on and access business data. It is easy to use and lets you seamlessly migrate existing business logic.
-
DataFrame method
This method requires some programming knowledge. However, it lets you combine components to implement complex business logic. It is suitable for complex and flexible scenarios.
Data access methods
Tablestore provides two data access methods for Spark batch computing: KV query on data tables or global secondary indexes, and search index query. These methods support fast reads and writes of massive structured data and provide rich query and analysis capabilities.
The differences between the two data access methods are as follows:
-
The KV query method is efficient when filter conditions are on primary key columns. However, it is not suitable for scenarios where filter conditions change frequently or involve many non-primary key columns. The KV query method does not support geo queries.
-
The search index query method is suitable for the following data access scenarios:
NoteSearch indexes are based on inverted indexes and columnar storage. They can solve complex query problems for big data. They provide query and analysis features similar to those of Elasticsearch, such as full-text search, fuzzy search, geo queries, and statistical aggregation.
-
Real-time data analytics scenarios with small data volumes and high latency requirements.
-
The filter conditions involve many non-primary key columns, and these columns are not included in the primary keys of the global secondary index or the data table.
-
The filter conditions are highly selective. A condition on a single column can filter out most of the data.
For example, in
select * from table where col = 1000;, `col` is a non-primary key column, and the condition `col = 1000` can filter out most of the data. -
The query conditions include a geo query.
-
The following figure uses the SQL statement select * from table where col1 like 'A%' or col2 = 'a'; to demonstrate two query methods.
-
When you access data using a search index, the search index on `col1` finds one row where `col1` is `'Ali%'`: `pk1 = 1`. The search index on `col2` finds two rows where `col2` is `'a'`: `pk1 = 1` and `pk1 = 2`. Then, a union operation is performed on the intermediate results to obtain the final result that meets the conditions:
pk1 = 1, col1 = 'Alibaba Cloud', col2 = 'a'.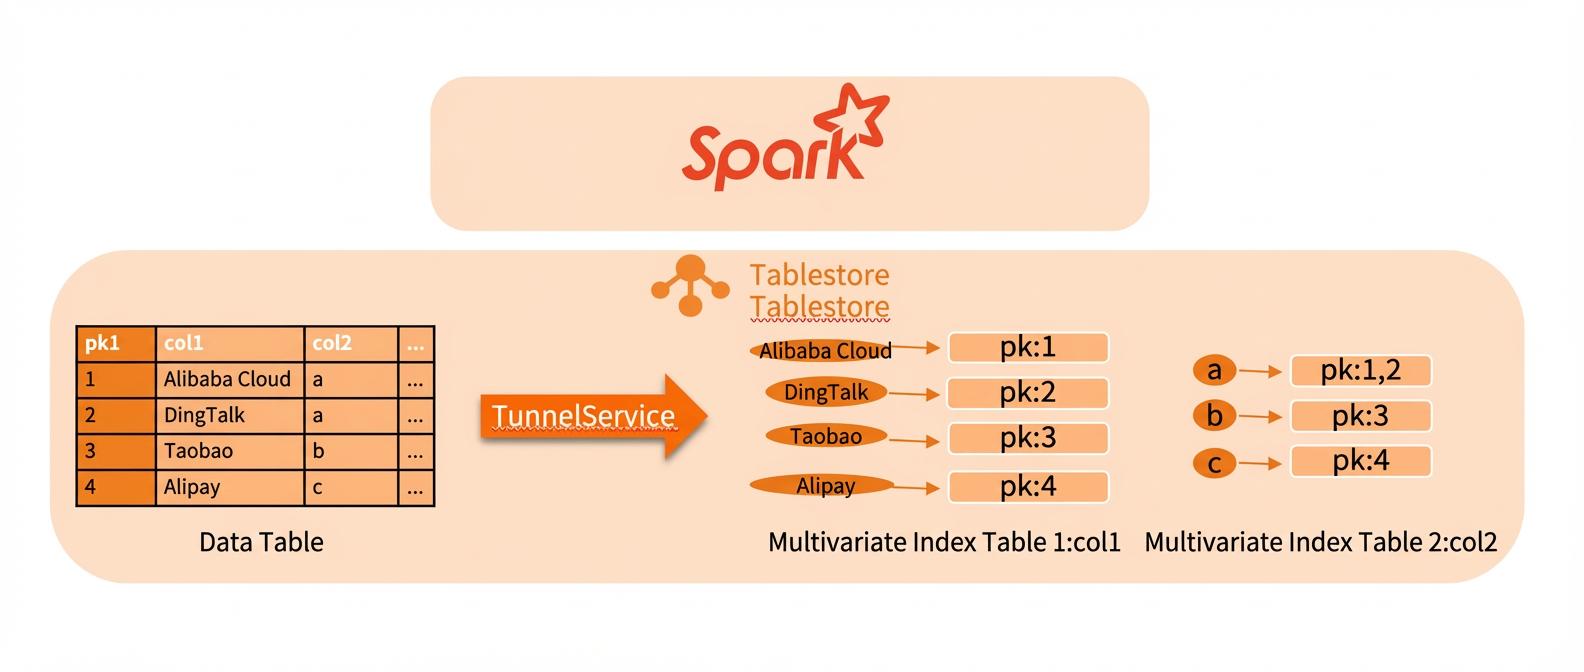
-
When you access data using the KV query method, the query is performed on the Tablestore data table. The data table can be queried only by primary key. If the filter columns in the SQL statement are not primary keys of the data table, a full table scan is required.
Because `col1` is not a primary key of the data table, Tablestore performs a full table scan to find the row where `col1` is `'Ali%'`. Because `col2` is not a primary key, Tablestore performs another full table scan to find the two rows where `col2` is `'a'`. Then, a union operation is performed on the intermediate results.
In this case, you can also create an index table with `col1` and `col2` as primary keys to support this query. However, this method is less flexible.