Wide Column model
The Wide Column model is similar to Bigtable and HBase and is used for metadata, big data, and various other scenarios. It stores data in schema-free tables that can hold petabytes of data and handle tens of millions of queries per second (QPS). The model supports wide rows, multiple data versions, and lifecycle management. Its features include auto-increment primary key columns, local transactions, atomic counters, filters, and conditional updates.
Model overview
Tablestore's Wide Column model is similar to Bigtable and HBase. It uses a three-dimensional structure (row, column, and time) to store data in tables. Because tables are schema-free, each row can have different columns, and you can dynamically add or remove attribute columns without defining a strict schema.
Model components
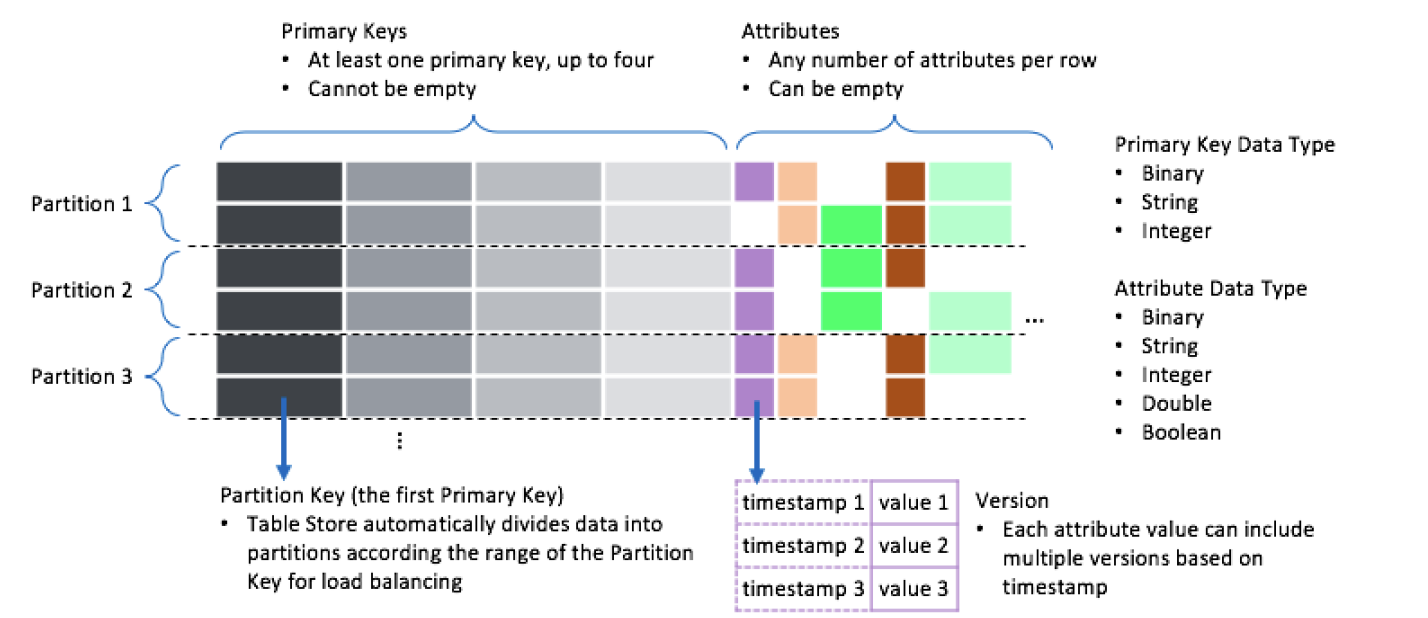
The Wide Column model, shown in the figure above, consists of the following components.
|
Component |
Description |
|
Primary Key |
A primary key uniquely identifies each row in a data table. A primary key consists of one to four primary key columns. |
|
Partition Key |
The first column of the primary key is called the partition key. Tablestore partitions data in a table based on the partition key. Rows with the same partition key are grouped into the same partition to achieve load balancing for data access. |
|
Attribute Column |
All columns in a row other than the primary key columns are attribute columns. An attribute column can have multiple values. Each value corresponds to a different version. There is no limit on the number of attribute columns per row. |
|
Version |
Each value corresponds to a different version. The version is a timestamp that defines the data lifecycle. For more information, see Version number. |
|
Data Type |
Tablestore supports multiple data types, including String, Binary, Double, Integer, and Boolean. For more information, see Data types. |
|
Time To Live (TTL) |
You can define a data lifecycle for each data table. For example, if you set the TTL to one month, Tablestore automatically cleans up data written to the table more than one month ago. For more information, see Time to live. |
|
Max Versions |
For each data table, you can define the maximum number of versions to save for each attribute column. This controls the number of data versions for an attribute column. When the number of versions for an attribute column exceeds the max versions, Tablestore asynchronously deletes older versions of the data. For more information, see Max versions. |
Core components
Data tables, rows, primary keys, and attributes are the core components of the Tablestore Wide Column model. A data table is a collection of rows, and each row is a collection of a primary key and attributes. The first primary key column is called the partition key.
The following table describes primary keys, attributes, and partition keys.
For more information about the data types of primary key columns and attribute columns, see Naming conventions and data types.
|
Component |
Description |
|
Primary key |
A primary key uniquely identifies each row in a data table. A primary key consists of one to four primary key columns. When you create a data table, you must specify the composition of the primary key, the name and data type of each primary key column, and the order of the primary key columns. Tablestore indexes data based on the primary key of the data table. Rows in a data table are sorted in ascending order by primary key by default. |
|
Partition key |
The first primary key column is called the partition key. Tablestore automatically assigns a row of data to a corresponding partition and machine based on the value range of its partition key to achieve load balancing. Rows with the same partition key value belong to the same data partition. A partition may contain multiple partition key values. The Tablestore service automatically splits and merges partitions based on specific rules. Note
A partition key value is the smallest unit of partitioning. Data with the same partition key value cannot be further split. To prevent a partition from becoming too large to split, the total size of all rows for a single partition key value should not exceed 10 GB. For more information about selecting a partition key, see Table operations. |
|
Attribute |
An attribute consists of multiple attribute columns. There is no limit on the number of attribute columns per row, and the attribute columns can be different for each row. The value of an attribute column in a row can be empty. The values of the same attribute column can have different data types. Attribute columns have a version feature. You can retain multiple versions of an attribute column's value for querying and use. You can also set a time to live (TTL) for the values of an attribute column. For more information, see Data versions and TTL. |
Differences from the relational model
The following table describes the differences between the Wide Column model and the relational model.
|
Model |
Features |
|
Wide Column model |
Three-dimensional structure (row, column, and time), schema-free, wide rows, multiple data versions, and lifecycle management. |
|
Relational model |
Two-dimensional (row, column) and a fixed schema. |
Limits
For information about the general limits of the Wide Column model, see Limits.
-
If you use a secondary index or search index to accelerate data queries, see the limits for that index type. For more information, see Secondary index limits and Search index limits.
-
If you use SQL to query and analyze data, see the limits for SQL queries. For more information, see SQL query limits.
Features
|
Features |
Description |
References |
|
Table operations |
Lets you list all data tables in an instance, create a data table, query and update the configuration of a data table, and delete a data table. |
|
|
Basic data operations |
Tablestore provides single-row data operation interfaces such as PutRow, GetRow, UpdateRow, and DeleteRow, and multi-row data operation interfaces such as BatchWriteRow, BatchGetRow, and GetRange. You can use these interfaces to read and write data in a table. |
|
|
Data versions and TTL |
Use data versions and time to live (TTL) to effectively manage data, reduce data storage space, and lower storage costs. |
|
|
Auto-increment primary key column |
After setting a non-partition key primary key column as an auto-increment column, you do not need to set a specific value for it when writing data. Tablestore automatically generates a value for the auto-increment column. This value is unique and strictly increasing at the partition key level. |
|
|
Conditional update |
Updates data in a data table only if a condition is met. If the condition is not met, the update fails. |
|
|
Local transaction |
Create a local transaction for a data range within a single partition key value. After performing read and write operations on the data in the local transaction, you can commit or discard the transaction as needed. |
|
|
Atomic counter |
Use a column as an atomic counter to perform atomic counting operations. This can be used for real-time statistics in online applications, such as counting the real-time page views (PV) of a post. |
|
|
Filter |
Filters the read results on the server-side and decides which rows to return based on the conditions in the filter. Because only rows that meet the conditions are returned, this can effectively reduce the amount of data transferred over the network and decrease the response time in most scenarios. |
|
|
Secondary index |
By creating one or more index tables, you can use the primary key columns of the index tables for queries. This extends the primary key query capability of the data table to different columns. Secondary indexes include global secondary indexes and local secondary indexes.
|
|
|
Search index |
A search index is based on an inverted index and columnar storage. It can solve complex query problems for big data. Features include non-primary key column queries, full-text search, prefix queries, fuzzy queries, queries with multiple combined conditions, nested queries, geo queries, statistical aggregations (max, min, count, sum, avg, distinct_count, group_by), and parallel scan. |
|
|
SQL query |
The SQL query feature provides a unified access interface for multiple data engines. Using the SQL query feature, you can perform complex queries and efficient analysis on data in Tablestore. When querying data with SQL, you can also use indexes to optimize your queries. |
|
|
Tunnel Service |
Tablestore provides three types of distributed real-time data consumption channels: incremental, full, and incremental plus full. These channels allow you to consume and process both historical and newly added data in a table. |
Billing
Tablestore supports two billing modes: VCU mode (formerly provisioned mode) and CU mode (formerly pay-as-you-go mode). The billing details vary based on the billing mode of your instance. For more information, see Billing overview.
-
VCU mode (formerly provisioned mode): Billable items include computing capacity, data storage, and outbound Internet traffic. Data storage includes high-performance storage, storage-optimized storage, and search index storage.
-
CU mode (formerly pay-as-you-go mode): Billable items include read throughput, write throughput, data storage, and outbound Internet traffic.
FAQ
References
-
To implement zone-level disaster recovery for instance data, you can create a zone-redundant instance. For more information, see Zone-redundant storage.
-
To ensure data storage security and network access security, you can use features such as data table encryption and VPC network access. For more information, see Data encryption and Network Security management.
-
To prevent important data from being accidentally deleted, you can use the data backup feature to periodically back up your data. For more information, see Data backup.
-
To consume and process historical and newly added data in a table, you can use Tunnel Service. For more information, see Tunnel Service.
-
To configure alert notifications for monitoring metrics, you can use Cloud Monitor. For more information, see Monitoring and alerting.
-
To visualize data in charts and other formats, you can use DataV or Grafana. For more information, see Data visualization.
-
The Wide Column model provides solutions for various scenarios, such as metadata and big data. Examples include building a massive intelligent metadata management system, building an order management system with hundreds of millions of orders based on Tablestore, building a store search system with hundreds of millions of items based on a search index, using Tablestore with Spark for integrated storage and stream/batch processing, and using Tablestore with real-time computing Flink for big data analytics. For more information about solutions, see Scenario-based practices - Typical scenario architectures and implementations.
-
To meet the demands of Internet of Things (IoT) scenarios, Tablestore offers IoTstore, a one-stop IoT storage solution. These demands include storing data from heterogeneous data sources, handling high-concurrency throughput, providing cost-effective storage for massive data volumes, and enabling multi-dimensional data processing and analytics. IoTstore provides capabilities to store, query, retrieve, analyze, and synchronize massive amounts of data, such as device metadata, message data, and time series trajectories. For more information, see IoT storage overview, Time series data ingestion, Device time series data development, Device metadata ingestion, and Time series analytics storage.