Multi-turn conversational search
A user guide and tuning recommendations for multi-turn conversational search.
Service creation
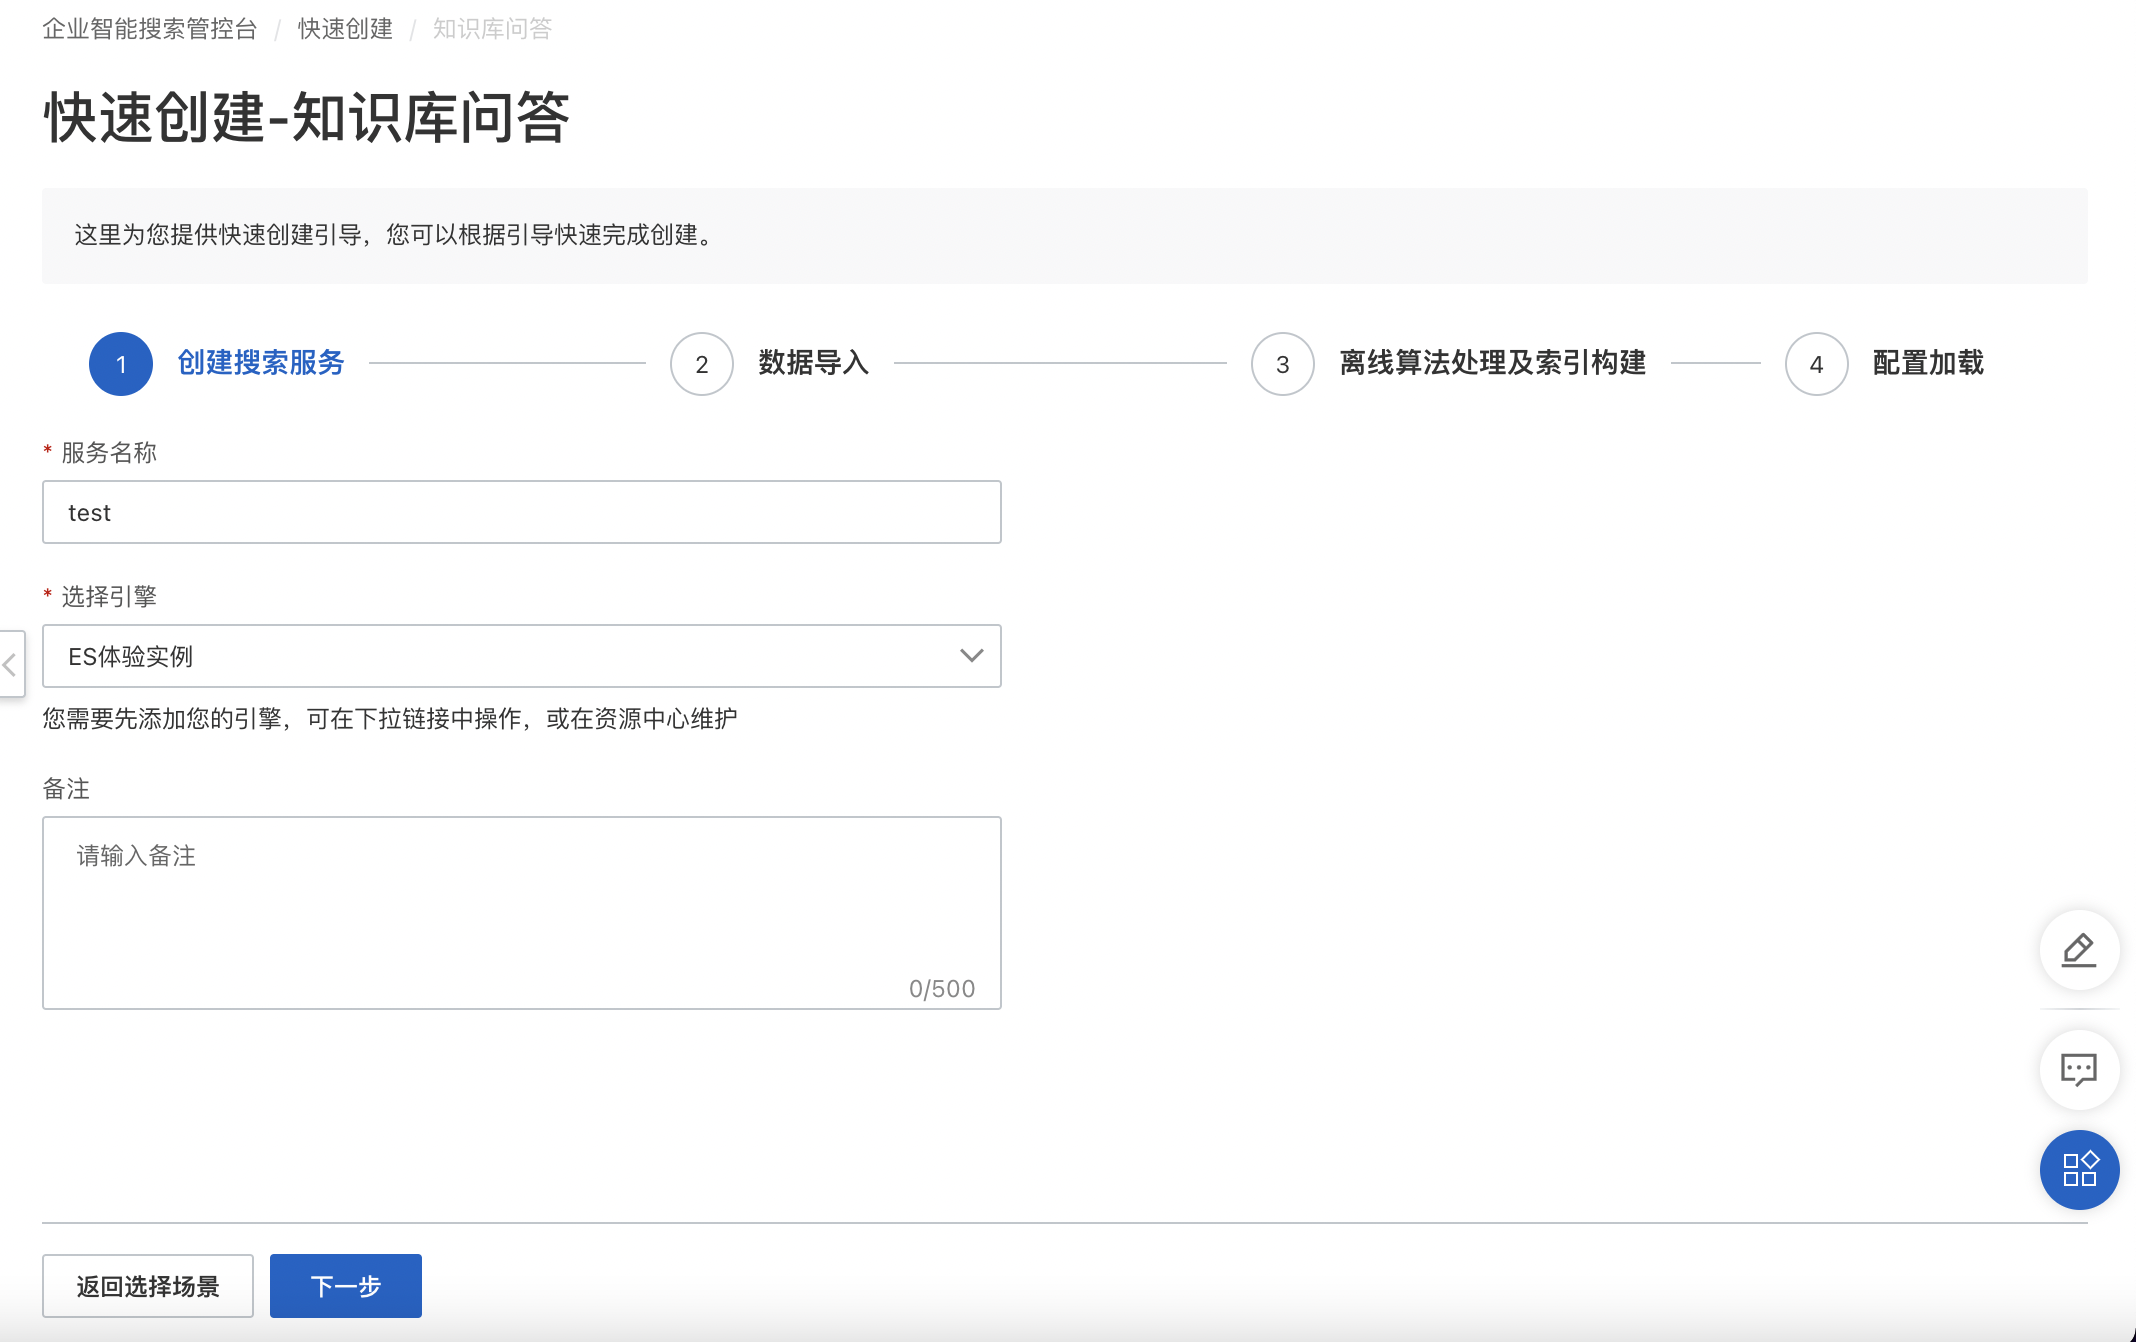
Click **Quick Create** and select **Multi-turn conversational search** to open the service creation page. Edit the service name, select an engine for the service, and complete the creation to proceed to index configuration.
Engine
The engine provides the basic components for the retrieval service. You can manage engines in the resource center or select and add them directly on the quick creation page. For more information, see the Engine Management user guide.
Supported engines |
Version |
Configuration |
Plugin |
Link |
Alibaba Cloud Elasticsearch |
V8.9 V7.10 V7.7 V6.8 V6.7 |
A minimum of 2 cores and 8 GB of memory is recommended. For vector retrieval, 8 cores and 32 GB of memory are required. |
No requirements |
Data import
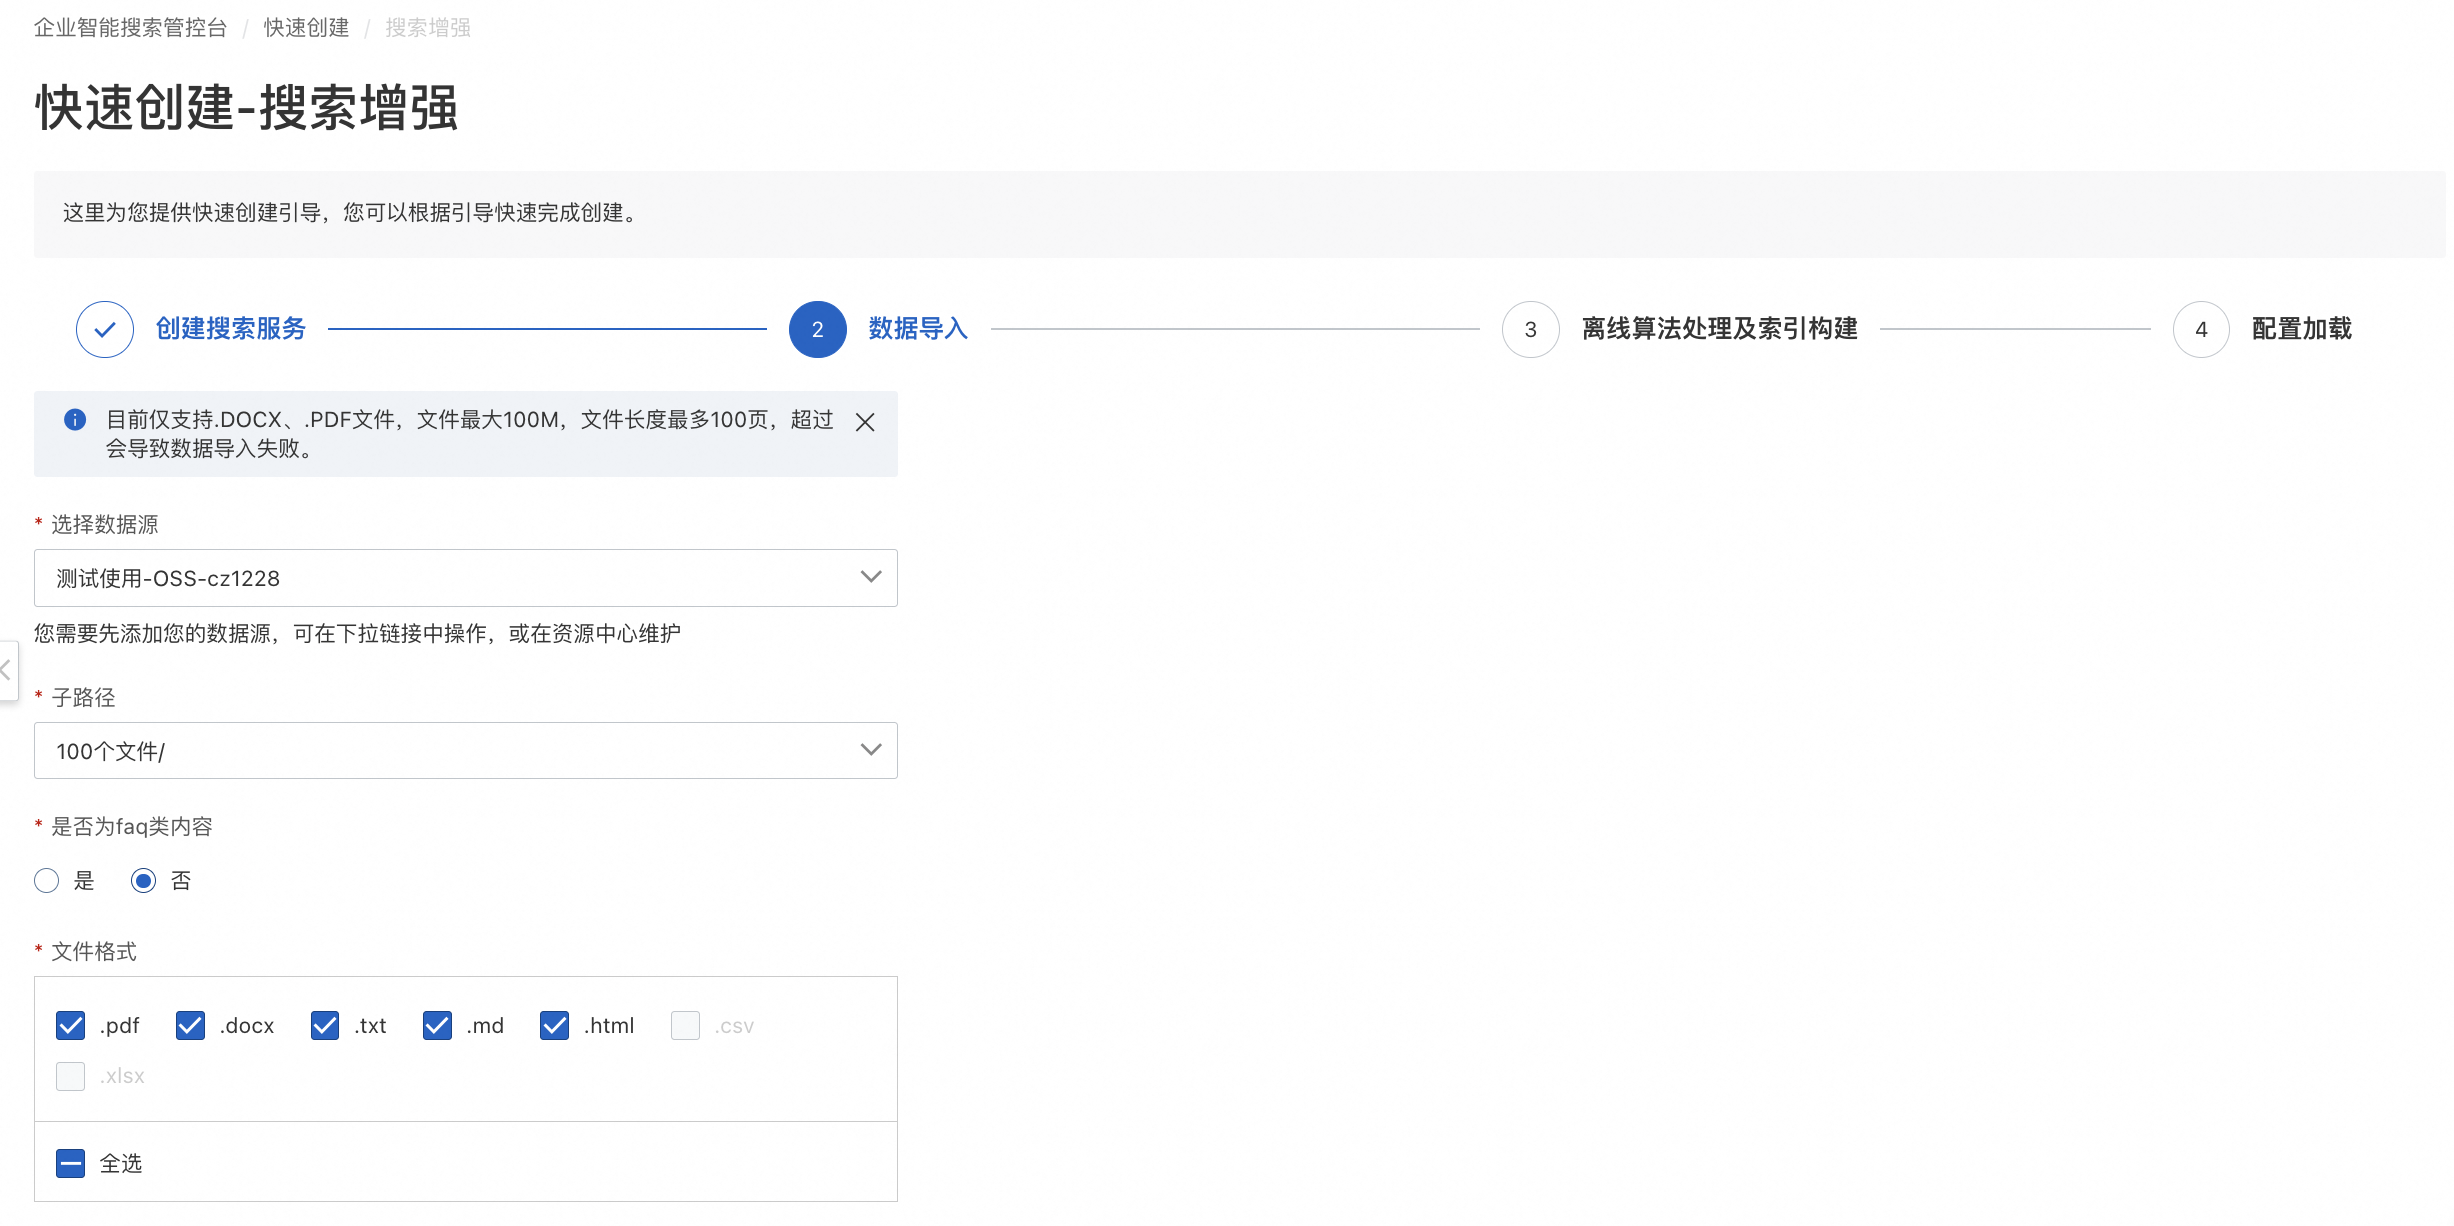
Data source
Your enterprise knowledge base is stored in a data source. You can manage data sources in the resource center or select and add them directly on the quick creation page. For more information, see the Data Source Management user guide.
Supported data sources |
Link |
ApsaraDB RDS for MySQL |
|
Alibaba Cloud MaxCompute |
|
Alibaba Cloud OSS |
Sub-path/Database table
This parameter specifies the storage address of the selected data source for your enterprise knowledge base. The system reads the files in the specified directory or the tables in the database. You can select specific files, subdirectories, or tables by specifying a sub-path.
Parsed fields
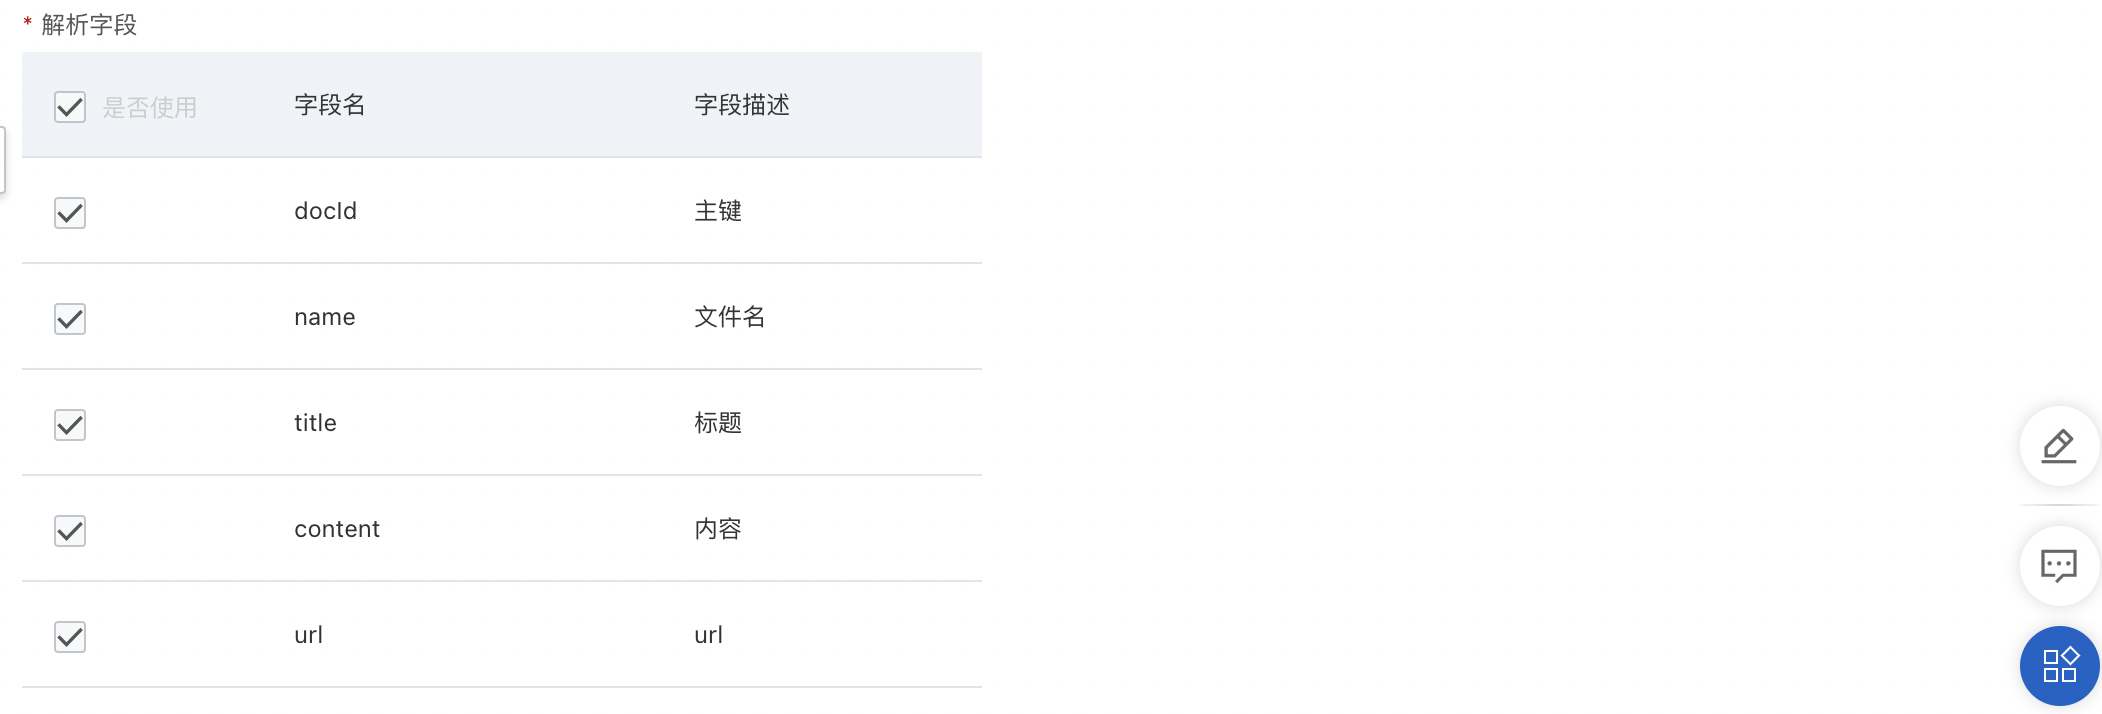
The system parses data source fields offline to build an index.
Select the fields that you want to use. The selected fields are indexed. Different field types are used in the retrieval and sorting stages of the search process and can be displayed in the query results. Unselected fields are not indexed.
Data source type |
Is FAQ |
Parsed fields |
RDS MySQL /MaxCompute |
Yes |
The database table must contain the following fields: id, question, answer, sim_question, url, and gmt_modified. |
No |
The parsed fields are the same as the fields in the selected database table and are not fixed options. |
|
OSS |
Yes |
Supported file formats are .csv and .xlsx. The data source must contain the following fields: id, question, answer, sim_question, and url. |
No |
Supported file formats are .pdf, .docx, .txt, .md, and .html. The parsed fields are default fields and are all selected. |
Configure index
Source data table index configuration
After you configure the data source, you must configure the index schema to build the index. The data fields vary based on the data source and scenario, but the index building process is similar. The following example uses an Alibaba Cloud OSS data source to describe the index building process.
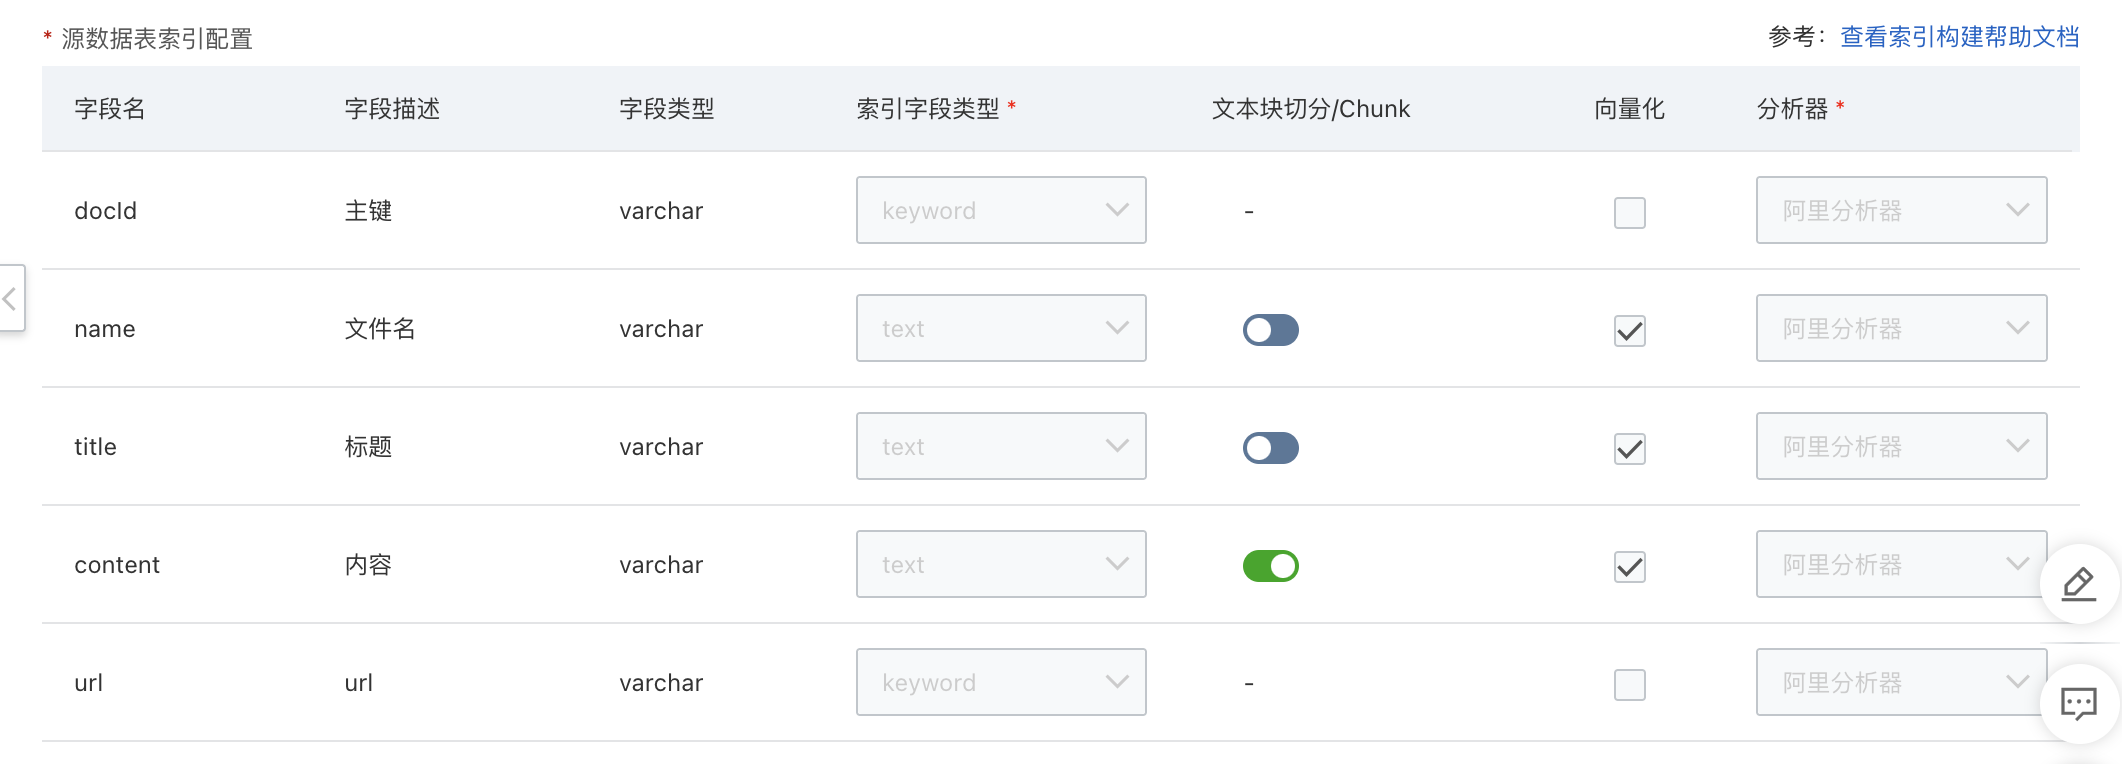
Field name
For an instance that uses OSS files as the data source, the field names correspond to the fields from the offline data parsing. The default field names from offline parsing include the following:
Field name |
Field description |
Field type |
docId |
Primary key, unique identifier ID |
varchar |
name |
File name |
varchar |
title |
Parsed segment title content |
varchar |
content |
Parsed segment body content |
varchar |
url |
URL |
varchar |
For an instance that uses a data table as the data source, the field names have a one-to-one correspondence with the table field names. For example, if the source data table contains only "id" and "content" fields, the index configuration displays "id" and "content" as field names. The field types match those defined in the source data table.
Index field type
The index field type defines the data type of a field so that a search engine, such as Elasticsearch, can correctly process and index the field values. Common index field types in Elasticsearch include the following:
Index field type |
Field type description |
text |
Used to index long text, such as article content or descriptions. Text types are tokenized to allow searching and matching based on individual words. |
keyword |
Used to index short text, such as tags or keywords. Keyword types are not tokenized. The entire field is indexed and matched as a single unit. |
integer |
Used to index INT type numbers. Numeric types can be used for sorting, range queries, and other operations. |
long |
Used to index LONG type numbers. Numeric types can be used for sorting, range queries, and other operations. |
double |
Used to index DOUBLE type numbers. Numeric types can be used for sorting, range queries, and other operations. |
float |
Used to index FLOAT type numbers. Numeric types can be used for sorting, range queries, and other operations. |
date |
Used to index dates and times. Date types can be used for date range queries, sorting, and other operations. |
boolean |
Used to index Boolean values, which are true or false. |
binary |
Used to index binary data, such as images or files. |
Text block splitting/Chunk
If a field contains long text that will be used as reference content for Large Language Model (LLM) responses, you can select this option. When this option is selected, the long text in this field is split into smaller text blocks, or chunks. If this option is not selected, the latter part of very long text may be truncated. For OSS data sources, this option is selected by default for the content field.
Vectorization
Text vectorization is the process of converting text data into numerical vectors. This process represents words and sentences as vectors to enable relevance calculations in tasks such as information retrieval. Selecting vectorization improves search accuracy, which allows the system to find correct knowledge even when a user's query does not exactly match the text in the knowledge base.
Example of text vectorization
Input text: "a yellow dress"

Vectorized result: [0.2694664001464844,-0.3998311161994934,-0.14598636329174042,-0.4976918697357178,-0.13986249268054962,0.6272065043449402,-0.1434994637966156,-0.33319777250289917]The vectorized result is a list of floating-point numbers. The length of the list depends on the output dimension of the vectorization model.
During index building, vectorization only applies to TEXT type fields.
If you select multiple TEXT fields for vectorization, the algorithm model automatically concatenates the fields and calculates a single vector result.
Analyzer
During index building, an analyzer (or tokenizer) is a tool used to split text data into tokens. It is a key component of the text analytics process and is used to build an inverted index for text searching and matching.
The analyzer splits input text according to specific rules. It breaks a long text into multiple tokens, which can then be indexed and searched.
Enterprise Search provides several built-in analyzers:
Alibaba Analyzer
Description: A Chinese and English tokenizer developed by Alibaba. It is adapted for various business scenarios and is the default option for multi-turn conversational search.
Tokenization example
Input text: "Alibaba is a global internet technology company."

Tokenization result: "Alibaba / is / a / global / internet / technology / company / ."
IK Analyzer
Description: An open source IK tokenizer. Its tokenization effect is similar to the Alibaba Analyzer.
Single-word analyzer
Description: Splits text by single characters (UTF-8 encoding). It is suitable for retrieval scenarios that do not require high semantic understanding but need high recall.
Tokenization example
Input text: "A single-word tokenizer is a basic tokenization method."

Tokenization result: "A / single / - / word / tokenizer / is / a / basic / tokenization / method / ."
Pinyin analyzer
Description: Parses Chinese fields into Pinyin. It is used for Pinyin-based retrieval scenarios.
Tokenization example:
Input text: "I love Chinese tokenizers"

Tokenization result: "wo ai zhong wen fen ci qi"
N-gram analyzer:
Description: Splits text by N-grams of characters (UTF-8 encoding). The default value of N is 3.
Tokenization example:
Input text: "Chinese tokenizer"

N-gram tokenization result (N=3): "zhong / wen / fen / ci / qi / zhongwen / wenfen / fenci / ciqi / zhongwenfen / wenfenci / fenciqi"
By selecting the appropriate analyzer, you can make the search engine more accurate and flexible when it indexes and searches text data.
Associate file data
If your data source contains both files and database data, and the **File Path Field** and **File Type Field** are both fields in the database, you can enable the **Associate File Data** feature. For more information, see Best practices. After you enable this feature, the system performs an automatic check. If any fields in the source data table have the same names as the system-extended fields (title, content, parent, hier_title, or nid), you must exit the process and rename the conflicting fields.
File storage class
OSS and HTTP data types are supported.
File path field
This field is used to retrieve the path of files stored in OSS. The field must be of the keyword or text type.
File type field
This field is used to retrieve the type of files stored in OSS. The field must be of the keyword or text type. Supported file types include .pdf, .docx, .txt, .md, and .html.
System-extended fields
The system-extended fields are fixed as title, content, parent, hier_title, and nid.
You can configure chunk parameters. The value for **chunk size** must be 50 or greater. The value for **chunk overlap** must be less than the chunk size and can be 0.
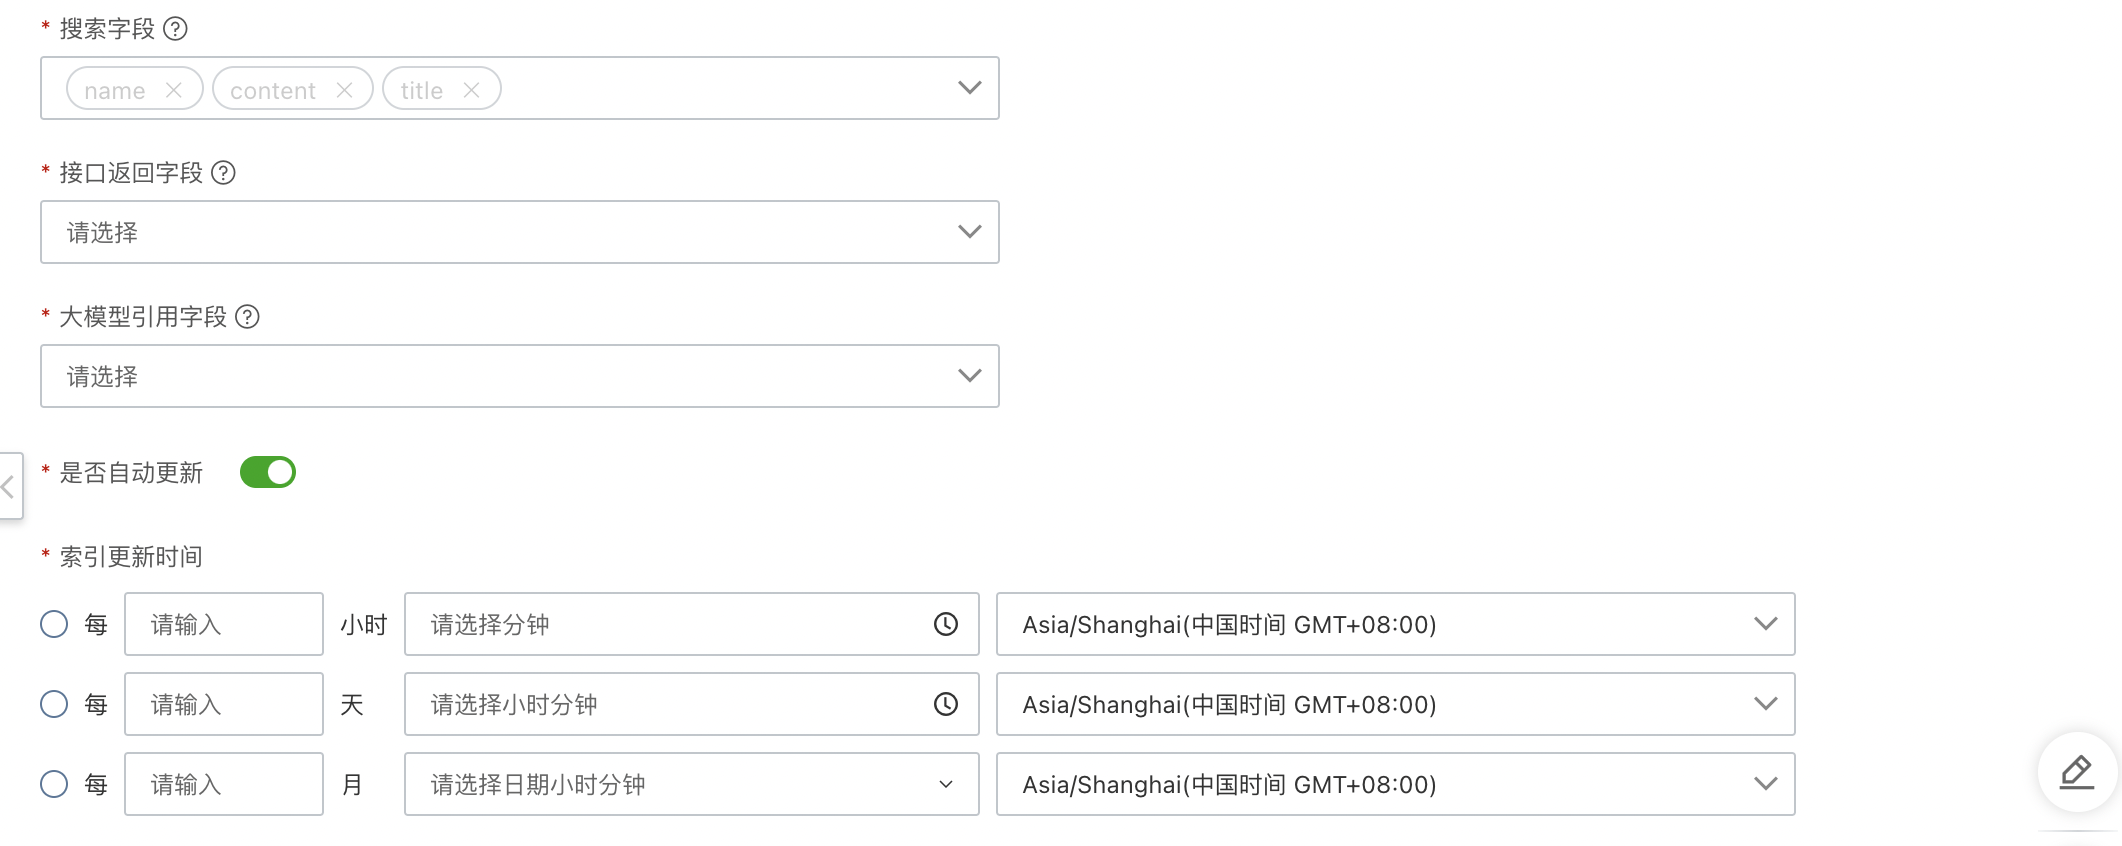
Search fields
These are the full-text index fields, which must be of the keyword or text type. They are used to perform search operations, match query conditions, and limit the search scope.
API response fields
These are the fields returned in the search request response. You can select the required business fields from the index configuration. These fields are returned in the `fields` field of the OpenAPI response. They can later be used as reference content in multi-turn conversations with the LLM.
LLM reference fields
These are the fields from the API response that the LLM uses as reference content. These fields must be a subset of the API response fields.
This helps the LLM retrieve more precise and effective information to provide more accurate answers. For example, if the API response fields are "id" and "content", you would select only "content" as the LLM reference field because the "id" field does not provide useful information to help the LLM understand the context.
Automatic updates
You can enable this option if the data source index needs to be updated periodically. You can set automatic updates to run hourly, daily, or monthly, and configure the specific time and time zone for the update.
Service testing
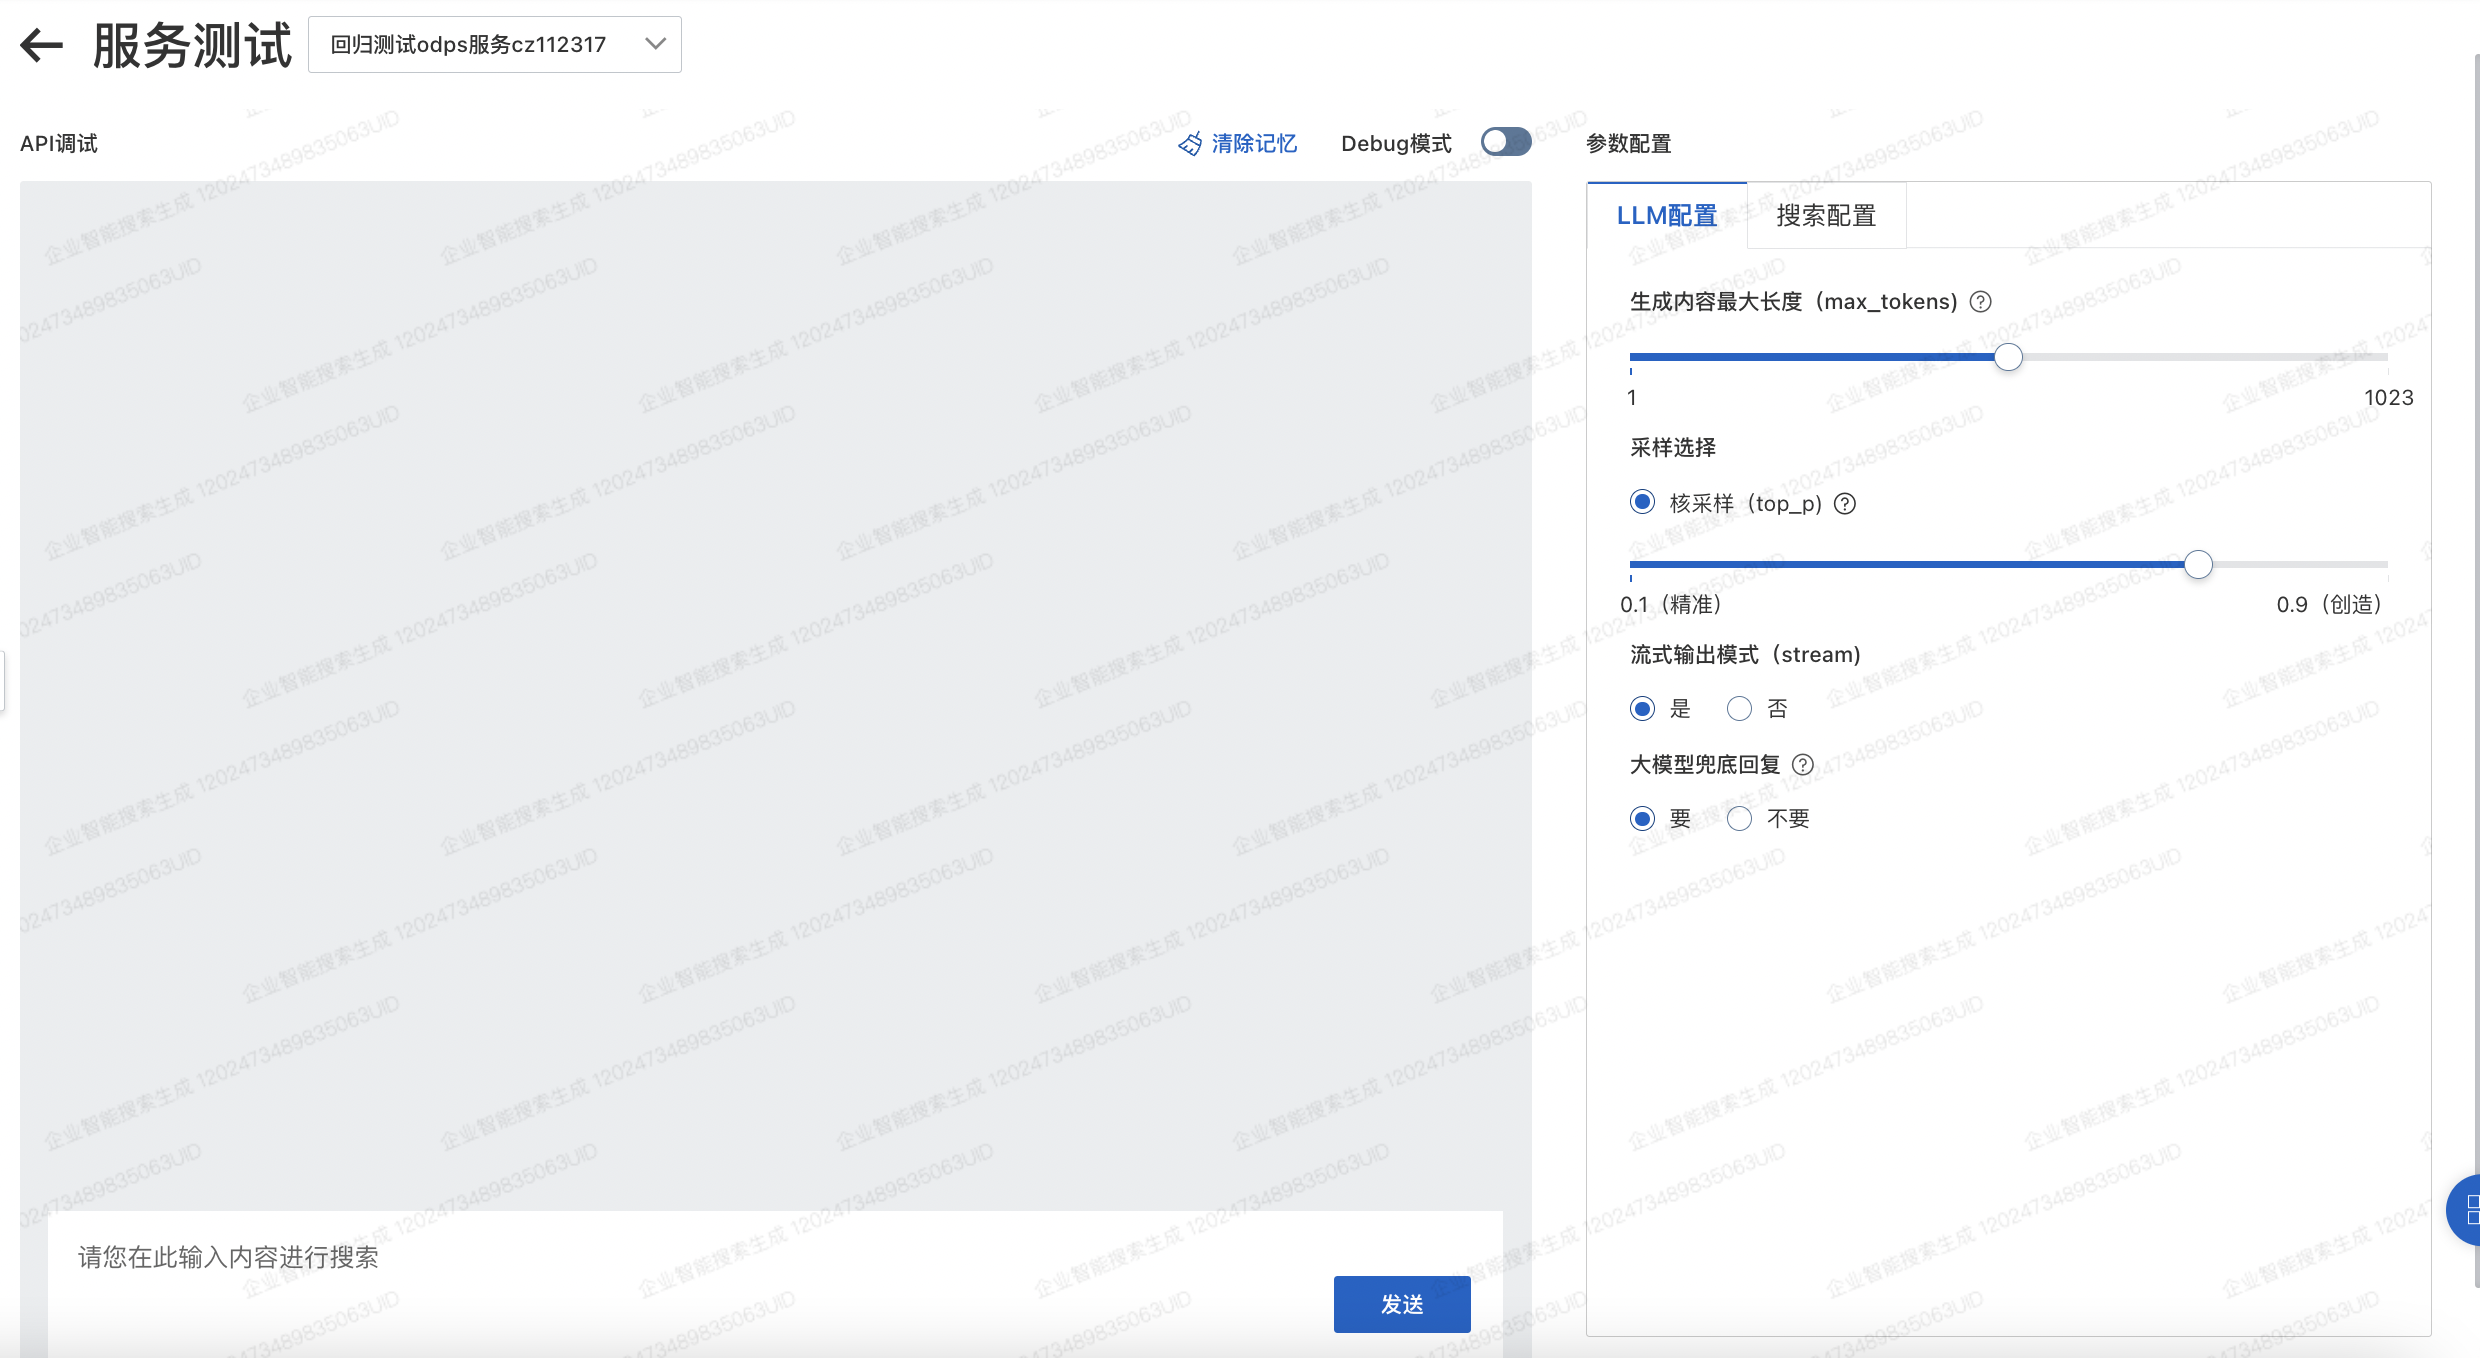
LLM parameter configuration
After you modify the configuration, click Save for the changes to take effect.
Maximum length of generated content (max_tokens)
This parameter controls the length of each generated conversation response. The maximum length cannot exceed 2048. Content that exceeds this limit is truncated.
Sample Selection
A lower top_p value results in more conservative output. A higher top_p value results in more creative output. A value of 0.7 to 0.8 is generally recommended, but you can adjust it as needed.
Streaming output mode (stream)
Yes: The final result is output word by word as it is being generated.
No: The final result is output as a single block after it has been fully generated.
LLM fallback response
Yes: If the search request does not return any valid information, the LLM provides a fallback response.
No: If the search request does not return any valid information, the LLM does not provide a fallback response. You can configure a custom response message instead.
Tips
How to test: After the initial configuration, select a document from your index as the target and write a query about it. Enter the query on the test page to see the model's response. If the response is as expected, run a few more tests. If not, enable the Debug switch.
You can then view the detailed logs of the multi-turn conversation flow. If the display box is too small, copy the content to another text or JSON editor. Focus on the content within "child_execs".
{
"start_time":1692850565627,
"trace_id":"f-s-5NRRqmDDUgkNGFLXw88888",
"exec_params":{
"streaming":true,
"debug":true,
"async_run":false,
"session_id":"f-s-5NRRqmDDUgkNGFLXw88888",
"flow_params":{
"top_p":"0.7",
"search_size":3,
"api_key":"**************",
"content_fields":"title,content",
"max_new_tokens":512,
"temperature":1,
"rank_model_info":"{\"rankModelInfo\": {\"default\": {\"features\": [{\"name\": \"vector_index\", \"weights\": 0.5, \"threshold\": 0, \"norm\": true}, {\"name\": \"static_value\", \"field\": \"_rc_t_score\", \"weights\": 0.5, \"threshold\": 0, \"norm\": true}], \"aggregate_algo\": \"weight_avg\"}}}",
"human_input":"Muyun",
"custom_config_info":"{\"rerankSize\": 200, \"uqVectorRecallRatio\": 0.5}",
"type":"title,content",
"fields":"title,content",
"scene":"dolphin_search_ms_index_es_113_prod"
},
"flow_json":null,
"flow_json_url":"https://******/corp_search.json"
},
"exec_result":{
"result":[
"Sorry",
", ",
"the ",
"current ",
"search ",
"results ",
"do ",
"not ",
"contain ",
"relevant ",
"content ",
"for ",
"this ",
"question",
". ",
"An ",
"answer ",
"cannot ",
"be ",
"provided ",
"at ",
"this ",
"time",
"."
],
"ext":{
},
"output_tokens":null,
"request_id":null,
"input_tokens":null,
"prompt":"{\"query\": \"Muyun\", \"model_id\": \"daily-top_qad-392\", \"api_key\": \"**************\", \"stream\": true, \"search_results\": [{\"id\": 1, \"content\": \"\\nThe core members of the product team were once responsible for the overall internal security of Alibaba Cloud. They have summarized Alibaba's best practices in enterprise security operations over the past 10+ years. The security operations team must first clearly understand the key challenges the enterprise is currently facing and what the enterprise's risk tolerance range is. What risks can we accept? What risks can we not accept? Once a security event exceeds this risk tolerance, it will directly lead to a state where the enterprise cannot operate, and business continuity will be affected. Therefore, only risks that can be proven to truly affect the business are real security risks and should be listed as the highest priority for remediation. The sole purpose of all security control measures is to mitigate business risks.\", \"raw_search_result\": {\"_rc_score\": 18.187634, \"_q_score\": 1.0, \"_id\": \"7606980412276885772_129\", \"title\": \"\", \"_score\": 18.187634, \"content\": \"The core members of the product team were once responsible for the overall internal security of Alibaba Cloud. They have summarized Alibaba's best practices in enterprise security operations over the past 10+ years. The security operations team must first clearly understand the key challenges the enterprise is currently facing and what the enterprise's risk tolerance range is. What risks can we accept? What risks can we not accept? Once a security event exceeds this risk tolerance, it will directly lead to a state where the enterprise cannot operate, and business continuity will be affected. Therefore, only risks that can be proven to truly affect the business are real security risks and should be listed as the highest priority for remediation. The sole purpose of all security control measures is to mitigate business risks.\"}}, {\"id\": 2, \"content\": \"\\nWhat is a WebShell\", \"raw_search_result\": {\"_rc_score\": 9.906794, \"_q_score\": 0.5446994369910897, \"_id\": \"5751733942449846217_6\", \"title\": \"\", \"_score\": 9.906794, \"content\": \"What is a WebShell\"}}, {\"id\": 3, \"content\": \"\\n1. Muyun Management Platform\", \"raw_search_result\": {\"_rc_score\": 9.759266, \"_q_score\": 0.5365879915991272, \"_id\": \"18103204782719913721_10\", \"title\": \"\", \"_score\": 9.759266, \"content\": \"1. Muyun Management Platform\"}}], \"history_messages\": [], \"temperature\": 1.0, \"top_p\": 0.7, \"top_k\": 50, \"length_penalty\": 1.0, \"num_doc\": 3, \"answer_doc\": false, \"max_new_tokens\": 512, \"tp_answer\": \"\", \"allow_direct_answer\": true}"
},
"child_execs":[
{
"start_time":1692850565683,
"trace_id":"f-s-5NRRqmDDUgkNGFLXw88888",
"exec_params":{
"top_p":0.7,
"api_key":"**************",
"stream":false,
"max_new_tokens":512,
"query":"Muyun",
"history_messages":[
],
"model_id":"daily-top_qad-392",
"tp_search":""
},
"exec_result":{
"do_search":true
},
"child_execs":null,
"end_time":1692850566121,
"exec_name":"search_toggle",
"exec_status":true,
"exec_kind":"AI_FLOW_STEP",
"exec_message":null
},
{
"start_time":1692850566122,
"trace_id":"f-s-5NRRqmDDUgkNGFLXw88888",
"exec_params":{
"top_p":0.7,
"api_key":"**************",
"stream":false,
"max_new_tokens":512,
"tp_query_rewrite":"",
"query":"Muyun",
"history_messages":[
],
"model_id":"daily-top_qad-392"
},
"exec_result":{
"queries_r":[
"What is Muyun"
]
},
"child_execs":null,
"end_time":1692850566617,
"exec_name":"search_rewrite",
"exec_status":true,
"exec_kind":"AI_FLOW_STEP",
"exec_message":null
},
{
"start_time":1692850566618,
"trace_id":"f-s-5NRRqmDDUgkNGFLXw88888",
"exec_params":{
"customConfigInfo":{
"rerankSize":200,
"uqVectorRecallRatio":0.5
},
"page":1,
"uq":"What is Muyun",
"fields":[
"content",
"title"
],
"rows":3,
"type":"title,content",
"scene":"dolphin_search_ms_index_es_113_prod",
"rankModelInfo":{
"rankModelInfo":{
"default":{
"features":[
{
"name":"vector_index",
"threshold":0,
"weights":0.5,
"norm":true
},
{
"field":"_rc_t_score",
"name":"static_value",
"threshold":0,
"weights":0.5,
"norm":true
}
],
"aggregate_algo":"weight_avg"
}
}
}
},
"exec_result":{
"msg":null,
"code":200,
"data":{
"headers":{
"__d_head_rtm":"1692850566901",
"__d_head_sip":"192.168.43.28",
"__d_head_es_rt":"t:32",
"__d_head_engine_rt":"q:104-s:92-r:7-i:65",
"__d_head_ver":"0.0.1-SNAPSHOT"
},
"debug":null,
"data":{
"qpInfos":[
{
"tokenized":[
"mu",
"yun",
"is",
"what"
],
"stopWords":[
],
"spellcheck":false,
"cleanQuery":"What is Muyun",
"query":"What is Muyun",
"sensitive":false,
"synonymWords":[
],
"recognitions":[
{
"name":"O",
"text":"mu"
},
{
"name":"O",
"text":"yun"
},
{
"name":"O",
"text":"is"
},
{
"name":"O",
"text":"what"
}
],
"spellchecked":"What is Muyun",
"rewrite":"What is Muyun",
"operator":"AND"
}
],
"total":89,
"docs":[
{
"_rc_score":18.187634,
"_q_score":1,
"_id":"7606980412276885772_129",
"title":"",
"_score":18.187634,
"content":"The core members of the product team were once responsible for the overall internal security of Alibaba Cloud. They have summarized Alibaba's best practices in enterprise security operations over the past 10+ years. The security operations team must first clearly understand the key challenges the enterprise is currently facing and what the enterprise's risk tolerance range is. What risks can we accept? What risks can we not accept? Once a security event exceeds this risk tolerance, it will directly lead to a state where the enterprise cannot operate, and business continuity will be affected. Therefore, only risks that can be proven to truly affect the business are real security risks and should be listed as the highest priority for remediation. The sole purpose of all security control measures is to mitigate business risks."
},
{
"_rc_score":9.906794,
"_q_score":0.5446994369910897,
"_id":"5751733942449846217_6",
"title":"",
"_score":9.906794,
"content":"What is a WebShell"
},
{
"_rc_score":9.759266,
"_q_score":0.5365879915991272,
"_id":"18103204782719913721_10",
"title":"",
"_score":9.759266,
"content":"1. Muyun Management Platform"
}
],
"keywords":[
{
"schema":"title,content",
"name":"Full-text",
"value":"What is Muyun",
"fuzzy":true
}
],
"totalDistinct":89,
"extras":null,
"aggs":null
},
"success":true,
"rid":null,
"message":null,
"status":0
},
"success":true,
"requestId":"3C90873D-CAAB-437D-925A-5E8D90E2E746",
"httpStatusCode":200
},
"child_execs":null,
"end_time":1692850566905,
"exec_name":"search",
"exec_status":true,
"exec_kind":"AI_FLOW_STEP",
"exec_message":null
},
{
"start_time":1692850570204,
"trace_id":"f-s-5NRRqmDDUgkNGFLXw88888",
"exec_params":{
"top_p":0.7,
"api_key":"**************",
"stream":false,
"max_new_tokens":512,
"query":null,
"history_messages":[
{
"role":"user",
"content":"Muyun"
},
{
"role":"assistant",
"content":"Sorry, the current search results do not contain relevant content for this question. An answer cannot be provided at this time."
}
],
"model_id":"daily-top_qad-392"
},
"exec_result":{
"queries_s":[
"What is Muyun?",
"What are the features of Muyun?",
"What are the advantages of Muyun?"
]
},
"child_execs":null,
"end_time":1692850571168,
"exec_name":"search_recommend",
"exec_status":true,
"exec_kind":"AI_FLOW_STEP",
"exec_message":null
}
],
"end_time":null,
"exec_name":"corp_search.json",
"exec_status":true,
"exec_kind":"AI_FLOW",
"exec_message":null
}Troubleshoot as follows:
First, check the first dictionary enclosed in {}. Check whether `do_search` is false. If `do_search` is false, check whether your query is one that does not require a search to be answered, such as "hello". If you want all queries to be searched by default, contact us to enable the force search switch.
Check the second dictionary enclosed in {}. Check whether `queries_r` meets expectations. `queries_r` is the model's rewrite of your input query, which is typically used in multi-turn conversations to resolve contextual references. If you do not want any queries to be rewritten by default, contact us to disable the rewrite feature.
Check the third dictionary enclosed in {}. Check whether the target document is included in the first `num_docs` documents under `exec_result->data->docs`. If not, the search failed to find it. In this case, you need to debug the sorting formula in the search enhancement module to ensure that the corresponding query can find the target document. Enter the debugged sorting formula and click Save Configuration.
After you ensure that the target document appears in the first `num_docs` documents, if the result is still not as expected, adjust the generation parameters in the LLM parameter configuration to achieve the desired outcome.
Search enhancement parameter configuration
Number of items configuration
Definition: Knowledge items are the relevant indexed entries retrieved by the search. They are structured based on the search API response fields. A sorting calculation prioritizes items with higher relevance. If you set **Number of candidate knowledge items** to 3, the three knowledge items with the highest sorting scores are passed to the downstream LLM as reference content.
Value limit: The current model's upper threshold is 6000. The threshold is calculated as: Number of candidate knowledge items × Length of a single knowledge item.
Recommended values: Set **Number of candidate knowledge items** to 3 and **Maximum length of a single knowledge item** to 1000.
Description: Controls the scope of knowledge items provided to the LLM.
Tips:
A higher number of candidate knowledge items leads to more generalized responses from the LLM. However, because of the model's threshold, the length of each knowledge item is limited. If the knowledge items are too short, the information may be incomplete, which affects the accuracy of the LLM's response.
Multi-channel retrieval - Vector retrieval ratio
Definition: The retrieval model mainly includes **text relevance retrieval** and **semantic vector retrieval**. Text relevance retrieval retrieves documents based on the consistency of tokenized words. Semantic vector retrieval converts text into semantic embeddings and finds the closest documents in the vector space.
Recommended value: 50%. This means that text retrieval and semantic vector retrieval each account for half of the total number of retrieved documents.
Description: Controls the proportion of vector retrieval in the total retrieval for a query.
Tips:
To disable vector retrieval and use only text relevance retrieval, set the value to 0%. The current version does not support using only vector retrieval, so do not set the value to 100%.
Number of documents for fine-grained sorting
Definition: The maximum number of documents to be included in the fine-grained sorting calculation.
Recommended value: 200 to 500.
Description: After a query retrieves all relevant text, a basic relevance score is calculated and the results are sorted. If the total number of retrieved documents is greater than the configured **Number of documents for fine-grained sorting (N)**, the top N documents with the highest basic relevance scores are used for fine-grained sorting.
Tips:
A larger number means more documents are used for fine-grained sorting, which can improve the final results but will increase the time required for the calculation.
Custom sorting formula
Definition: The product provides a rich set of sorting features that allow users to implement custom sorting based on their needs. The sorting formula is in JSON format and is configured in **rankModelInfo**. The built-in sorting model scores the retrieved results based on the sorting features specified in **rankModelInfo** and calculates the final sorting score and results. The built-in sorting module offers various sorting features and supports the configuration of the corresponding index field, weight, threshold, and normalization for each feature.
rankModelInfo
This is the configuration field for the custom sorting formula. It contains sorting formulas for the original query and extra queries. Each type of sorting formula is a dictionary, and the dictionary name is the corresponding query field name. The default sorting formula type for the query (uq) is named "default". The sorting formula types for extra queries are named after their corresponding query names in the "extras" field.
Sorting formula
The content of each sorting formula includes two parts: "features" and "aggregate_algo". "features" is a list of specific sorting features and their parameters. "aggregate_algo" currently only supports "weight_avg", which is a weighted sum of all features.
Feature
Each feature is a dictionary containing the feature name and its parameters. The common parameters for features are as follows:
Common feature parameters
name: The feature name.
field: The index field for calculating the relevance feature.
weights: The feature weight, which is a floating-point number.
threshold: The feature score threshold, which is a floating-point number. Feature scores below the threshold are set to 0. **Note**: The threshold filter value is the score before normalization.
norm: A Boolean value that specifies whether to normalize the feature.
norm_factor: A floating-point number coefficient used to adjust the distribution of scores after normalization.
The specific details of each feature are as follows:
Feature descriptions:
Feature name |
Description |
Feature-specific parameters |
vector_index |
Vector match score (requires vector retrieval to be configured). |
score_type: The score calculation type for vector retrieval. Options are L2 (higher score for more relevance) and IP (lower score for more relevance). The default is IP. Select the appropriate score_type based on the vector engine configuration. |
text_index |
Search engine retrieval score. Tips: This feature is only supported for text-only retrieval. When using multi-channel retrieval (vector + search engine), you can use `static_value` to get the ES retrieval score by setting the `field` to "_rc_t_score". |
|
timeliness |
Timeliness score, proportional to the difference in milliseconds between the given time field and a base time. The value ranges from 0 to 1. |
time_field (str): The name of the time field, in the format "%Y-%m-%d %H:%M:%S.%f". field (str): The field name, which must be the same as the time field name. base_time (str): The base time field, in the format "%Y-%m-%d %H:%M:%S". It should be set to the time of the earliest document. normalized_number (float): Controls the granularity of the timeliness score. It should typically be set to 1e6. |
doc_match_ratio |
The ratio of the number of matching words between the field and the query to the total number of words in the field. |
|
query_match_ratio |
The ratio of the number of matching words between the query and the field to the total number of words in the query. |
|
doc_match_count |
The number of matching words between the field and the query. |
|
query_match_count |
The number of matching words between the query and the field. |
|
query_min_slide_window |
Measures the proximity of matching words between the query and the field. It is the ratio of the number of matching words in the query to the minimum window in the field that contains those words (ignoring the order of the query words). |
|
ordered_query_min_slide_window |
Measures the proximity of matching words between the query and the field, considering the order. It is the ratio of the number of token groups from the query that are hit in a field to the minimum window in the field that contains those groups (with sequential matching). |
|
doc_unique_ratio |
The ratio of the number of unique words to the total number of words in a field. It is used to filter documents with repetitive keywords. |
|
overlap_coefficient |
The ratio of the number of matching words between the query and the field to the total number of words in the query and the field. It measures text match degree. |
|
char_overlap_coefficient |
The ratio of the number of matching characters between the query and the field to the total number of characters in the query and the field. It measures character-level similarity. |
|
lcs_match_ratio |
The ratio of the word count in the field to the word count in the search query. |
|
char_lcs_match_ratio |
The ratio of the length of the LCS at the character level between the query and the field to the number of characters in the query. It is suitable for string matching scenarios such as emails and mobile numbers. |
|
edit_similarity |
Text similarity calculated based on the edit distance between the field and the query. The value ranges from 0 to 1, where a higher value indicates greater similarity. It is used to measure the degree of an exact match between the query and the field. It is suitable for matching a question to another question and should be used with a high threshold. |
|
char_edit_similarity |
Character-level edit similarity. |
|
char_sequential_match_priority |
A specialized feature for name matching that considers the matching order. It calculates character-level sequential match similarity. The similarity of the i-th character is 1 / |i-j|, where j is the position of the nearest identical character in the field. The weight of the i-th character is 1.0 / i. The final score is the weighted average of all character similarities. This feature is used to calculate order-dependent text similarity. |
|
pinyin_lc_substr |
The ratio of the length of the longest common Pinyin substring between the query and the field to the length of the Pinyin in the field. It measures Pinyin similarity. |
|
doc_pinyin_lc_substr |
The ratio of the length of the longest common Pinyin substring between the query and the field to the length of the Pinyin in the query. It measures Pinyin similarity. |
|
static_value |
Uses the value of a numeric field as the feature score. |
|
name_pinyin_match |
A specialized feature for matching names in Pinyin. It checks for matches between the query and the field's full Pinyin, Pinyin initialisms, and a mix of initials and full Pinyin. For example, if a name field has the value "Zhang San", this feature checks if the query's Pinyin is one of ["zhangsan", "zs", "zhangs", "zsan"]. If a match is found, it returns a score of 1. Otherwise, it returns 0. |
|
prefix_match_ratio |
A word-level prefix matching feature. The match score is the length of the longest common prefix between the query and the field divided by the query length. Prefix matching means that each word from the beginning of the query and the document is matched in order. It is suitable for scenarios where the match position is important, such as email matching where a match at the beginning is more relevant. It is recommended to use this with other features, such as lcs_match_ratio. |
|
char_prefix_match_ratio |
A character-level prefix matching feature. The match score is the length of the longest common prefix between the query and the field divided by the query length. It is suitable for scenarios where the match position is important, such as email matching where a match at the beginning is more relevant. It is recommended to use this with other features, such as lcs_match_ratio. |
|
pinyin_prefix_match_ratio |
A Pinyin prefix matching feature. The match score is the length of the longest common prefix between the query and the field divided by the query length. It is suitable for scenarios where the match position is important, such as email matching where a match at the beginning is more relevant. It is recommended to use this with other features, such as lcs_match_ratio. |
|
is_contained |
Checks if the query is an exact match for any item in a given list-type field. It is used for matching tags. The corresponding index field must be of type list[string]. |
|
contained_boost |
The number of times the full query appears in a given field. It is used to boost the relevance of exact query matches. |
|
part_of_doc |
Checks if the full query appears in a given field (1 if it appears, 0 if not). It is used to boost the relevance of exact query matches. |
Best practices
Tips: The following examples assume that a field named "content" exists in the index.
{
    "rankModelInfo":{
        "default":{
            "features":[
                {
                    "name":"text_index",
                    "weights":1,
                    "threshold":10,
                    "norm":true
                },
                {
                    "name":"query_match_ratio",
                    "weights":1,
                    "threshold":0,
                    "field":"content"
                }
            ],
            "aggregate_algo":"weight_avg"
        }
    }
}
{
"rankModelInfo":{
"default":{
"features":[
{
"name":"static_value",
"field":"_rc_t_score",
"weights":1,
"threshold":10,
"norm":true
},
{
"name":"vector_index",
"weights":1,
"threshold":0,
"norm":true,
"norm_factor":0.001,
"score_type": "L2"
},
{
"name":"query_match_ratio",
"weights":1,
"threshold":0,
"field":"content"
}
],
"aggregate_algo":"weight_avg"
}
}
}{
"rankModelInfo": {
"default": {
"features": [
{
"name": "static_value",
"field": "_rc_t_score",
"weights": 1,
"threshold": 10,
"norm": true
},
{
"name": "vector_index",
"weights": 1,
"threshold": 0,
"norm": true,
"norm_factor": 0.001,
"score_type": "L2"
},
{
"name": "query_match_ratio",
"weights": 1,
"threshold": 0,
"field": "title"
}
],
"aggregate_algo": "weight_avg"
}
},
"keyword": {
"features": [
{
"name": "query_match_ratio",
"weights": 1,
"threshold": 0,
"field": "content"
}
],
"aggregate_algo": "weight_avg"
}
}This example shows a sorting formula with an extra query named "keyword". You need to configure a query field with the same name as the feature field (in this case, "keyword") in the "extras" field.
Conversation testing
After you configure and save all parameters, you can start testing the conversation. You can enter your query in the input box on the interface or through the Multi-turn Conversational Search API to retrieve the corresponding answer. The LLM summarizes and generates a response based on the retrieved knowledge snippets and contextual information.