Search enhancement
Service creation
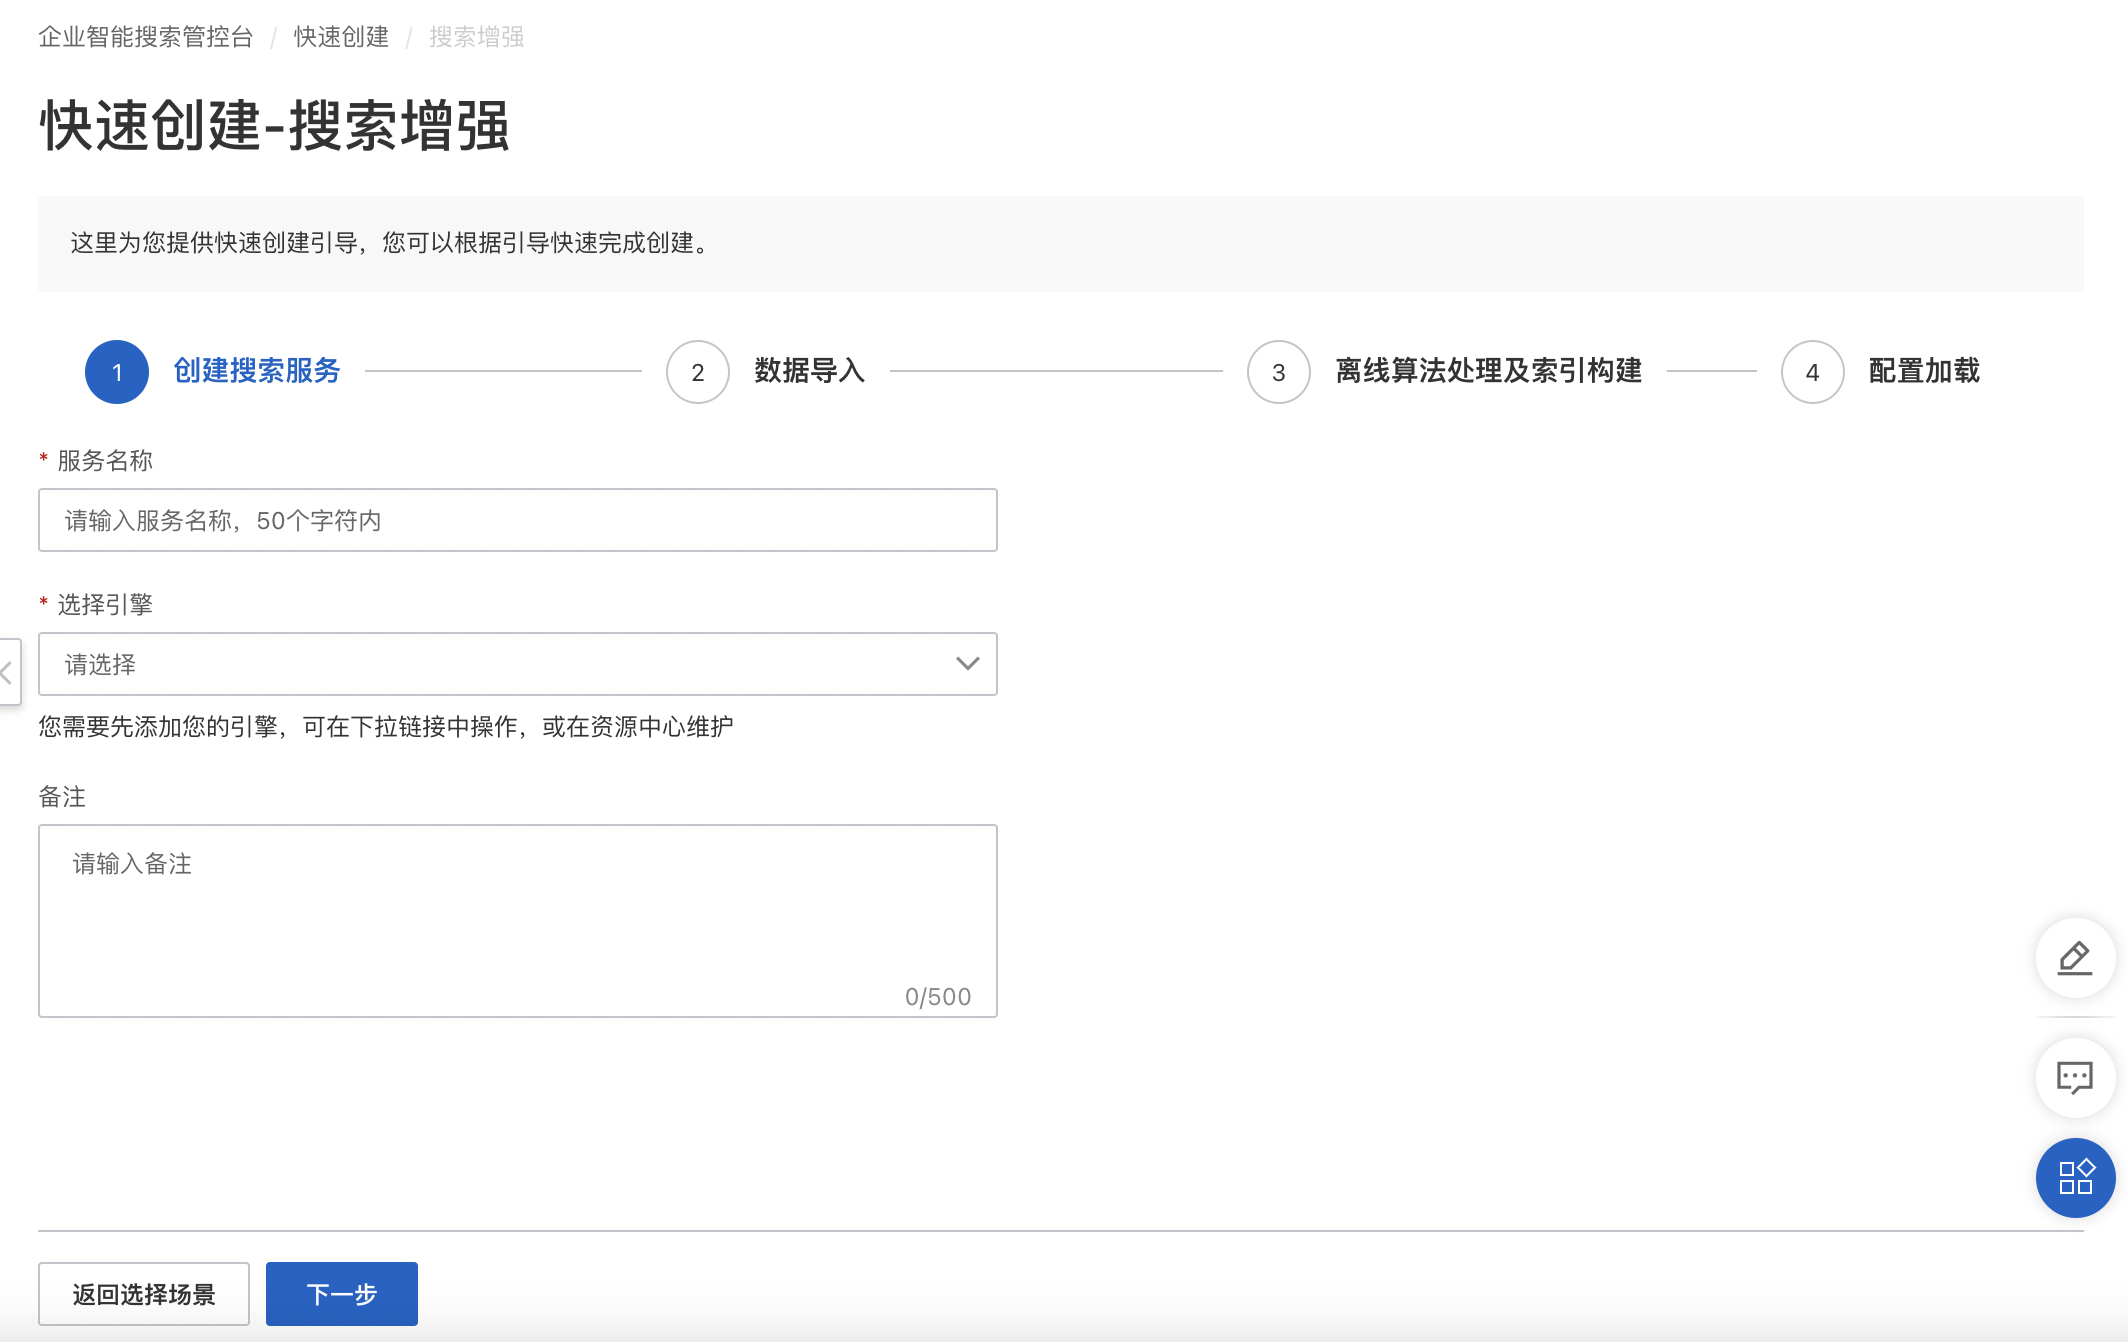
Click quick create and select search enhancement to open the service creation page. Enter the service name and select an engine and a data source. After the service is created, you are redirected to the index configuration page.
Engine
The engine is the core component that provides search services. You can manage engines in the Resource Center or select and add them directly on the quick create page. For more information, see the engine management guide.
Supported engines | Version | Configuration | Plugin | Link |
Alibaba Cloud Elasticsearch | V8.9 V7.10 V7.7 V6.8 V6.7 | A 2-core, 8 GB configuration is recommended for basic use, while an 8-core, 32 GB configuration is recommended for vector search. | None |
Data import
Data source
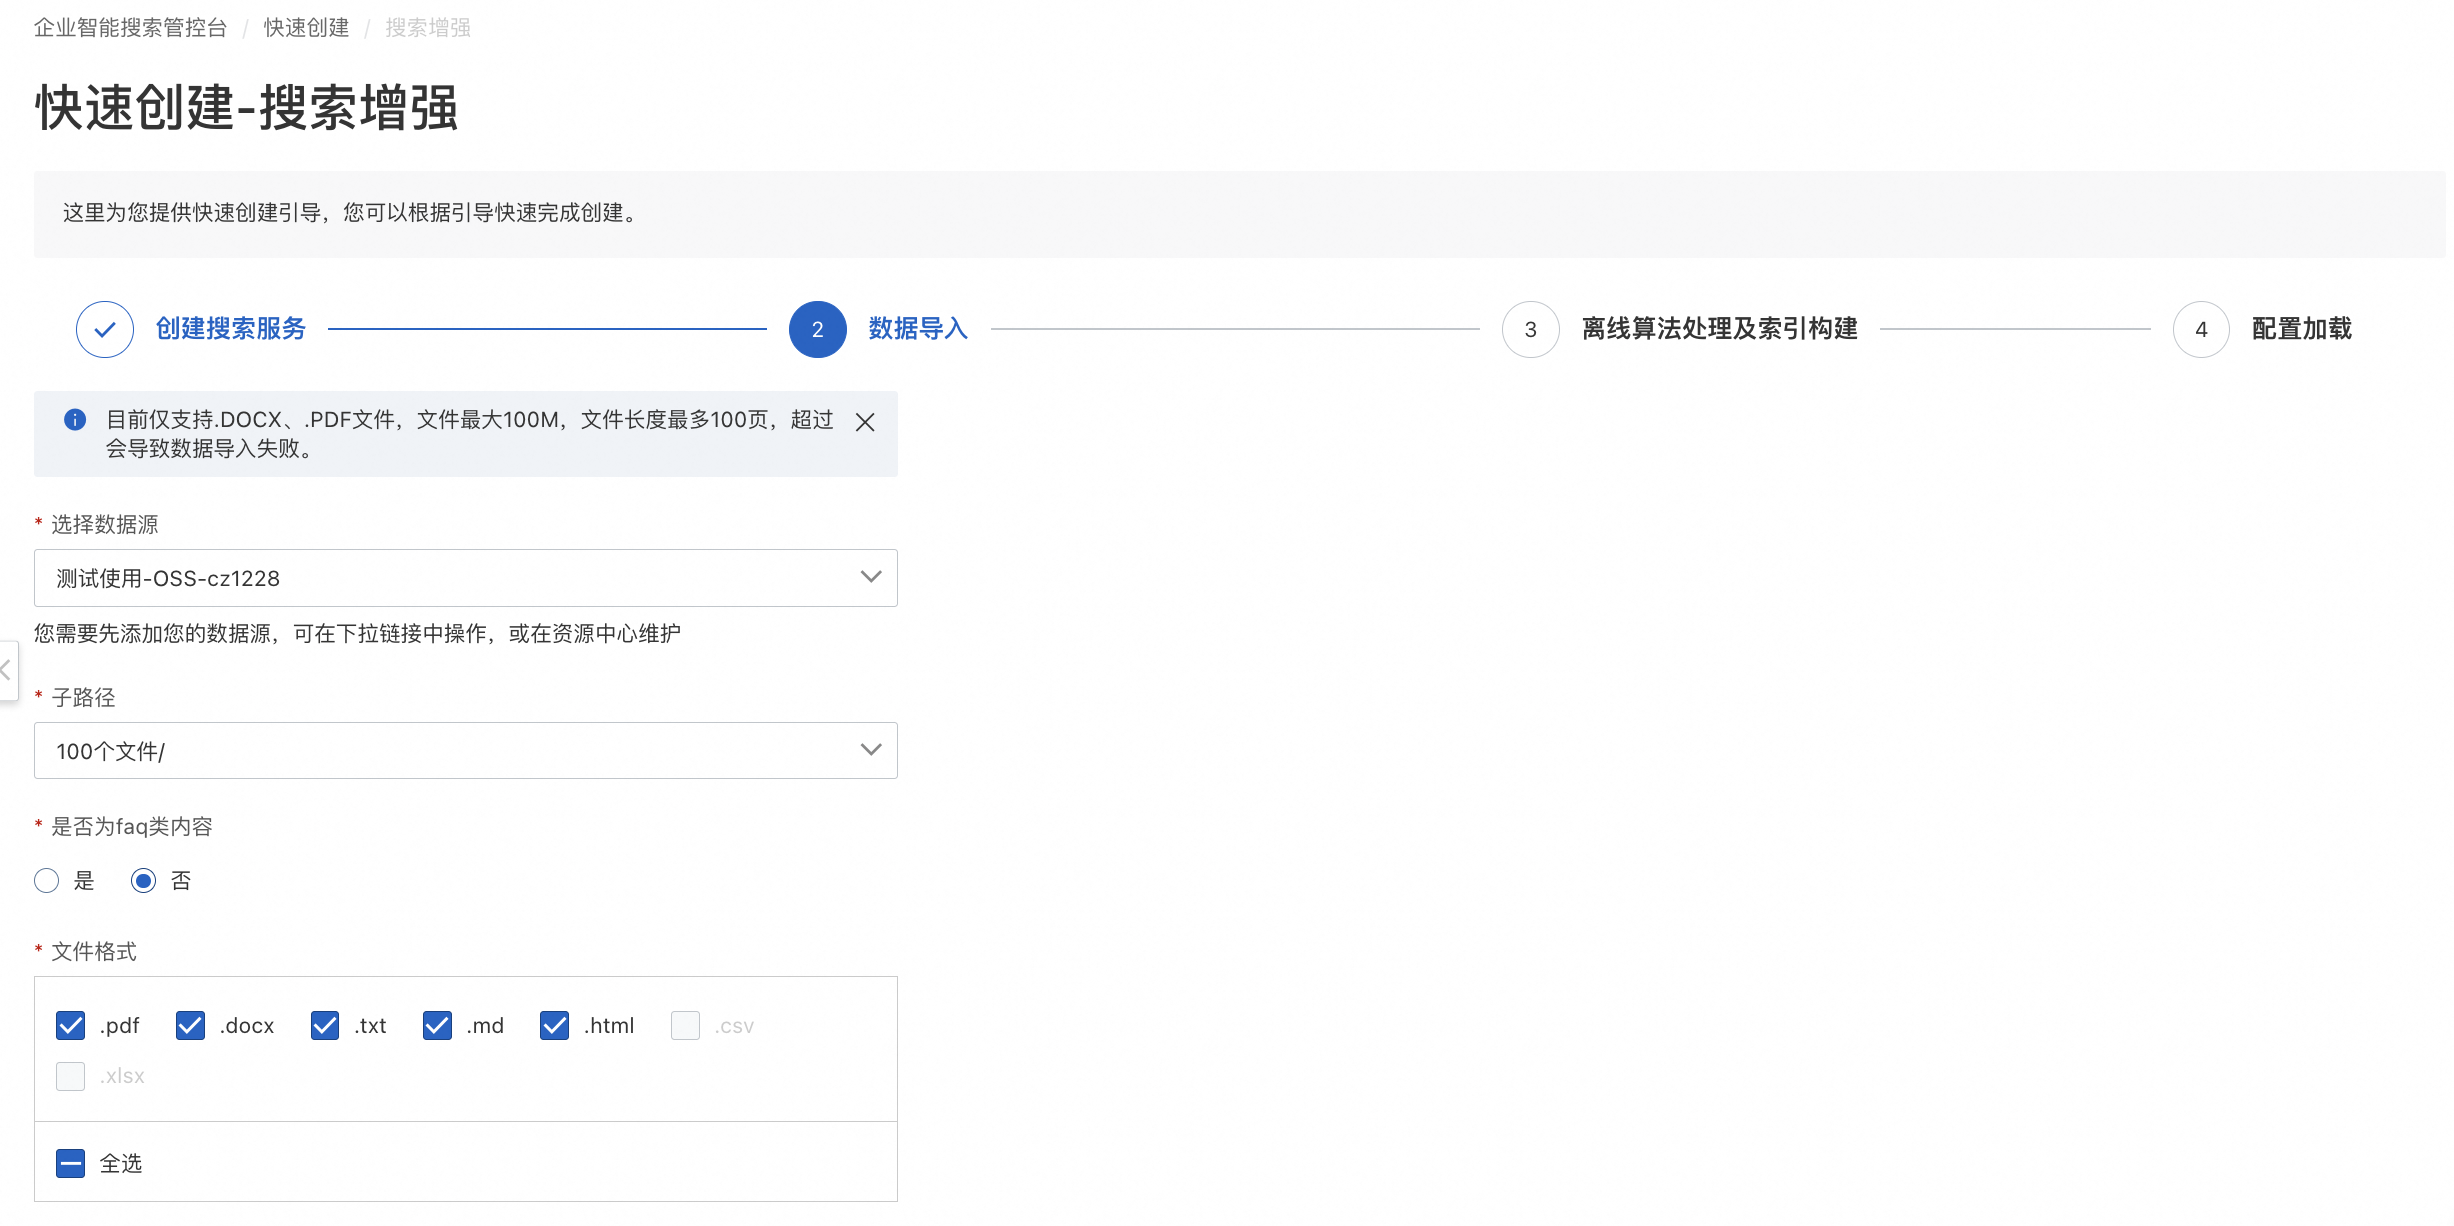
You can manage data sources for your enterprise knowledge base in the Resource Center, or add them directly on the Quick Creation page. For more information, see the Data Source Management guide.
Supported data sources | Links |
ApsaraDB RDS for MySQL | |
MaxCompute | |
OSS |
Subpath/database and table
Specify the location of your data within the selected data source. You can provide a subpath to target specific directories and files, or select a database and table.
Parsed fields
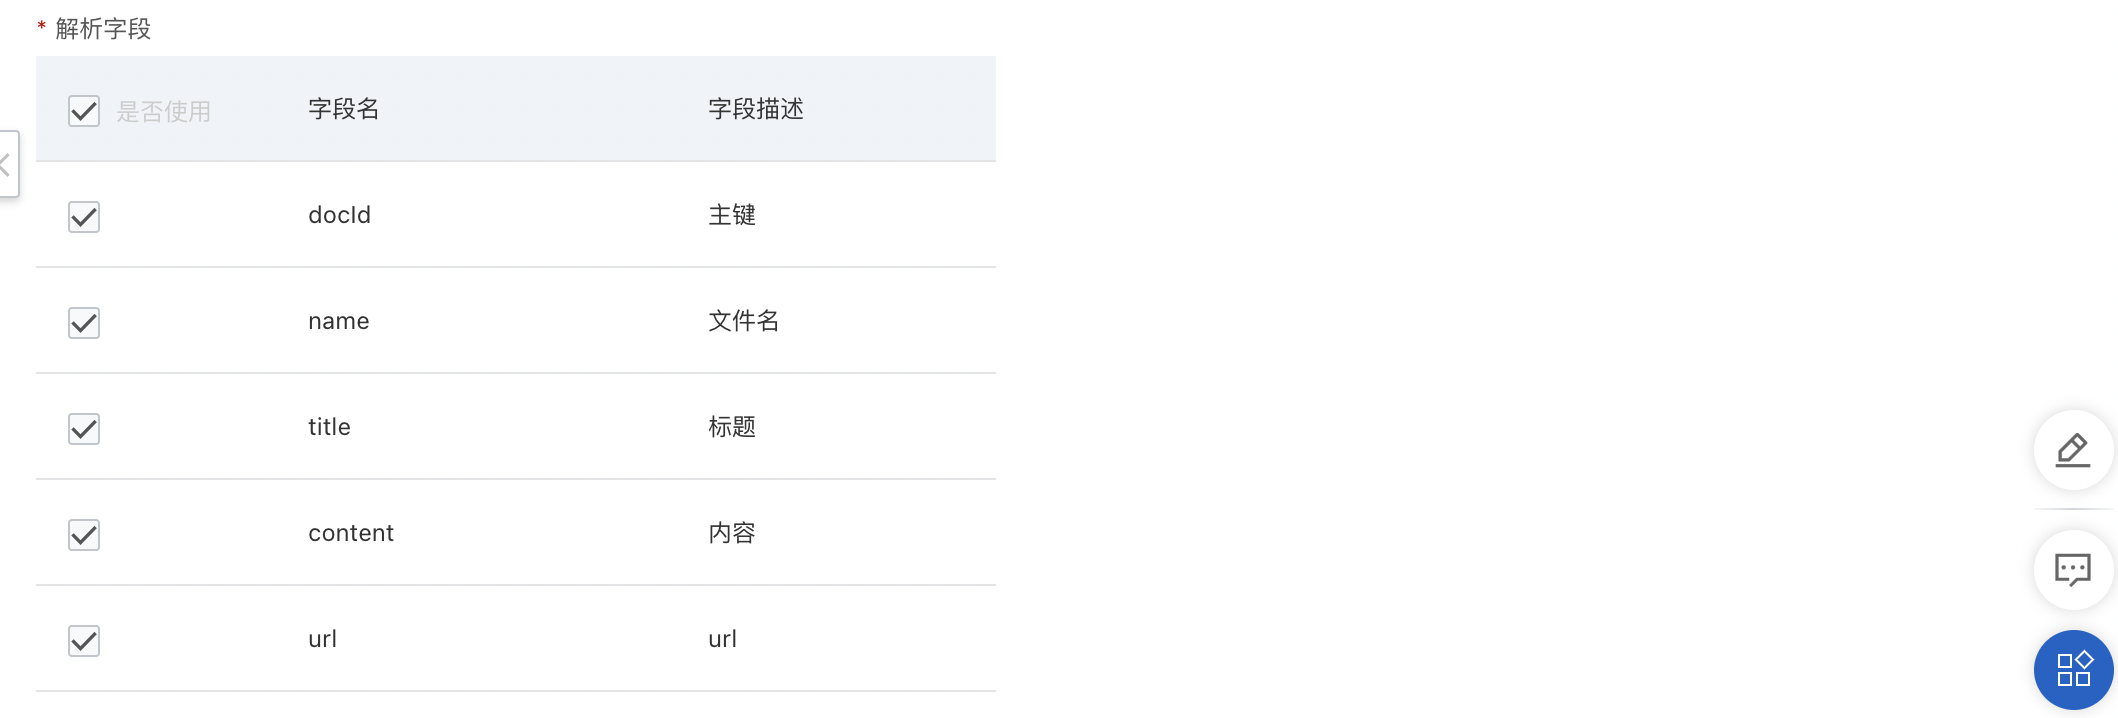
The system parses data source fields offline for index creation.
Select the fields you want to index. The system uses these fields for recall and ranking during searches and can also display them in the query results. Unselected fields are not indexed.
Data source type | Is FAQ | Parsed fields |
ApsaraDB RDS for MySQL and MaxCompute | Yes | The database and table must contain the following fields: |
No | You can select any fields from the chosen database and table to be parsed. | |
OSS | Yes | Supported file formats: The data source must contain the following fields: |
No | Supported file formats: The parsed fields consist of a fixed set of default fields. |
Configure an index
Data source table
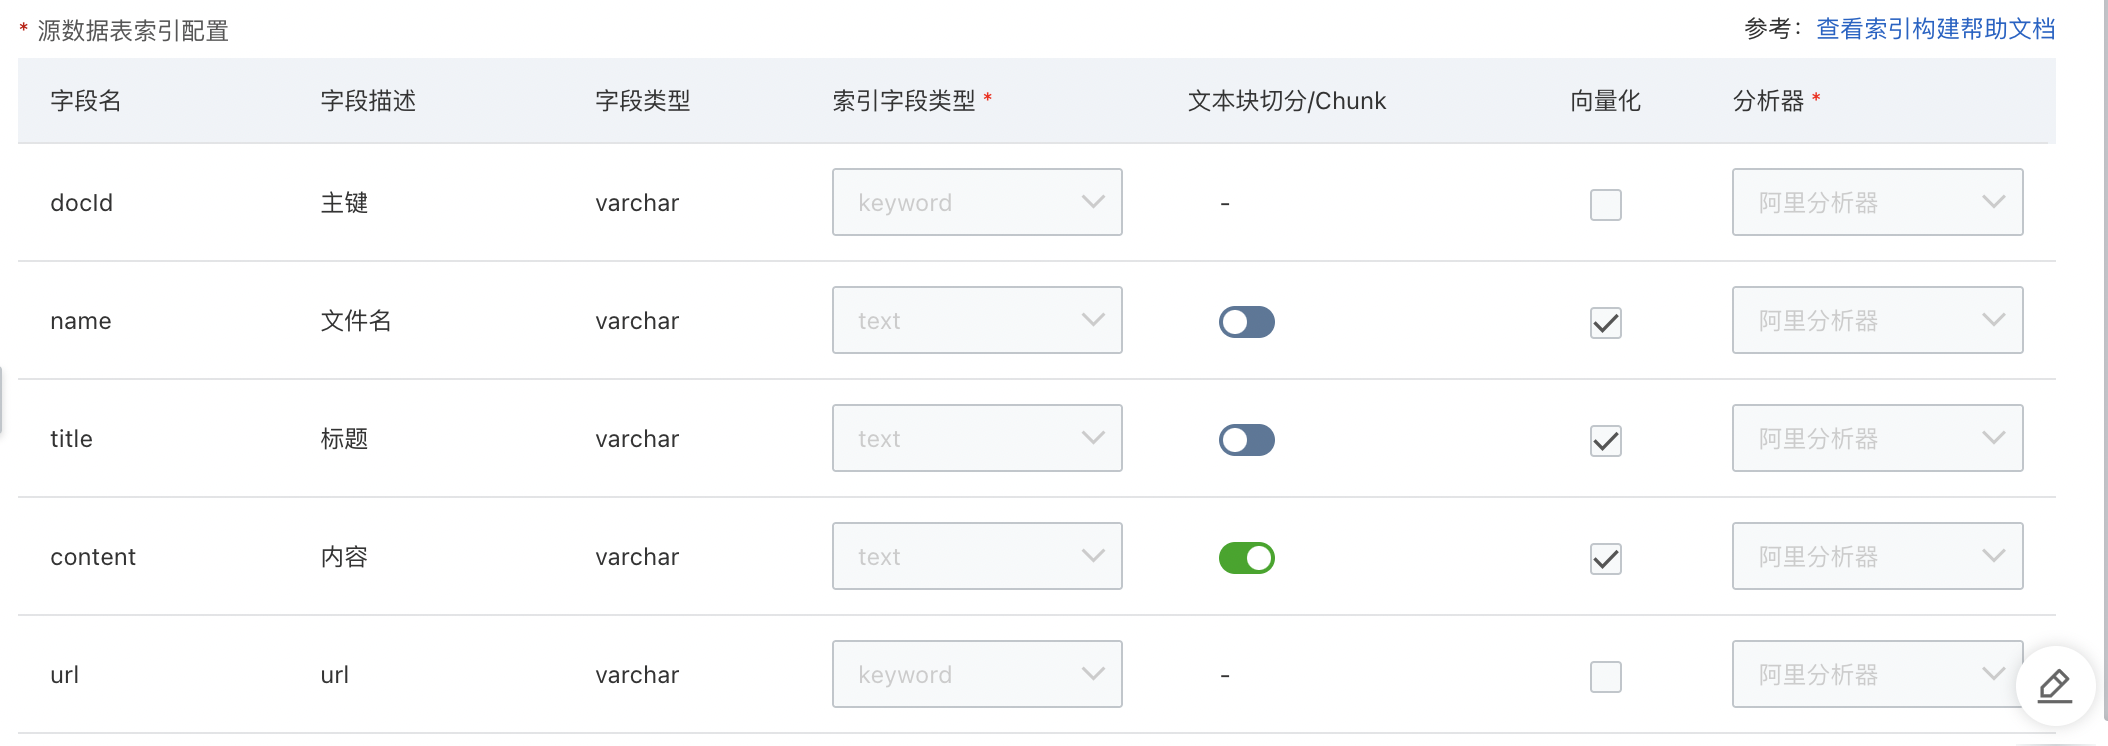
Field name, description, and type
For instances that use OSS files as a data source, the field names match the fields in the offline data parsing results. The default field names from offline parsing include the following:
Parameter | Description | Type |
docId | Primary key and unique identifier. | varchar |
name | The file name. | varchar |
title | The title of the parsed chunk. | varchar |
content | The body content of the parsed chunk. | varchar |
url | URL | varchar |
For instances that use a database as a data source, the field names must match the column names of the source table. Field names cannot start with an underscore (_).
Index field type
An index field's type defines how a search engine, such as Elasticsearch, processes and indexes the field's values.
The following index field types are available:
Index field type | Description |
text | Used to index long-form text, such as article content or descriptions. Text fields undergo tokenization, allowing them to be searched and matched based on individual words. |
keyword | Used to index short, exact text, such as tags or identifiers. Keyword fields are not tokenized; the entire field is indexed and matched as a single term. |
integer | Indexes INT values. Supports sorting and range queries. |
long | Indexes LONG values. Supports sorting and range queries. |
double | Indexes DOUBLE values. Supports sorting and range queries. |
float | Indexes FLOAT values. Supports sorting and range queries. |
date | Indexes dates and times. Supports date range queries and sorting. |
boolean | Indexes boolean values: |
binary | Indexes binary data, such as images or files. |
Chunking
In search enhancement scenarios, enabling chunking for a field divides its content into smaller pieces to meet the needs of downstream tasks. Use the following recommendations based on your data source and use case:
For OSS file data sources, the offline data processing workflow automatically analyzes the data into chunks. You must enable chunking for the
titleorcontentfield to trigger this offline analysis process.For database data sources that already contain processed data, you do not need to enable chunking.
Analyzer
During index creation, an analyzer breaks text data into terms. As a key component of text analysis, it builds an inverted index to make the text searchable.
An analyzer splits input text according to specific rules. It can divide a long text into individual characters or word segments, allowing these segments to be indexed and searched.
Enterprise search provides a variety of built-in analyzers, including:
Alibaba analyzer
Description: A Chinese and English tokenization tool developed by Alibaba.
Tokenization Example:
Input text: "阿里巴巴是一家全球的互联网科技公司。" (Alibaba is a global internet technology company.)

Tokenization result: "阿里巴巴 / 是 / 一家 / 全球 / 的 / 互联网 / 科技 / 公司 / 。"
IK analyzer
Description: An open-source IK analyzer with tokenization results similar to the Alibaba Analyzer.
Single character analyzer
Description: Splits text by individual characters (UTF-8 encoding). Use this for search scenarios that require high recall but have low semantic search requirements.
Tokenization Example:
Input text: "单字分词器是一种最基础的分词方式。" (A single-character tokenizer is a very basic tokenization method.)

Tokenization result: "单 / 字 / 分 / 词 / 器 / 是 / 一 / 种 / 最 / 基 / 础 / 的 / 分 / 词 / 方 / 式 / 。"
Pinyin analyzer
Description: Analyzes Chinese character fields into Pinyin. Use this for Pinyin-based search scenarios.
Tokenization Example:
Input text: "我爱中文分词器" (I love Chinese tokenizers)

Tokenization result: "wo ai zhong wen fen ci qi"
N-gram analyzer
Description: Splits text into N-grams based on characters (UTF-8 encoding). The default value for N is 3.
Tokenization Example:
Input text: "中文分词器" (Chinese tokenizer)

N-gram tokenization result (N=3): "中 / 文 / 分 / 词 / 器/ 中文 / 文分 / 分词 / 词器/ 中文分 / 文分词 / 分词器"
Selecting the appropriate analyzer improves accuracy and flexibility when indexing and querying text data.
Feature enhancement
Feature enhancement improves search quality and efficiency by adding feature factors and applying corresponding algorithms. The available feature factors include:
Feature factor 1: Tokenization
Definition: The process of splitting a continuous character sequence into semantically independent tokens based on a set of rules.
What it does: Tokenizes text for indexing.
Example:
Input text: "a yellow dress", Result after tokenization: ["a", "yellow", "dress"]
Feature factor 2: Term weight
Definition: Scores the importance of each term in the tokenized input text.
What it does: Calculates the weight of each term in the text to be indexed.
Example:
Input text: "a yellow dress"
Term weight: [0.44163678889106406, 0.6124273381472254, 0.07400746404941613, 1.0]
Note: The length of the term weight output matches the length of the tokenization result.
Feature factor 3: Entity recognition
Definition: Identifies entities in text that have specific meanings, such as names of people, places, and organizations, as well as proper nouns, times, and quantities.
What it does: Performs entity recognition on the text to be indexed.
Example:
Input text: "a yellow dress"
Entity recognition result: {"mention": "yellow", "type": "color", "score": 1.0},
{"mention": "dress", "type": "category", "score": 1.0}
Note: mention is the entity term, type is the entity category, and score is the model's confidence score.
Vectorization
Vectorization is the process of converting text data into numerical vectors. It represents words and sentences as vectors so that their relevance can be calculated for tasks like information retrieval.
Vectorization example:
Input text: "a yellow dress"

Vectorization result: [0.2694664001464844,-0.3998311161994934,-0.14598636329174042,-0.4976918697357178,-0.13986249268054962,0.6272065043449402,-0.1434994637966156,-0.33319777250289917]
Note:
1. The vectorization result is a list of floating-point numbers. The length of the list depends on the output dimension of the vectorization model.
2. During index creation, vectorization only applies to fields of the text type.
3. If you select multiple text fields for vectorization, the model automatically concatenates the fields and computes a single vector result.
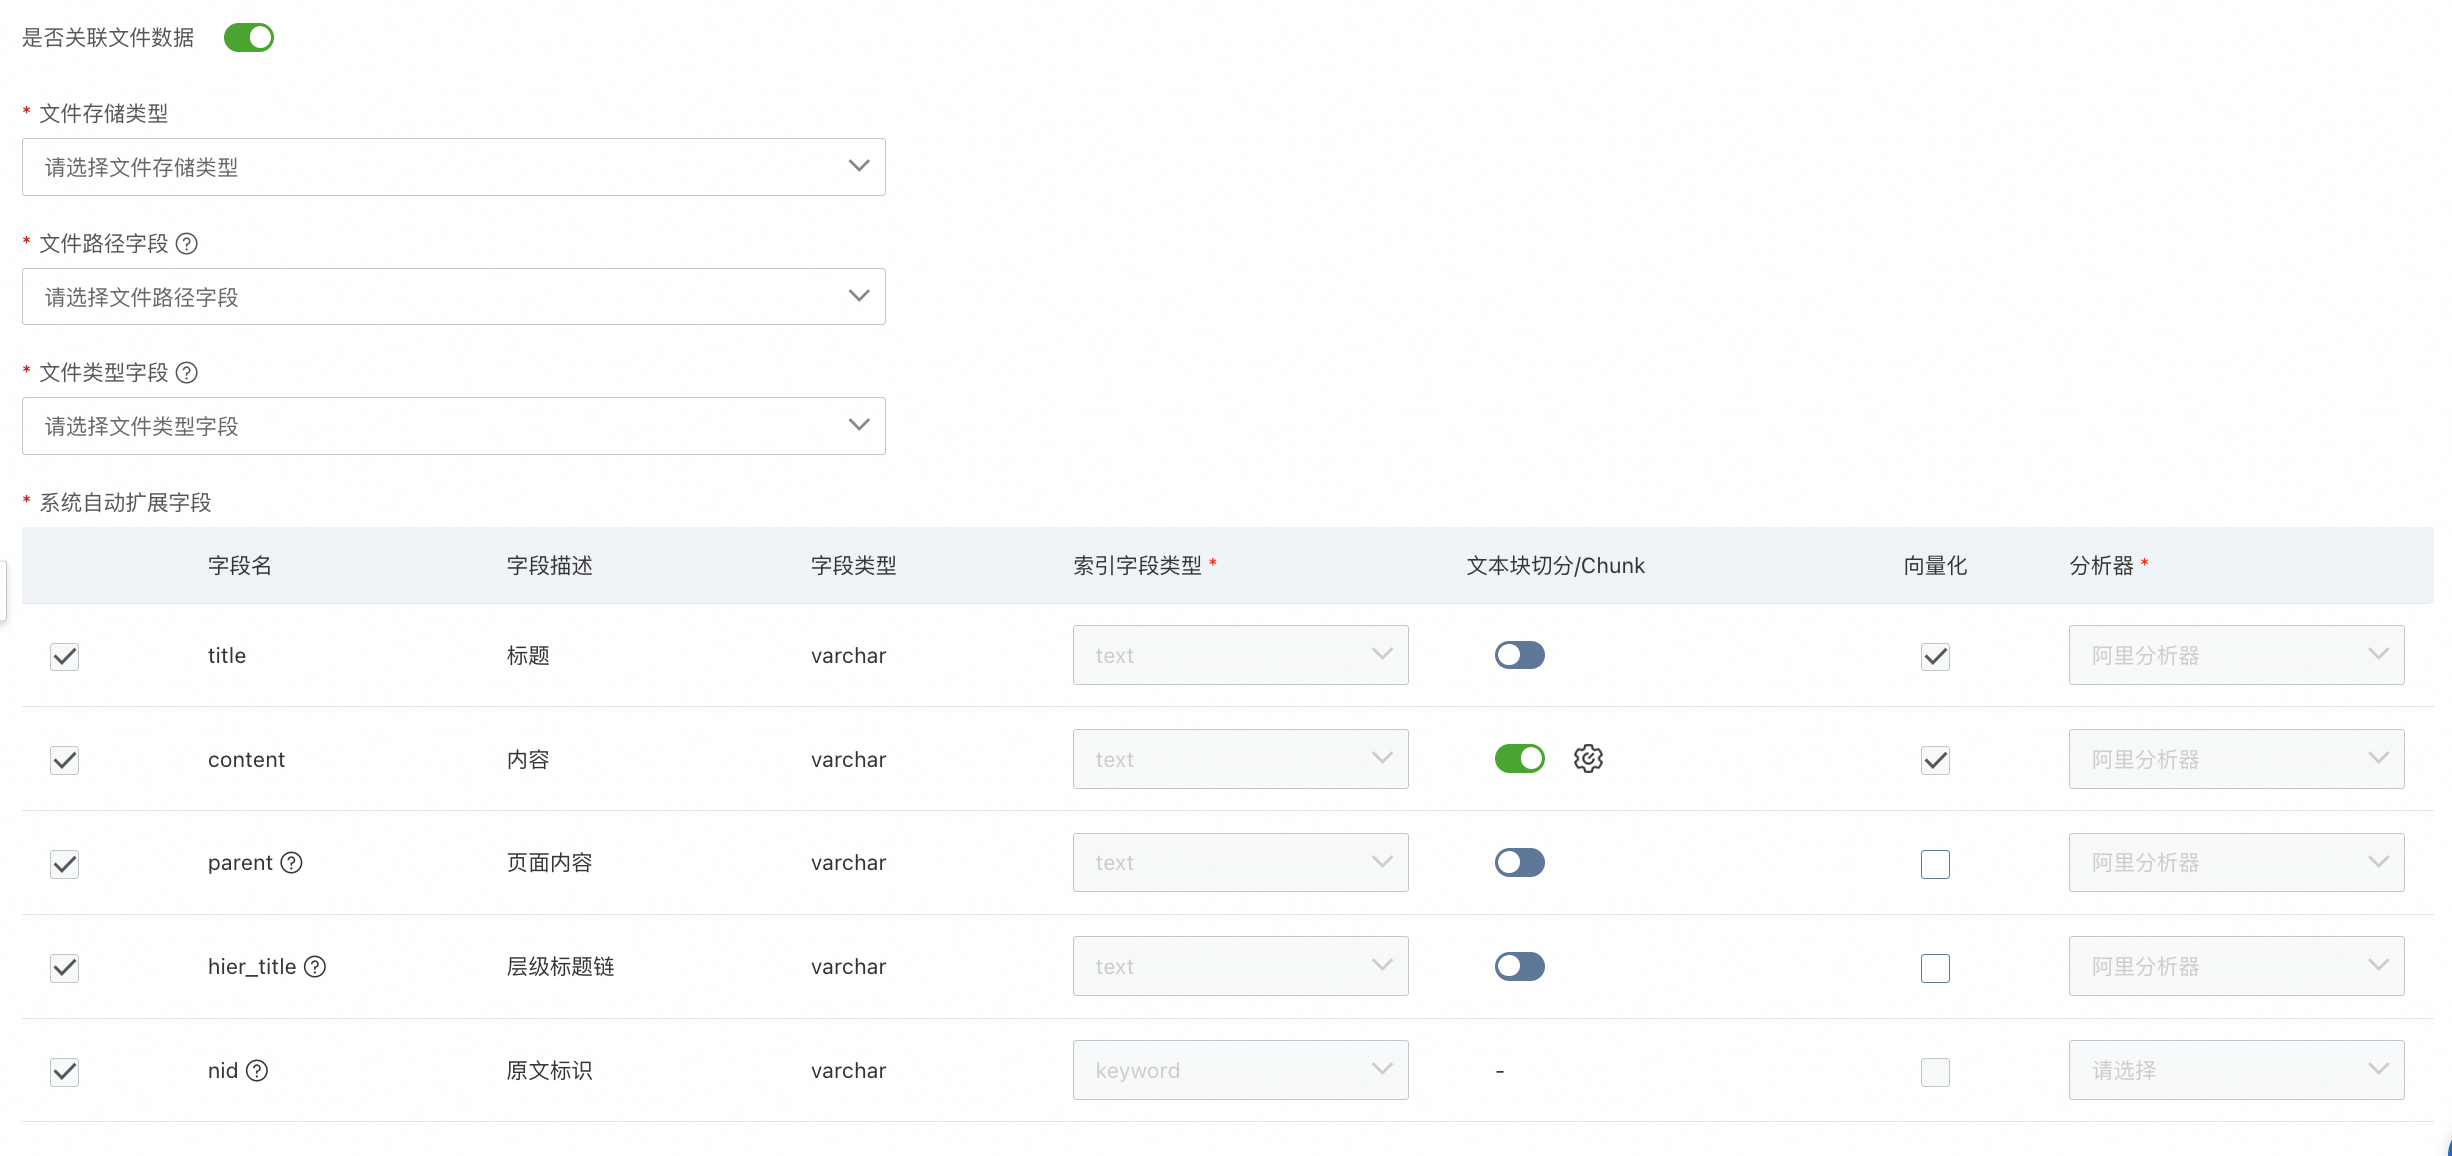
Associate file data
If your data source contains both file and database records, and your database contains fields for the file path and file type, you must enable the Associate File Data feature. For more details, refer to our best practices. Once enabled, the system performs a validation check. If any fields in your source table conflict with the system-extended fields (title, content, parent, hier_title, nid), you must exit the process and rename the conflicting fields.
File storage type
OSS and HTTP are supported.
File path field
Specifies the field that contains the OSS file path. This field must be of the keyword or text type.
File type field
Specifies the field that contains the file type. This field must be of the keyword or text type. Supported file types are .pdf, .docx, .txt, .md, and .html.
System-extended fields
The system automatically extends the data with the following fixed fields: title, content, parent, hier_title, and nid.
You can configure chunking parameters. The value for Chunk Size must be 50 or greater. The value for Chunk Overlap must be less than the specified chunk size and can be 0.
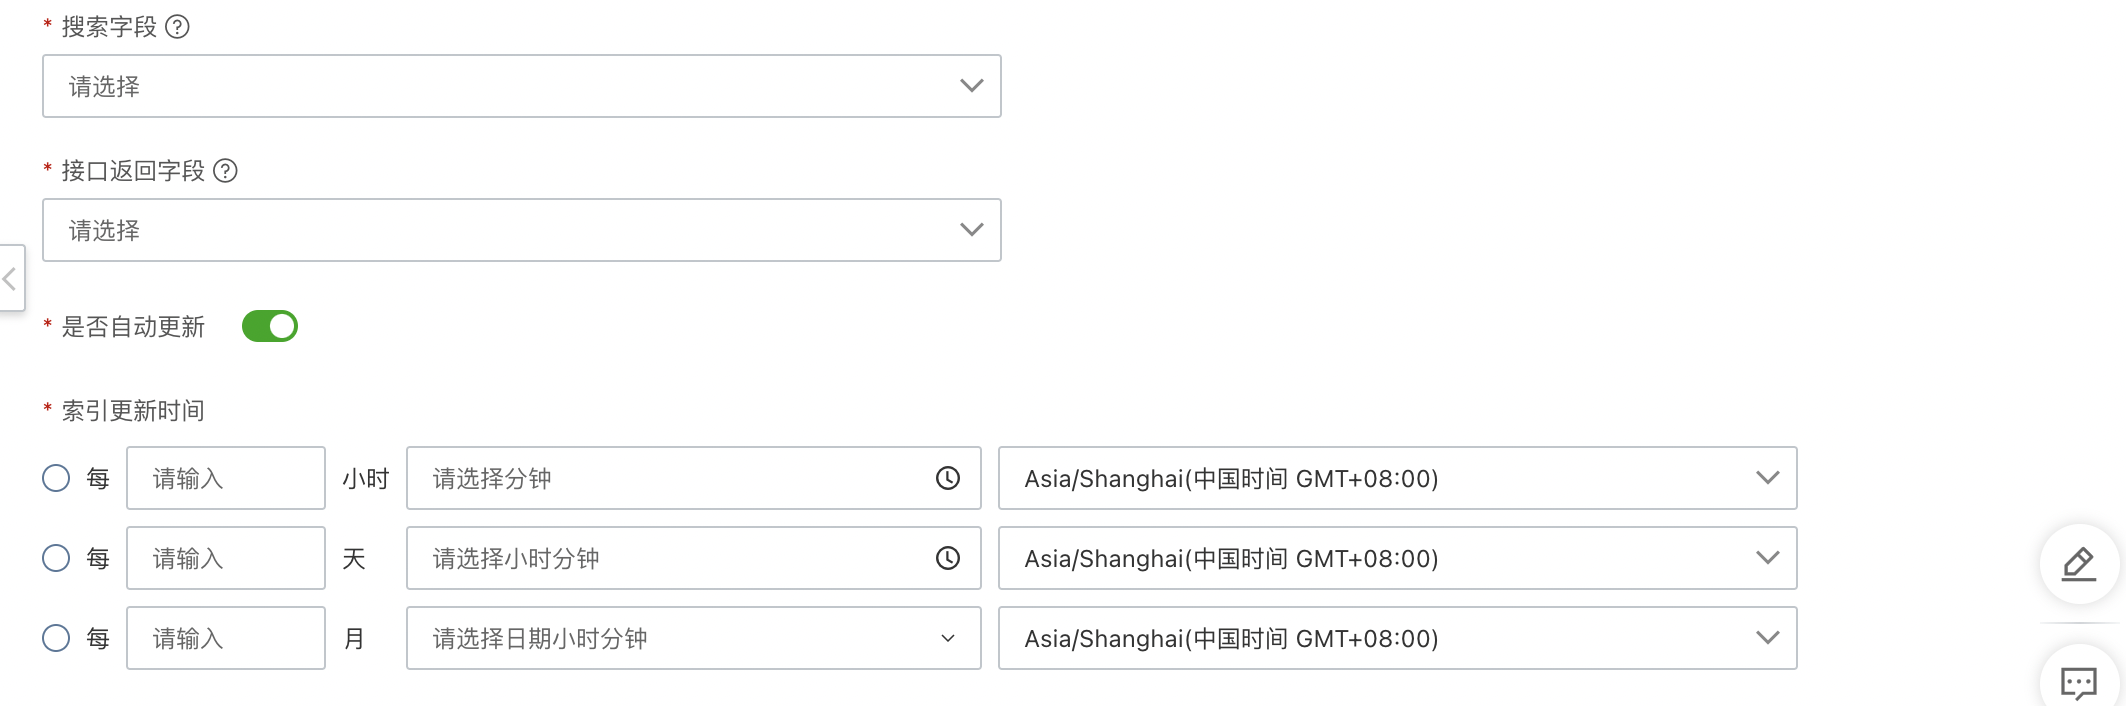
Search fields
These are the fields for full-text search. They must be of the keyword or text type and are used to execute queries, match conditions, and limit the search scope.
API return fields
These are the fields to include in the search response. You can select which fields to return in the index configuration. These fields are returned in the fields parameter of the open API response and can serve as reference content for multi-turn conversations with a large language model.
Auto update
Enable this switch if your data source index needs to be updated periodically. You can schedule updates to run on an hourly, daily, or monthly basis and configure the specific time and time zone.
Configuration loading
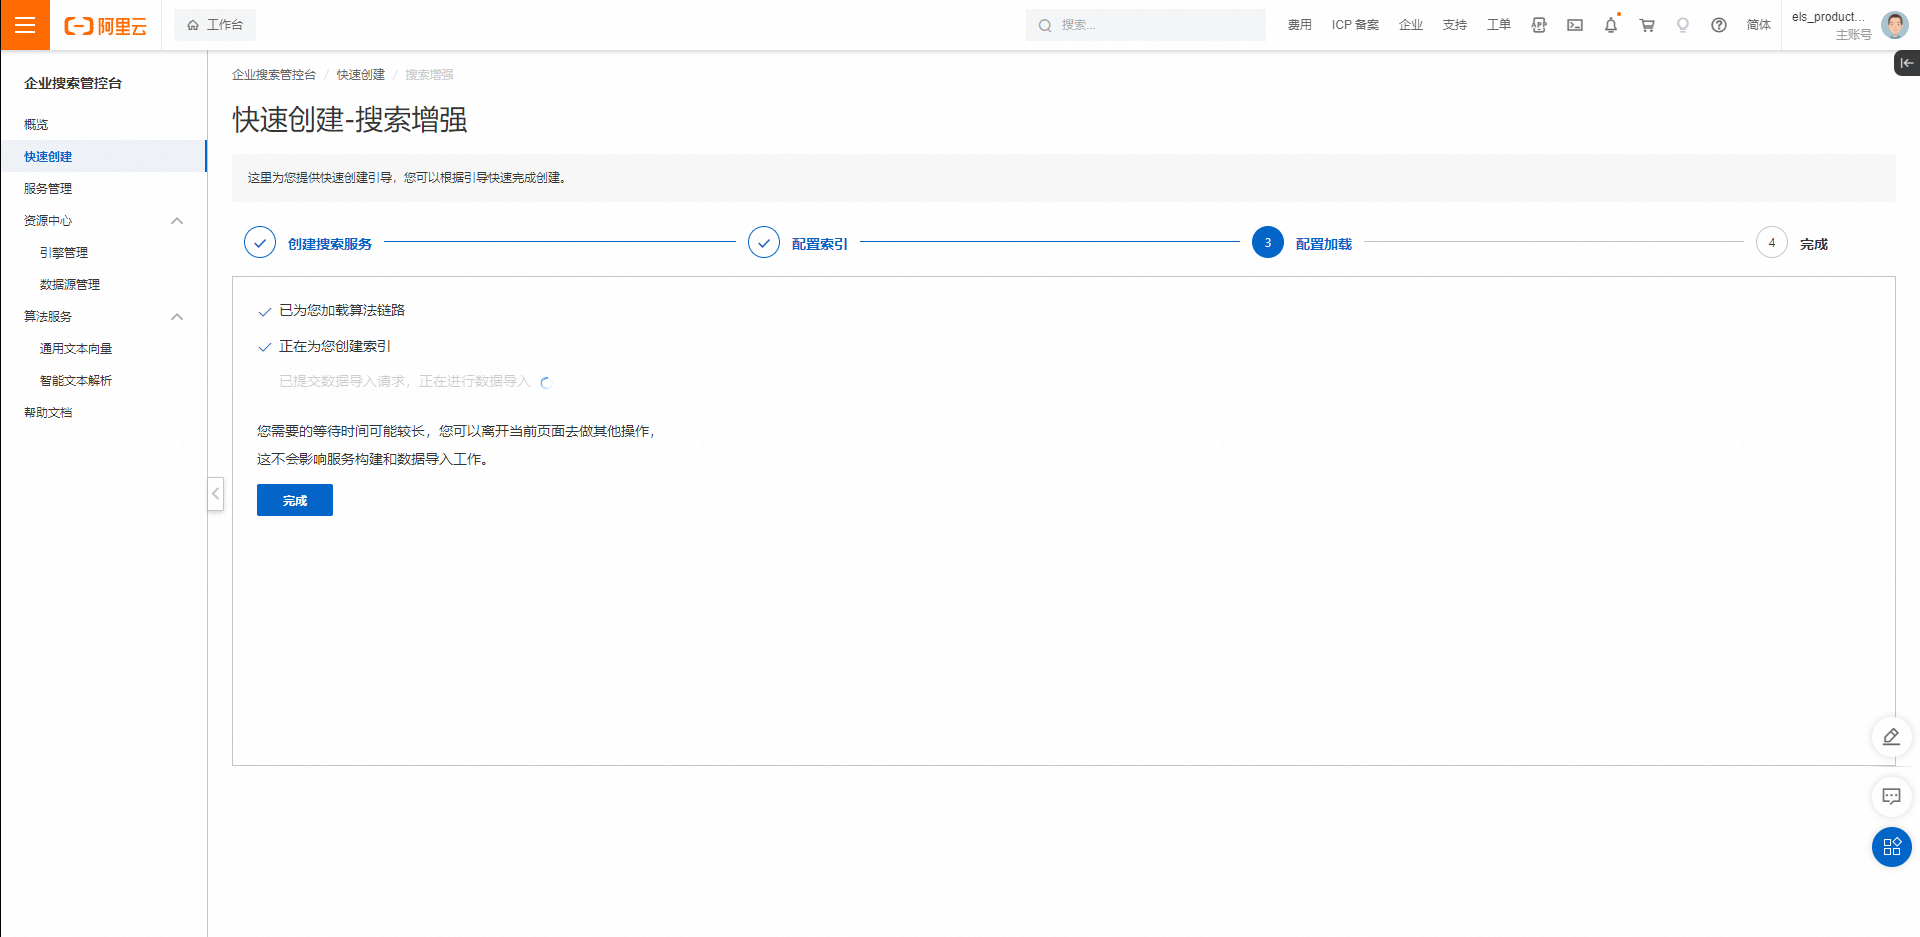
Once the creation and configuration process is complete, configuration loading begins. You can leave the current page during this process without affecting the service build and data import.
Service testing and online tuning
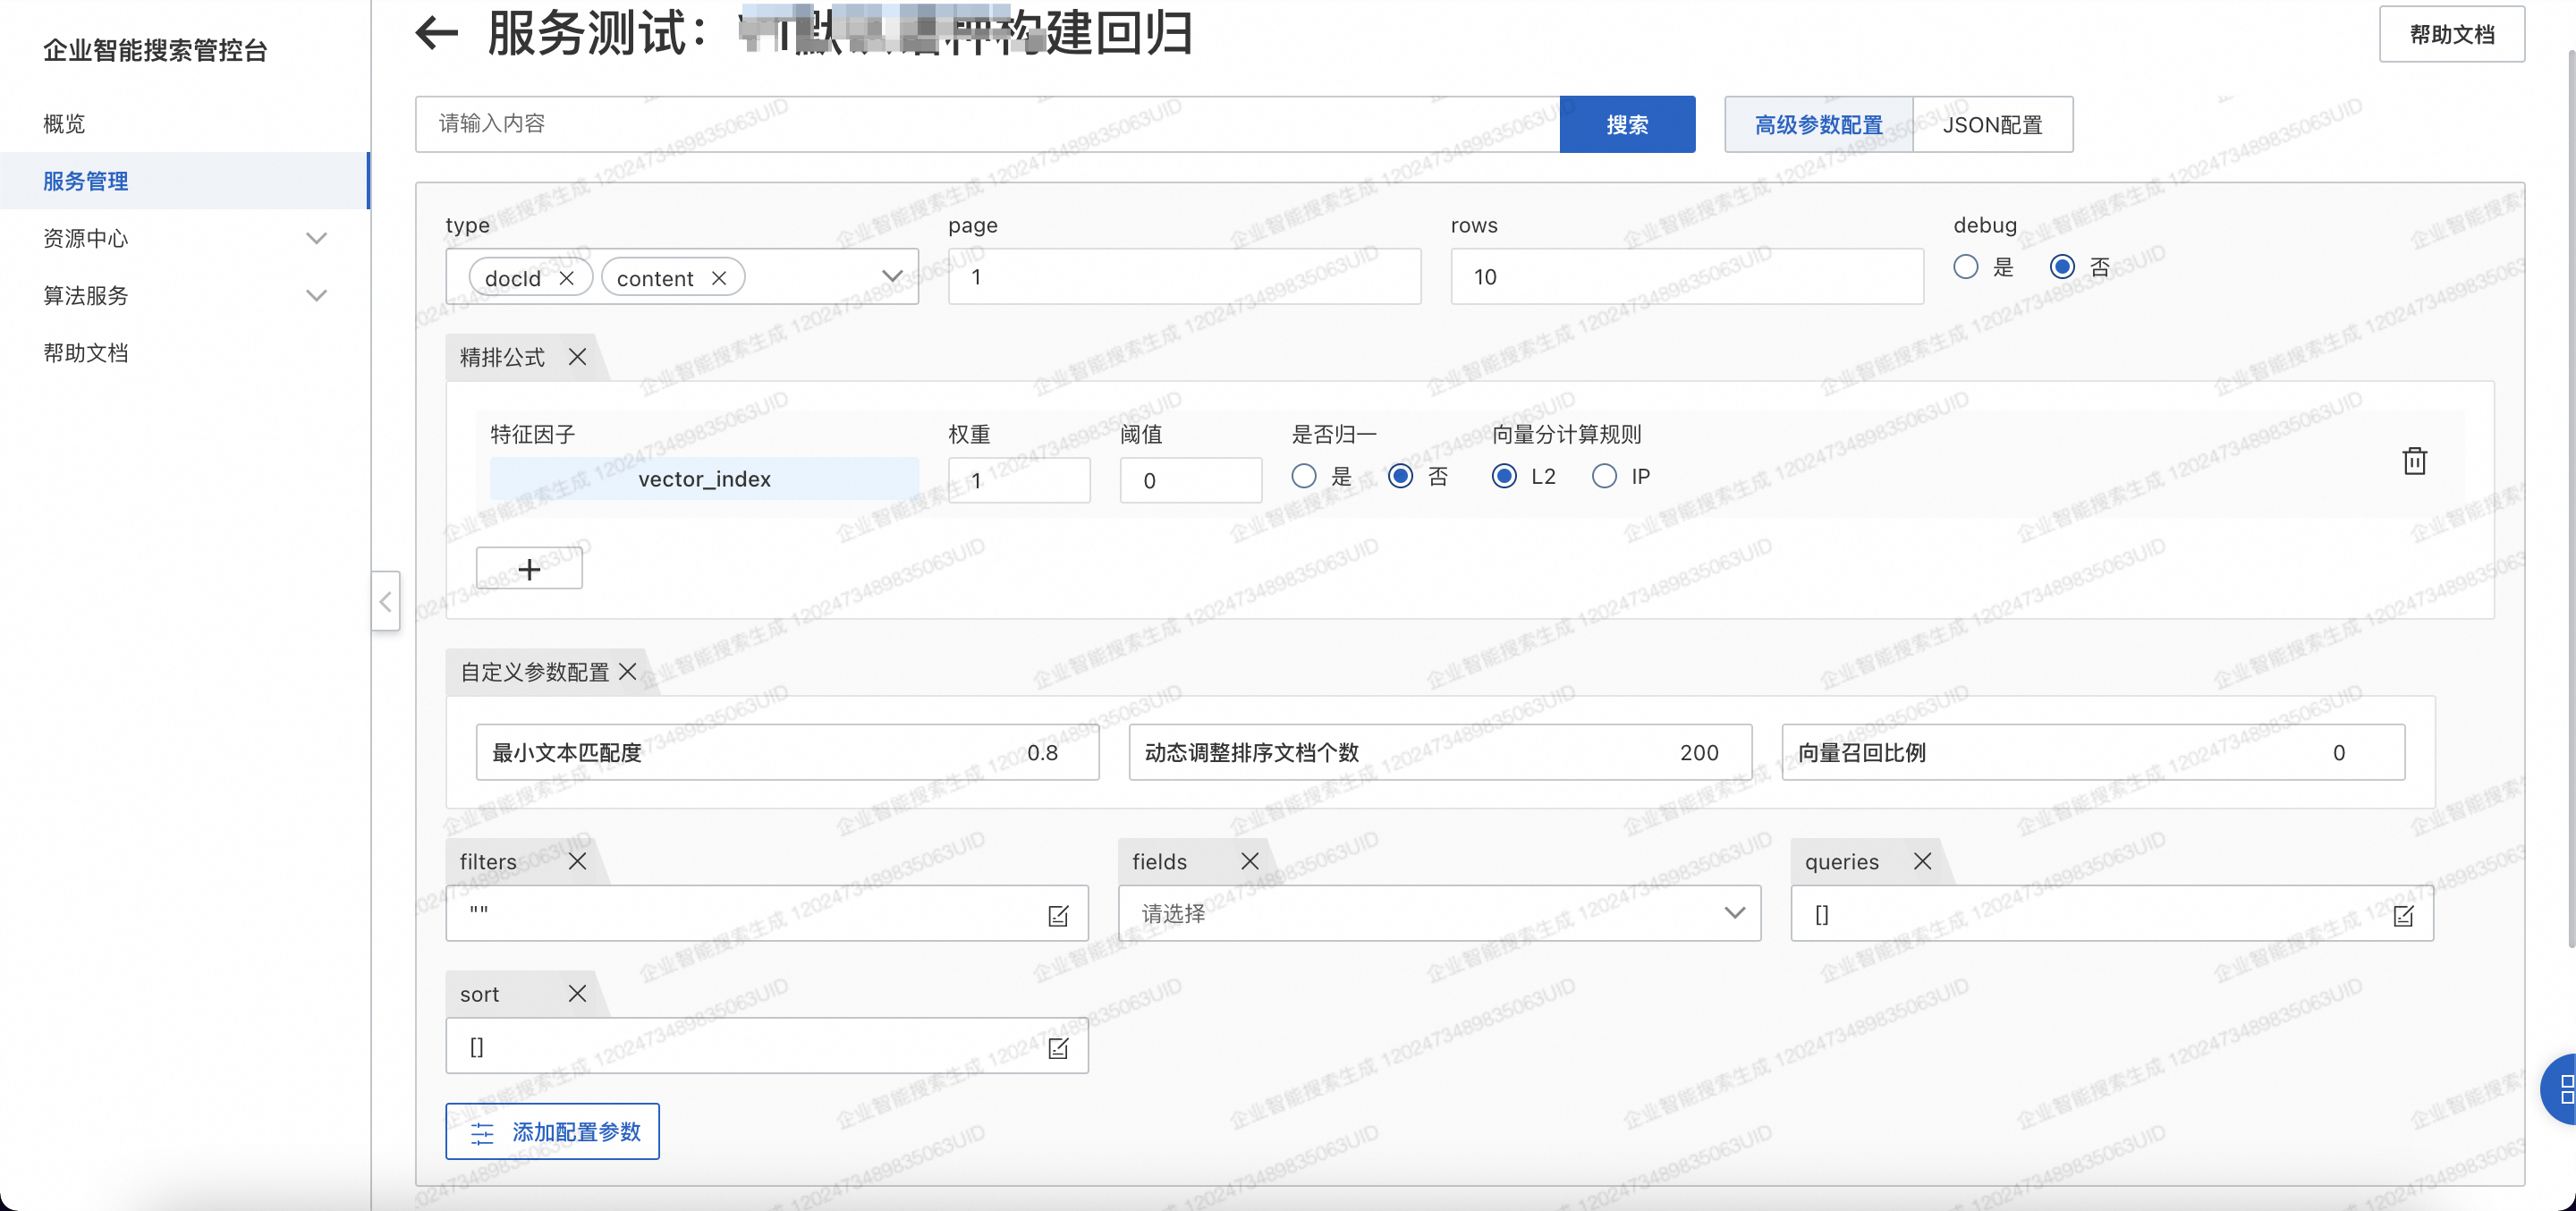
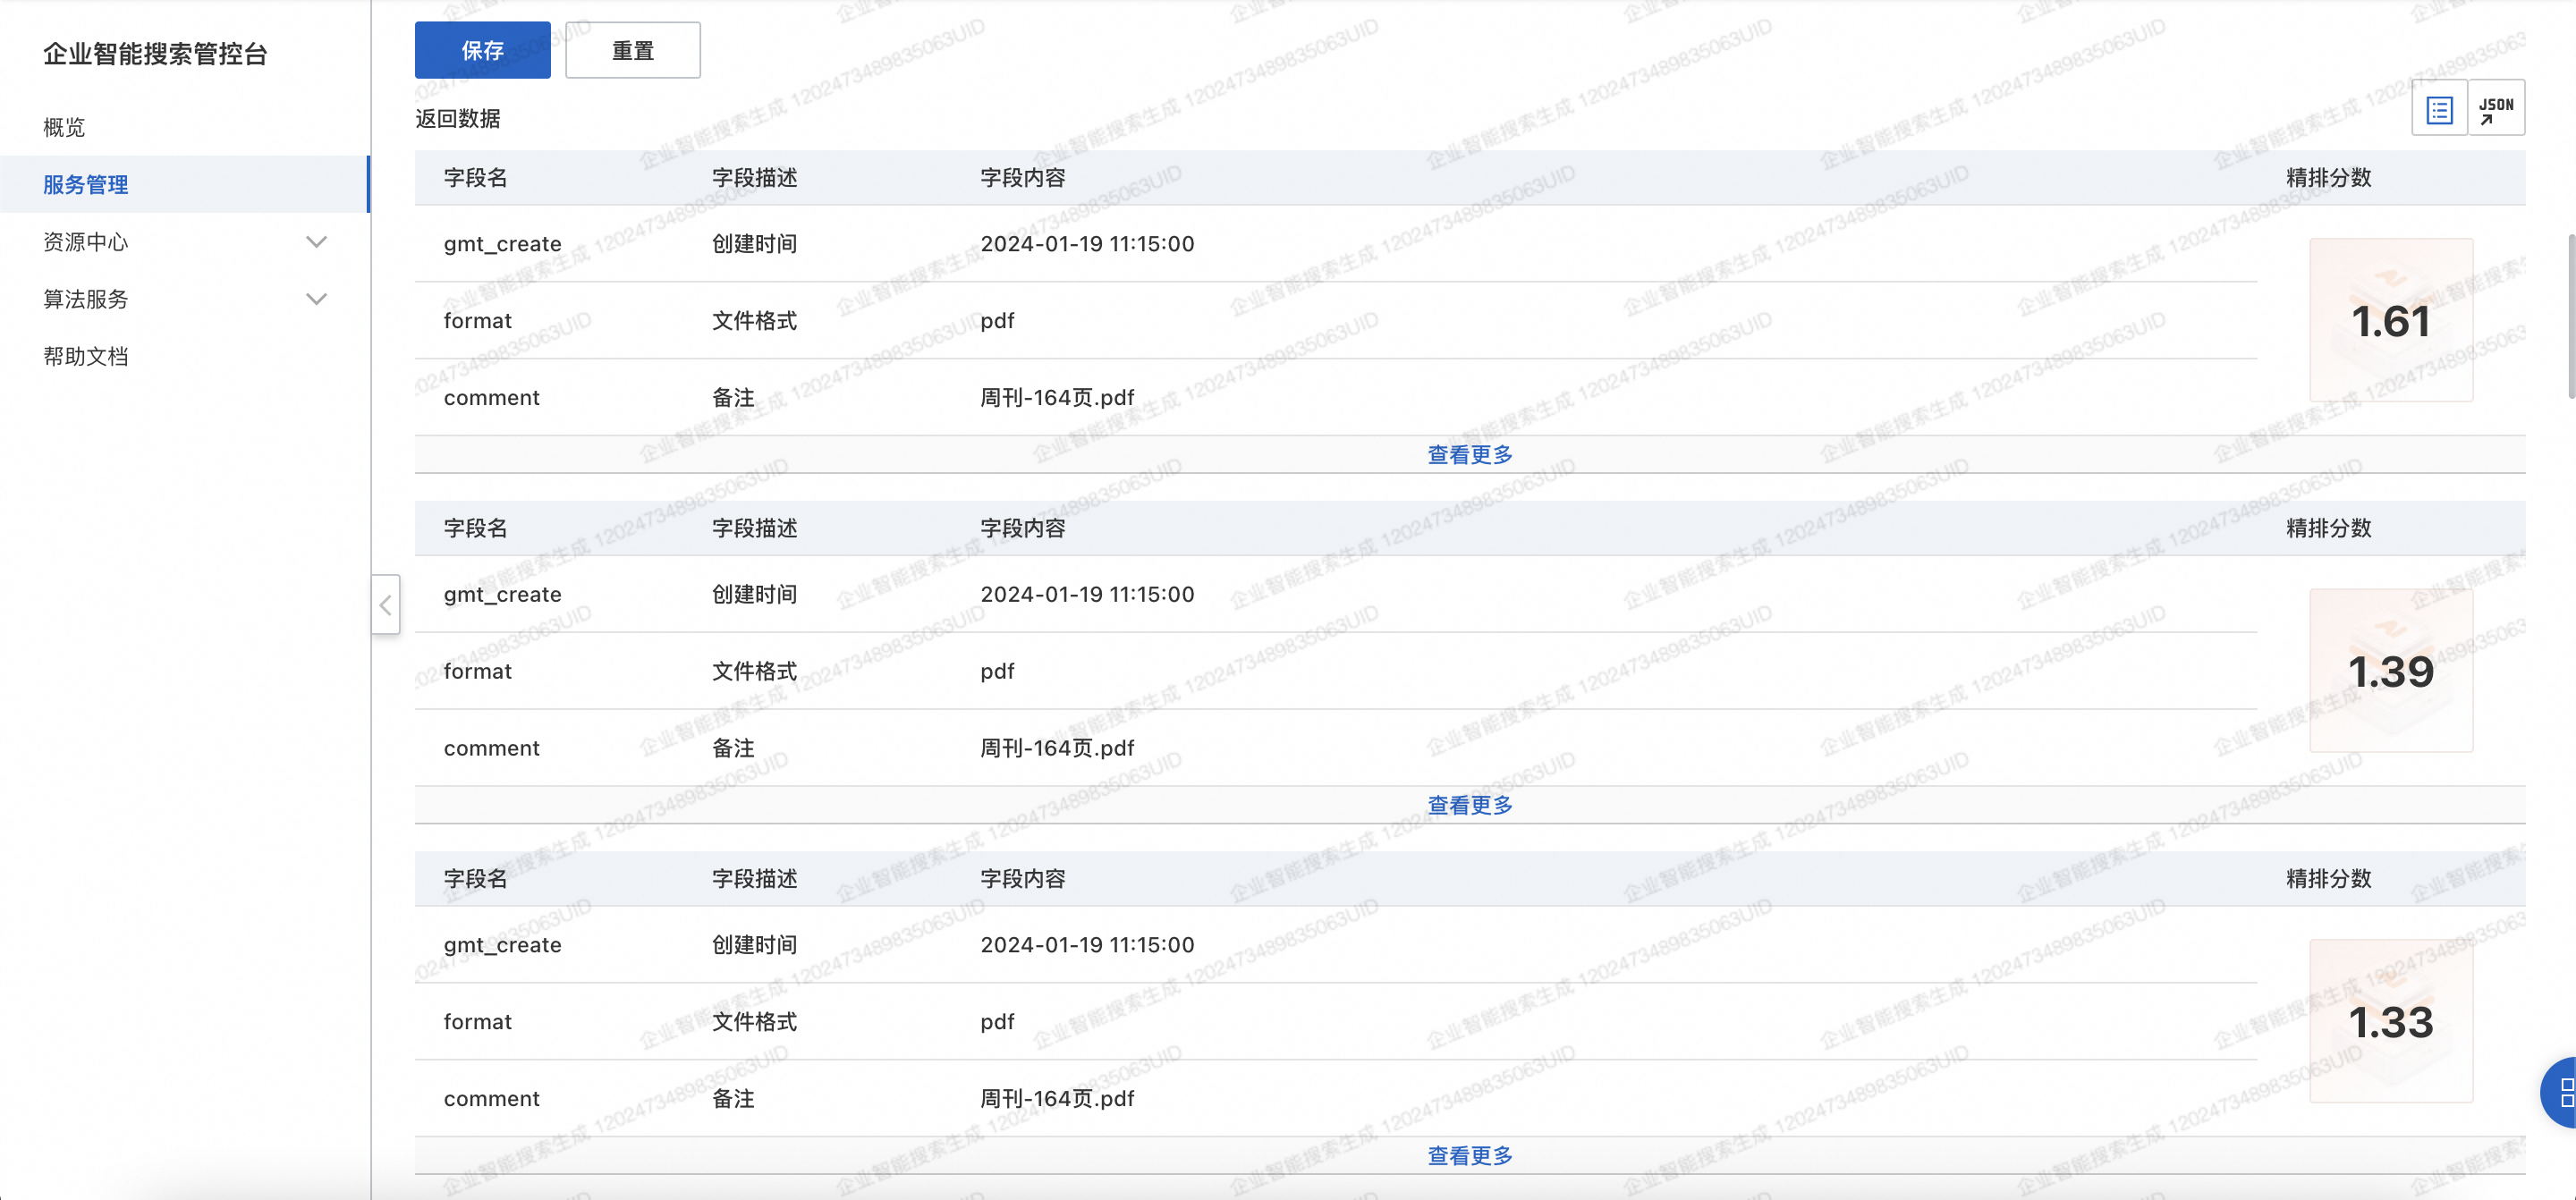
Search input
You can provide search input parameters for service testing in two ways:
JSON configuration: Enter search parameters in JSON format. For parameter details, see the Search Enhancement API.
Advanced parameter configuration: On the service testing page, expand the advanced parameter configuration section, click "Add configuration parameter", select and configure the desired parameters, and then click "Save".
Request parameters
Parameter | Type | Description | Default |
serviceId | long | The service ID. | 101 |
uq | string | The user's search query. | |
type | string | The retrieval type (full-text or chunked). | Dynamically adapted |
queries | List<map<string, object>> | The search conditions. | [] |
filters | List<map<string, object>> | The filters. | [] |
fields | array | The retrieved fields (stored fields). | [] |
sort | array | The sort fields. | [] |
page | int | The page number for pagination. | 1 |
rows | int | The number of rows per page for pagination. | 10 |
rankModelInfo | map<string, object> | The algorithm intervention configuration. For internal use only. | {} |
customConfigInfo | map<string, object> | The custom intervention configuration. | {} |
debug | boolean | If true, the response includes debugging information. | 0 |
minScore | float | The score threshold. | 0 |
Response parameters
Parameter | Type | Description | Default |
requestId | string | The request ID. | xxxx |
status | int | The status of the request. | 0 |
message | string | The response message. | |
data.total | int | The total number of hits. | 0 |
data.docs | array<object> | The search results. | [] |
debug | map<string, object> | The debugging information. |
The following example shows a common search request with parameter explanations.
{
    "uq": "search request", // The user's search query.
    "type": "title,content,vector", // The index fields used in the recall phase.
    "debug": false, // Specifies whether to enable debugging.
    "fields": [ // The retrieved fields.
        "title",
        "content"
    ],
    "page": 1, // The page number for pagination. The initial value is 1.
    "rows": 10, // The number of rows per page for pagination.
    "customConfigInfo": {
        "qpEmbedding": true, // Specifies whether to use vector search.
        "uqVectorRecallRatio": 0.5, // The ratio of vector recall in a multi-recall strategy.
        "rerankSize": 100  // The number of documents to re-rank.
    },
    "rankModelInfo": { // The ranking formula.
        "default": {
            "features": [
                {
                    "name": "vector_index", // The vector recall score.
                    "weights": 1.0, // The feature weight.
                    "threshold": 0.0,  // The feature threshold. Features with scores below this threshold will be scored as 0.
                    "norm_factor": 0.001,
                    "norm": true,
                    "score_type": "L2"
                },
                {
                    "name":"static_value", // _rc_t_score is the text recall score, obtained through the static_value feature.
                    "field":"_rc_t_score",
                    "weights":0.1,
                    "threshold":0,
                    "norm_factor": 80, // The normalization factor. For more information, see the ranking formula documentation.
                    "norm":true // Specifies whether to apply normalization.
                },
                {
                    "name": "query_match_ratio", // The coverage ratio of query terms in the corresponding field.
                    "field": "title", // The field name.
                    "weights": 0.5,
                    "threshold": 0.0,
                    "norm": false
                },
                {
                    "name": "cross_ranker", // The semantic matching feature.
                    "weights": 1.0,
                    "threshold": 0,
                    "fields": ["title", "desc"] // The fields to which the semantic matching feature is applied (list type).
                },
                {
                    "name": "doc_match_ratio", // The coverage ratio of the document's field terms that appear in the query.
                    "field": "title",
                    "weights": 0.5,
                    "threshold": 0.0,
                    "norm": false
                }
            ],
            "aggregate_algo": "weight_avg" // The method for calculating the final ranking score. Currently, only "weight_avg" is supported.
        }
    }
}
Multi-recall: vector recall ratio
Definition: Recall models primarily include text relevance recall and semantic vector recall. Text relevance recall retrieves documents based on term-level overlap after tokenization. Semantic vector recall converts text into semantic vectors and retrieves the documents that are closest in the vector space.
Recommended value: 50%. This means that text relevance recall and semantic vector recall each account for half of the total recalled documents.
Description: Controls the proportion of results returned by vector recall relative to the total number of documents recalled for a query.
Tip: To use only text relevance recall, set this parameter to 0%. The current version does not support vector-only recall, so setting this value to 100% is not recommended.
Rerank size
Definition: The maximum number of documents that enter the re-ranking stage.
Recommended value: 200–500.
Description: After a query retrieves all relevant documents, the system computes a baseline relevance score for them and sorts them. If the total number of recalled documents exceeds the configured rerank size (N), the system sends only the top N documents with the highest baseline scores for re-ranking.
Tip: A larger value improves the final result quality by re-ranking more documents, but it also increases processing time and resource consumption.
Minimum text similarity
Definition: The degree of similarity between the search query and the text content.
Recommended value: 80%. This value is a percentage ranging from 0 to 100.
Description: In non-exact match mode, this parameter controls the text similarity threshold. For example, a value of 0.8 means 80% of the text must match the search query. If the similarity is lower than this configured value, the text is not considered a valid match.
Score threshold
Definition: The minimum ranking score for a document to be returned.
Recommended value: 0
Description: Excludes documents from the final results if their score falls below this threshold.
Custom ranking formula
The service provides a rich set of ranking features, allowing you to implement custom ranking logic for your specific use case. The ranking formula is configured in JSON format within the rankModelInfo parameter. The built-in ranking model uses the specified formula to score the recalled results based on various ranking features, then computes the final ranking score and order. The model supports configuring an index field, weight, threshold, and normalization for each feature.
rankModelInfo
This field contains the custom ranking formula configurations for both the original query and any extra queries. Each ranking formula is a dictionary object, where the key is the name of the corresponding query field. The ranking formula for the default query (uq) is named default, while formulas for extra queries are named after their corresponding query names in the extras field.
Ranking formula
Each ranking formula consists of two parts: features and aggregate_algo. The features parameter is a list of ranking features and their configurations. The aggregate_algo parameter specifies the aggregation method. Currently, only weight_avg (weighted average) is supported, which calculates the weighted sum of all feature scores. This sum becomes the final re-ranking score.
Features
Each feature is a dictionary object containing the feature name and its parameters. The following parameters are common to all features:
Common parameters
name: The name of the feature.
field: The index field used to calculate the relevance feature.
weights: The feature weight, specified as a float.
threshold: The score threshold for the feature, specified as a float. Feature scores below this threshold are set to 0. Note: The threshold is applied to the score before normalization. Setting a threshold helps filter out the impact of low-scoring features and allows for effective feature selection.
norm: A boolean value that specifies whether to apply normalization to the feature score. Normalization transforms raw feature scores to a uniform scale (0 to 1), making scores from different features comparable by eliminating dimensional differences.
norm_factor: A float value that serves as the normalization factor, used to scale the raw score. We recommend setting this to the mean of the raw score distribution (must not be 0).
The following section provides a detailed description of each feature.
Features
Feature name | Description | Specific parameters |
vector_index | The vector match score. Requires semantic vector recall to be configured. |
|
text_index | The recall score from the search engine. Tip: This feature is supported only for text relevance recall. When using multi-recall (vector + search engine), use the | |
timeliness | A timeliness score, proportional to the millisecond difference between a given time field and a base time. The value ranges from 0 to 1. |
|
doc_match_ratio | The ratio of the number of matching words between the query and the field to the total number of words in the field. | |
query_match_ratio | The ratio of the number of matching words between the field and the query to the total number of words in the query. | |
doc_match_count | The number of matching words between the field and the query. | |
query_match_count | The number of matching words between the query and the field. | |
query_min_slide_window | Measures the proximity of matching words between the query and the field. It is the ratio of the number of matched query words to the minimum window size in the field that contains those words, regardless of order. | |
ordered_query_min_slide_window | Measures the proximity of matching words while respecting their order. It is the ratio of the number of matched token groups to the minimum window size in the field that contains those groups in the correct order. | |
doc_unique_ratio | The ratio of unique words to total words in the field. Used to filter documents with repetitive keywords. | |
overlap_coefficient | Measures text match level. It is the ratio of the number of matching words to the total number of words in both the query and the field. | |
char_overlap_coefficient | Measures character-level similarity. It is the ratio of matching characters to the total number of characters in both the query and the field. | |
lcs_match_ratio | The ratio of the length of the word-level longest common subsequence between the query and the field to the number of words in the query. | |
char_lcs_match_ratio | The ratio of the length of the character-level longest common subsequence between the query and the field to the number of characters in the query. Suitable for string matching scenarios such as emails or mobile numbers. | |
edit_similarity | A text similarity score (0–1) calculated based on the edit distance between the field and the query. A higher score indicates greater similarity. Useful for measuring the degree of an exact match, such as in question-to-question matching scenarios. A high threshold is recommended. | |
char_edit_similarity | Character-level edit similarity. | |
char_sequential_match_priority | A feature designed for matching names that considers the order of characters. It calculates a character-level sequential match score. The similarity for the i-th character is 1/|i-j|, where j is the position of the nearest identical character in the field. The weight for the i-th character is 1.0/i. The final score is the weighted average of all character similarities. | |
pinyin_lc_substr | The ratio of the length of the Pinyin longest common substring between the query and the field to the Pinyin length of the field. Measures Pinyin similarity. | |
doc_pinyin_lc_substr | The ratio of the length of the Pinyin longest common substring between the query and the field to the Pinyin length of the query. Measures Pinyin similarity. | |
static_value | Uses the value of a numeric field directly as the feature score. | |
name_pinyin_match | A feature designed for matching names using Pinyin. It checks if the query matches the field's full Pinyin, Pinyin initialism, or a mix of initials and full Pinyin. For example, if a name field has the value "Zhang San", this feature checks if the query's Pinyin is any of ["zhangsan", "zs", "zhangs", "zsan"]. If a match is found, it returns a score of 1; otherwise, it returns 0. | |
prefix_match_ratio | A word-level prefix match feature. The score is the length of the longest common prefix between the query and the field, divided by the query length. A prefix match means the words in the query and document match sequentially from the beginning. This is useful for scenarios where match position is important (e.g., email matching). It is recommended to use this with other features, such as | |
char_prefix_match_ratio | A character-level prefix match feature. The score is the length of the longest common prefix between the query and the field, divided by the query length. This is useful for scenarios where match position is important (e.g., email matching). It is recommended to use this with other features, such as | |
pinyin_prefix_match_ratio | A Pinyin prefix match feature. The score is the length of the longest common Pinyin prefix between the query and the field, divided by the query length. This is useful for scenarios where match position is important (e.g., email matching). It is recommended to use this with other features, such as | |
is_contained | Checks if the query exactly matches any item in a given list-type field. Used for matching tags. The corresponding index field must be of type | |
contained_boost | The number of times the complete query appears in a given field. Used to boost the score of exact matches. | |
part_of_doc | Checks if the complete query appears in a given field (returns 1 if it appears, 0 if not). Used to boost the score of exact matches. |
Custom ranking best practices
Tip: The following examples assume that an index field named "content" exists.
{
    "rankModelInfo": {
        "default": {
            "features": [
                {
                    "name": "text_index",
                    "weights": 1.0,
                    "threshold": 10,
                    "norm": true
                },
                {
                    "name": "query_match_ratio",
                    "weights": 1.0,
                    "threshold": 0.0,
                    "field":"content"
                }
            ],
            "aggregate_algo": "weight_avg"
        },
    }
}
{
"rankModelInfo":{
"default":{
"features":[
{
"name":"static_value",
"field":"_rc_t_score",
"weights":1,
"threshold":10,
"norm":true
},
{
"name":"vector_index",
"weights":1,
"threshold":0,
"norm":true,
"norm_factor":0.001,
"score_type": "L2"
},
{
"name":"query_match_ratio",
"weights":1,
"threshold":0,
"field":"content"
}
],
"aggregate_algo":"weight_avg"
}
}
}{
"rankModelInfo": {
"default": {
"features": [
{
"name": "static_value",
"field": "_rc_t_score",
"weights": 1,
"threshold": 10,
"norm": true
},
{
"name": "vector_index",
"weights": 1,
"threshold": 0,
"norm": true,
"norm_factor": 0.001,
"score_type": "L2"
},
{
"name": "query_match_ratio",
"weights": 1,
"threshold": 0,
"field": "title"
}
],
"aggregate_algo": "weight_avg"
}
},
"keyword": {
"features": [
{
"name": "query_match_ratio",
"weights": 1,
"threshold": 0,
"field": "content"
}
],
"aggregate_algo": "weight_avg"
}
}This example shows a ranking formula with an additional query named keyword. To use this, you must also define a keyword query in the extras request parameter, as shown below.