training-xpu-pytorch 25.07, training-xpu-pytorch 25.07
These are the release notes for training-xpu-pytorch 25.07.
Main features and bug fixes
Main features
Upgraded PPU SDK to 1.5.3.
Upgraded vllm to v0.9.1 and optimized sailSHMEM performance.
Bug fixes
SDK 1.5.3 includes the following fixes:
torch profiler: Fixed incorrect performance data reporting in PyTorch 2.6.
acext: Fixed a precision issue caused by passing a bias to the w8a8-int8 gemm interface.
acext: Fixed a crash in the int8_gemm Python API during CUDA Graph Capture.
Contents
Use cases | Training/inference |
Framework | PyTorch |
Requirements | PPU SDK 1.5.3 |
Core components |
|
Assets
We recommend using a VPC to accelerate image pulls and reduce pull times.
25.07
Public image
egslingjun-registry.cn-wulanchabu.cr.aliyuncs.com/egslingjun/training-xpu-pytorch:25.07
VPC images
acs-registry-vpc.{region-id}.cr.aliyuncs.com/egslingjun/{image:tag}
{region-id}is the ID of the region where your Container Service for Kubernetes (ACK) cluster is located, such ascn-beijingorcn-wulanchabu.{image:tag}is the actual image name and tag.
Driver requirements
Driver version >= 1.1.0.
Key features and enhancements
PyTorch compilation optimizations
The compilation optimization feature introduced in PyTorch 2.0 usually provides significant benefits in small-scale, single-GPU scenarios, but in LLM training, the need to incorporate memory optimization and distributed frameworks such as FSDP and Deepspeed makes it difficult for torch.compile() to provide benefits and can even cause performance degradation:
This optimization controls communication granularity within the DeepSpeed framework, allowing the compiler to capture a more complete computation graph and apply broader optimizations.
This release includes an optimized version of PyTorch with the following enhancements:
An optimized PyTorch compiler frontend that ensures successful compilation even when arbitrary graph breaks occur.
Enhanced pattern matching and dynamic shape capabilities to improve the performance of compiled code.
With these optimizations, you can typically achieve an end-to-end (E2E) throughput gain of around 20% when training an 8B LLM.
Memory optimization through recomputation
A model to predict memory overhead was built using extensive benchmark data from various models, clusters, and training configurations—along with system metrics like memory utilization. This allows the system to recommend the optimal number of activation checkpointing layers. Integrated into PyTorch and compatible with the DeepSpeed framework, this feature helps users optimize memory usage.
ACCL communication library
ACCL is a high-performance network communication library developed by Alibaba for Lingjun products. It is available in three versions: ACCL-N for NVIDIA GPUs, ACCL-P for PPUs, and ACCL-R for AMD accelerators. ACCL-N is based on NVIDIA NCCL, offering full compatibility and including bug fixes and optimizations for performance and stability. ACCL-P is a collective communication library built upon T-Head's open-source pccl. ACCL-R is built upon AMD's open-source ROCm rccl. This release ports key features from ACCL and ACCL-N to pccl, resolves known issues, and is deeply customized for integration with Alibaba Cloud's proprietary networking components.
E2E performance gain assessment
Using CNP, a cloud-native AI performance evaluation and analysis tool, we conducted a comprehensive end-to-end performance comparison between our image and a standard base image using mainstream open-source models and framework configurations. We also performed an ablation study to assess the contribution of each optimized component to the overall model training performance.
Image comparison: Base image vs. iterative evaluation.

E2E performance contribution of PPU core components.
We conducted the following tests on a multi-node PPU cluster using release 25.07 to evaluate and compare end-to-end (E2E) training performance. The comparison items include:
Base: The PPU PyTorch image.
ACS AI Image (Base + ACCL): The image using the ACCL communication library.
ACS AI Image (AC2 + ACCL): The golden image on AC2 BaseOS with optimizations disabled.
ACS AI Image (AC2 + ACCL + CompilerOpt): The golden image using AC2 BaseOS with only the
torch.compileoptimization enabled.ACS AI Image (AC2 + ACCL + CompilerOpt + CkptOpt): The golden image using AC2 BaseOS with both
torch.compileand selective gradient checkpoint optimizations enabled.
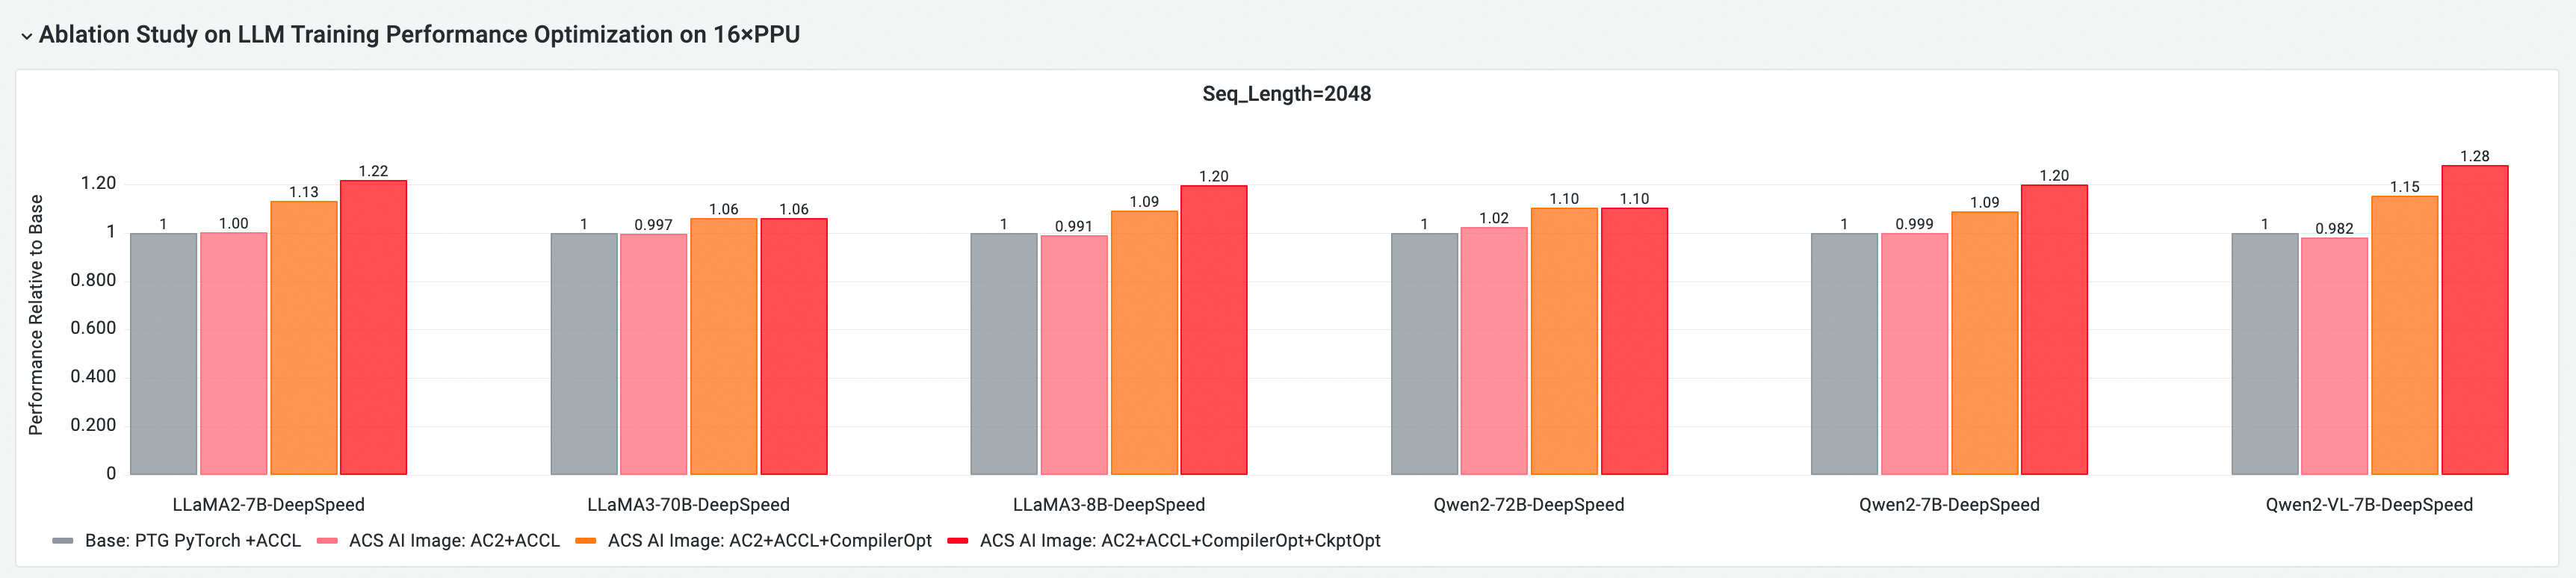
Quick start
This example shows how to pull the image using Docker.
To use the training-xpu-pytorch image in Alibaba Cloud Service (ACS), select it from the Artifacts page when you create a workload in the Console, or specify the image reference in a YAML file.
1. Select the image
docker login egslingjun-registry.cn-wulanchabu.cr.aliyuncs.com2. Enable compiler and memory optimization
Enable compilation optimization
Using the transformers Trainer API:

Enable memory optimization with recomputation
export CHECKPOINT_OPTIMIZATION=true
3. Start a container
The following steps show how to start a container and run a training task with the built-in ljperf tool.
For ACS-based products, use the image by specifying it in a YAML file.
For LLMs
# Start and enter the container
docker run --rm -it --ipc=host --net=host  --privileged egslingjun-registry.cn-wulanchabu.cr.aliyuncs.com/egslingjun/training-xpu-pytorch:25.07

# Run the training demo
ljperf --action train --model_name deepspeed/llama3-8b
Usage notes
This image contains modified libraries, including PyTorch and DeepSpeed. Do not reinstall them.
Leave the
zero_optimization.stage3_prefetch_bucket_sizesetting in your DeepSpeed configuration empty or set it toauto.SDK 1.5.3 supports new quantization capabilities.
vLLM 0.9.1, released in SDK 1.5.3, is not yet adapted for AWQ/GPTQ and has performance issues. We recommend using vLLM 0.8.5 or waiting for the SDK 1.6 image release. vLLM 0.9.1 in SDK 1.5.3 supports a8w8_int8 quantization.
DeepSeek R1 (671B):
vLLM 0.9.1 (SDK 1.5.3): Supports per-token/per-channel a8w8 (int8) quantization schemes but does not support AWQ (w4a16) or GPTQ (w4a16, w8a16). It is not adapted for AWQ and GPTQ, leading to significant performance issues.
To use AWQ (w4a16) or GPTQ (w4a16, w8a16) quantization schemes with vLLM, you must use the SDK 1.5.2 image (image path: egslingjun-registry.cn-wulanchabu.cr.aliyuncs.com/egslingjun/training-xpu-pytorch:25.06.post1).
Qwen3:
vLLM 0.9.1 (SDK 1.5.3): Supports per-token/per-channel a8w8 (int8) quantization schemes but does not support AWQ (w4a16) or GPTQ (w4a16, w8a16). It is not adapted for AWQ and GPTQ, leading to significant performance issues.
To use AWQ (w4a16) or GPTQ (w4a16, w8a16) quantization schemes, you must use the SDK 1.5.2 image (image path: egslingjun-registry.cn-wulanchabu.cr.aliyuncs.com/egslingjun/training-xpu-pytorch:25.06.post1).
Adjust the built-in
NCCL_SOCKET_IFNAMEenvironment variable based on your use case:When a single pod requests 1, 2, 4, or 8 cards for an inference task: Set
NCCL_SOCKET_IFNAME=eth0. This is the default configuration in this inference image.When a single pod requests all 16 cards of a full node for an inference task (which allows you to use the HPN): Set
NCCL_SOCKET_IFNAME=hpn0.
Known issues
Enabling
torch.compilefor LLaMA3.2-11b-vision in this release causes an error. A fix is planned for the next version.vLLM v0.9.1 estimates less available KV Cache space compared to v0.8.5. This can reduce concurrency in KV Cache-bound scenarios, affecting performance (for example, running DeepSeek-R1-bf16 on a single 810e machine).
ImportantWe recommend running A8W8 quantized models on the Zhenwu 810E to avoid performance degradation.