API deployment guide
This document uses Qwen model deployment as an example to demonstrate the full workflow of deploying models in Alibaba Cloud Model Studio via API (HTTP), including deployment, status query, inference, deletion, and permission troubleshooting.
ImportantThis topic is applicable only to the China (Beijing) region.
Prerequisites
- Read Model deployment to understand the supported models and basic steps for model deployment in Alibaba Cloud Model Studio.
- Obtain an API key and export the API key as an environment variable. Replace
DASHSCOPE_API_KEYin the sample code with your own Bailian API key; if you use the dashscope CLI, also setDASHSCOPE_HTTP_BASE_URLto your obtained API Host.
1. Deploy a model
The following command deploys a fine-tuned custom model qwen3-8b-ft-202511132025-0260 as a dedicated service named qwen3-8b-ft-202511132025-0260.
To obtain a custom model ID, go to the Model Studio console – Model fine-tuning, click the Task Name you want to deploy → Outputs → click the blue model name to open the My Models page. The model ID appears in the basic model information section.
Use the model ID as the value for the model_name parameter to deploy the model via API.
Billing by provisioned throughput units (PTU)
NoteAfter running the deployment command below, billing starts immediately upon successful deployment—even if you have not yet called the model. Confirm the billing rules before deploying.
The PTU billing mode charges based on the duration of provisioned throughput usage. It suits scenarios requiring stable throughput guarantees, high concurrency, low latency, and predictable traffic. In this mode, throughput/concurrency and generation speed are preset by the platform and cannot be adjusted.
curl "https://dashscope.aliyuncs.com/api/v1/deployments" \
--header "Authorization: Bearer $DASHSCOPE_API_KEY" \
--header 'Content-Type: application/json' \
--data '{
    "name": "my_qwen_flash",
    "model_name": "qwen-flash-2025-07-28",
    "plan": "ptu",
    "ptu_capacity": {
        "input_tpm": 10000,
	"output_tpm": 1000
    }
}'
Billing by model unit usage duration
Note
- After running the deployment command below, billing starts immediately upon successful deployment—even if you have not yet called the model. Confirm the billing rules before deploying.
- Model unit pay-as-you-go computing resources are allocated on a first-come, first-served basis. If purchase fails, you receive a full refund.
Select the model unit billing method. This mode charges based on model unit usage duration and suits large-scale inference workloads after model fine-tuning. Resources are dedicated, and performance and cost are flexible. Throughput/concurrency and generation speed are customizable.
curl "https://dashscope.aliyuncs.com/api/v1/deployments" \
--header "Authorization: Bearer $DASHSCOPE_API_KEY" \
--header 'Content-Type: application/json' \
--data '{
    "name": "my_qwen_plus",
    "model_name": "qwen-plus-2025-12-01",
    "plan": "mu",
    "deploy_spec": "MU1",
    "enable_thinking": true,
    "capacity": 4,
    "max_context_length": 10000,
    "rpm_limit": 500,
    "tpm_limit": 1000
}'
The model unit deployment mode supports additional settings:
Configuration item | Configuration details |
|---|---|
Service name | A custom name for the deployment service. |
Model | Select the model to deploy, including platform preset models and fine-tuned models. |
Model unit type | Select the deployment specification. Different specifications correspond to different computing power and performance. |
Replica count | Set the initial number of deployment replicas, which affects the concurrent processing capability of the service. |
Deployment template | Select a deployment template (for example, "single-node deployment"). Different templates correspond to different resource configuration schemes. Available only in the model unit billing mode. |
Model inference mode | For some models, when deployed inModel Unit mode, you can configure the inference mode, maximum context, and more.
|
Maximum context | TheModel Unit deployment mode of some models supports this setting. The maximum context length depends on the model type. |
Service throttling | TheModel Unit deployment mode of some models supports this setting, which can limit the RPM and TPM of model calls. |
For details on setting these options via API, see Create a model deployment task using the API.
Billing by token usage
Select the token-based billing method. This mode charges based on token usage and suits cost-sensitive scenarios with low requirements for concurrency and latency. It offers the highest price advantage. Throughput/concurrency and generation speed are preset by the platform and cannot be adjusted.
curl "https://dashscope.aliyuncs.com/api/v1/deployments" \
--header "Authorization: Bearer $DASHSCOPE_API_KEY" \
--header 'Content-Type: application/json' \
--data '{
    "model_name": "qwen3-8b-ft-202511132025-0260",
    "plan": "lora",
    "capacity": 1,
    "name": "qwen3-8b-ft"
}'
The capacity parameter has no effect but must be included. To scale up or down, go to the dedicated deployment console and submit a form request.
dashscope CLI
export DASHSCOPE_API_KEY="your-api-key"
# Replace {WorkspaceId} with your Workspace ID, and cn-beijing with the corresponding region (Singapore: ap-southeast-1, US East: us-east-1)
export DASHSCOPE_HTTP_BASE_URL="https://{WorkspaceId}.cn-beijing.maas.aliyuncs.com/api/v1"
# List deployed dedicated services
dashscope deployments list

# Create a dedicated service (--plan required)
# plan options: ptu (PTU reserved resources) / mu (model unit) / lora (LoRA deployment)
dashscope deployments create -m qwen2.5-7b-instruct -s tst -c 1 --plan ptu
-mspecifies the model name,-sspecifies the service suffix,-cspecifies the deployment capacity.
ImportantThe SDK Expert interactive assistant can accomplish the same development and troubleshooting in natural language. See
DashScope SDK Expert.For the complete region table, see Base URL overview.
After successful execution, the command returns the following result (using model unit deployment as an example):
{
    "request_id": "83b173ab-2b2f-41aa-8c57-b173e8be934e",
    "output":
    {
        "deployed_model": "qwen3-8b-ft-202511132025-0260",
        "gmt_create": "2025-11-20T20:06:46.405",
        "gmt_modified": "2025-11-20T20:06:46.405",
        "status": "PENDING",
        "model_name": "qwen3-8b-ft-202511132025-0260",
        "base_model": "qwen3-8b",
        "workspace_id": "llm-8v*****",
        "charge_type": "post_paid",
        "creator": "16542*****",
        "modifier": "16542*****",
        "plan": "mu",
        "model_unit_spec": "MU1"
    }
}
The deployed_model field is the unique ID of the dedicated service. In subsequent query and delete API paths, use this deployed_model value (not the name request parameter).
2. Check service status
Use the following command to query details for a specific dedicated service:
curl "https://dashscope.aliyuncs.com/api/v1/deployments/qwen3-8b-ft-202511132025-0260" \
    --header "Authorization: Bearer $DASHSCOPE_API_KEY" \
    --header 'Content-Type: application/json'
After successful execution, the command returns the following result:
{
    "request_id": "ca36952d-9136-426e-ab08-68a97ad72719",
    "output":
    {
        "deployed_model": "qwen3-8b-ft-202511132025-0260",
        "gmt_create": "2025-11-20T20:32:08",
        "gmt_modified": "2025-11-20T20:42:25",
        "status": "RUNNING",
        "model_name": "qwen3-8b-ft-202511132025-0260",
        "base_model": "qwen3-8b",
        "base_capacity": 2,
        "capacity": 2,
        "ready_capacity": 2,
        "workspace_id": "llm-8v53etv3hwb8orx1",
        "charge_type": "post_paid",
        "creator": "1654290265984853",
        "modifier": "1654290265984853",
        "plan": "mu",
        "model_unit_spec": "MU1"
    }
}
When the service status is RUNNING, deployment is complete.
3. Make an inference request
NoteIf you are using the DashScope SDK for the first time, see Install the SDK.
Ensure the workspace of your API key matches the workspace where the model is deployed.
When calling a successfully deployed model, the value of model should be the model code generated after successful deployment. Go to the Dedicated Deployment console (Beijing) to obtain it.
import os
import dashscope

messages = [
    {"role": "system", "content": "You are a helpful assistant."},
    {"role": "user", "content": "Who are you?"},
]
response = dashscope.Generation.call(
    # If you have not configured environment variables, replace the next line with your Bailian API Key: api_key="sk-xxx",
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    model="qwen3-14b-xxx-xxx",  # Please replace with the code returned after the model is successfully deployed
    messages=messages,
    result_format="message",
    enable_thinking=False,
)
print(response)
import os
from openai import OpenAI

client = OpenAI(
    # If you have not configured environment variables, replace the next line with your Bailian API Key: api_key="sk-xxx",
    api_key=os.getenv('DASHSCOPE_API_KEY'),
    base_url="https://dashscope.aliyuncs.com/compatible-mode/v1",
)

completion = client.chat.completions.create(
    model="qwen3-14b-xxx-xxx",  # Please replace with the code returned after the model is successfully deployed
    messages=[
        {"role": "system", "content": "You are a helpful assistant."},
        {"role": "user", "content": "Who are you?"},
    ],
    extra_body={"enable_thinking": False},
)
print(completion)
Inference parameter alignment
Model Studio's inference engine may use different default parameter values than your local framework. To ensure consistent results, adjust the following parameters when calling the API:
Parameter name | Recommended value (matches vLLM defaults) |
|---|---|
temperature | Range: [0, 2). Set to 1.0 to match vLLM's default. |
top_p | Range: (0, 1.0]. Set to 1.0 to match vLLM's default. |
top_k | Set to None or a value greater than 100 to disable top_k sampling (only top_p applies). Setting to 99 approximates vLLM's default value of 0 (full sampling). |
presence_penalty | Range: [-2.0, 2.0]. Set to 0 to match vLLM's default. |
repetition_penalty (DashScope protocol) | Increasing repetition_penalty reduces repetition in generated text. A value of 1.0 means no penalty. Range: greater than 0. Set to 1.0 to match vLLM's default. |
4. Delete a dedicated service
WarningAfter running the delete command below, the model deployment service begins immediate offline removal and cannot be recovered. You will:
- No longer be able to call the model.
- Stop incurring deployment charges.
Delete unused dedicated services using the following command:
curl --request DELETE 'https://dashscope.aliyuncs.com/api/v1/deployments/qwen3-8b-ft-202511132025-0260' \
    --header "Authorization: Bearer $DASHSCOPE_API_KEY" \
    --header 'Content-Type: application/json'
After successful execution, the command returns the following result:
{
    "request_id": "8f726017-6042-420e-a465-0d366a3aba59",
    "output":
    {
        "deployed_model": "qwen3-8b-ft-202511132025-0260",
        "gmt_create": "2025-11-20T20:32:08",
        "gmt_modified": "2025-11-27T16:35:31.591",
        "status": "DELETING",
        "model_name": "qwen3-8b-ft-202511132025-0260",
        "base_model": "qwen3-8b",
        "base_capacity": 2,
        "capacity": 2,
        "ready_capacity": 2,
        "workspace_id": "llm-8v53etv3hwb8orx1",
        "charge_type": "post_paid",
        "creator": "1654290265984853",
        "modifier": "1654290265984853",
        "plan": "mu",
        "model_unit_spec": "MU1"
    }
}
After successful deletion, the 2. Check service status API no longer returns the deployment status.
Permission troubleshooting
If you encounter a permission error during model deployment, follow the troubleshooting path that matches your deployment method:
Console deployment
-
If "Missing permission for this module" is displayed, please ensure that your account has the Model Deployment - Operation permission on the permission management page of the business space.
If you cannot operate normally, please contact your organization or IT administrator to add the relevant permissions or check the permission issues on your behalf.
-
If the error "xx business space does not have permission to deploy the xx model" is reported during deployment, please go to the Business Space Management page of Model Studio to add the deployment permission of the corresponding model for the corresponding business space.
API call error:
Workspace xxx does not have deployment privilege for model xxxx.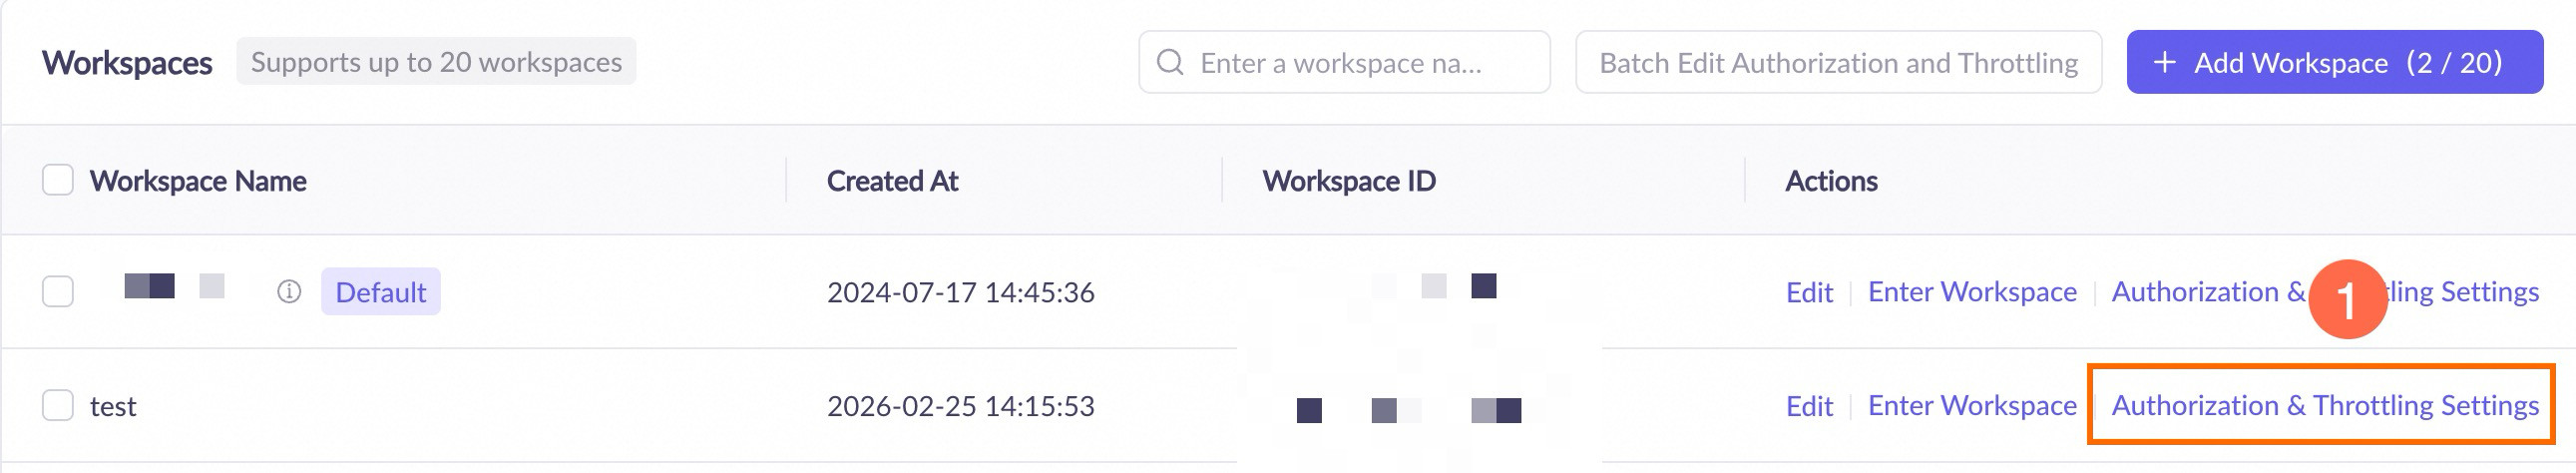
If insufficient permissions are prompted, please contact your organization or IT administrator to add the relevant permissions or operate on your behalf.
API deployment
When deploying a model using the API, ensure the following:
-
The Workspace associated with your API key has permission to manage the model. Go to the Model Studio Workspace management page and check the model deployment permissions for the relevant workspace.
API call error:
Workspace xxx does not have deployment privilege for model xxxx.In the Actions column, click Model permission and throttling settings.
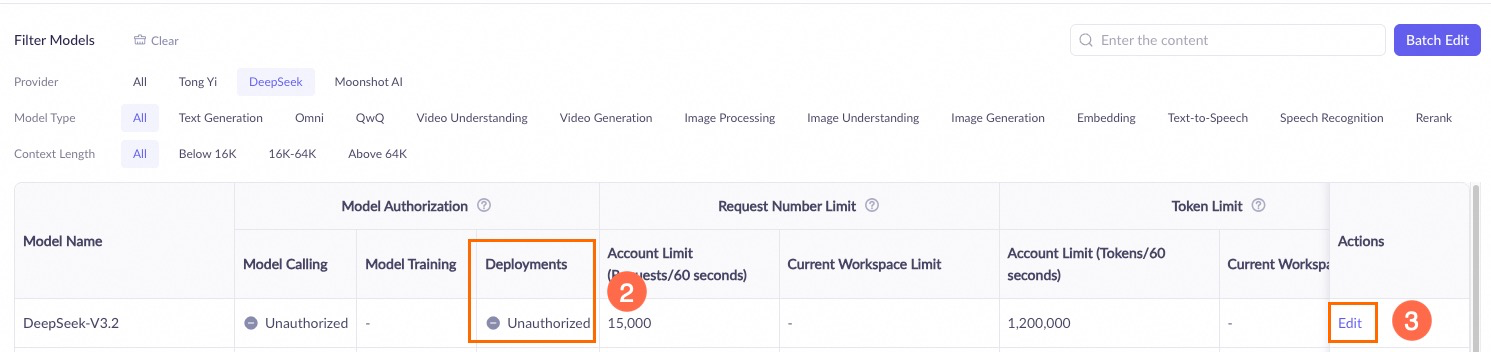
In the Model List, find your target model and check the authorization status in the Model deployment column. If it shows Unauthorized, click Edit in the Actions column to grant permission.
-
The Owner Account associated with your API key has operation permissions in its Workspace. Go to the Model Studio console, click the workspace in the bottom-left corner to switch to the correct workspace, then click
 to check model deployment permissions.
API error:
Workspace access denied.In the navigation pane on the left, click Permission Management and confirm that the user list includes the API key’s associated account (type: Alibaba Cloud account).
API reference
For detailed API usage, see API details and the complete deployment API reference.