Reinforcement learning training
- Reinforcement Learning Development Guide
- Reinforcement Learning Training Configuration
- Observability Configuration for Reinforcement Learning
This guide walks you through submitting and monitoring your first reinforcement learning (RL) training job using an end-to-end example.
Learn about the basic concepts and use cases of RL training.
Model Studio offers several model fine-tuning methods that are not mutually exclusive. Instead, they form a progressive and complementary workflow.
continued pre-training (CPT) (optional) → supervised fine-tuning (SFT) → direct preference optimization (DPO) (optional) → RL (optional)
-
Continued pre-training (CPT) - Fills knowledge gaps. General models have broad but shallow knowledge and often cannot meet the depth and accuracy requirements of specialized domains.
- Financial model:
Learns financial terminology - Medical model:
Memorizes drugs and pathologies - Legal model:
Understands legal articles and case law
- Financial model:
-
Supervised fine-tuning (SFT) - Learns to perform tasks
- Customer service bot:
Learns customer service procedures - Code assistant:
Learns programming paradigms - tool calling (agent):
Learns to use Model Context Protocol (MCP)
- Customer service bot:
-
Direct preference optimization (DPO) - Improves performance
- Safety and responsibility:
Rejects harmful suggestions - Conciseness and effectiveness:
Provides crisp and clear answers - Objectivity and neutrality:
Gives fair and unbiased evaluations
- Safety and responsibility:
-
Reinforcement learning (RL) - Learns to reason. The model autonomously explores optimal strategies guided by a reward signal, without needing a standard answer.
- Mathematical reasoning:
Solves problems more accurately - tool calling (agent):
Makes more reliable calls - Code generation:
Writes executable code
- Mathematical reasoning:
RL training workflow
The RL training process consists of five steps, from environment setup to model deployment:
- Set up the environment — Install the offline SDK, get an API key, and complete RL service authorization.
- Prepare data and code — Download the demo package to understand the data format and project structure.
- Submit the training job — Run the demo to deploy functions, upload data, and submit the job in one step.
- Monitor training status — View the training status, logs, and reward trends.
- Publish and deploy the model — Publish a checkpoint to "My Models" and deploy it for API access.
How RL training works
RL training continuously improves the model's capabilities through a "generate-score-optimize" loop. The data flow for each training round is as follows:
训练数据(用户问题 + 参考答案)
            │
            ▼
策略采样(Rollout):模型按当前策略生成候选结果
            │
            ▼
奖励评分(Reward):对比参考答案,给出 0~1 分(可以合并到 Rollout)
            │
            ▼
策略更新:根据奖励信号,强化高分策略、抑制低分策略
            │
            ▼
循环迭代:用更新后的模型重新采样,逐轮提升质量
Supported models
NotePlease contact your account manager to enable the reinforcement learning training feature.
Model name | Model code | MoE | Recommended MTUs |
|---|---|---|---|
Qwen3.5-9B | qwen3.5-9b | No | Type IV training unit * 24 |
Qwen3.6-flash-2026-04-16 | qwen3.6-flash-2026-04-16 | Yes | Type IV training unit * 40 |
Qwen3.5-flash-2026-02-23 | qwen3.5-flash-2026-02-23 | Yes | Type IV training unit * 40 |
Qwen3.6-35B-A3B | qwen3.6-35b-a3b | Yes | Type IV training unit * 40 |
WarningThe number of model training units requested (mtu_capacity) must strictly equal nnodes_rollout × n_gpus_rollout + nnodes_training × n_gpus_training. These four parameters are configured in hyper_parameters (default values vary by model). The table above lists the recommended numbers for each model. When changing any of these parameters, update the number accordingly based on the formula. For details, see Optional parameters (advanced configuration).
Training unit pricing
For the training unit purchase process, the submission configuration of subscription jobs (how to obtain the instance_id), and the complete usage instructions, see Model training units (invitation-only).
Billing method | Description | Billing formula |
|---|---|---|
Model training unit · subscription | Purchase exclusive model training units on a monthly subscription for faster, queue-free training. The minimum billing unit is one hour. If you cancel your subscription early, you are charged at 1.2 times the hourly rate. To purchase or manage subscription training units, go to the Model Fine-tuning console and click Resource pool management (subscription). |
|
Model training unit · pay-as-you-go | Use exclusive training resources for faster, queue-free training. You are billed for the actual duration of use. This option is enabled automatically when you create a job and does not require a pre-purchase. |
|
Training unit type | Billing method | Unit price | Minimum billing unit |
|---|---|---|---|
Type IV (MTU4) | subscription (monthly) | CNY 19,914.00/month/instance | 1 hour |
pay-as-you-go (per minute) | CNY 41.00/hour/instance | 1 minute |
NoteContact your account manager for rules on subscription scaling, renewal, and cancellation, or for specific model training unit (MTU) capacity calculations. For the full training unit specifications and billing details, see Model training unit billing.
Environment preparation
WarningRL training only supports billing through model training units (MTU), and does not support token-based billing.
Complete the environment configuration by following these steps:
-
Obtain an API Key: Obtain a DashScope API Key in the Bailian console.
-
Complete RL service authorization: Complete the one-click authorization on the model fine-tuning page of the Bailian console. When you use RL training for the first time, the console will prompt you to authorize three Alibaba Cloud services: Alibaba Cloud OpenTelemetry, Function Compute (FC), and Log Service (SLS).
-
Set environment variables: The following variables are read by the local SDK and control packaging, upload, and deployment behavior:
- DASHSCOPE_API_KEY (required): The API key.
- LOG_LEVEL (optional, default
info): Set todebugto output complete request/response information, which helps troubleshoot issues such as submission failures. - FC_ZIP_EXCLUDE_PATTERNS (optional): Directories or files excluded during upload (comma-separated), used to reduce the upload package size. By default,
.git,data,__pycache__, etc. are excluded. The maximum upload package size is 200 MB.
export DASHSCOPE_API_KEY="sk-your-api-key"
export LOG_LEVEL="info"
Prepare data and code
- Download the demo package agentic-rl-example.zip. (This demo requires a minimum of 24 Type IV model training units to run)
- After the download is complete, install the DashScope SDK (Python >= 3.10 required): Follow the instructions included in the demo package to install the required dependencies:
# 本地环境与 FC 容器侧均直接从 PyPI 安装(Demo 依赖 dashscope 2.0.3):
pip install dashscope==2.0.3
You will get the following project structure:
agentic-rl-example/
├── submit_job.py                         ← 主入口,提交训练任务
├── test_functions.py                     ← 函数注册与远程测试
├── config.yaml                           ← 可选的 YAML 配置文件
├── job.yaml                              ← YAML 提交配置(CLI run / SDK init)
├── cli.sh                                ← 本地测试与查询脚本集合
├── requirements.txt                      ← 依赖清单
├── data/
│   ├── calc_train.jsonl                  ← 训练数据(完整版)
│   ├── calc_train_min.jsonl              ← 训练数据(Demo 默认使用精简版)
│   ├── calc_validation.jsonl             ← 验证数据(完整版)
│   └── calc_validation_min.jsonl         ← 验证数据(Demo 默认使用精简版)
├── functions/
│   ├── __init__.py
│   ├── rollout/
│   │   ├── rollout.py                    ← Rollout 函数(LangGraph + MCP 工具)
│   │   └── rollout_only.py              ← Rollout 函数(简单版,含追踪示例)
│   └── reward/
│       ├── reward.py                     ← Reward 函数(基础评分)
│       ├── reward_decorator.py           ← Reward 函数(装饰器风格)
│       └── group_reward.py              ← Reward 函数(分组评分)
├── resources/
│   ├── rollout_input.json               ← Rollout 测试输入
│   ├── reward_input.json                ← Reward 测试输入
│   ├── reward_decorator_input.json      ← 装饰器 Reward 测试输入
│   └── group_reward_input.json          ← 分组 Reward 测试输入
└── scripts/                             ← 本地启动与查询辅助脚本(build/install/start_local_*/query_local_*/query_online_tuning/convert_parquet_to_jsonl)
Demo overview
This demo implements a math calculation agent:
- Rollout function: Calls the model being trained and uses a calculator tool to answer math questions
- Reward function: Compares the model output with the reference answer to determine whether the answer is correct and assign a score
NoteThe rollout function in the demo uses LangGraph to orchestrate the agent flow and calls the calculator tool via MCP (Model Context Protocol, a tool calling protocol for LLMs).
To write your own rollout and reward functions, see the reinforcement learning development guide.
Data format
Training data uses the JSONL format, with one JSON object per line containing the messages and rollout_extra fields:
{"messages": [{"content": "Output the answer when you are ready. The answer should be surrounded by three sharps (`###`), in the form of ### ANSWER: <answer> ###. 6.6 minus x (3/2) times equals 5.6.", "role": "user"}], "rollout_extra": {"solution": "2/3"}}
messages: The user question, in the same format as ChatMLrollout_extra: Stores the reference answer or other business data, and is passed to the reward function for scoring (rollout_extra supports custom fields)
Data in rollout_extra is passed through to RolloutInput.rollout_extra of the rollout function and RewardInput.agent_output.rollout_extra of the reward function, making it easy to use in scoring logic. This field supports custom keys and is not limited to the solution in the example.
Data volume recommendations
- Getting started: A few dozen to a few hundred samples are enough to verify that the approach works (the data volume must be at least greater than
Batch_size). - Formal training: Larger data volumes yield better results, and large-scale datasets also support a larger batch_size, which helps improve training stability
Submit a training task
NoteTraining is billed by training unit hours, and a task that fails after it starts running is the most expensive way to fail. For your first submission (especially when switching to your own functions and data), we recommend going through the reinforcement learning pre-submission checklist first: tiered checks costing nothing to a dozen or so CNY catch data, code, and configuration errors before submission.
The demo already includes the rollout and reward functions. Run the following command to complete function deployment, data upload, and training task submission in one step:
python submit_job.py
Complete code and parameter descriptions
The following is the complete code of the training script, with comments explaining the meaning of each parameter and recommended values:
import asyncio
from dashscope.finetune.reinforcement import (
    RolloutFunctionComponent, RewardFunctionComponent,
    FunctionComponentModel, FunctionComponentRuntime,
    TrainingDataset, ValidationDataset, DataSourceType,
)
from dashscope.finetune.agentic_rl import AgenticRL

async def main():
    client = AgenticRL()

    # client.run() 一步完成:注册函数到 FC → 上传训练数据 → 提交训练任务
    result = await client.run(
        model="qwen3.5-9b",                              # 基座模型
        training_datasets=[TrainingDataset(              # 训练集
            data_source_type=DataSourceType.FILE_ID,
            file_name="./data/calc_train_min.jsonl",
        )],
        validation_datasets=[ValidationDataset(          # 验证集(可选)
            data_source_type=DataSourceType.FILE_ID,
            file_name="./data/calc_validation_min.jsonl",
        )],
        functions=[
            # Rollout 函数:定义模型如何执行策略采样
            RolloutFunctionComponent(
                name="rollout-1",
                timeout=600,
                fcmodel=FunctionComponentModel(
                    classpath="functions.rollout.rollout.CalcXRolloutProcessor"),
                runtime=FunctionComponentRuntime(
                    cpu=2, memory_size=4096, disk_size=512,
                    concurrency=30, capacity=30,
                    min_capacity=30, max_capacity=60,
                    memory_scale_threshold=0.6,
                    concurrency_scale_threshold=0.6,
                    env={})),                            # FC 函数环境变量
            RewardFunctionComponent(
                name="reward-1",
                weight=1.0,
                timeout=120,
                fcmodel=FunctionComponentModel(
                    classpath="functions.reward.reward.DemoRewardProcessor"),
                runtime=FunctionComponentRuntime(
                    cpu=2, memory_size=4096, disk_size=512,
                    concurrency=30, capacity=30,
                    min_capacity=30, max_capacity=60,
                    memory_scale_threshold=0.6,
                    concurrency_scale_threshold=0.6,
                    env={})),
        ],
        # MTU 计费配置
        resources={
            "charge_type": "mtu_postpaid",   # 计费方式:后付费填 mtu_postpaid;预付费填 mtu_prepaid,并需额外提供 instance_id(联系商务经理获取)
            "mtu_spec_code": "MTU4",         # 训练单元规格
            "mtu_capacity": 24,              # 本次任务占用的 MTU 数量,不必用满已购容量
        },
        # GSPO 算法超参数(以下为 qwen3.5-9b 非 MoE 模型的全部必选超参)
        hyper_parameters={
            "algorithm": "gspo",             # 训练算法
            "batch_size": 64,                # 批大小
            "eval_steps": 1,                 # 每 N 步执行一次验证
            "kl_loss_coef": 0.002,           # KL 散度损失系数
            "learning_rate": 2e-6,           # 学习率
            "lr_scheduler_type": "linear",   # 学习率调度策略
            "max_length": 8192,              # 最大序列长度(prompt + response)
            "n_epochs": 1,                   # 训练轮数
            "n_rollouts": 8,                 # 每个样本的 Rollout 次数
            "ppo_mini_batch_size": 8,        # PPO 小批量大小
            "save_strategy": "epoch",        # 保存策略(steps 或 epoch)
        })

    if result.status_code == 200:
        print(f"训练任务已提交,Job ID: {result.output.job_id}")
    else:
        print(f"提交失败: {result}")

asyncio.run(main())
NoteYou can also submit a training task via a configuration file or the CLI (dashscope rl run). For a field-by-field explanation of the three submission methods, see Training Configuration — Submission and Configuration.
Getting-started tips
After your first successful run, we recommend following these 4 practices:
- Start with a small dataset: Run once with the demo default
calc_train_min.jsonl+n_epochs=1to confirm the pipeline works, then switch to the full dataset. This avoids burning a large dataset on 24 MTUs only to discover a configuration error. - Leave hyperparameters unchanged at first: The 11 hyperparameters above are the recommended starting point for qwen3.5-9b, so do not tune them during your first training run. When you do tune, change only one variable at a time (lr or batch_size) and run a full
eval_steps × 3steps before judging the trend. - Watch one core metric: Check
critic/rewards/meanon the Metric tab — a steady increase means the model is learning; if it stalls or declines, stop and troubleshoot instead of running idle. - On FAILED, check logs first: Task failed → check the last error at the end of the Logs tab, or use the SDK to pull
AgenticRL.logs(job_id="ft-xxx", lines=100). Configuration/dependency errors can usually be identified at a glance.
NoteSee algorithm selection, hyperparameter starting points, and tuning decisions in Reinforcement Learning Training Configuration — Submission and Configuration; see reward function design philosophy and hacking defense in the reinforcement learning development guide; for metric anomaly attribution, see the troubleshooting decision tree in Observable Configuration and Metrics Reference for Reinforcement Learning.
Training monitoring and analysis
After you submit the job, the job_id returned by run() is the unique identifier for querying the training status. Training typically takes from tens of minutes to several hours, depending on the dataset size and model.
In the Model Studio console, go to the Model Fine-tuning page and click a job to open its details page, which contains the following five tabs:
Tab | Purpose | Main content |
|---|---|---|
Details | Job metadata | Job ID, status, base model, training method, start/end times, data configuration |
Trajectory | Agent behavior replay | Complete dialogue process, reward analysis (across step, sample, and trajectory dimensions), and tool calling details |
Metrics | Training health | 13 groups of metric charts (actor, critic, trajectory, trace, timing, perf, fully_async, etc.), including user-defined metrics |
Logs | Runtime troubleshooting | stdout/stderr from the training process, used to locate the cause of errors when a job fails |
Output | Model assets | List of checkpoints and their publishing status. You can publish a checkpoint to "My Models" for deployment and use. |
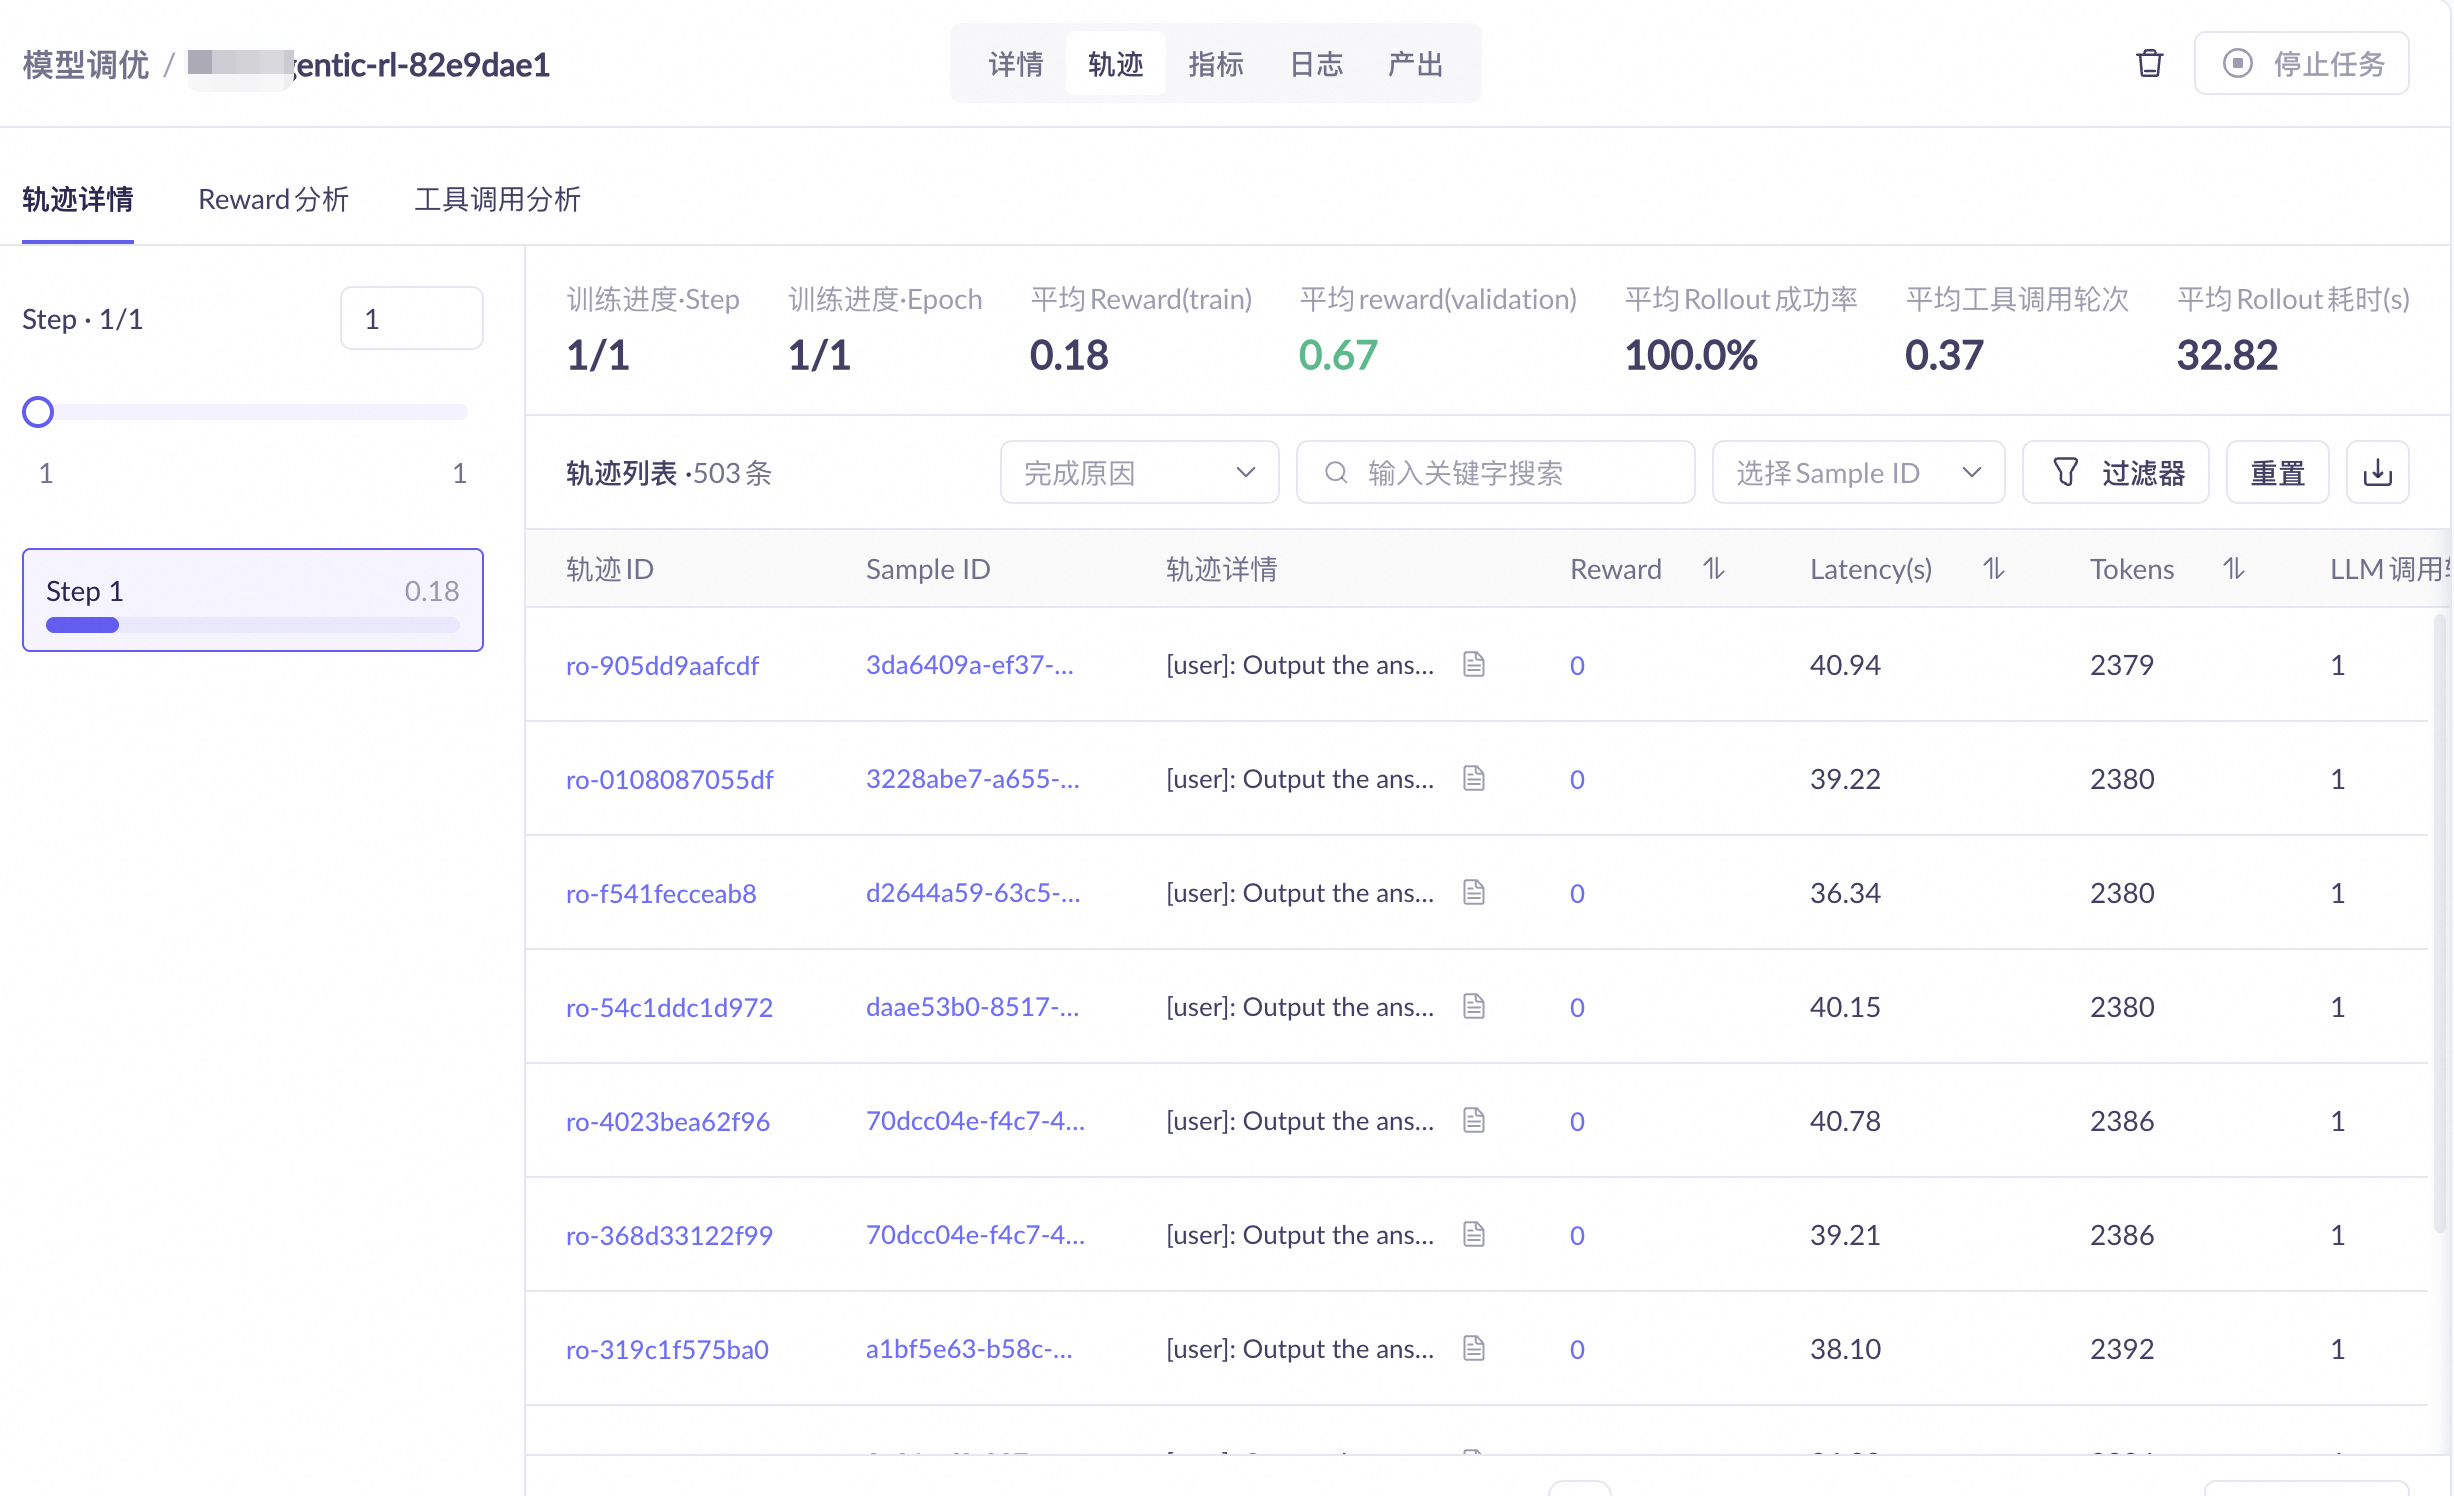
For a detailed description of each tab, see Observability Configuration for Reinforcement Learning.
Model publishing and deployment
After training completes, the last checkpoint is automatically published to My Models. To publish an intermediate checkpoint, go to the Model Studio console's Model Fine-tuning > Output page and do it manually. For more information, see Model fine-tuning in the console.
After a model is published, you can deploy it from the My Models page. Once deployed, you can call the model via an API. For details, see Model deployment.
Next steps
- Learn the full details of function development → Reinforcement Learning Development Guide
- Learn about training configuration and monitoring → Reinforcement Learning Training Configuration — Submission and Configuration
- Learn about observability configuration, trajectory viewing, and training metrics → Observability Configuration and Metric Reference for Reinforcement Learning