Video generation
Alibaba Cloud Model Studio provides video generation models for general-purpose creation (text-to-video, image-to-video, reference-to-video, video editing) and vertical scenarios (digital human lip-syncing, image-to-action, video character swapping, emoji creation).
Videos generated on the Online Experience page of the Model Studio console always carry a watermark: the text "AI generated" in the lower-right corner of the video. Because of legal compliance requirements, this watermark cannot be turned off from the console UI. To obtain videos without a watermark, call the Wan video generation models through the DashScope API, where the watermark parameter defaults to false (no watermark added). For more information, see Wan 2.7 text-to-video API reference and Wan 2.7 image-to-video API reference.
Model overview
| Service deployment scope | Chinese Mainland
| Global
| International
| US
|
Region | Beijing | Virginia | Singapore | Virginia |
Supported models | Wan - image-to-video - first frame | Wan - image-to-video - first frame |
Model selection
-
General video generation
- To generate a video from a text prompt, use Wan - text-to-video.
- To generate a cinematic shot from a single image, use Wan - Image-to-Video - First Frame.
- To control the transition between a starting and an ending image, use Wan - Image-to-Video - First and Last Frames.
- To replicate a character's appearance and voice from reference videos to match a new script, use Wan - reference-to-video.
- Also provides Third-party Models, such as
-
Digital human lip-syncing: Animates static photos to speak, sing, or narrate --- background stays fixed while the face, head, and body move.
- For the most natural results, including facial expressions, head, and body movements, use Wan - Digital human. This model replaces EMO.
- For videos longer than 20 seconds with simple head movements, such as news reports, use LivePortrait.
-
Video motion transfer : This feature keeps the background of the photo static and animates the person using motion from a reference video. Use Wan - image-to-action.
-
Video character swapping : This feature replaces the person in a video with a person from an image while keeping the original background. Use Wan - video character swapping.
-
Dance replacement: Replaces the dancer in a video with a person from an image. For best quality, use Wan - image-to-action and Wan - video character swapping. If budget is limited, use AnimateAnyone.
-
Video lip replacement: This feature replaces the lip movements in an existing video to match new audio. Use VideoRetalk.
-
Emoji creation: This feature creates emojis using fixed-style templates. Use Emoji.
-
Video redrawing: To use fixed-style templates, use Video style transfer. To describe styles freely using prompts, use Wan - general video editing.
-
Video editing: For all the following tasks, use Wan - general video editing.
- Local video editing: Replace elements such as subjects or clothing, or remove bystanders.
- Video extension: Extend short videos, for example, from 1 second to 5 seconds.
- Video frame expansion: Convert landscape videos to portrait mode or fill in missing borders.
- Multi-image reference generation: Fuse background and subject images to create a video.
Video generation models
Wan - text-to-video
This model generates cinematic, multi-shot narrative videos from text prompts and audio inputs.
API reference | Model pricing | Prompt guide | Try online: Beijing, Singapore, US (Virginia)
Chinese mainland
If you select the Chinese mainland deployment scope, model inference compute resources are restricted to the Chinese mainland. Static data is stored in your selected region. Supported region: China (Beijing).
| Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.7-t2v-2026-04-25 | Video with audio Multi-shot narrative, audio-video synchronization | Text, audio | Resolution options: 720P, 1080P Video duration: [2s, 15s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.7-t2v | Video with audio Multi-shot narrative, audio-video synchronization | Text, audio | Resolution options: 720P, 1080P Video duration: [2s, 15s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.6-t2v | Video with audio Multi-shot narrative, audio-video synchronization | Text, audio | Resolution options: 720P, 1080P Video duration: [2s, 15s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.5-t2v-preview | Video with audio Audio-video synchronization | Text, audio | Resolution options: 480P, 720P, 1080P Video duration: 5s, 10s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.2-t2v-plus | Silent video
| Text | Resolution options: 480P, 1080P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wanx2.1-t2v-turbo | Silent video | Text | Resolution options: 480P, 720P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wanx2.1-t2v-plus | Silent video | Text | Resolution options: 720P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
Global
If you select the Global deployment scope, model inference compute resources are dynamically scheduled worldwide. Static data is stored in your selected region. Supported regions: US (Virginia), Germany (Frankfurt).
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.6-t2v | Video with audio Multi-shot narrative, audio-video synchronization | Text, audio | Resolution options: 720P, 1080P Video duration: 5s, 10s, 15s Defined specifications: 30 fps, MP4 (H.264 encoding) |
International
If you select the International deployment scope, model inference compute resources are dynamically scheduled worldwide, excluding the Chinese mainland. Static data is stored in your selected region. Supported region: Singapore.
| Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.7-t2v-2026-04-25 | Video with audio Multi-shot narrative, audio-video synchronization | Text, audio | Resolution options: 720P, 1080P Video duration: [2s, 15s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.7-t2v | Video with audio Multi-shot narrative, audio-video synchronization | Text, audio | Resolution options: 720P, 1080P Video duration: [2s, 15s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.6-t2v | Video with audio Multi-shot narrative, audio-video synchronization | Text, audio | Resolution options: 720P, 1080P Video duration: [2s, 15s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.5-t2v-preview | Video with audio Audio-video synchronization | Text, audio | Resolution options: 480P, 720P, 1080P Video duration: 5s, 10s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.2-t2v-plus | Silent video
| Text | Resolution options: 480P, 1080P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.1-t2v-turbo | Silent video | Text | Resolution options: 480P, 720P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.1-t2v-plus | Silent video | Text | Resolution options: 720P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
US
If you select the US deployment scope, model inference compute resources are restricted to the United States. Static data is stored in your selected region. Supported region: US (Virginia).
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.6-t2v-us | Video with audio Multi-shot narrative, audio-video synchronization | Text, audio | Resolution options: 720P, 1080P Video duration: 5s, 10s, 15s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.7 is a video generation model. It outputs only an MP4 video stream and does not return coordinates, bounding boxes, or structured recognition data. To obtain the coordinates of objects in an image, for example the doors, windows, or furniture in a floor plan, use a visual understanding model such as Qwen3-VL-Plus for object detection. This type of model returns structured results with bounding box coordinates.
| Input prompt | Output video (wan2.6, multi-shot video) |
|---|---|
An epic and adorable scene. A small, cute cartoon kitten general, wearing detailed golden armor and a slightly oversized helmet, stands bravely on a cliff. He rides a small but heroic warhorse and says: "Dark clouds from Qinghai hang over the snowy range; My lonely fort looks out to Yumen Pass. My golden armor is pierced by sand in a hundred fights; I will not return until we have broken Loulan." Below the cliff, a vast and endless army of mice with makeshift weapons charges forward. This is a dramatic, large-scale battle scene inspired by ancient Chinese war epics. In the distance, dark clouds gather over the snowy mountains. The overall atmosphere is a humorous and epic fusion of "cute" and "domineering". |
Wan - image-to-video
The Wan image-to-video model is upgraded with multimodal input (text/image/audio/video) and supports three tasks: first-frame-to-video, first-and-last-frame-to-video, and video continuation.
API reference | Model pricing | Prompt guide
Chinese Mainland
If you select the Chinese mainland deployment scope, model inference compute resources are restricted to the Chinese mainland. Static data is stored in your selected region. Supported region: China (Beijing).
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.7-i2v-2026-04-25 | Video with audio First-frame-to-video, first-and-last-frame-to-video, video continuation, video continuation with last frame control Multi-shot narrative, audio-video synchronization | Text, image, audio, video | Resolution options: 720P, 1080P Video duration: [2s, 15s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.7-i2v | Video with audio First-frame-to-video, first-and-last-frame-to-video, video continuation, video continuation with last frame control Multi-shot narrative, audio-video synchronization | Text, image, audio, video | Resolution options: 720P, 1080P Video duration: [2s, 15s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
International
If you select the International deployment scope, model inference compute resources are dynamically scheduled worldwide, excluding the Chinese mainland. Static data is stored in your selected region. Supported region: Singapore.
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.7-i2v-2026-04-25 | Video with audio First-frame-to-video, first-and-last-frame-to-video, video continuation, video continuation with last frame control Multi-shot narrative, audio-video synchronization | Text, image, audio, video | Resolution options: 720P, 1080P Video duration: [2s, 15s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.7-i2v | Video with audio First-frame-to-video, first-and-last-frame-to-video, video continuation, video continuation with last frame control Multi-shot narrative, audio-video synchronization | Text, image, audio, video | Resolution options: 720P, 1080P Video duration: [2s, 15s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
Wan - Image-to-video from first frame
Generates a video from a first-frame image. This model accepts a prompt, a first-frame image, and audio as input to produce cinematic, multi-shot narrative videos.
API reference | Model pricing | Prompt guide | Try online: Beijing, Singapore, Virginia
Chinese mainland
If you select the Chinese mainland deployment scope, model inference compute resources are restricted to the Chinese mainland. Static data is stored in your selected region. Supported region: China (Beijing).
| Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.6-i2v-flash | Video with audio, silent video Multi-shot narrative, audio-video synchronization | Text, image, audio | Resolution options: 720P, 1080P Video duration: [2s, 15s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.6-i2v | Video with audio Multi-shot narrative, audio-video synchronization | Text, image, audio | Resolution options: 720P, 1080P Video duration: [2s, 15s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.5-i2v-preview | Video with audio Audio-video synchronization | Text, image, audio | Resolution options: 480P, 720P, 1080P Video duration: 5s, 10s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.2-i2v-flash | Silent video
| Text, image | Resolution options: 480P, 720P, 1080P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.2-i2v-plus | Silent video
| Text, image | Resolution options: 480P, 1080P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wanx2.1-i2v-plus | Silent video | Text, image | Resolution options: 720P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wanx2.1-i2v-turbo | Silent video | Text, image | Resolution options: 480P, 720P Video duration: 3s, 4s, 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
Global
If you select the Global deployment scope, model inference compute resources are dynamically scheduled worldwide. Static data is stored in your selected region. Supported regions: US (Virginia), Germany (Frankfurt).
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.6-i2v | Video with audio Multi-shot narrative, audio-video synchronization | Text, image, audio | Resolution options: 720P, 1080P Video duration: 5s, 10s, 15s Defined specifications: 30 fps, MP4 (H.264 encoding) |
International
If you select the International deployment scope, model inference compute resources are dynamically scheduled worldwide, excluding the Chinese mainland. Static data is stored in your selected region. Supported region: Singapore.
| Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.6-i2v-flash | Video with audio, silent video Multi-shot narrative, audio-video synchronization | Text, image, audio | Resolution options: 720P, 1080P Video duration: [2s, 15s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.6-i2v | Video with audio Multi-shot narrative, audio-video synchronization | Text, image, audio | Resolution options: 720P, 1080P Video duration: [2s, 15s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.5-i2v-preview | Video with audio Audio-video synchronization | Text, image, audio | Resolution options: 480P, 720P, 1080P Video duration: 5s, 10s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.2-i2v-flash | Silent video
| Text, image | Resolution options: 480P, 720P, 1080P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.2-i2v-plus | Silent video
| Text, image | Resolution options: 480P, 1080P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.1-i2v-plus | Silent video | Text, image | Resolution options: 720P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.1-i2v-turbo | Silent video | Text, image | Resolution options: 480P, 720P Video duration: 3s, 4s, 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
US
If you select the US deployment scope, model inference compute resources are restricted to the United States. Static data is stored in your selected region. Supported region: US (Virginia).
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.6-i2v-us | Video with audio Multi-shot narrative, audio-video synchronization | Text, image, audio | Resolution options: 720P, 1080P Video duration: 5s, 10s, 15s Defined specifications: 30 fps, MP4 (H.264 encoding) |
| Input prompt | Input first frame image and audio | Output video (wan2.6, multi-shot video) |
|---|---|---|
An urban fantasy art scene. A dynamic graffiti art character. A teenager made of spray paint comes to life from a concrete wall. He performs an English rap at high speed while striking a classic, energetic rapper pose. The scene is set under an urban railway bridge at night. The lighting comes from a single streetlight, creating a cinematic atmosphere with high energy and amazing detail. The audio of the video consists entirely of his rap, with no other dialogue or noise. | 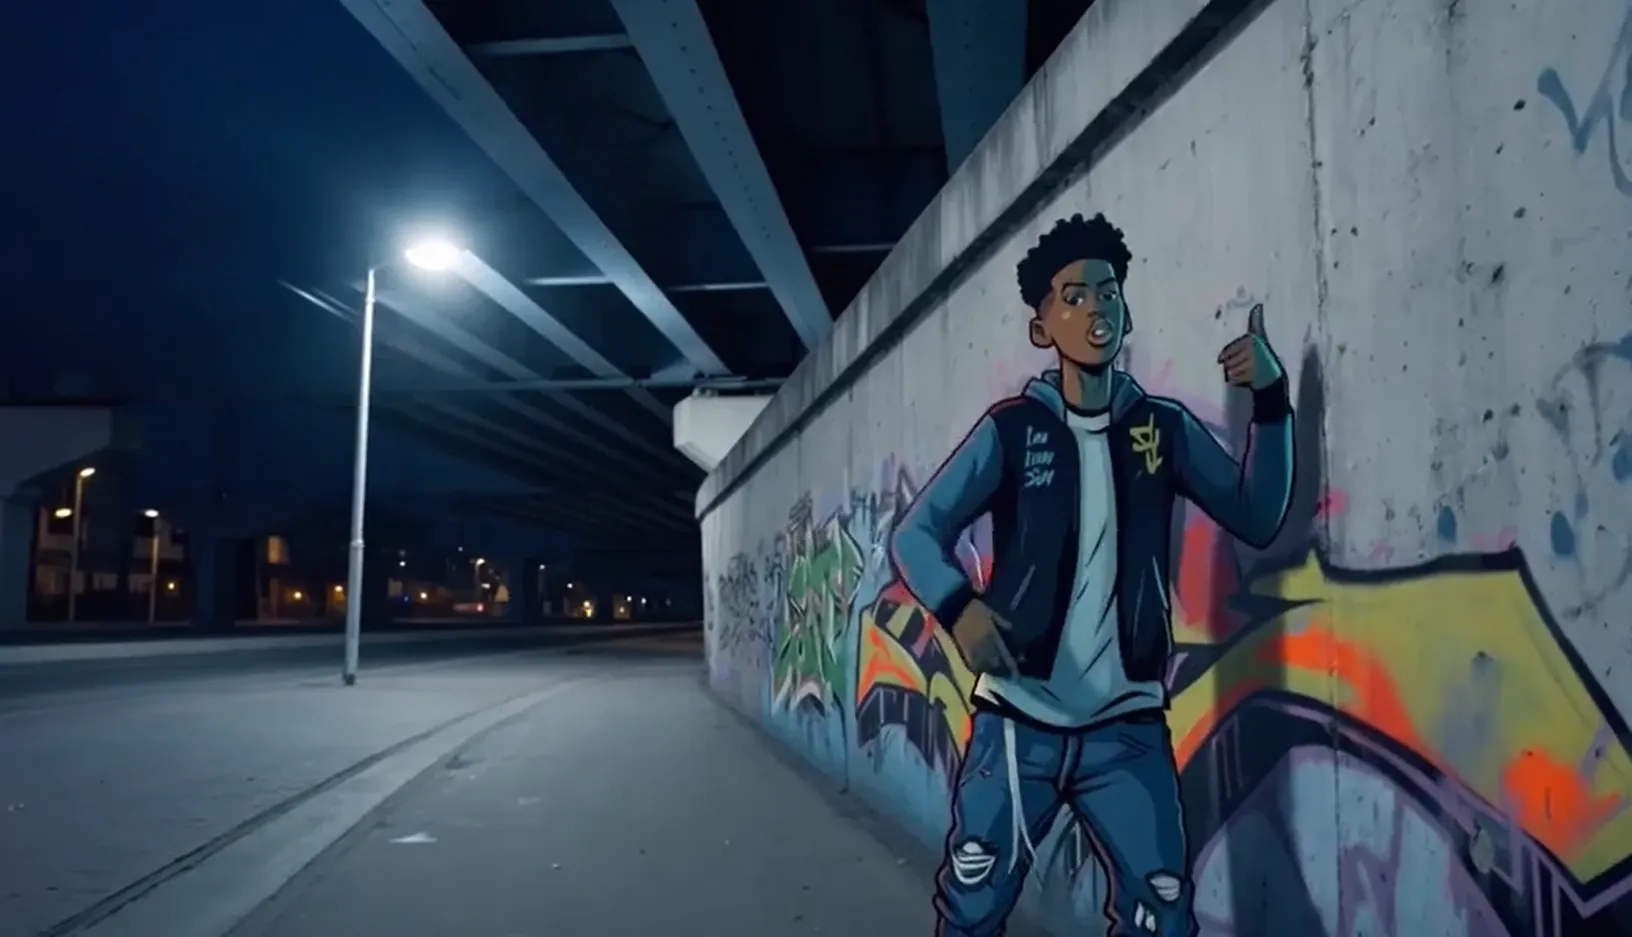 Input audio: |
Wan - Image-to-video - First and last frames
Generates a video with a natural transition between a first-frame and last-frame image. The model uses text, a first-frame image, a last-frame image, and audio to create cinematic, multi-shot videos.
API reference | Model pricing | Prompt guide
Chinese mainland
If you select the Chinese mainland deployment scope, model inference compute resources are restricted to the Chinese mainland. Static data is stored in your selected region. Supported region: China (Beijing).
| Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.2-kf2v-flash | Silent video
| Text, image | Resolution options: 480P, 720P, 1080P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
wanx2.1-kf2v-plus | Silent video | Text, image | Resolution options: 720P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
International
If you select the International deployment scope, model inference compute resources are dynamically scheduled worldwide, excluding the Chinese mainland. Static data is stored in your selected region. Supported region: Singapore.
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.1-kf2v-plus | Silent video | Text, image | Resolution options: 720P Video duration: 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
| Input first frame image | Input last frame image | Input prompt | Output video |
|---|---|---|---|
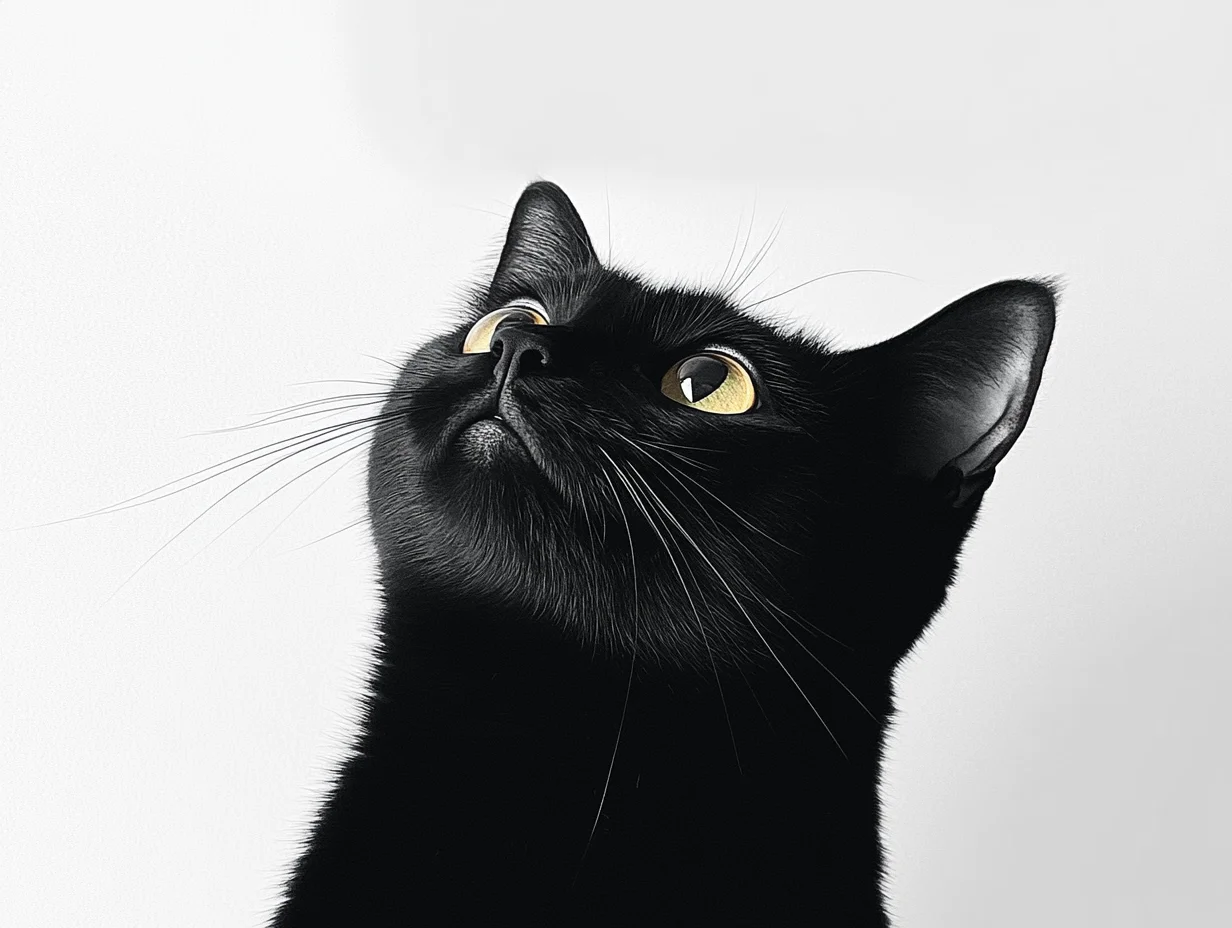 | 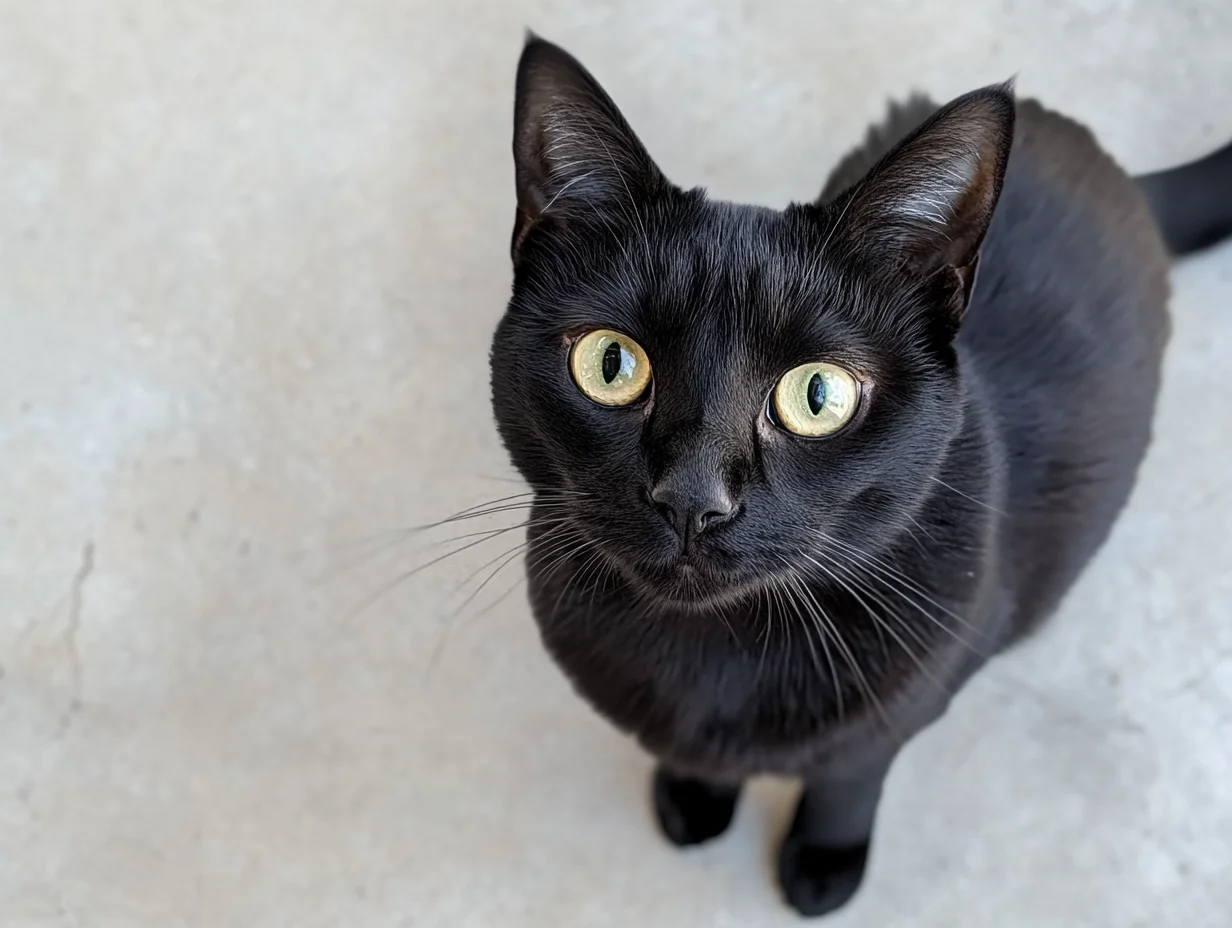 | Realistic style. A small black cat looks up at the sky curiously. The camera starts at eye level, gradually rises, and ends with a top-down shot of the cat's curious gaze. |
Wan - Reference-to-video
Replicates a character's appearance and voice from a reference video to act out a new script. This model uses a reference video and a text Prompt to generate a video with Multi-shot Narrative and Audio-visual Synchronization, ensuring character consistency.
API reference | Model pricing | Prompt guide
Chinese mainland
If you select the Chinese mainland deployment scope, model inference compute resources are restricted to the Chinese mainland. Static data is stored in your selected region. Supported region: China (Beijing).
| Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.7-r2v | Video with audio Multi-entity reference-to-video, supports configuring timbre for entities. | Text, image, video, audio | Resolution options: 720P, 1080P Video duration: [2s, 10s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.6-r2v-flash | Video with audio, silent video Single-role/multi-role video generation Multi-shot narrative, audio-video synchronization
| Text, image, video | Resolution options: 720P, 1080P Video duration: [2s, 10s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.6-r2v | Video with audio Single-role/multi-role video generation Multi-shot narrative, audio-video synchronization | Text, image, video | Resolution options: 720P, 1080P Video duration: [2s, 10s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
Global
If you select the Global deployment scope, model inference compute resources are dynamically scheduled worldwide. Static data is stored in your selected region. Supported regions: US (Virginia), Germany (Frankfurt).
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.6-r2v | Video with audio Single-role/multi-role video generation Multi-shot narrative, audio-video synchronization | Text, video | Resolution options: 720P, 1080P Video duration: 5s, 10s Defined specifications: 30 fps, MP4 (H.264 encoding) |
International
If you select the International deployment scope, model inference compute resources are dynamically scheduled worldwide, excluding the Chinese mainland. Static data is stored in your selected region. Supported region: Singapore.
| Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.7-r2v | Video with audio Multi-entity reference-to-video, supports configuring timbre for entities. | Text, image, video, audio | Resolution options: 720P, 1080P Video duration: [2s, 10s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.6-r2v-flash | Video with audio, silent video Single-role/multi-role video generation Multi-shot narrative, audio-video synchronization
| Text, image, video | Resolution options: 720P, 1080P Video duration: [2s, 10s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.6-r2v | Video with audio Single-role/multi-role video generation Multi-shot narrative, audio-video synchronization | Text, image, video | Resolution options: 720P, 1080P Video duration: [2s, 10s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
| Input reference video 1 (role: little girl) | Input reference video 2 (role: alarm clock) | Input prompt | Output video (multi-role dialogue) |
|---|---|---|---|
character1 says to character2: “I’ll rely on you tomorrow morning!” character2 replies: “You can count on me!” |
Wan - Video editing
Video editing model. Accepts text, image, and video multimodal input to perform various video generation and editing tasks.
Video editing 2.7 API reference | Video editing 2.1 API reference | Model pricing
Chinese mainland
If you select the Chinese mainland deployment scope, model inference compute resources are restricted to the Chinese mainland. Static data is stored in your selected region. Supported region: China (Beijing).
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.7-videoedit | Video with audio, silent video (depends on the input video) Instruction-based editing, video migration | Text, image, video | Resolution options: 720P, 1080P Video duration: [2s, 10s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wanx2.1-vace-plus | Silent video Multi-image reference, video redrawing, local editing, video extension, video frame extension | Text, image, video | Resolution options: 720P Video duration: Up to 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
International
If you select the International deployment scope, model inference compute resources are dynamically scheduled worldwide, excluding the Chinese mainland. Static data is stored in your selected region. Supported region: Singapore.
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.7-videoedit | Video with audio, silent video (depends on the input video) Instruction-based editing, video migration | Text, image, video | Resolution options: 720P, 1080P Video duration: [2s, 10s] (integer) Defined specifications: 30 fps, MP4 (H.264 encoding) |
wan2.1-vace-plus | Silent video Multi-image reference, video redrawing, local editing, video extension, video frame extension | Text, image, video | Resolution options: 720P Video duration: Up to 5s Defined specifications: 30 fps, MP4 (H.264 encoding) |
Video editing 2.1 model
-
Feature 1: Multi-image reference
Input reference image 1 (reference entity) Input reference image 2 (reference background) Input prompt Output video 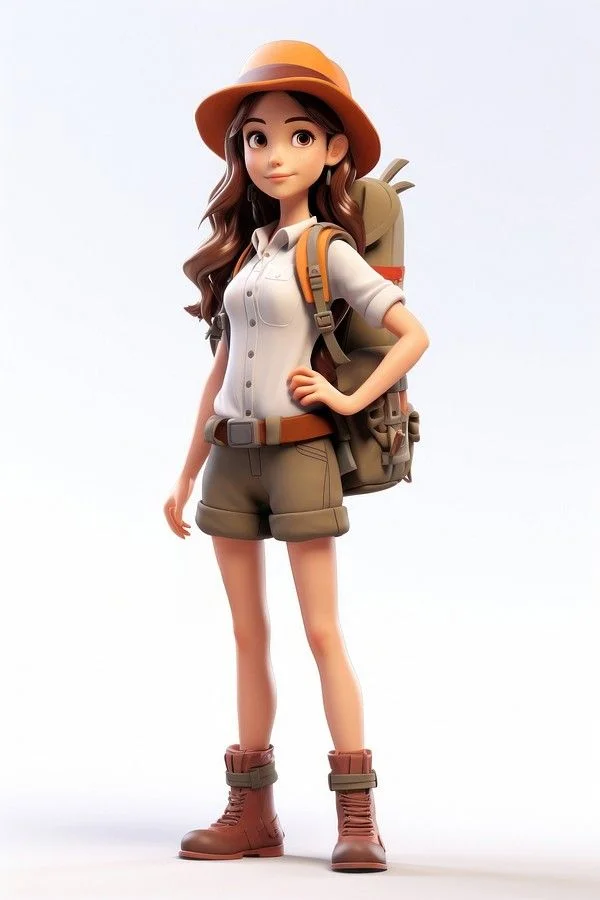
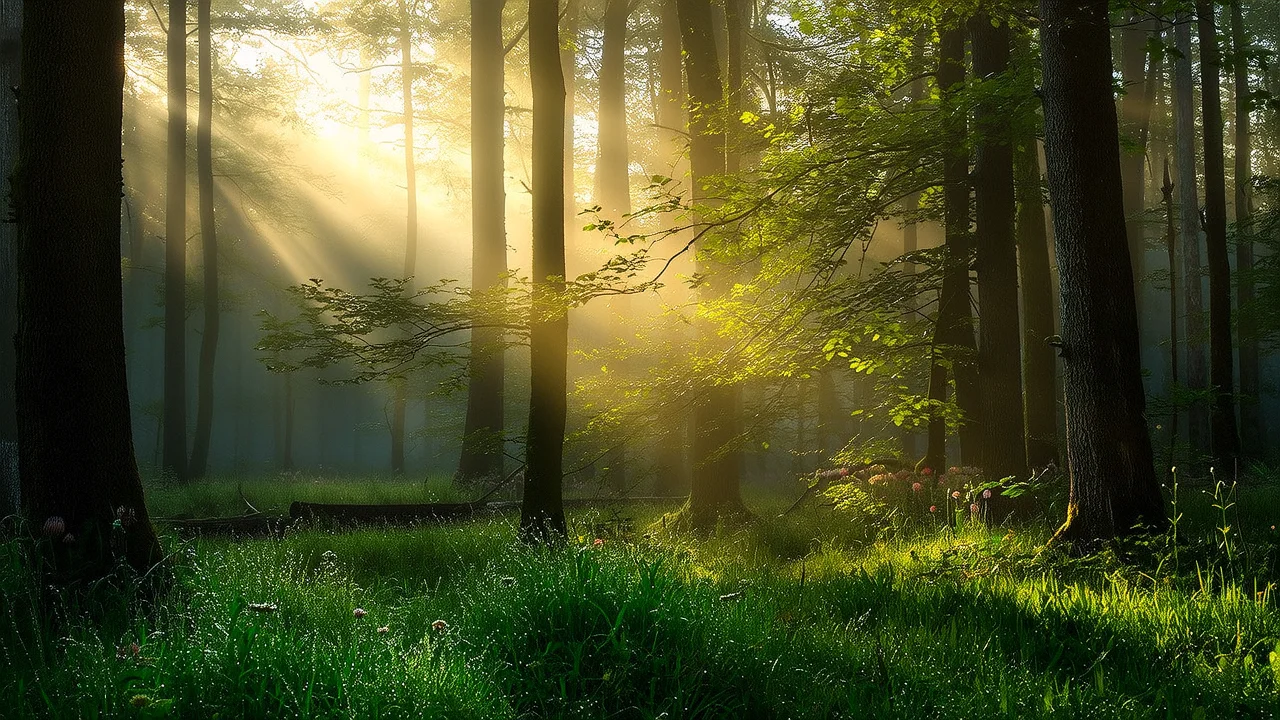
In the video, a girl gracefully walks out from the depths of an ancient, misty forest. Her steps are light, and the camera captures her every nimble moment. When she stops and looks around at the lush woods, a smile of surprise and joy blossoms on her face. This moment, frozen in the interplay of light and shadow, records her wonderful encounter with nature.
-
Feature 2: Video redrawing
Input video Input prompt Output video The video shows a black steampunk-style car driven by a gentleman, adorned with gears and copper pipes. The background is a steam-powered candy factory with retro elements, creating a vintage and playful scene.
-
Feature 3: Local video editing
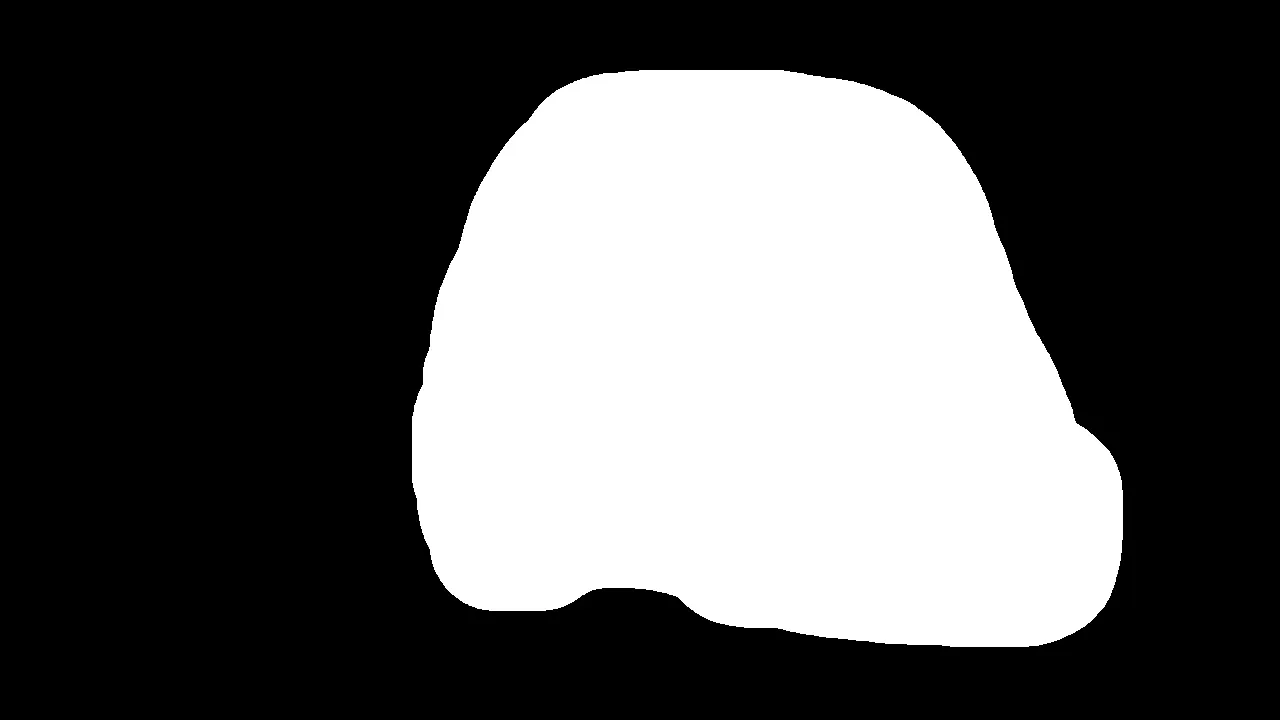
Input video Input mask image (the white area indicates the editing area) Input prompt Output video 
The video shows a Parisian-style French cafe where a lion in a suit elegantly sips coffee. It holds a coffee cup in one hand, taking a gentle sip with a contented expression. The cafe is tastefully decorated, with soft hues and warm lighting illuminating the area where the lion is.
-
Feature 4: Video extension
Input first video segment (1s) Input prompt Output video (extended video is 5s) A dog wearing sunglasses skateboards on a street, 3D cartoon.
-
Feature 5: Video frame extension
Input video Input prompt Output video An elegant woman passionately plays the violin, with a full symphony orchestra behind her.
Wan - Digital human
NoteOnly the Chinese mainland service deployment scope is supported. Data storage is in the Beijing access region. Model inference compute resources are limited to the Chinese mainland.
Generate performance and narration Videos from an Image. This model synthesizes an Image and an Audio file into a Video where a person or cartoon character speaks, sings, or narrates. The output Video automatically includes synchronized lip movements, facial expressions, and head and body movements.
Image detection API reference | Video generation API reference | Model pricing
Model | Features | Input modality | Output description |
|---|---|---|---|
wan2.2-s2v-detect | Image detection | Image | Output detection status: Pass or Fail |
wan2.2-s2v | Video generation Video with audio | Image, audio | Resolution options: 480P, 720P Video duration: Up to 20s (follows audio duration) Defined specifications:
|
| Input example (character image + audio) | Output video (lip-sync) |
|---|---|
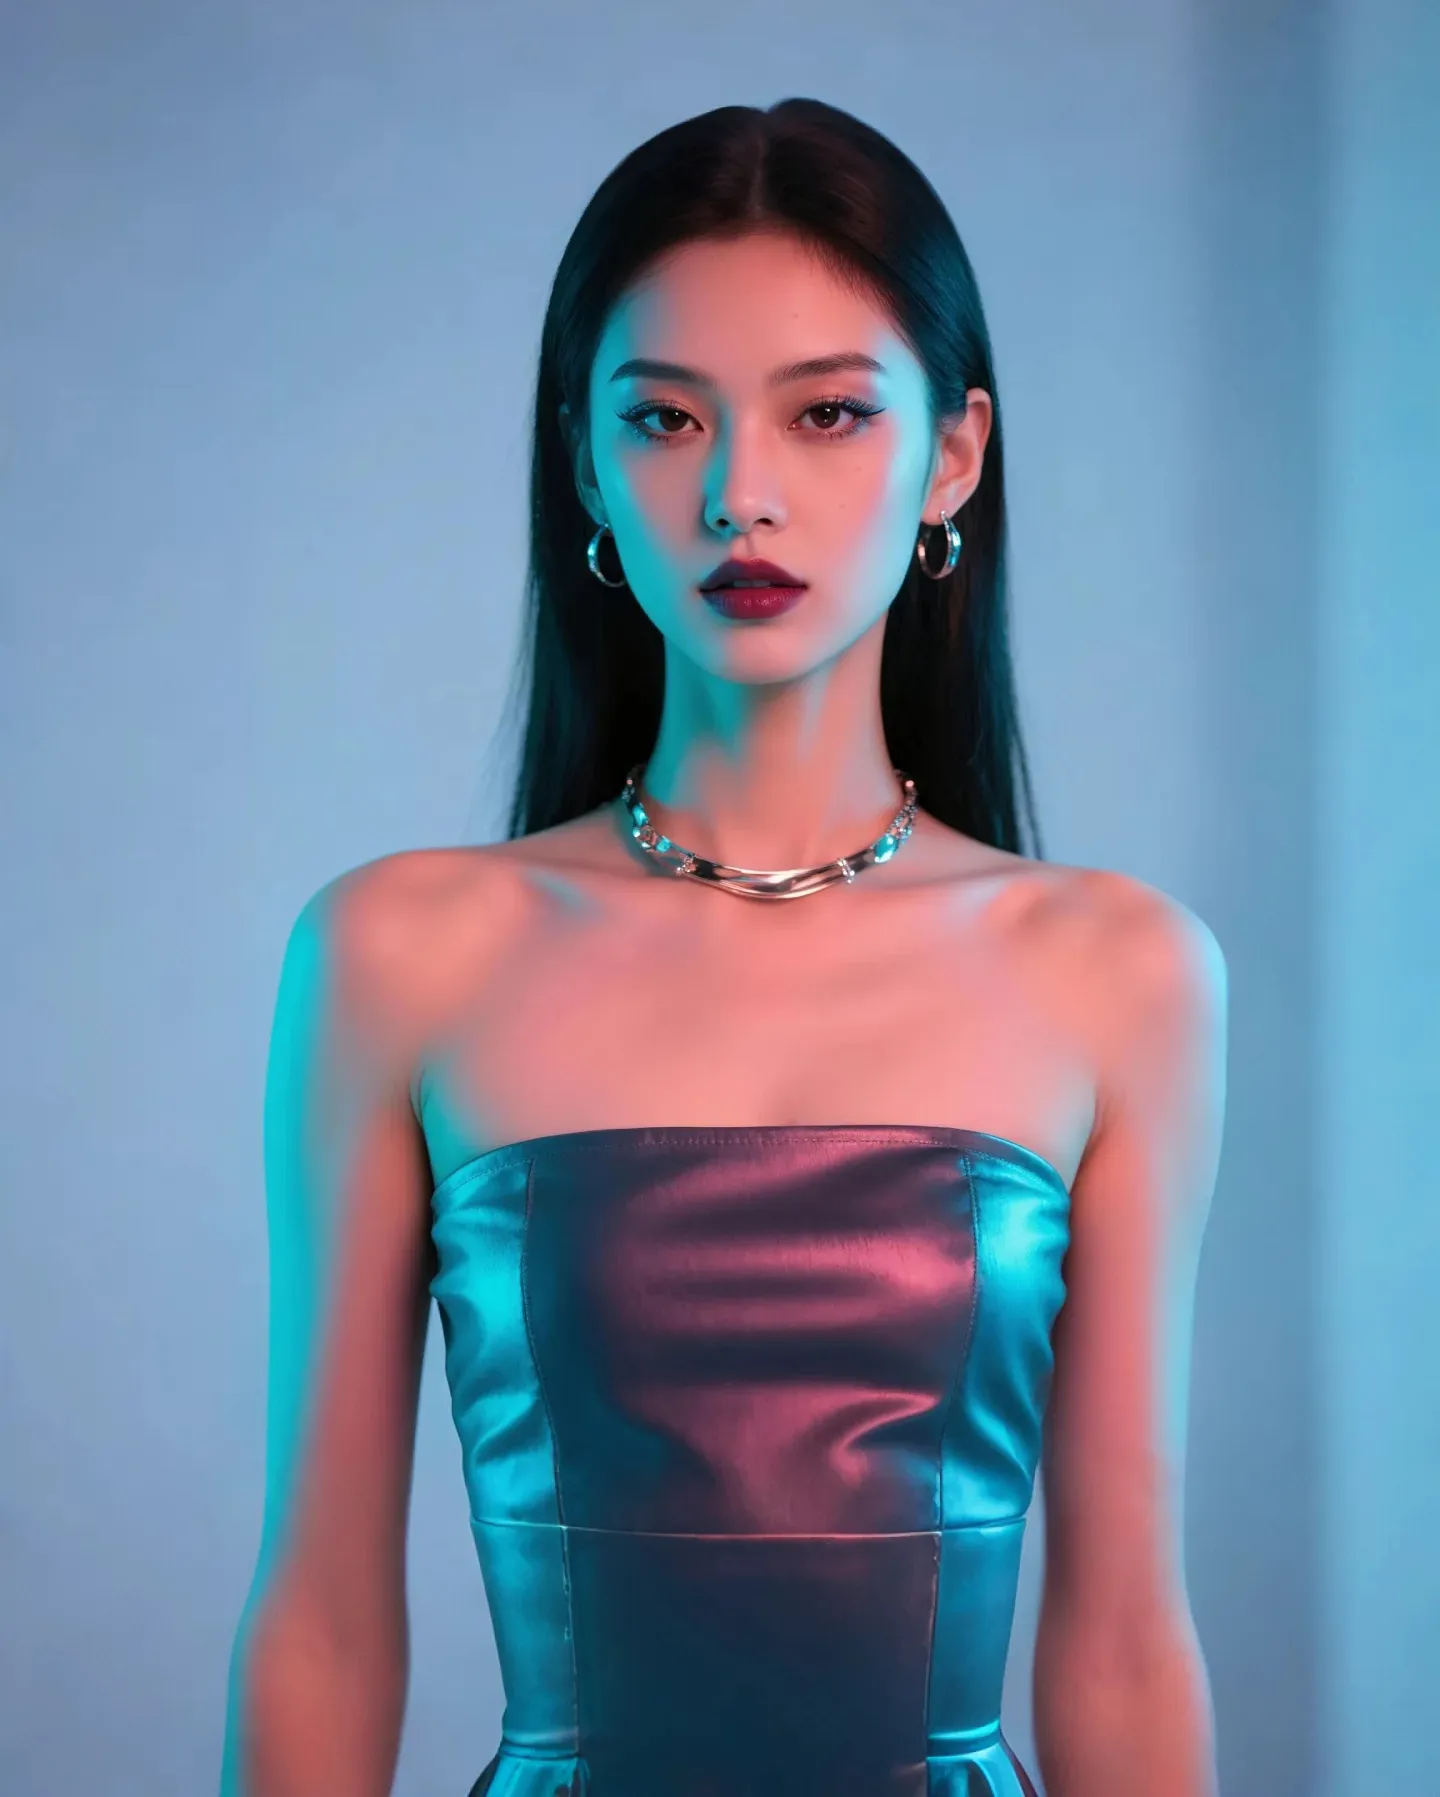 Input audio: |
Wan - Image-to-action
Animates a person in an image using motion from a reference video. You provide an image and a video, and the model generates an output video where the person performs the motion from the video against the static background of the image.
Chinese mainland
If you select the Chinese mainland deployment scope, model inference compute resources are restricted to the Chinese mainland. Static data is stored in your selected region. Supported region: China (Beijing).
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.2-animate-move | Video with audio, silent video (depends on the input video)
| Image, video | Resolution options: 720P Video duration: 2s < duration < 30s Defined specifications:
|
International
If you select the International deployment scope, model inference compute resources are dynamically scheduled worldwide, excluding the Chinese mainland. Static data is stored in your selected region. Supported region: Singapore.
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.2-animate-move | Video with audio, silent video (depends on the input video)
| Image, video | Resolution options: 720P Video duration: 2s < duration < 30s Defined specifications:
|
| Input character image | Input reference video | Output video (standard mode | Output video (professional mode |
|---|---|---|---|
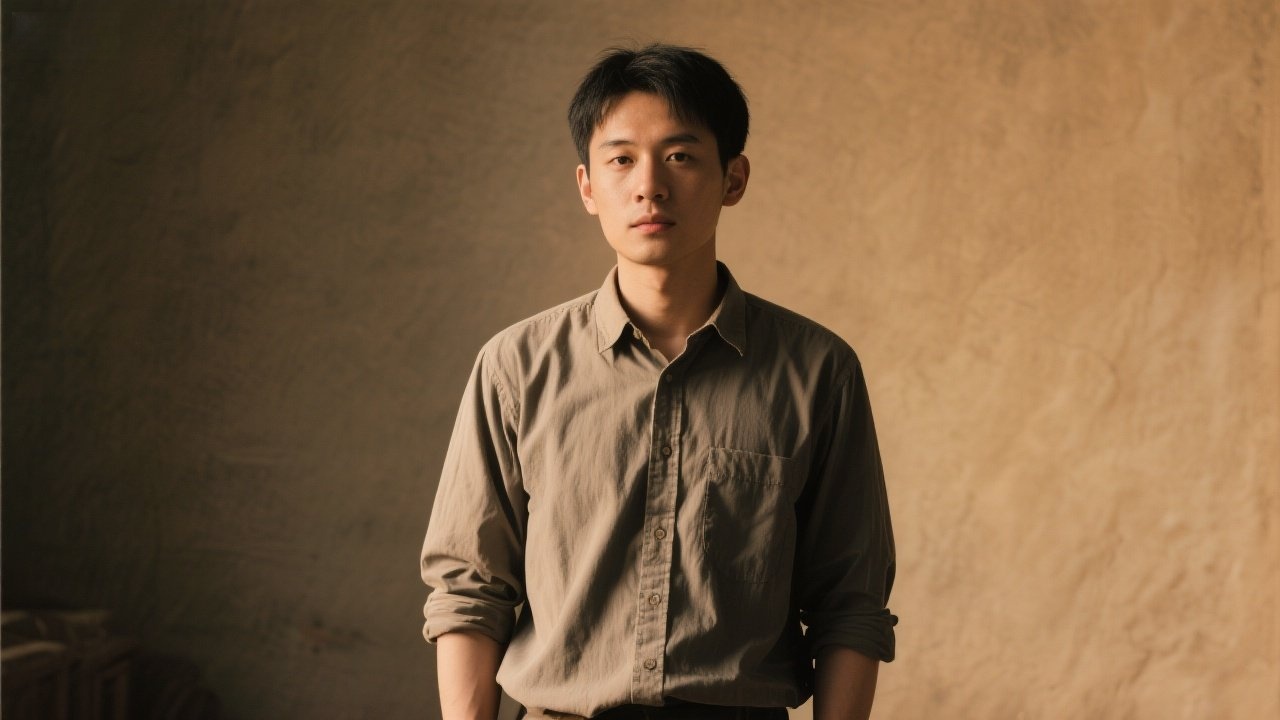 |
Wan - Video character swapping
Replaces a person in a video with a person from an image. Provide a video and a replacement image. The model generates an output video that retains the original video's background. This enables face swapping and character replacement.
Chinese Mainland
If you select the Chinese mainland deployment scope, model inference compute resources are restricted to the Chinese mainland. Static data is stored in your selected region. Supported region: China (Beijing).
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.2-animate-mix | Video with audio, silent video (depends on the input video)
| Image, video | Resolution options: 720P Video duration: 2s < duration < 30s Defined specifications:
|
International
If you select the International deployment scope, model inference compute resources are dynamically scheduled worldwide, excluding the Chinese mainland. Static data is stored in your selected region. Supported region: Singapore.
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
wan2.2-animate-mix | Video with audio, silent video (depends on the input video)
| Image, video | Resolution options: 720P Video duration: 2s < duration < 30s Defined specifications:
|
| Input video | Input character image for replacement | Output video (standard mode | Output video (professional mode |
|---|---|---|---|
 |
AnimateAnyone
Note
- Only the Chinese mainland service deployment scope is supported. Data storage is in the Beijing access region. Model inference compute resources are limited to the Chinese mainland.
- We recommend using Wan - image-to-action and Wan - Video character swapping to replace AnimateAnyone. These models provide better results, while AnimateAnyone is a more cost-effective option.
Designed specifically for dancing, this model replaces the dancer in a video with a person from an image. You provide an image and a video. The model generates an output video, which can either retain the image background or the video background.
Image detection API reference | Motion Template Generation API reference | Video generation API reference | Model pricing
| Model | Features | Input modality | Output description |
|---|---|---|---|
animate-anyone-detect-gen2 | Image detection | Image | Output detection status: Pass or Fail |
animate-anyone-template-gen2 | Dance video template generation
| Video | Outputs a dance action template ID. |
animate-anyone-gen2 | Video generation Silent video | Image, video, dance action template ID | Video resolution options: 720P Video duration: 2s ≤ duration ≤ 60s Defined specifications: 15 fps, MP4 (H.264 encoding) |
| Input character image | Input dance video | Output video (generated with image background) | Output video (generated with video background) |
|---|---|---|---|
 |
EMO
Note
- Only the Chinese mainland service deployment scope is supported. Data storage is in the Beijing access region. Model inference compute resources are limited to the Chinese mainland.
- We recommend using Wan-Digital Human to replace EMO. Wan-Digital Human provides better results, while EMO is a more cost-effective option.
Generates singing or performance videos from an image. You provide an image and an audio file, and EMO automatically generates a video with synchronized lip movements, facial expressions, and head motions.
Image detection API reference | Video generation API reference | Model pricing
Model | Features | Input modality | Output description |
|---|---|---|---|
emo-detect-v1 | Image detection | Image | Output detection status: Pass or Fail |
emo-v1 | Video generation Video with audio | Image, audio | Video resolution:
Video duration: Up to 60s Defined specifications: 15 fps, MP4 (H.264 encoding) |
| Input example (portrait image + audio) | Output video (lip-sync singing) |
|---|---|
 Input audio: |
LivePortrait
Note
- Only the Chinese mainland service deployment scope is supported. Data storage is in the Beijing access region. Model inference compute resources are limited to the Chinese mainland.
- For higher-quality results, use Wan - Digital human instead of LivePortrait. However, LivePortrait is a more cost-effective option and is suitable for generating videos longer than 20 seconds.
Generates narration videos from an image, animating a person to deliver news or tell stories. You provide an image and an audio file. The model then automatically generates a video with synchronized lip movements, facial expressions, and slight head motion.
Image detection API reference | Video generation API reference | Model pricing
Model | Features | Input modality | Output description |
|---|---|---|---|
liveportrait-detect | Image detection | Image | Output detection status: Pass or Fail |
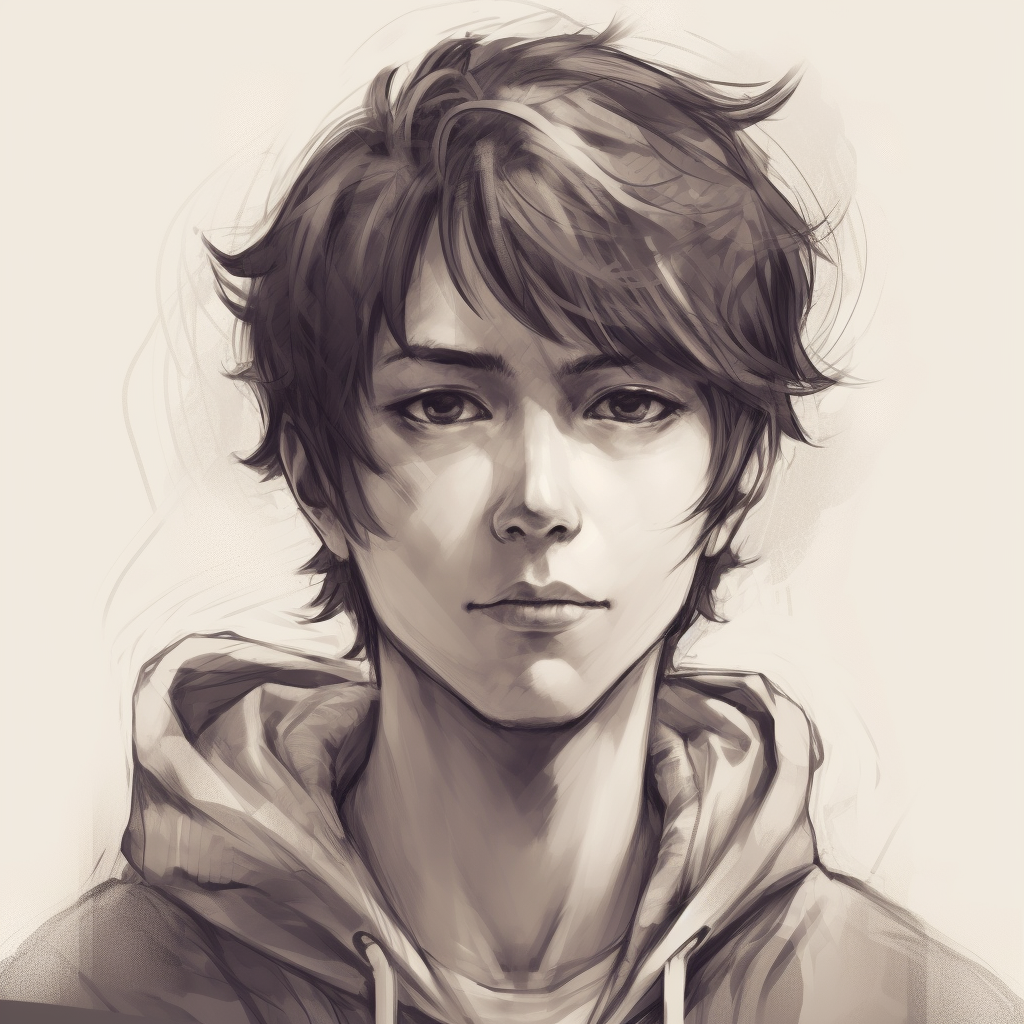
liveportrait | Video generation Video with audio | Image, audio | Video resolution: Follows the input image, up to nearly 4K (4096 × 4096). Video duration: 1s < duration < 180s Video frame rate: 15 fps ≤ frame rate ≤ 30 fps Video format: MP4 (H.264 encoding) |
| Input example (portrait image + audio) | Output video (lip-sync voiceover) |
|---|---|
 Input audio: |
Emoji
NoteOnly the Chinese mainland service deployment scope is supported. Data storage is in the Beijing access region. Model inference compute resources are limited to the Chinese mainland.
Creates emojis from fixed templates. Provide an image and a template ID to generate an emoji video.
Image detection API reference | Video generation API reference | Model pricing
Model | Features | Input modality | Output description |
|---|---|---|---|
emoji-detect-v1 | Image detection | Image | Output detection status: Pass or Fail |
emoji-v1 | Video generation Silent video | Image, emoji template ID | Video resolution: Fixed at 512x512 Video duration: Up to 5s (follows template duration) Defined specifications: 15 fps, MP4 (H.264 encoding) |
| Input portrait image | Output video ("disgusted" emoji) |
|---|---|
 |
VideoRetalk
NoteOnly the Chinese mainland service deployment scope is supported. Data storage is in the Beijing access region. Model inference compute resources are limited to the Chinese mainland.
Lip sync: Replaces the lip movements in a video to match a new audio track. Provide a video and an audio file. The model then generates a new video with synchronized lip movements.
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
videoretalk | Video with audio | Video, audio | Video resolution: Follows the input video, up to nearly 2K (2048 × 2048). Video duration: 2s < duration < 120s Video frame rate: 15 fps ≤ frame rate ≤ 60 fps Video format: MP4 (H.264 encoding) |
| Input example (character broadcast video + audio) | Output video (lip-sync replacement) |
|---|---|
Input audio: |
Video style transfer
NoteOnly the Chinese mainland service deployment scope is supported. Data storage is in the Beijing access region. Model inference compute resources are limited to the Chinese mainland.
Applies an artistic style to a video based on a style template. You provide a video and a style transfer ID to generate a restyled video.
| Model | Features | Input modality | Output video specifications |
|---|---|---|---|
video-style-transform | Video with audio, silent video
| Video, style transfer ID | Video resolution: Follows the input video, up to nearly 4K (4096 × 4096). Video duration: Up to 30s Video frame rate: 15 fps ≤ frame rate ≤ 25 fps Video format: MP4 (H.264 encoding) |
| Input video | Output video (style transfer: "Japanese manga") |
|---|---|
Video generation - third-party models
AIsphere - Text-to-video
NoteOnly the Chinese mainland service deployment scope is supported. Data storage is in the Beijing access region. Model inference compute resources are limited to the Chinese mainland.
API Reference | Model Pricing | Online Demo: Beijing
| Model | Features | Input modality | Output video specifications |
|---|---|---|---|
pixverse/pixverse-v6-t2v | Video with audio, silent video
| Text | Resolution options: 360P, 540P, 720P, 1080P Video duration: [1, 15] seconds (integer) Defined specifications: 24 fps, MP4 (H.264 encoding) |
pixverse/pixverse-v5.6-t2v | Video with audio, silent video | Text | Resolution options: 360P, 540P, 720P, 1080P Video duration: 5s, 8s, 10s (10s is not supported for 1080P) Defined specifications: 24 fps, MP4 (H.264 encoding) |
AIsphere - Image-to-video (first frame)
NoteOnly the Chinese mainland service deployment scope is supported. Data storage is in the Beijing access region. Model inference compute resources are limited to the Chinese mainland.
API Reference | Model Pricing | Online Demo: Beijing
| Model | Features | Input modality | Output video specifications |
|---|---|---|---|
pixverse/pixverse-v6-it2v | Video with audio, silent video
| Text, image | Resolution options: 360P, 540P, 720P, 1080P Video duration: [1, 15] seconds (integer) Defined specifications: 24 fps, MP4 (H.264 encoding) |
pixverse/pixverse-v5.6-it2v | Video with audio, silent video | Text, image | Resolution options: 360P, 540P, 720P, 1080P Video duration: 5s, 8s, 10s (10s is not supported for 1080P) Defined specifications: 24 fps, MP4 (H.264 encoding) |
AIsphere - Image-to-video (first and last frames)
NoteOnly the Chinese mainland service deployment scope is supported. Data storage is in the Beijing access region. Model inference compute resources are limited to the Chinese mainland.
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
pixverse/pixverse-v6-kf2v | Video with audio, silent video | Text, image | Resolution options: 360P, 540P, 720P, 1080P Video duration: [1, 15] seconds (integer) Defined specifications: 24 fps, MP4 (H.264 encoding) |
pixverse/pixverse-v5.6-kf2v | Video with audio, silent video | Text, image | Resolution options: 360P, 540P, 720P, 1080P Video duration: 5s, 8s, 10s (10s is not supported for 1080P) Defined specifications: 24 fps, MP4 (H.264 encoding) |
AIsphere - Reference-to-video
NoteOnly the Chinese mainland service deployment scope is supported. Data storage is in the Beijing access region. Model inference compute resources are limited to the Chinese mainland.
Generates a video from multiple reference images. Provide images and a Text Prompt to generate a video that maintains Character Consistency.
Model | Features | Input modality | Output video specifications |
|---|---|---|---|
pixverse/pixverse-v5.6-r2v | Video with audio, silent video | Text, image | Resolution options: 360P, 540P, 720P, 1080P Video duration: 5s, 8s, 10s (10s is not supported for 1080P) Defined specifications: 24 fps, MP4 (H.264 encoding) |