Deploy AHPA
Container Service for Kubernetes supports AHPA (Advanced Horizontal Pod Autoscaler) scaling. Based on historical data, AHPA predicts future resource demand and adjusts Pod replicas to ensure that resources are scaled out and pre-warmed before traffic peaks. This improves responsiveness and stability, while scale-in during predicted off-peak hours reduces resource costs.
Prerequisites
-
Create an ACK managed cluster or an ACK Serverless cluster. For more information, see Create an ACK managed cluster or Create an ACK Serverless cluster.
-
Enable Prometheus monitoring and collect at least seven days of historical application data, such as CPU and memory usage. For information about how to enable Prometheus monitoring, see Configure Managed Service for Prometheus.
Step 1: Install AHPA Controller
-
Log on to the ACK console. In the left navigation pane, click Clusters.
-
On the Clusters page, click the name of your cluster. In the left navigation pane, click Components and Add-ons .
-
On the Add-ons page, find the AHPA Controller add-on. On the add-on card, click Install and follow the on-screen instructions to install the add-on.
Step 2: Configure the Prometheus data source
Log on to the ARMS console.
-
In the left navigation pane, choose .
-
At the top of the Instances page, select the region where the Prometheus instance resides, and then click the name of the target instance. The instance name matches the name of the Container Service for Kubernetes (ACK) cluster.
-
On the current Settings page, record the values of the following configuration items in the HTTP API Address (Grafana Read Address) section.
-
(Optional) If a token is enabled, set the access token.
-
View and record the Internal Network address (Prometheus URL).
-
-
Set the Prometheus query URL in the ACK cluster.
-
Create application-intelligence.yaml with the following content:
-
prometheusUrl: The Prometheus access URL of Application Real-Time Monitoring Service (ARMS). -
token: The Prometheus access token.
apiVersion: v1 kind: ConfigMap metadata: name: application-intelligence namespace: kube-system data: prometheusUrl: "http://cn-hangzhou-intranet.arms.aliyuncs.com:9443/api/v1/prometheus/da9d7dece901db4c9fc7f5b9c40****/158120454317****/cc6df477a982145d986e3f79c985a****/cn-hangzhou" token: "eyJhxxxxx"NoteTo view the Prometheus monitoring dashboard for AHPA, you must also configure the following fields in this ConfigMap:
-
prometheus_writer_url: The internal endpoint for Remote Write. -
prometheus_writer_ak: The AccessKey ID of your Alibaba Cloud account. -
prometheus_writer_sk: The AccessKey secret of your Alibaba Cloud account.
For more information, see Enable Prometheus Service for AHPA.
-
-
Deploy application-intelligence.
kubectl apply -f application-intelligence.yaml
-
Step 3: Deploy a test service
The test service includes fib-deployment, fib-svc, and fib-loader. The fib-loader service simulates request peaks and troughs. A Horizontal Pod Autoscaler (HPA) resource is also deployed to compare results with AHPA.
Create demo.yaml with the following content:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: fib-deployment
  namespace: default
  annotations:
    k8s.aliyun.com/eci-use-specs: "1-2Gi"
spec:
  replicas: 1
  selector:
    matchLabels:
      app: fib-deployment
  strategy:
    rollingUpdate:
      maxSurge: 25%
      maxUnavailable: 25%
    type: RollingUpdate
  template:
    metadata:
      creationTimestamp: null
      labels:
        app: fib-deployment
    spec:
      containers:
      - image: registry.cn-huhehaote.aliyuncs.com/kubeway/knative-sample-fib-server:20200820-171837
        imagePullPolicy: IfNotPresent
        name: user-container
        ports:
        - containerPort: 8080
          name: user-port
          protocol: TCP
        resources:
          limits:
            cpu: "1"
            memory: 2000Mi
          requests:
            cpu: "1"
            memory: 2000Mi
---
apiVersion: v1
kind: Service
metadata:
  name: fib-svc
  namespace: default
spec:
  ports:
  - name: http
    port: 80
    protocol: TCP
    targetPort: 8080
  selector:
    app: fib-deployment
  sessionAffinity: None
  type: ClusterIP
---
apiVersion: apps/v1
kind: Deployment
metadata:
  name: fib-loader
  namespace: default
spec:
  progressDeadlineSeconds: 600
  replicas: 1
  revisionHistoryLimit: 10
  selector:
    matchLabels:
      app: fib-loader
  strategy:
    rollingUpdate:
      maxSurge: 25%
      maxUnavailable: 25%
    type: RollingUpdate
  template:
    metadata:
      creationTimestamp: null
      labels:
        app: fib-loader
    spec:
      containers:
      - args:
        - -c
        - |
          /ko-app/fib-loader --service-url="http://fib-svc.${NAMESPACE}?size=35&interval=0" --save-path=/tmp/fib-loader-chart.html
        command:
        - sh
        env:
        - name: NAMESPACE
          valueFrom:
            fieldRef:
              apiVersion: v1
              fieldPath: metadata.namespace
        image: registry.cn-huhehaote.aliyuncs.com/kubeway/knative-sample-fib-loader:20201126-110434
        imagePullPolicy: IfNotPresent
        name: loader
        ports:
        - containerPort: 8090
          name: chart
          protocol: TCP
        resources:
          limits:
            cpu: "8"
            memory: 16000Mi
          requests:
            cpu: "2"
            memory: 4000Mi
---
apiVersion: autoscaling/v1
kind: HorizontalPodAutoscaler
metadata:
  name: fib-hpa
  namespace: default
spec:
  maxReplicas: 50
  minReplicas: 1
  scaleTargetRef:
    apiVersion: apps/v1
    kind: Deployment
    name: fib-deployment
  targetCPUUtilizationPercentage: 50
---
Step 4: Deploy AHPA
Submit an AdvancedHorizontalPodAutoscaler resource to configure a scaling policy. Complete the following steps:
-
Create ahpa-demo.yaml with the following content:
apiVersion: autoscaling.alibabacloud.com/v1beta1
kind: AdvancedHorizontalPodAutoscaler
metadata:
  name: ahpa-demo
spec:
  scaleStrategy: observer
  metrics:
  - type: Resource
    resource:
      name: cpu
      target:
        type: Utilization
        averageUtilization: 40
  scaleTargetRef:
    apiVersion: apps/v1
    kind: Deployment
    name: fib-deployment
  maxReplicas: 100
  minReplicas: 2
  stabilizationWindowSeconds: 300
  prediction:
    quantile: 95
    scaleUpForward: 180
  instanceBounds:
  - startTime: "2021-12-16 00:00:00"
    endTime: "2031-12-16 00:00:00"
    bounds:
    - cron: "* 0-8 ? * MON-FRI"
      maxReplicas: 15
      minReplicas: 4
    - cron: "* 9-15 ? * MON-FRI"
      maxReplicas: 15
      minReplicas: 10
    - cron: "* 16-23 ? * MON-FRI"
      maxReplicas: 20
      minReplicas: 15
The following table describes some of the parameters:
Parameter
Required
Description
scaleTargetRef
Yes
The target Deployment.
metrics
Yes
The scaling metrics. Supported metrics include CPU, GPU, memory, queries per second (QPS), and RT.
target
Yes
The target threshold. For example,
averageUtilization: 40indicates that the target CPU utilization is 40%.scaleStrategy
No
The scaling mode. Default value: observer.
-
auto: AHPA performs scaling.
-
observer: AHPA only observes and does not perform actual scaling. Use this mode to check whether AHPA works as expected.
-
proactive: Only proactive prediction takes effect.
-
reactive: Only reactive prediction takes effect.
maxReplicas
Yes
The maximum number of replicas for scale-out.
minReplicas
Yes
The minimum number of replicas for scale-in.
stabilizationWindowSeconds
No
The scale-in cooldown period. Default value: 300 seconds.
prediction. quantile
Yes
The prediction quantile. The greater the probability that the actual metric value is lower than the specified target value, the more conservative the prediction. Valid values: 0 to 100. Default value: 99. Recommended values: 90 to 99.
prediction. scaleUpForward
Yes
The time required for a Pod to reach the Ready state (cold start time).
instanceBounds
No
The replica count boundaries for scaling time periods.
-
startTime: The start time.
-
endTime: The end time.
instanceBounds. bounds. cron
No
Configures a scheduled task. A Cron expression represents a set of points in time and consists of five fields separated by spaces. For example,
- cron: "* 0-8 ? * MON-FRI"runs the task from midnight to 08:00, Monday through Friday, every month.The following table describes the fields of a Cron expression. For more information, see Cron jobs.
Field
Required
Allowed values
Allowed special characters
Minutes
Yes
0 to 59
* / , -
Hours
Yes
0 to 23
* / , -
Day of month
Yes
1 to 31
* / , - ?
Month
Yes
1 to 12 or JAN to DEC
* / , -
Day of week
No
0 to 6 or SUN to SAT
* / , - ?
-
Values in the Month and Day of week fields are case-insensitive. For example,
SUN,Sun, andsunhave the same effect. -
If the Day of week field is not configured, the default value is
*. -
Special characters:
-
*: Represents all possible values. -
/: Represents an increment of a specified value. -
,: Represents a list of enumerated values. -
-: Represents a range. -
?: Represents an unspecified value.
-
-
-
Create the AHPA scaling policy.
kubectl apply -f ahpa-demo.yaml
Step 5: View prediction results
To view the AHPA scaling prediction results, see Enable Prometheus Service for AHPA.
Predictions require seven days of historical data. After the preceding example is deployed, it must run for seven days before you can view the prediction results. If you already have an application running in production, specify it directly in AHPA.
This example sets the scaling mode to observer and compares it with an HPA policy. The HPA policy serves as a reference for the resources that an application actually requires, so you can check whether the AHPA prediction results meet expectations.
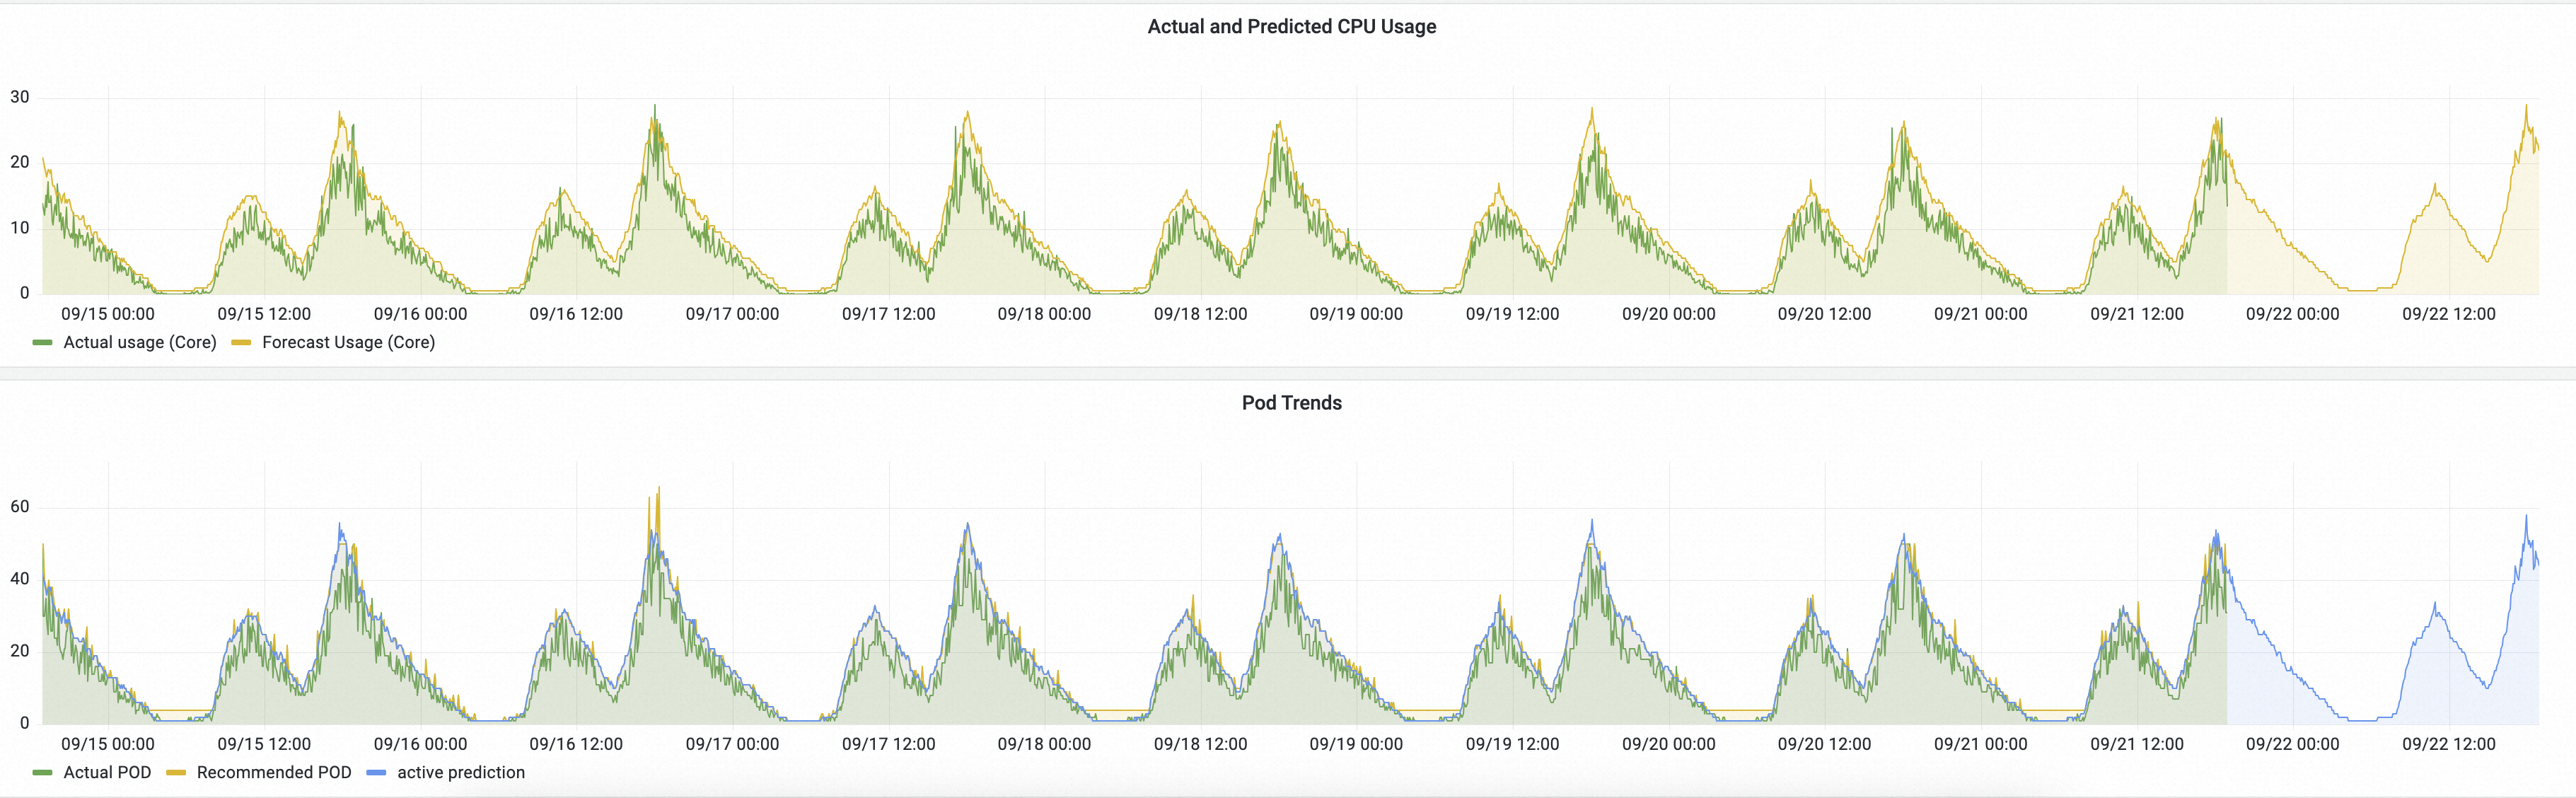
-
Actual and predicted CPU usage: The green line indicates the actual CPU usage under HPA, and the yellow line indicates the CPU usage predicted by AHPA.
-
If the yellow line is above the green line, the predicted CPU capacity is sufficient.
-
If the yellow line precedes the green line, the required resources are prepared in advance.
-
-
Pod trend: The green line indicates the actual number of Pods scaled by HPA, and the yellow line indicates the number of Pods predicted by AHPA.
-
If the yellow line is below the green line, the predicted number of Pods is lower.
-
If the yellow line is smoother than the green line, AHPA scaling fluctuates less, which improves service stability.
-
The prediction trend meets expectations. If your observations confirm this, set the scaling mode to auto so that AHPA performs scaling.
References
-
To observe GPU metrics through Managed Service for Prometheus, see Implement AHPA elastic prediction based on GPU metrics.
-
To view the monitoring dashboards provided by Managed Service for Prometheus, see Enable Prometheus Service for AHPA.