Synchronize PolarDB-X to AnalyticDB for PostgreSQL
Data Transmission Service (DTS) synchronizes data from PolarDB-X to AnalyticDB for PostgreSQL (formerly HybridDB for PostgreSQL), enabling ad-hoc query and analysis, ETL processing, and visual exploration on petabyte-scale data.
Prerequisites
-
The databases in your PolarDB-X instance must be created on ApsaraDB RDS for MySQL.
-
The source tables to be synchronized must have a primary key.
-
You have an AnalyticDB for PostgreSQL instance. For more information, see .
Precautions
During full data initialization, DTS consumes read and write resources of the source and destination databases, which may increase the database load. When the databases have low performance, low specifications, or heavy workloads (for example, a large number of slow SQL statements, tables without primary keys, or deadlocks on the destination database), the database pressure may be further increased and services may become unavailable. Therefore, you must evaluate the performance of the source and destination databases before starting data synchronization, and it is recommended that you perform data synchronization during off-peak hours (for example, when the CPU load of both the source and destination databases is below 30%).
-
During data synchronization, do not perform operations such as scaling, migrating hot tables, changing sharding keys, or executing DDL statements on the PolarDB-X instance. These operations can cause the data synchronization task to fail.
-
If you need to change the network type of a PolarDB-X instance during data synchronization, you must update the task's network connection information afterward.
-
If you create a new source table to synchronize after the task has started, you must add it as a synchronization object to the task.
-
The source PolarDB-X instance must be version 5.2 or later. For information about how to view the instance version, see Instance version overview.
Billing
|
Synchronization type |
Pricing |
|
Schema synchronization and full data synchronization |
Free of charge. |
|
Incremental data synchronization |
Charged. For more information, see Billing overview. |
Limitations
-
DTS supports only table-level data synchronization. You cannot use append-optimized (AO) tables as destination tables.
-
DTS does not support synchronizing data of the following types: JSON, GEOMETRY, CURVE, SURFACE, MULTIPOINT, MULTILINESTRING, MULTIPOLYGON, and GEOMETRYCOLLECTION.
Supported SQL operations
INSERT, UPDATE, and DELETE.
Term mappings
|
PolarDB-X |
AnalyticDB for PostgreSQL |
|
Database |
Schema |
|
Table |
Table |
Procedure
-
Purchase a data synchronization task. For more information, see Purchase a DTS instance.
NoteWhen purchasing the task, set the source instance to PolarDB-X (upgraded from DRDS), the destination instance to AnalyticDB for PostgreSQL, and the synchronization topology to One-way Synchronization.
- Log on to the Data Transmission Service console.
Note
If you are automatically redirected to the Data Management (DMS) console, you can click the
 icon in the lower-right corner and then click
 to return to the classic DTS console.
- In the navigation pane on the left, click Data Synchronization.
- In the top navigation bar of the Data Synchronization page, select the region where the destination instance is located.
- Find the purchased data synchronization instance and click Configure Synchronization Channel.
-
Configure the source and destination instances for the synchronization task.
Category
Parameter
Description
N/A
Synchronization task name
DTS automatically generates a task name. We recommend that you use a descriptive name for easier identification. The name does not need to be unique.
Source instance information
Instance type
This parameter is fixed to DRDS Instance.
Instance region
The region of the source instance that you selected during purchase. This parameter cannot be changed.
DRDS instance ID
Select the ID of the PolarDB-X instance.
Destination instance information
Instance type
This parameter is fixed to AnalyticDB for PostgreSQL.
Instance region
The region of the destination instance that you selected during purchase. This parameter cannot be changed.
Instance ID
Select the ID of the AnalyticDB for PostgreSQL instance.
Database name
Enter the name of the destination database in the AnalyticDB for PostgreSQL instance.
Database account
Enter the database account for the AnalyticDB for PostgreSQL instance.
Database password
Enter the password for the database account.
-
In the lower-right corner of the page, click Set Whitelist and Next.
If the source or destination database is an Alibaba Cloud database instance, such as an ApsaraDB RDS for MySQL or ApsaraDB for MongoDB instance, DTS automatically adds the CIDR blocks of DTS servers to the IP address whitelist of the instance. If the source or destination database is a self-managed database hosted on an Elastic Compute Service (ECS) instance, DTS automatically adds the CIDR blocks of DTS servers to the security group rules of the ECS instance, and you must make sure that the ECS instance can access the database. If the self-managed database is hosted on multiple ECS instances, you must manually add the CIDR blocks of DTS servers to the security group rules of each ECS instance. If the source or destination database is a self-managed database that is deployed in a data center or provided by a third-party cloud service provider, you must manually add the CIDR blocks of DTS servers to the IP address whitelist of the database to allow DTS to access the database. For more information, see Whitelist DTS server IP addresses.
WarningAdding the public IP address blocks of the DTS service, either automatically or manually, may pose security risks. Using this product, you acknowledge that you understand and accept the potential security risks and that you must implement basic security measures. These measures include, but are not limited to, strengthening password security, limiting the ports open to each CIDR block, using authentication for internal API calls, and regularly checking and restricting unnecessary CIDR blocks. Alternatively, you can connect through a private network using a leased line, VPN Gateway, or Smart Access Gateway.
-
Configure the synchronization policy and objects.
Category
Parameter
Description
Synchronization policy configuration
Synchronization initialization
By default, you must select both Schema initialization and Full data initialization. After the precheck passes, DTS initializes the schema and data of the selected objects in the destination instance, providing a baseline for subsequent incremental data synchronization.
Processing mode for existing destination table
-
Clear data in destination table
Skips the Destination table is empty check item during the precheck phase. Clears data from the destination table before full initialization. This option is suitable for production synchronization after you have tested the synchronization task.
-
Ignore Errors and Proceed
Skips the Whether the target table is empty check item in the precheck phase. During full data initialization, synchronized data is directly appended. This option is suitable for scenarios where you need to aggregate data from multiple tables into a single table.
Synchronization operation type
Select the operation types to synchronize based on your business requirements:
-
Insert
-
Update
-
Delete
Select synchronization objects
N/A
In the Source Objects box, select the tables you want to synchronize, and then click the
 icon to move them to the Selected Objects box.Note
-
You can only select tables as synchronization objects.
-
If you want to map to a destination table with a different column structure, use the DTS field mapping feature. For more information, see Set object names in the destination instance.
Map object names
N/A
Change the names of synchronized objects in the destination instance. For more information, see Map databases, tables, and columns.
ImportantIf you use column mapping for partial table synchronization or when the source and destination table schemas are inconsistent, data from source columns that do not have a corresponding destination column is lost.
Connection retry duration
N/A
If DTS cannot connect to the source or destination instance, it retries for 720 minutes (12 hours) by default. You can also specify a custom retry duration. If DTS reconnects to the source or destination instance within the specified duration, the synchronization task automatically resumes. Otherwise, the task fails.
NoteYou are billed for task run time during connection retries. Customize the retry duration based on your business needs, or release the DTS instance as soon as the source and destination instances are released.
-
-
After completing these configurations, click Next in the lower-right corner of the page.
-
Specify the primary key and distribution columns for the tables to be synchronized in the AnalyticDB for PostgreSQL instance.
The configuration page displays the Schema, Table, Primary key column, Distribution column, and Definition status of the tables to be synchronized. For example, for the
mysqltest.customertable, you can set both the primary key column and the distribution column toid. The definition status then changes to Defined. After you complete the settings, click Precheck and Start.NoteThis page appears only if you selected Schema initialization in Step 8. For more information about primary key columns and distribution columns, see Define table constraints and Define table distribution keys.
After you complete the preceding configurations, click Precheck and Start in the lower-right corner of the page.
NoteBefore the synchronization task is officially started, a precheck is performed. The synchronization task can only be started after the precheck passes.
If the precheck fails, click the
 icon next to a specific check item to view the failure details.
Follow the prompt to fix the issue and run the precheck again.
If you do not need to fix the warning check items, you can also select Ignore, Ignore Warning Items and Rerun Precheck to skip the warning check items and run the precheck again.
- After Precheck Passed is displayed in the Precheck dialog box, close the dialog box. The synchronization task starts automatically.
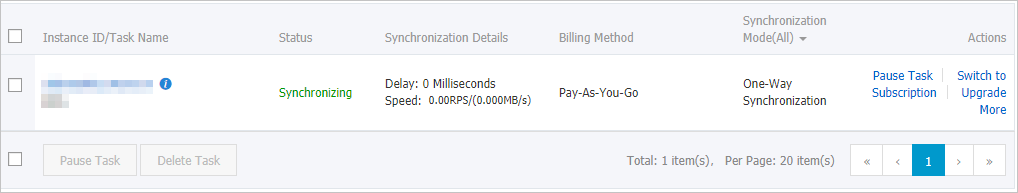
- Wait until the synchronization channel is initialized and the task enters the Synchronizing state.
The Data Synchronization page displays the status of data synchronization jobs.