Connection guide
This document describes the WebSocket API for real-time multimodal interaction. The WebSocket protocol is the recommended connection method due to its low latency and minimal resource consumption.
WebSocket is a network protocol that supports full-duplex communication. A client and server establish a persistent connection through a single handshake. This allows both parties to actively push data to each other, offering significant advantages in real-time performance and efficiency.
Many WebSocket libraries and examples are available for common programming languages, such as:
- Go:
gorilla/websocket - PHP:
Ratchet - Node.js:
ws
Before you start development, you should understand the basic principles and technical details of WebSocket.
NoteFor RTOS or some older Linux systems, you must configure the TLS tunnel for secure WebSocket communication as follows:
- The TLS version must be TLS 1.2 or later.
- Enable SNI (Server Name Indication).
- Configure the CA certificate (GlobalSign Root CA - R3). You can also download it from the official GlobalSign website.
Prerequisites
You must activate the service and obtain an API key. To prevent security risks from code leaks, we recommend that you configure the API key as an environment variable instead of hard coding it in your application.
NoteHandling an API key on the client poses a security risk. Instead, your server should use the API key to obtain a temporary authentication token and send it to the client. For more information, see Obtain a temporary authentication token.
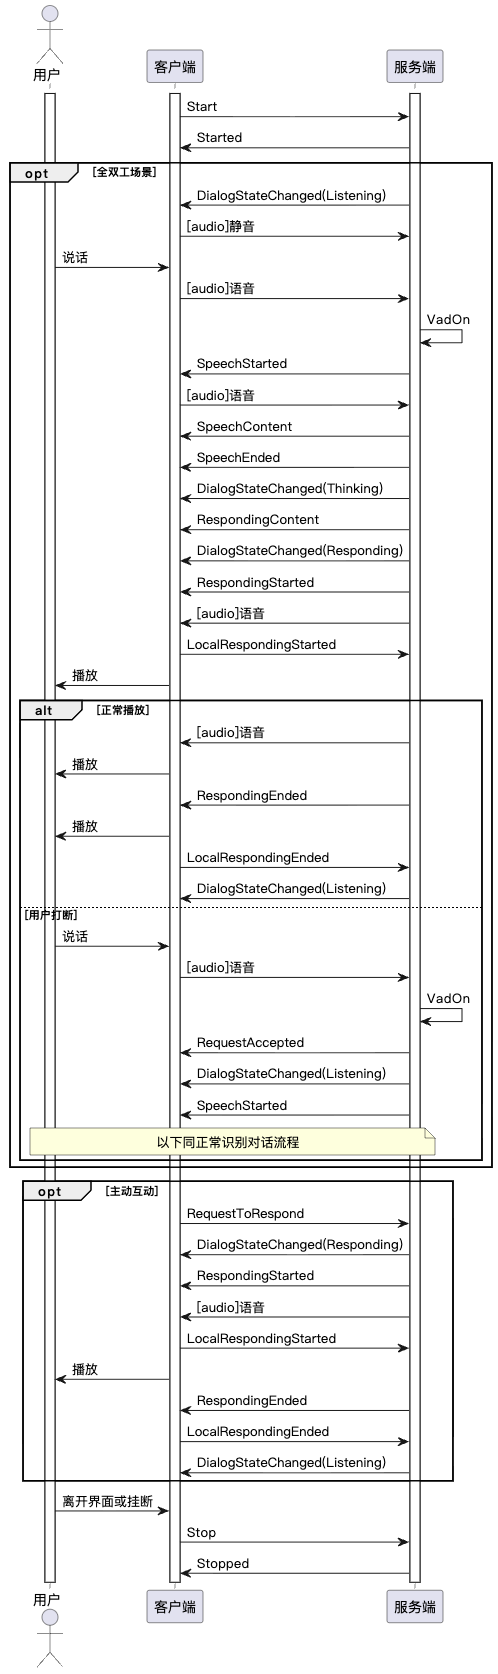
Call sequence diagram
Key workflow: A Started message from the server confirms that the session is created, but the client must not send audio immediately. The client must wait for the DialogStateChanged event and can only start sending the audio stream when the state is Listening.
Endpoint
wss://dashscope.aliyuncs.com/api-ws/v1/inference
Authentication
To initiate a WebSocket handshake (HTTP Upgrade) request, include the API key in the HTTP header. Replace your_api_key with your actual API key:
"Authorization": "Bearer your_api_key"
Voice interaction
Enabling voice interaction adds speech recognition and speech synthesis capabilities to your multimodal interaction application.
Speech recognition supports the following models: Paraformer, FunASR, Qwen-Audio-3.0-ASR-Flash-Streaming, qwen3-asr-flash-realtime, and AppSpecificASR-Realtime.
Speech synthesis supports the following models: cosyvoice-v2, cosyvoice-v3-flash, cosyvoice-v3-plus, cosyvoice-v3.5-flash, cosyvoice-v3.5-plus, qwen3-tts, qwen3-tts-instruct, qwen3-tts-vd, qwen3-tts-vc, sambert, and AppSpecificTTS.
After you select a speech synthesis model in the console, click the voice list in the upper-right corner of the voice interaction area to view the supported voices.
You can also find lists of official voices in the documentation. For the voices of cosyvoice-v2, cosyvoice-v3-plus, and cosyvoice-v3-flash, see the CosyVoice voice list. For qwen3-tts voices, see Supported voices. For sambert voices, see the Java SDK. For the voice parameter, use the name from the SDK, but remove the sambert- prefix and v1 suffix.
Before using a custom voice, ensure its status is "OK". To check the status, see Query a specific voice.
Message types
Binary messages
Currently, binary messages contain only audio data.
Upload audio
To upload audio, you can convert the raw audio directly into a binary stream without extra processing.
The audio uploaded for speech recognition must be 16-bit, single-channel, signed, little-endian PCM. For the sample rate, refer to the description of the parameters.upstream.sample_rate parameter in the Start message.
To reduce network traffic and bandwidth consumption, you can encode the PCM audio into Opus format and set the upload audio format to raw-opus.
When you upload audio, the action to take depends on the upstream.mode setting in the Start message:
-
If
modeistap2talkorduplex, the client must continuously upload audio, and the server automatically detects voice activity. We recommend that you upload data every 100 ms. An interval that is too long or too short can negatively affect latency and processing efficiency.- Calculate the bytes per upload with the following formula:
Bytes per upload = sample rate * bit depth / 8 * time interval (ms) / 1000 - For example, with a 16 kHz sample rate, 16-bit bit depth, and a 100 ms interval, upload
16000 * (16/8) * 100 / 1000 = 3200bytes of PCM data each time.
- Calculate the bytes per upload with the following formula:
-
If the mode is
push2talk, the client does not need to continuously upload audio. Instead, you must use SendSpeech and StopSpeech to notify the server of the start and end of audio recognition. You must upload the audio immediately after you send SendSpeech. Otherwise, the processing time increases.
Receive audio
The server sends the large model's response to the Text-to-Speech (TTS) service to generate audio, which is then sent to the client.
- The received audio is 16-bit single-channel. The sample rate and encoding format are defined by the parameters in the Start message.
- The delivery speed depends on the TTS service performance and is usually faster than the playback speed.
- The server sends a RespondingStarted event before it sends the audio and a RespondingEnded event after.
- After playback is complete, the client must send LocalRespondingEnded to signal that playback has finished.
Text messages
Text messages are JSON-formatted strings and are classified into two types based on their direction:
- Input Message: A directive sent from the client to the server that specifies an action for the server to execute.
- Output Message: An event sent from the server to the client that indicates the result or progress of a server action.
Text messages mark key points in the interaction flow. They control the process and transmit critical information. For more information about the interaction sequence of different messages, see the time series chart.
A text message consists of two parts: header and payload.
-
payload: The content varies based on the message type. -
header: The content is fixed and includes the following parameters:Parameter
Type
Required
Description
task_id
string
Yes
The client generates this unique identifier for the connection to track task execution in the engineering pipeline. We recommend a 36-character UUID string, for example: "f894c16f-f20e-4c1d-837e-89e0fbc63a43"
streaming
string
Yes
The input and output type. For multimodal interaction, this must be set to "duplex", which indicates streaming input and streaming output.
action
string
Yes
The type of input message for the model:
run-task: The first input message of a task.
finish-task: The last input message of a task.
continue-task: Other input messages in the task.
Connection keepalive policy
If 60 seconds pass without the server sending a message to the client, Model Studio terminates the connection and returns a ResponseTimeout error.
To maintain the connection during periods of inactivity, you must periodically send a HeartBeat message. The server responds to the heartbeat to keep the connection active and prevent a timeout.
The mobile and C++ software development kits (SDKs) have built-in keepalive logic. You do not need to send heartbeats manually.
Text message types
Start a session
Start - Input Message
The client sends this message to request the start of a session. After the server receives a Start message, it sends a Started message to the client.
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
task_group | string | Yes | The name of the task group. This parameter is fixed to | |
task | string | Yes | The name of the task. This parameter is fixed to | |
function | string | Yes | The function to call. This parameter is fixed to | |
model | string | Yes | The name of the Alibaba Cloud Model Studio model. This parameter is fixed to | |
input | directive | string | Yes | The name of the instruction: Start |
workspace_id | string | Yes | Your workspace ID from Alibaba Cloud Model Studio (Workspace ID). To find this ID, go to the multimodal interaction console, click the workspace name in the lower-left corner, and look in Workspace Details. Currently, only the default workspace of an Alibaba Cloud account is supported. | |
app_id | string | Yes | Your App ID (App ID). You can find this on the My Applications page of the multimodal interaction console. | |
dialog_id | string | No | The dialog ID. Omit this parameter to start a new session. The server generates a dialog ID and returns it in an event. The format is a 36-character string, for example: "12345678-1234-1234-1234-1234567890ab". To continue a previous conversation, pass the | |
parameters | upstream | object | Yes | For details, see the parameters.upstream table below. |
downstream | object | No | For details, see the parameters.downstream table below. | |
client_info | object | Yes | For details, see the parameters.client_info table below. | |
biz_params | object | No | For details, see the parameters.biz_params table below. |
The following table describes the parameters for parameters.upstream.
Parameter | Type | Required | Description |
|---|---|---|---|
type | string | Yes | The upstream type.
|
mode | string | No | The mode the client uses. Default is Options:
For a comparison of the three client modes, see the Comparison of the three client modes table below. |
audio_format | string | No | The audio format. Supported formats are |
sample_rate | int | No | The sample rate for speech recognition. Supported values:
The default is 16000. |
vocabulary_id | string | No | The custom vocabulary ID. If you set this parameter, it overrides the custom vocabulary configuration in the console. If the custom vocabularies in the console do not meet your needs, you can manage them programmatically by using the OpenAPI. For more information, see the custom vocabulary API documentation. |
language | string | No | The speech recognition language. By default, it matches the language selected in the console. To specify multiple languages, separate them with commas, for example: |
The following table describes the parameters for parameters.downstream:
Parameter | Type | Required | Description |
|---|---|---|---|
voice | string | No | The voice for speech synthesis. The supported voices depend on the speech synthesis model that you select in the console. |
sample_rate | int | No | The sample rate for speech synthesis. Supported values:
The default is 24000. The Qwen-TTS and Qwen3-TTS models support only 24000. |
audio_format | string | No | The audio format. Supported formats are The Qwen-TTS model supports only Note: The difference between |
frame_size | int | No | The frame size of the synthesized audio, in milliseconds. Valid values:
The default is 60. This parameter applies only when the audio format for speech synthesis is |
volume | int | No | The volume of the synthesized audio. Valid range: 0–100. Default: 50. |
speech_rate | int | No | The speech rate of the synthesized audio, as a percentage of the normal speed. Valid range: 50–200. Default: 100. |
pitch_rate | int | No | The pitch of the synthesized audio. Valid range: 50–200. Default: 100. |
bit_rate | int | No | The bit rate of the synthesized audio, in kbps. Valid range: 6–510. Default: 32. This parameter applies only when the audio format for speech synthesis is |
intermediate_text | string | No | Controls which intermediate text is returned to the user:
You can specify multiple types, separated by commas. The default is |
word_timestamp_enabled | boolean | No | Specifies whether to return timestamps for the synthesized audio. If set to This parameter requires Timestamps are returned only for cloned voices and for voices that are specified to support timestamps in the CosyVoice voice list. |
transmit_rate_limit | int | No | The rate limit for sending downstream audio, in bytes per second. |
incremental_response | boolean | No | Specifies whether to stream results from the large model. If |
instruction | string | No | Sets instructions to control synthesis effects such as dialect and emotion. This feature applies to The |
The following table describes the parameters for parameters.client_info:
Parameter | Sub-parameter | Type | Required | Description |
|---|---|---|---|---|
user_id | string | Yes | The end-user ID. Generate this ID based on your business rules to implement customized features for different end users. The maximum length is 36 characters. | |
device | uuid | string | No | A globally unique ID for the client device. You must generate this and pass it to the SDK. The maximum length is 40 characters. An end user can have multiple devices, each with a different |
network | ip | string | No | The public IP address of the caller. |
location | latitude | string | No | The latitude of the caller. Submit this for business scenarios that require the client's precise location. |
longitude | string | No | The longitude of the caller. Submit this for business scenarios that require the client's precise location. | |
city_name | string | No | The city where the caller is located. This indicates the client's approximate location. |
The following table describes the parameters for parameters.biz_params:
Parameter | Type | Required | Description |
|---|---|---|---|
user_defined_params | json object | No | Pass-through parameters for the agent. For parameters required by different agents, see the Call an Official Agent documentation. You can set dialog extension parameters in the |
user_prompt_params | json object | No | User-defined variables for the prompt. You can define the keys and values in the JSON object. For details on how to configure custom prompt variables in the console, see Application Configuration - Prompts. |
user_query_params | json object | No | User-defined dialogue variables. You can define the keys and values in the JSON object. For details on how to configure dialogue variables in the console, see Application Configuration - Dialogue Variables. |
Client mode comparison
Comparison item | push2talk | tap2talk | duplex |
|---|---|---|---|
Type | Client-controlled mode | Tap-to-talk mode | Duplex mode |
Audio upload method | On-demand | Continuous An error occurs if the client does not upload audio for more than 20 seconds in the | Continuous An error occurs if the client does not upload audio for more than 20 seconds in any state. |
VAD detection | Client | Server | Server |
Interruption method | Interruption via a | Interruption via a | Voice interruption |
Use case | The client application controls when to send audio for recognition. This is suitable for push-to-talk scenarios where the user presses a button to speak and releases it to stop. | The client continuously uploads audio, and the server detects voice activity. This mode does not support voice interruption; you must send a | The client continuously uploads audio, and the server detects voice activity. The user can interrupt the model's output by speaking at any time. |
Example:
{
    "header": {
        "action":"run-task",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43",
        "streaming":"duplex"
    },
    "payload": {
        "task_group":"aigc",
        "task":"multimodal-generation", // Task: multimodal generation
        "function":"generation",
        "model":"multimodal-dialog", // Model: multimodal dialog (note this is different from the task)
        "input":{
          "directive": "Start",
          "workspace_id": "llm-***********",
          "app_id": "****************"
        },
        "parameters":{
          "upstream":{
            "type": "AudioOnly",
            "mode": "duplex"
          },
          "downstream":{
            "voice": "longxiaochun_v2",
            "sample_rate": 24000
          },
          "client_info":{
            "user_id": "bin********207",
            "device":{
              "uuid": "432k*********k449"
            },
            "network":{
              "ip": "203.0.113.10"
            },
            "location":{
              "city_name": "Beijing"
            }
          },
          "biz_params":{
            "user_defined_params": {
                "extra_config": {
                    "enable_web_search": false
                },
                "agent_id_xxxxx": {
                    "name": "value"
                }
            },
            "user_prompt_params": {
                "name": "value"
            },
            "user_query_params": {
                "name": "value"
            }
          }
        }
    }
}
Started - Output Message
NoteAfter receiving the Started message, do not send audio immediately. You must wait for a DialogStateChanged message that confirms the session has entered the Listening state before sending audio.
Level 1 Parameter | Level 2 Parameter | Type | Description |
|---|---|---|---|
output | event | string | The name of the event: Started |
dialog_id | string | The dialog ID. |
Example:
Sample Started response:
{
    "header": {
        "event":"result-generated",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43"
    },
    "payload": {
        "output":{
          "event": "Started",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
End a session
Stop - Input Message
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
input | directive | string | Yes | The name of the instruction: Stop |
dialog_id | string | No | The dialog ID. |
Example:
{
    "header": {
        "action":"finish-task",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43",
        "streaming":"duplex"
    },
    "payload": {
        "input":{
          "directive": "Stop",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
Stopped - Output Message
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
output | event | string | Yes | The name of the event: Stopped |
dialog_id | string | Yes | The dialog ID. |
Example:
{
    "header": {
        "event":"result-generated",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43"
    },
    "payload": {
        "output":{
          "event": "Stopped",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
Server state change event
DialogStateChanged - Output Message
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
output | event | string | Yes | The name of the event: DialogStateChanged |
state | string | Yes | The AI interaction state. Valid values: Note: The | |
dialog_id | string | Yes | The dialog ID. |
Example:
{
    "header": {
        "event":"result-generated",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43"
    },
    "payload": {
        "output":{
          "event": "DialogStateChanged",
          "state": "Listening",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
Request to upload voice
RequestToSpeak - Input Message
If a user wants to speak when the state is not Listening, they can send this directive to interrupt the large language model's (LLM) response.
The specific user action that triggers this event varies by interaction type, such as pressing a button or interrupting with a voice command (requires duplex mode).
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
input | directive | string | Yes | The name of the instruction: RequestToSpeak |
dialog_id | string | No | The dialog ID. |
Example:
{
    "header": {
        "action":"continue-task",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43",
        "streaming":"duplex"
    },
    "payload": {
        "input":{
          "directive": "RequestToSpeak",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
RequestAccepted - Output Message
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
output | event | string | Yes | The name of the event: RequestAccepted |
dialog_id | string | Yes | The dialog ID. |
Example:
{
    "header": {
        "event":"result-generated",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43"
    },
    "payload": {
        "output":{
          "event": "RequestAccepted",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
Upload voice command
SendSpeech - Input Message
When the Start message specifies the push2talk mode, the client must notify the server when the user starts speaking. In the Listening state, the client sends a SendSpeech message when the user presses a button. This message signals that an audio upload is about to begin. The client must send the audio data immediately after this message.
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
input | directive | string | Yes | The name of the instruction: SendSpeech |
dialog_id | string | No | The dialog ID. |
Example:
{
    "header": {
        "action":"continue-task",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43",
        "streaming":"duplex"
    },
    "payload": {
        "input":{
          "directive": "SendSpeech",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
StopSpeech - Input Message
When the Start message specifies the push2talk mode, the client must send a StopSpeech message when the user finishes speaking and releases the button to signal the end of the voice input.
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
input | directive | string | Yes | The name of the instruction: StopSpeech |
dialog_id | string | No | The dialog ID. |
Example:
{
    "header": {
        "action":"continue-task",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43",
        "streaming":"duplex"
    },
    "payload": {
        "input":{
          "directive": "StopSpeech",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
CancelSpeech - Input message
In push2talk or tap2talk mode, the client can send a CancelSpeech message to terminate the voice input. The server then stops the recognition process and returns to an idle state.
Level 1 parameter | Level 2 parameter | Type | Required | Description |
|---|---|---|---|---|
input | directive | string | Yes | Directive name: CancelSpeech |
dialog_id | string | No | dialog ID |
Example:
{
    "header": {
        "action":"continue-task",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43",
        "streaming":"duplex"
    },
    "payload": {
        "input":{
          "directive": "CancelSpeech",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
Speech recognition start/end
SpeechStarted - Output Message
The server sends this event when it detects the start of speech for automatic speech recognition (ASR).
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
output | event | string | Yes | The name of the event: SpeechStarted |
dialog_id | string | Yes | The dialog ID. |
Example:
{
    "header": {
        "event":"result-generated",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43"
    },
    "payload": {
        "output":{
          "event": "SpeechStarted",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
SpeechEnded - Output Message
The server sends this event when it detects the end of speech for ASR. If the client is still uploading audio, it must stop after it receives this event.
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
output | event | string | Yes | The name of the event: SpeechEnded |
dialog_id | string | Yes | The dialog ID. |
Example:
{
    "header": {
        "event":"result-generated",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43"
    },
    "payload": {
        "output":{
          "event": "SpeechEnded",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
Specify response content
RequestToRespond - Input Message
In the Listening state, this message notifies the server to proactively interact with the user. Based on the type field, the server either directly converts the text in the text field to speech and sends it, or calls the large model and then converts the result to speech before sending it.
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
input | directive | string | Yes | The name of the instruction: RequestToRespond |
dialog_id | string | Yes | The dialog ID. | |
type | string | Yes | Specifies the interaction type. Two values are supported:
| |
text | string | Yes | The text to process. Must not be null.
| |
parameters | images | list[] | No | Information about the images to be analyzed. |
biz_params | object | No | For details, see the parameters.biz_params table below. |
The following table describes parameters.biz_params:
Parameter | Type | Required | Description |
|---|---|---|---|
videos | list[] | No | Manages video call connections. Example: Setting Setting |
Other parameters | No | This parameter is the same as |
NoteIn addition to the videos parameter, parameters.biz_params is the same as the parameters.biz_params in the Start message and is used to pass custom parameters to the dialog system. The biz_params parameter of RequestToRespond is valid only for the current request.
{
    "header": {
        "action":"continue-task",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43",
        "streaming":"duplex"
    },
    "payload": {
        "input":{
          "directive": "RequestToRespond",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb",
          "type": "prompt",
          "text": "Hello, what would you like to talk about?"
        },
        "parameters":{
          "images":[{
              "type": "base64",
              "value": "aGVsbG8gd29ybGQ="
          }],
          "biz_params":{
            "user_defined_params":{},
            "videos": [
                  {
                    "action": "connect/exit",
                    "type": "voicechat_video_channel"
                  }
                ]
          }
        }
    }
}
AI voice response status
RespondingStarted - Output Message
The AI voice response has started. The SDK must prepare to receive audio data from the server.
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
output | event | string | Yes | The name of the event: RespondingStarted |
dialog_id | string | Yes | The dialog ID. |
Example:
{
    "header": {
        "event":"result-generated",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43"
    },
    "payload": {
        "output":{
          "event": "RespondingStarted",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
RespondingEnded - Output Message
The AI voice response has ended.
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
output | event | string | Yes | The name of the event: RespondingEnded |
dialog_id | string | Yes | The dialog ID. |
Example:
{
    "header": {
        "event":"result-generated",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43"
    },
    "payload": {
        "output":{
          "event": "RespondingEnded",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
Client-side playback event
LocalRespondingStarted - Input Message
The client starts playing the audio sent from the server.
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
input | directive | string | Yes | The name of the instruction: LocalRespondingStarted |
dialog_id | string | No | The dialog ID. |
Example:
{
    "header": {
        "action":"continue-task",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43",
        "streaming":"duplex"
    },
    "payload": {
        "input":{
          "directive": "LocalRespondingStarted",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
LocalRespondingEnded - Input Message
The client has finished playing audio from the server. This message confirms that playback is complete, prompting the server to end the current question and answer session and return to the Listening state.
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
input | directive | string | Yes | The name of the instruction: LocalRespondingEnded |
dialog_id | string | No | The dialog ID. |
Example:
{
    "header": {
        "action":"continue-task",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43",
        "streaming":"duplex"
    },
    "payload": {
        "input":{
          "directive": "LocalRespondingEnded",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
Text delivery event
SpeechContent - Output Message
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
output | event | string | Yes | The name of the event: SpeechContent |
dialog_id | string | Yes | The dialog ID. | |
text | string | Yes | The text from speech recognition, returned as a streaming output. Each message contains the full, cumulative text recognized so far. For example, you might first receive | |
finished | bool | Yes | Indicates whether the output is finished. |
Example:
{
    "header": {
        "event":"result-generated",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43"
    },
    "payload": {
        "output":{
          "event": "SpeechContent",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb",
          "text": "One two three",
          "finished": false
        }
    }
}
RespondingContent - Output Message
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
output | event | string | Yes | The event name: |
dialog_id | string | Yes | The dialog ID. | |
round_id | string | Yes | The ID of the current interaction round. | |
llm_request_id | string | Yes | The request_id for the large language model (LLM) call. | |
text | string | Yes | The text output by the system. This is a full streaming output. | |
spoken | string | Yes | The text used for speech synthesis. This is a full streaming output. | |
finished | bool | Yes | Indicates whether the output is finished. | |
extra_info | object | No | Other extension information. Currently supports:
Omit this field if no extra information is available. |
Example:
{
    "header": {
        "event": "result-generated",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43"
    },
    "payload": {
        "output": {
            "event": "RespondingContent",
            "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb",
            "text": "You entered the number sequence \"12345\". If you have any questions about these numbers or need me to perform a task with them, please provide more details, and I'll do my best to help you.",
            "spoken": "You entered the number sequence \"12345\". If you have any questions about these numbers or need me to perform a task with them, please provide more details, and I'll do my best to help you.",
            "finished": true,
            "extra_info": {
                "commands": "[{\"name\":\"VOLUME_SET\",\"params\":[{\"name\":\"series\",\"normValue\":\"70\",\"value\":\"70\"}]}]",
                "tool_calls": [
                    {
                        "id": "",
                        "type": "function",
                        "function": {
                            "name": "function_name",
                            "arguments": "{\"id\": \"123\", \"name\": \"test\"}",
                            "outputs": "{\"result\": \"success\"}",
                            "status": {
                                "code": 200,
                                "message": "Success."
                            }
                        }
                    }
                ]
            }
        }
    }
}
Client-side update event
UpdateInfo - Input Message
Level 1 Parameter | Level 2 Parameter | Level 3 Parameter | Type | Required | Description |
|---|---|---|---|---|---|
input | directive | string | Yes | The name of the instruction: UpdateInfo | |
dialog_id | string | No | The dialog ID. | ||
parameters | images | list[] | No | Image data. | |
client_info | status | object | No | The current status of the client. | |
biz_params | object | No | Specifies custom parameters for the dialog system, similar to | ||
upstream | language | string | No | Updates the speech recognition language. If omitted, the language remains unchanged. To specify multiple languages, separate them with commas, for example: | |
downstream | language | string | No | Updates the speech synthesis language. If omitted, the language remains unchanged. |
Example:
{
    "header": {
        "action":"continue-task",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43",
        "streaming":"duplex"
    },
    "payload": {
        "input":{
          "directive": "UpdateInfo",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        },
        "parameters":{
          "images":[{
              "type": "base64",
              "value": "base64String"
          }],
          "client_info": {
              "status": {
                  "bluetooth_announcement": {
                      "status": "stopped"
                  },
                  "stream_media_playback": {
                      "status": "stopped"
                  },
                  "phone_ringing": {
                      "status": "stopped"
                  },
                  "stream_media_playback_qq": {
                      "status": "stopped"
                  }
              }
          },
          "biz_params":{
          }
        }
    }
}
Heartbeat event
Periodically send this message to the server to prevent connection timeouts. To account for network latency and processing time, we recommend sending it every 50 seconds. The server will respond with the same message, which the client can safely ignore.
HeartBeat - Input Message
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
input | directive | string | Yes | The name of the instruction: HeartBeat |
dialog_id | string | No | The dialog ID. |
Example:
{
  "header": {
    "action": "continue-task",
    "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43",
    "streaming": "duplex"
  },
  "payload": {
    "input": {
      "directive": "HeartBeat",
      "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
    }
  }
}
HeartBeat - Output Message
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
output | event | string | Yes | The name of the event: HeartBeat |
dialog_id | string | Yes | The dialog ID. |
Example:
{
    "header": {
        "event":"result-generated",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43"
    },
    "payload": {
        "output":{
          "event": "HeartBeat",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb"
        }
    }
}
Error event
Error - Output Message
Level 1 Parameter | Level 2 Parameter | Type | Required | Description |
|---|---|---|---|---|
output | error_code | int | Yes | The error code. |
error_name | string | Yes | The name of the error. | |
error_message | string | Yes | The error message. |
{
    "header": {
        "event":"result-generated",
        "task_id": "f894c16f-f20e-4c1d-837e-89e0fbc63a43"
    },
    "payload": {
        "output":{
          "event": "Error",
          "dialog_id": "dd84xxxx-xxxx-xxxx-xxxx-xxxxb7bb",
          "error_code": 500,
          "error_name": "InternalLLMError",
          "error_message": "Internal LLM error"
        }
    }
}
Error codes
For troubleshooting, see multimodal interaction service - error codes.
If the issue persists, contact technical support with the full request_id and dialog_id.
Glossary
VAD: Voice Activity Detection
ASR: Automatic Speech Recognition
TTS: Text-to-Speech
LLM: Large Language Model