Fine-tune with the API or CLI
Learn how to tune Qwen models in Alibaba Cloud Model Studio using the API (HTTP) and the command line (shell). Model tuning involves three methods: supervised fine-tuning (SFT), continual pre-training (CPT), and direct preference optimization (DPO).
ImportantThis topic is applicable only to the China (Beijing) region.
Prerequisites
- Review Introduction to model fine-tuning to understand its concepts, process, and data requirements.
- Activate the service and obtain an API key. For instructions, see Get an API key.
- Grant the RAM user (RAM user) the necessary invocation, training, and deployment permissions.
NoteThe API supports only token-based billing for training jobs. To use model training units (prepaid or postpaid), create the job in the console.
Tuning file upload
Preparing fine-tuning files
SFT training set
SFT ChatML (Chat Markup Language) format training data supports multi-turn conversations and various role settings.
The OpenAI
nameandweightparameters are not supported. All assistant outputs will be trained.
# A single line of training data (in JSON format) has the following typical structure when expanded:
{"messages": [
  {"role": "system", "content": "System input 1"},
  {"role": "user", "content": "User input 1"},
  {"role": "assistant", "content": "Expected model output 1"},
  {"role": "user", "content": "User input 2"},
  {"role": "assistant", "content": "Expected model output 2"}
  ...
]}
For information about the differences between system, user, and assistant, see Overview. Sample training datasets: SFT-ChatML_format_example.jsonl, SFT-ChatML_format_example.xlsx. XLS and XLSX formats support only single-turn conversations.
All assistant lines in a single training data entry support the "loss_weight" parameter, which sets the relative importance of that line during training. (Range: 0.0 to 1.0. A larger value indicates higher importance.)
This parameter is available for invitational preview. To use it, contact your account manager.
 {"role": "assistant", "content": "Expected model output 1", "loss_weight": 1.0},
 {"role": "assistant", "content": "Expected model output 2", "loss_weight": 0.5}
SFT thinking model
The training data supports multi-turn conversations and various role settings, but only the last assistant output can be trained. A single line of training data has the following structure when expanded:
The newline characters
\nbefore and after the think tag must be preserved.
# A single line of training data (in JSON format) has the following typical structure when expanded:
{"messages": [
  {"role": "system", "content": "System input 1"},
  {"role": "user", "content": "User input 1"},
  {"role": "assistant", "content": "Model output 1"}, --Intermediate assistant outputs should not have <think style={{ verticalAlign: "top" }}> tags
   ...
  {"role": "user", "content": "User input 2"},
  {"role": "assistant", "content": "<think style={{ verticalAlign: "top" }}>\nExpected thinking content 2\n</think>\n\nExpected output 2"} --Thinking content can only be included in the last assistant output.
]}
For information about the differences between system, user, and assistant, see Overview. Sample training dataset: SFT-deep_thinking_content_example.jsonl.
You can also set the model not to output the <think style={{ verticalAlign: "top" }}> tag in the training samples. If you use this output method, it is not recommended to enable the thinking mode for calls after the model is trained.
{"role": "assistant", "content": "Expected model output 2"} --Tells the model not to enable thinking
The last assistant line of a single training data entry supports the "loss_weight" parameter, which sets the relative importance of that entry during training. (Range: 0.0 to 1.0. A larger value indicates higher importance.)
This parameter is available for invitational preview. To use it, contact your account manager.
{"role": "assistant", "content": "<think style={{ verticalAlign: "top" }}>\nExpected thinking content 2\n</think>\n\nExpected output 2", "loss_weight": 1.0}
SFT visual understanding (Qwen-VL)
The OpenAI
nameandweightparameters are not supported. All assistant outputs will be trained.
For information about the differences between system, user, and assistant, see Overview. Sample ChatML format training data:
To pass a
systemmessage, the correspondingcontentmust use the array format[{"text":"..."}]and not the string format"content":"string".
NoteIf you are training a thinking model, you must also follow the data format requirements for the SFT thinking model.
# A single line of training data (in JSON format) has the following structure when expanded:
{"messages": [
  {"role": "system", "content": [{"text": "System input"}]},
  {"role": "user", "content": [{"text": "User input 1"}, {"image": "image_file_name1.jpg", "resized_width": 200, "resized_height": 200}]},
  {"role": "assistant", "content": [{"text": "Expected model output 1"}]},
  {"role": "user", "content": [{"text": "User input 2"}, {"video": "video_file_name1.mp4", "fps": 3.0, "resized_width": 200, "resized_height": 200, "video_start": 0.0, "video_end": 3.0}]},
  {"role": "assistant", "content": [{"text": "Expected model output 2"}]},
  {"role": "user", "content": [{"text": "User input 2"}, {"video": ["0.jpg", "1.jpg", "2.jpg", "3.jpg"], "sample_fps": 5.0, "resized_width": 200, "resized_height": 200}]},
  {"role": "assistant", "content": [{"text": "Expected model output 2"}]},
  ...
]}
Click here to see more supported parameters
Field | Type | Required | Description |
|---|---|---|---|
Image file | |||
|
| Yes | Image file path |
|
| No | Target image scaling width (pixels) |
|
| No | Target image scaling height (pixels) |
Video file - Video file path mode (supported only by qwen3.5 and later VL models) Sample:AlibabaCloud_VL_Video.zip | |||
|
| Yes | Video file path mode: |
|
| No | Target video scaling width (pixels) |
|
| No | Target video scaling height (pixels) |
|
| No | Input frequency during training. If you set |
|
| No | Video clip start time (seconds) |
|
| No | Video clip end time (seconds) |
Video file - Image frame list mode (supported only by qwen3.5 and later VL models) | |||
|
| Yes | Image frame list mode: |
|
| No | Used to inform the frame rate of the image frames. |
|
| No | Image frame scaling width (pixels) |
|
| No | Image frame scaling height (pixels) |
Suggestions for training object localization:
- Qwen2.5-VL: The training coordinates are absolute values relative to the top-left corner of the scaled image, in pixels.
- Qwen3-VL: The training coordinates are relative, and the coordinate values are scaled to the range of
[0, 999].
ZIP file requirements:
-
Format: ZIP. The maximum size is 2 GB. Folders and file names within the ZIP file must only contain ASCII characters, including letters (a-z, A-Z), numbers (0-9), underscores (_), and hyphens (-).
-
The training text file must be named data.jsonl and located in the root directory of the ZIP file. Ensure that the
data.jsonlfile is at the top level of the ZIP file and not in a subfolder. -
The width and height of a single image must not exceed 1024 pixels, and the size must not exceed 10 MB. The supported formats are
.bmp,.jpeg /.jpg,.png,.tif /.tiff, and.webp. -
Image file names must be unique, even if they are in different folders.
-
ZIP file directory structure:
Single-level directory (recommended)
The image files and the
data.jsonlfile are all located in the root directory of the ZIP file.Trainingdata_vl.zip |--- data.jsonl #Note: Do not wrap in an outer folder |--- image1.png |--- video1.mp4Multi-level directory
-
The data.jsonl file must be in the root directory of the ZIP file.
-
In the data.jsonl file, you only need to specify the image or video filename, not the file path. For example:
Correct example:
image1.jpg. Incorrect example:jpg_folder/image1.jpg. -
Image/video file names must be globally unique within the ZIP file.
Trainingdata_vl.zip |--- data.jsonl #Note: Do not wrap in an outer folder |--- jpg_folder | └── image1.jpg |--- mp4_folder └── video.mp4 -
DPO dataset
DPO ChatML format training data. A single line of training data has the following structure when expanded:
For information about the differences between system, user, and assistant, see Overview. Sample training dataset: DPO_ChatML_format_example.jsonl.
# A single line of training data (in JSON format) has the following typical structure when expanded:
{"messages": [
  {"role": "system", "content": "System input"},
  {"role": "user", "content": "User input 1"},
  {"role": "assistant", "content": "Model output 1"},
  {"role": "user", "content": "User input 2"},
  {"role": "assistant", "content": "Model output 2"},
  {"role": "user", "content": "User input 3"}
 ],
 "chosen":
   {"role": "assistant", "content": "Agreed-upon expected model output 3"},
 "rejected":
   {"role": "assistant", "content": "Rejected expected model output 3"}}
The model takes all content within messages as input. DPO is used to train the model on positive and negative feedback for User input 3.
For deep thinking content, you need to wrap it with <think style={{ verticalAlign: "top" }}> tags:
{"role": "assistant", "content": "<think style={{ verticalAlign: "top" }}>Expected model thinking content</think>Expected model output"}
The "chosen" module of a single training data entry supports the "loss_weight" parameter, which sets the relative importance of that training data in the training process. (Range: 0.0 to 1.0. A larger value indicates higher importance.)
This parameter is available for invitational preview. To use it, contact your account manager.
 "chosen":
   {"role": "assistant", "content": "Agreed-upon expected model output 3", "loss_weight": 1.0},
CPT training set
CPT plain text format training data. A single line of training data has the following structure when expanded:
{"text":"Text content"}
Sample training dataset: CPT-text_generation_training_set_example.jsonl
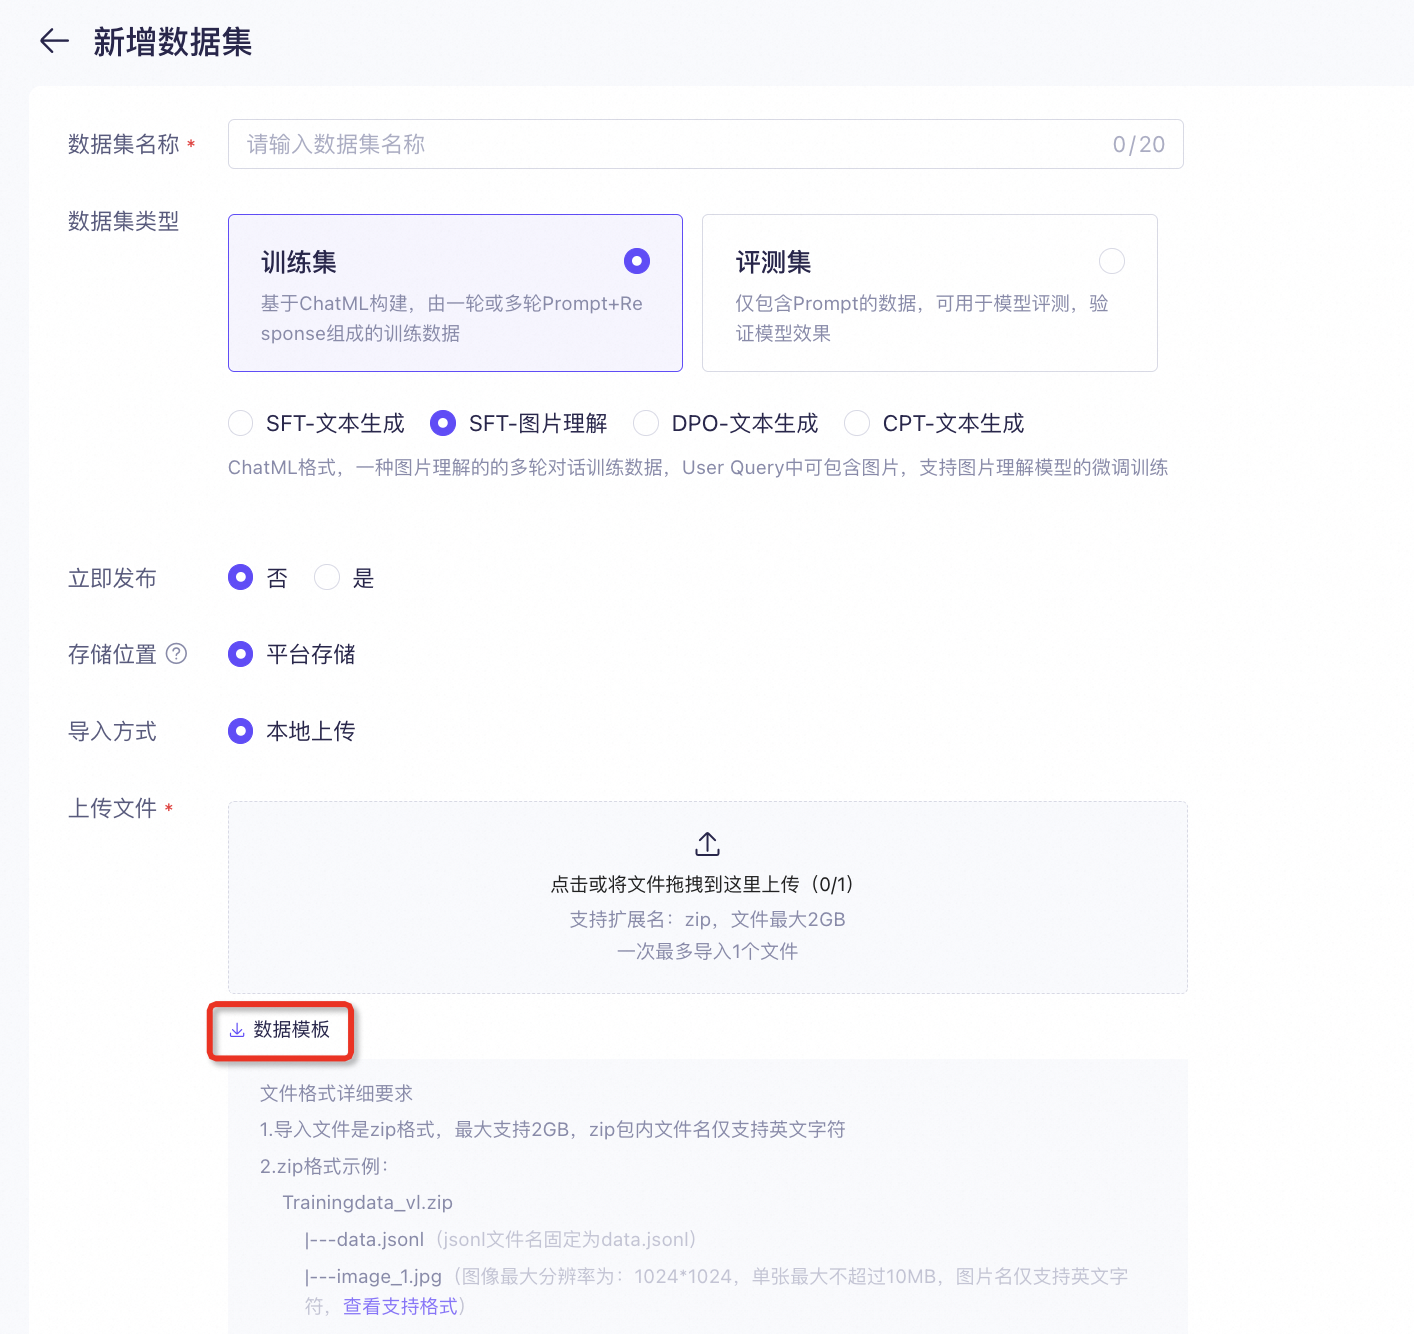
You can also download a data template from the Model Studio console. |
|
Upload fine-tuning fileto Model Studio
DashScope API
For Windows CMD, replace
${DASHSCOPE_API_KEY}with%DASHSCOPE_API_KEY%. For PowerShell, replace it with$env:DASHSCOPE_API_KEY.
curl --request POST \
'https://dashscope.aliyuncs.com/api/v1/files' \
--header 'Authorization: Bearer '${DASHSCOPE_API_KEY} \
--form 'files=@"/path/to/your/file.jsonl"' \
--form 'purpose="fine-tune"' \
--form 'descriptions="a sample fine-tune data file for qwen"'
NoteLimitations:
- The maximum size of a single file is 300 MB.
- The total size of all non-deleted files is limited to 5 GB.
- You can store a maximum of 100 non-deleted files.
- Files are stored indefinitely.
For more details, see model fine-tuning file management service.
Sample response:
{
  "request_id":"xx",
  "data":{
    "uploaded_files":[{
      "file_id":"976bd01a-f30b-4414-86fd-50c54486e3ef",
      "name":"qwen-fine-tune-sample.jsonl"}],
   "failed_uploads":[]}
 }
Model fine-tuning
Creating, querying, logging, checkpoint management, and listing/canceling/deleting fine-tuning jobs are all done via API. Each interface's complete request/response parameters and examples are on the corresponding API page; this section only outlines the workflow.
Create a fine-tuning job
Call the Create a fine-tuning job interface (POST /api/v1/fine-tunes) to start training. See that page for the request body (model / training_datasets / hyper_parameters / training_type, etc.) and response examples.
Retrieve a fine-tuning job
Use the job_id to query the task status. See Query fine-tuning task details.
Get fine-tuning job logs
Retrieve training logs via the Get fine-tuning task logs interface (GET /api/v1/fine-tunes/{job_id}/logs).
Query and publish model checkpoints
Checkpoints produced by fine-tuning can be listed and exported (published):
- List checkpoints: see List Checkpoint (
GET /api/v1/fine-tunes/{job_id}/checkpoints). - Export (publish) a specific checkpoint: see Export Checkpoint (
GET /api/v1/fine-tunes/{job_id}/export/{checkpoint}?model_name=...), asynchronous; poll status via the list interface.
More fine-tuning operations
- List jobs: List fine-tuning jobs
- Cancel job: Cancel fine-tuning job
- Delete job: Delete fine-tuning job
API reference
This topic provides a reference for DashScope command-line calls. For details on API calls, see API details.
Model deployment and invocation
Model deployment
For other deployment methods, see Deploy a model by using the API.
curl "https://dashscope.aliyuncs.com/api/v1/deployments" \
--header "Authorization: Bearer $DASHSCOPE_API_KEY" \
--header 'Content-Type: application/json' \
--data '{
    "model_name": "qwen3-8b-ft-202511132025-0260",
    "plan": "lora",
    "capacity": 1,
    "name": "qwen3-8b-ft"
}'
curl "https://dashscope.aliyuncs.com/api/v1/deployments" \
--header "Authorization: Bearer $DASHSCOPE_API_KEY" \
--header 'Content-Type: application/json' \
--data '{
    "name": "my_qwen_plus",
    "model_name": "qwen-plus-2025-12-01",
    "plan": "mu",
    "deploy_spec": "MU1",
    "enable_thinking": true,
    "capacity": 4,
    "max_context_length": 10000,
    "rpm_limit": 500,
    "tpm_limit": 1000
}'
Query deployment status
Once the deployment status is RUNNING, you can invoke the model.
curl 'https://dashscope.aliyuncs.com/api/v1/deployments/<your_model_instance_id>' \
--header 'Authorization: Bearer '${DASHSCOPE_API_KEY}  \
--header 'Content-Type: application/json'
For other deployment operations, such as scaling and deprovisioning, see Model Deployment - API Details.
Model invocation
Once the model deployment status is RUNNING, you can invoke the fine-tuned model just like any other model.
You can also get the Model Code from the Dedicated Deployment console.
For details on usage and parameters, see the DashScope API Reference.
curl 'https://dashscope.aliyuncs.com/api/v1/services/aigc/text-generation/generation' \
--header 'Authorization: Bearer '${DASHSCOPE_API_KEY}  \
--header 'Content-Type: application/json' \
--data '{
    "model": "<your_model_instance_id>",
    "input":{
        "messages":[
            {
                "role": "user",
                "content": "Who are you?"
            }
        ]
    },
    "parameters": {
        "result_format": "message"
    }
}'
Model evaluation
The model evaluation feature is exclusive to the Alibaba Cloud Model Studio console. Go to the Model Evaluation page to evaluate model performance.
For more information, see Model Evaluation.